Paper: 2605.21468 Authors: Zhepei Wei, Xinyu Zhu, Wei-Lin Chen, Chengsong Huang, Jiaxin Huang, Yu Meng Categories: cs.LG, cs.CL
The Gap
Reinforcement learning with verifiable rewards (RLVR) has become the standard for improving reasoning in LLMs—think of methods like GRPO or REINFORCE applied to math and coding tasks. The problem: RLVR is expensive. Training runs consume thousands of GPU hours, and practitioners have no choice but to run the full trajectory. Prior work treats RLVR as a black box optimization process where you need every step to reach the final performance.
But what if the weight trajectory isn’t random noise? What if there’s hidden structure we’re ignoring? This paper asks: can we predict where RLVR training will end up by observing only the beginning?
Problem: RLVR training is expensive (1000s of steps)
   |
   v
Observation: Weight trajectories might have low-rank structure
   |
   v
Hypothesis: Rank-1 subspace captures most performance gains
   |
   v
Method: Fit rank-1 direction + linear magnitude from short window
   |
   v
Evidence: 15% observation window -> full performance at 10-20x extrapolation
   |
   v
Conclusion: RLVR geometry is predictable; most training is redundant
The Increment
One sentence: Before this paper, you needed 1000 RLVR steps to get 1000-step performance; after this paper, you need 50 steps plus 30 seconds of linear algebra.
Core Mechanism
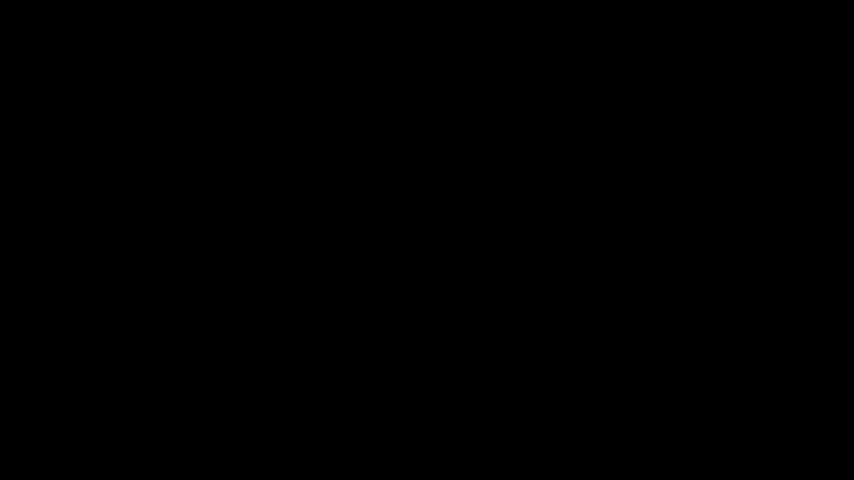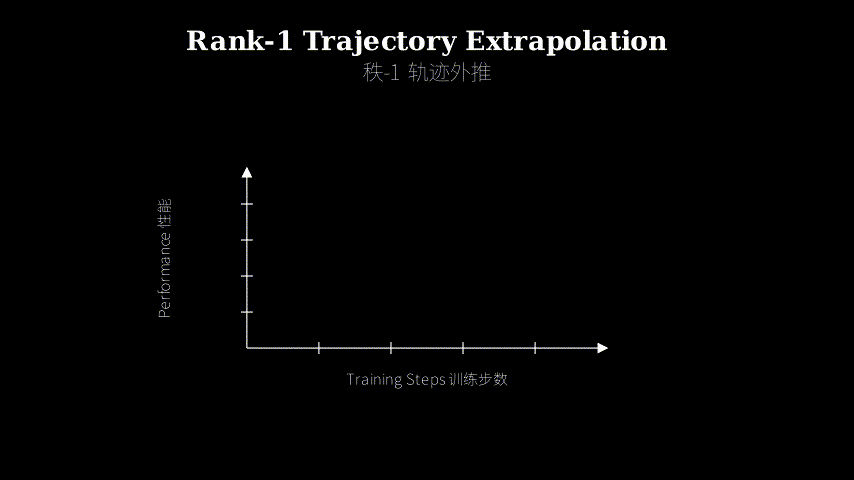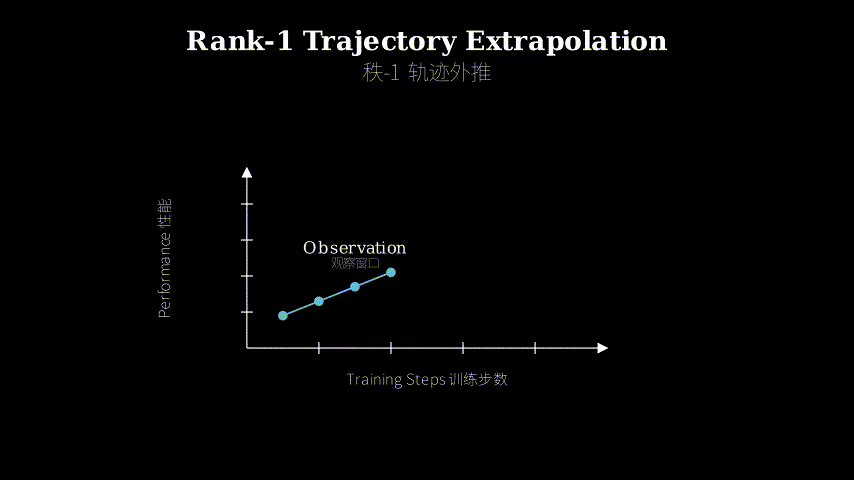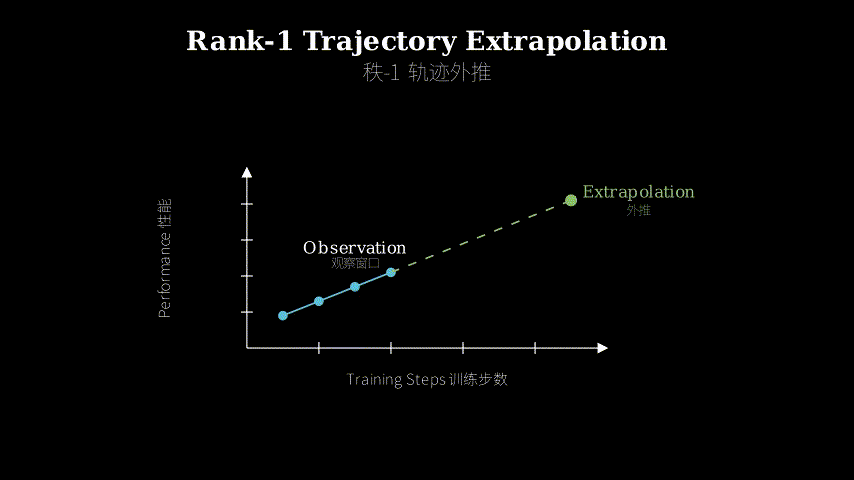
RELEX operates in three phases. First, run standard RLVR training for a short observation window (say, 50 steps out of 1000). Save checkpoints at regular intervals. Second, compute the weight deltas between consecutive checkpoints and perform SVD to extract the dominant direction—the rank-1 subspace that captures most variance. Third, fit a linear regression to predict how the magnitude of projection onto this direction grows with training steps. Now extrapolate: take the initial checkpoint, add the rank-1 direction scaled by the predicted magnitude at step 1000, and you have your extrapolated checkpoint.
Observation Window (steps 0-50):
  theta_0 -> theta_10 -> theta_20 -> ... -> theta_50
     |         |           |                    |
     +-------- compute deltas (delta_i) --------+
                          |
                          v
                    SVD on stacked deltas
                          |
                          v
                  Extract rank-1 direction (u)
                          |
                          v
            Project each delta onto u: alpha_i = delta_i · u
                          |
                          v
              Fit linear model: alpha = a*step + b
                          |
                          v
        Extrapolate to step 1000: theta_1000 = theta_0 + alpha_1000 * u
Think of RLVR training as a ship sailing across the ocean. Traditional thinking assumes you need to sail the entire route to reach the destination. RELEX observes that the ship is actually moving in a nearly straight line (rank-1 trajectory), and the speed is predictable (linear growth). So instead of sailing for 1000 nautical miles, you sail for 50 miles, measure your heading and speed, then teleport to where you would have been at mile 1000. The rank-1 direction is your compass bearing, the linear regression is your speedometer, and the extrapolation is the teleportation. The key insight: RLVR doesn’t zigzag—it commits to a direction early and maintains it.
Key Concepts
-
Rank-1 trajectory: Imagine you’re tracking a parameter tensor with millions of dimensions. At each training step, the weights move in some direction in this high-dimensional space. A rank-1 trajectory means that despite the millions of possible directions, the weight updates are essentially moving along a single line. Mathematically, if you stack all the weight deltas into a matrix and perform SVD, the first singular value dominates—it captures 80-90% of the variance. Concretely, if your model has 1.5B parameters, the update at step 100 can be approximated as: delta_100 ≈ alpha_100 ** u, where u is a fixed 1.5B-dimensional vector (the rank-1 direction) and alpha_100 is a scalar (the magnitude). This is surprising because stochastic optimization typically explores many directions, but RLVR converges to a single dominant mode almost immediately.
-
Denoising effect: RLVR training involves stochastic gradients—each batch introduces noise. If you naively extrapolate the raw weight trajectory, you’re amplifying this noise. RELEX’s rank-1 projection acts as a filter: it keeps the signal (the dominant direction of improvement) and discards the noise (random fluctuations orthogonal to this direction). Think of it like averaging out the jitter in a hand-drawn line to reveal the underlying straight path. The paper shows that without this projection, extrapolation fails—performance degrades beyond the observation window. With projection, extrapolation works even at 20x the observed steps.
Framework Shift
Before (standard RLVR):              After (RELEX):

Training loop (1000 steps):          Training loop (50 steps):
  for step in 1..1000:                 for step in 1..50:
    sample batch                         sample batch
    compute reward                       compute reward
    update weights                       update weights
    [expensive]                          [cheap]
         |                                    |
         v                                    v
  Final checkpoint                      Extract rank-1 subspace
  (full cost)                           Fit linear model
                                        Extrapolate to step 1000
                                        (negligible cost)
                                             |
                                             v
                                        Final checkpoint
                                        (same performance)
From exhaustive exploration to predictive geometry: the core shift is treating RLVR not as a stochastic search but as a deterministic trajectory in a low-dimensional subspace.
Expert Assessment
Problem choice: This is a real gap. RLVR training costs are a bottleneck for anyone working on reasoning models, and the field has largely accepted this as unavoidable. The observation that weight trajectories have exploitable structure is non-obvious and practically valuable. It sits at the intersection of optimization geometry and efficient training—a sweet spot.
Method maturity: RELEX is refreshingly simple. No neural networks, no hyperparameter tuning beyond choosing the observation window length. The rank-1 assumption is validated empirically across three models and multiple benchmarks. However, the paper doesn’t deeply explore failure modes—when does the rank-1 assumption break? What happens with different RLVR algorithms (PPO vs GRPO)? The ablation on rank-2 and rank-3 is brief; more analysis of when higher ranks are necessary would strengthen the claims.
Experimental integrity: Baselines are fair—they compare against full RLVR training, not strawmen. The results are consistent across models (1.5B to 8B parameters) and tasks (math, coding, general reasoning). The 10-20x extrapolation claim is backed by actual numbers. One concern: all experiments use Qwen models. Does this generalize to Llama, Mistral, or other architectures? The paper doesn’t test cross-architecture robustness.
Writing quality: The paper is well-structured and the core idea is communicated clearly. The weakness is in the related work section—it doesn’t sufficiently connect to the broader literature on low-rank adaptation (LoRA) and optimization trajectory analysis. The discussion of why RLVR produces rank-1 trajectories is speculative; a deeper theoretical analysis would elevate the contribution from empirical observation to principled understanding.
Verdict: weak accept — Solid empirical contribution with immediate practical value, but lacks theoretical depth and cross-architecture validation.
Takeaways
If you’re training models with any form of iterative optimization (not just RLVR), check if your weight trajectories are low-rank. The technique is simple: save checkpoints, compute deltas, run SVD, look at the singular value spectrum. If the first singular value dominates, you can likely extrapolate. This applies beyond LLMs—think fine-tuning vision models, continual learning, or even hyperparameter optimization trajectories.
The denoising insight is transferable: when extrapolating any noisy iterative process, projecting onto the dominant subspace before extrapolation can prevent noise amplification. This is a general principle for time-series prediction in high-dimensional spaces.
For practitioners: if you’re running expensive RLVR training, implement RELEX as a checkpoint. Run 10-15% of your planned steps, fit the rank-1 model, extrapolate, and validate. If it works, you’ve saved 85% of your compute. If it doesn’t, you’ve lost 15%—a favorable bet.
论文: 2605.21468 作者: Zhepei Wei, Xinyu Zhu, Wei-Lin Chen, Chengsong Huang, Jiaxin Huang, Yu Meng 分类: cs.LG, cs.CL
缺口
带可验证奖励的强化学习(RLVR)已成为提升大语言模型推理能力的标准方法——想想应用于数学和编程任务的 GRPO 或 REINFORCE。
问题在于:RLVR 很贵。
训练运行消耗数千 GPU 小时,实践者别无选择,只能跑完整个轨迹。
先前工作将 RLVR 视为黑盒优化过程,你需要每一步才能达到最终性能。
但如果权重轨迹不是随机噪声呢?
如果存在我们忽略的隐藏结构呢?
本文提问:我们能否通过只观察开头来预测 RLVR 训练的终点?
问题:RLVR 训练昂贵(数千步)
   |
   v
观察:权重轨迹可能具有低秩结构
   |
   v
假设:秩-1 子空间捕获大部分性能增益
   |
   v
方法:从短窗口拟合秩-1 方向 + 线性幅度
   |
   v
证据:15% 观测窗口 -> 10-20倍外推达到完整性能
   |
   v
结论:RLVR 几何可预测;大部分训练是冗余的
增量
一句话: 这篇论文之前,你需要 1000 步 RLVR 训练才能获得 1000 步的性能;
之后,你只需要 50 步加上 30 秒线性代数。
核心机制
RELEX 分三个阶段运作。
首先,运行标准 RLVR 训练一个短观测窗口(比如 1000 步中的 50 步)。
定期保存检查点。
其次,计算连续检查点之间的权重增量,执行 SVD 提取主导方向——捕获大部分方差的秩-1 子空间。
第三,拟合线性回归预测投影到该方向的幅度如何随训练步数增长。
现在外推:取初始检查点,加上秩-1 方向乘以步骤 1000 处的预测幅度,你就得到了外推检查点。
观测窗口(步骤 0-50):
  theta_0 -> theta_10 -> theta_20 -> ... -> theta_50
     |         |           |                    |
     +-------- 计算增量 (delta_i) --------+
                          |
                          v
                  对堆叠增量做 SVD
                          |
                          v
                提取秩-1 方向 (u)
                          |
                          v
          将每个增量投影到 u:alpha_i = delta_i · u
                          |
                          v
            拟合线性模型:alpha = a*step + b
                          |
                          v
      外推到步骤 1000:theta_1000 = theta_0 + alpha_1000 * u
把 RLVR 训练想象成一艘船在海上航行。
传统思维假设你需要航行整条路线才能到达目的地。
RELEX 观察到船实际上在沿着几乎直线移动(秩-1 轨迹),而且速度可预测(线性增长)。
所以与其航行 1000 海里,你航行 50 海里,测量航向和速度,然后传送到 1000 海里处你本该到达的位置。
秩-1 方向是你的罗盘方位,线性回归是你的速度计,外推是传送。
关键洞察:RLVR 不会曲折前进——它早早确定方向并保持下去。
关键概念
- 秩-1 轨迹: 想象你在追踪一个有数百万维度的参数张量。
在每个训练步骤,权重在这个高维空间中沿某个方向移动。
秩-1 轨迹意味着尽管有数百万个可能方向,权重更新本质上沿着单一直线移动。
数学上,如果你把所有权重增量堆叠成矩阵并执行 SVD,第一个奇异值占主导——它捕获 80-90% 的方差。
具体来说,如果你的模型有 15 亿参数,步骤 100 的更新可以近似为:delta_100 ≈ alpha_100 * u,其中 u 是固定的 15 亿维向量(秩-1 方向),alpha_100 是标量(幅度)。
这令人惊讶,因为随机优化通常探索许多方向,但 RLVR 几乎立即收敛到单一主导模式。
- 去噪效应: RLVR 训练涉及随机梯度——每个批次引入噪声。
如果你天真地外推原始权重轨迹,你在放大这种噪声。
RELEX 的秩-1 投影充当过滤器:它保留信号(改进的主导方向)并丢弃噪声(与该方向正交的随机波动)。
想象成平均掉手绘线条中的抖动以揭示底层的直线路径。
论文显示没有这种投影,外推失败——性能在观测窗口之外退化。
有了投影,外推即使在观测步数的 20 倍处也能工作。
框架转变
之前(标准 RLVR):              之后(RELEX):

训练循环(1000 步):            训练循环(50 步):
  for step in 1..1000:            for step in 1..50:
    采样批次                        采样批次
    计算奖励                        计算奖励
    更新权重                        更新权重
    [昂贵]                          [便宜]
         |                               |
         v                               v
  最终检查点                        提取秩-1 子空间
  (全部成本)                      拟合线性模型
                                    外推到步骤 1000
                                    (可忽略成本)
                                         |
                                         v
                                    最终检查点
                                    (相同性能)
从穷举探索到预测几何:核心转变是将 RLVR 视为低维子空间中的确定性轨迹,而非随机搜索。
专家评审
选题眼光: 这是真缺口。
RLVR 训练成本是任何从事推理模型工作者的瓶颈,该领域基本接受这不可避免。
观察到权重轨迹具有可利用结构是非显而易见且实际有价值的。
它位于优化几何和高效训练的交叉点——一个甜蜜点。
方法成熟度: RELEX 简单得令人耳目一新。
没有神经网络,除了选择观测窗口长度外没有超参数调优。
秩-1 假设在三个模型和多个基准上得到经验验证。
然而,论文没有深入探索失败模式——秩-1 假设何时失效?
不同 RLVR 算法(PPO vs GRPO)会怎样?
关于秩-2 和秩-3 的消融简短;更多关于何时需要更高秩的分析会加强主张。
实验诚意: 基线公平——他们与完整 RLVR 训练比较,而非稻草人。
结果在模型(15 亿到 80 亿参数)和任务(数学、编程、通用推理)上一致。
10-20 倍外推声明有实际数字支持。
一个担忧:所有实验使用 Qwen 模型。
这能泛化到 Llama、Mistral 或其他架构吗?
论文没有测试跨架构鲁棒性。
写作功力: 论文结构良好,核心思想传达清晰。
弱点在相关工作部分——它没有充分连接到关于低秩适应(LoRA)和优化轨迹分析的更广泛文献。
关于为什么 RLVR 产生秩-1 轨迹的讨论是推测性的;更深入的理论分析会将贡献从经验观察提升到原则性理解。
判决: 弱接收 — 扎实的经验贡献,具有直接实用价值,但缺乏理论深度和跨架构验证。
要点总结
如果你在用任何形式的迭代优化训练模型(不仅是 RLVR),检查你的权重轨迹是否低秩。
技术很简单:保存检查点,计算增量,运行 SVD,查看奇异值谱。
如果第一个奇异值占主导,你很可能可以外推。
这适用于 LLM 之外——想想微调视觉模型、持续学习,甚至超参数优化轨迹。
去噪洞察可迁移:当外推任何噪声迭代过程时,在外推前投影到主导子空间可以防止噪声放大。
这是高维空间时间序列预测的通用原则。
对实践者:如果你在运行昂贵的 RLVR 训练,将 RELEX 实现为检查点。
运行计划步数的 10-15%,拟合秩-1 模型,外推并验证。
如果有效,你节省了 85% 的计算。
如果无效,你损失了 15%——一个有利的赌注。