Paper: 2604.26934 Authors: Wanyue Zhang, Wenxiang Wu, Wang Xu, Jiaxin Luo, Helu Zhi, Yibin Huang, Shuo Ren, Zitao Liu, Jiajun Zhang Categories: cs.CV
The Gap
Vision-language models excel at describing static images but fail when asked “if I move forward 2 meters, what will I see?” Two camps tried to fix this: (1) synthetic data scaling approaches that generate more training examples but don’t explicitly model how motion transforms scenes, and (2) inference-time coupling where you attach a world model to generate future views on-the-fly, which works but burns compute at every query. The gap: VLMs lack internalized spatial imagination, and existing fixes either skip the motion physics or pay a heavy runtime tax.
Problem: VLMs can't imagine scene evolution under motion
   |
   v
Assumption: World models know motion physics, VLMs need that knowledge baked in
   |
   v
Method: Use world model as teacher during training, not crutch during inference
   |
   v
Evidence: Matches inference-time coupling performance at zero inference cost
   |
   v
Conclusion: Distillation transfers spatial imagination into VLM weights
The Increment
One sentence: Before, VLMs either guessed at spatial outcomes or needed a world model running alongside them at inference; after, they internalize motion-conditioned reasoning during training and answer spatial queries directly.
Core Mechanism
World2VLM has three stages. First, a view-consistent world model (trained on video data) takes an initial image and a camera trajectory, then generates geometrically aligned future frames showing what you’d see after that motion. Second, the framework extracts two types of supervision from these synthetic sequences: forward reasoning (given action, predict outcome) and inverse reasoning (given outcome, infer action). Third, the VLM undergoes two-stage post-training—first on forward tasks to learn action-to-outcome mappings, then on inverse tasks to learn outcome-to-action inference.
Stage 1: World Model Generation
   [Initial Image] + [Camera Trajectory]
          |
          v
   [World Model] --> [Future View Sequence]
          |
          v
   Geometrically consistent frames

Stage 2: Supervision Extraction
   [Future Views] --> Forward: (action, initial) -> outcome
                  --> Inverse: (outcome, initial) -> action

Stage 3: VLM Post-Training
   Phase 1: Forward reasoning tasks
   Phase 2: Inverse reasoning tasks
          |
          v
   [VLM with internalized spatial imagination]
Think of it like teaching someone to navigate by mental simulation. The world model is an experienced guide who can vividly describe what’s around each corner. Instead of having the guide walk alongside the student forever (inference-time coupling), you have the guide create a training course with detailed “if you turn left here, you’ll see X” scenarios. The student practices these scenarios until they can mentally simulate turns themselves. The forward tasks are like “I’m turning left—what will I see?” and the inverse tasks are “I see a red door—what turn got me here?” After enough practice, the student internalizes the spatial logic and no longer needs the guide present.
Key Concepts
-
View-consistent world model: A generative model trained on video that doesn’t just predict any plausible next frame, but specifically predicts frames that maintain geometric consistency with a specified camera motion. If you say “move forward 1 meter,” it generates a frame where objects scale and shift exactly as they would under that motion, not just a visually plausible but geometrically arbitrary scene. This is crucial because spatial reasoning requires geometric precision, not just visual coherence.
-
Forward vs inverse spatial reasoning: Forward reasoning is “given this action, what outcome?” (predictive). Inverse reasoning is “given this outcome, what action caused it?” (diagnostic). Most prior work focuses only on forward, but inverse reasoning is essential for tasks like “which direction should I go to see the fountain?” The VLM needs both directions to build a complete mental model of space.
-
Distillation as internalization: Traditional distillation compresses a large model into a small one. Here, distillation transfers a capability (spatial imagination) from one modality (generative world model) to another (vision-language model). The world model never runs at inference—it’s purely a teacher that creates training data encoding its spatial knowledge. The VLM learns to reproduce that knowledge through its own parameters.
Framework Shift
Before (mainstream approach):        After (this paper):

VLM alone:                           Training time:
[Image] -> [VLM] -> [Guess]          [Image] + [Trajectory]
   ^                                      |
   |                                      v
   No motion model                   [World Model Teacher]
                                          |
OR                                        v
                                     [Synthetic Views]
Inference-time coupling:                  |
[Image] + [Action]                        v
   |                                 [Forward + Inverse Tasks]
   v                                      |
[World Model] -> [Future View]            v
   |                                 [VLM Post-Training]
   v                                      |
[VLM] -> [Answer]                         v
   ^                                 Inference time:
   |                                 [Image] + [Query]
   Expensive at every query               |
                                          v
                                     [VLM] -> [Answer]
                                          ^
                                          |
                                     Knowledge baked in
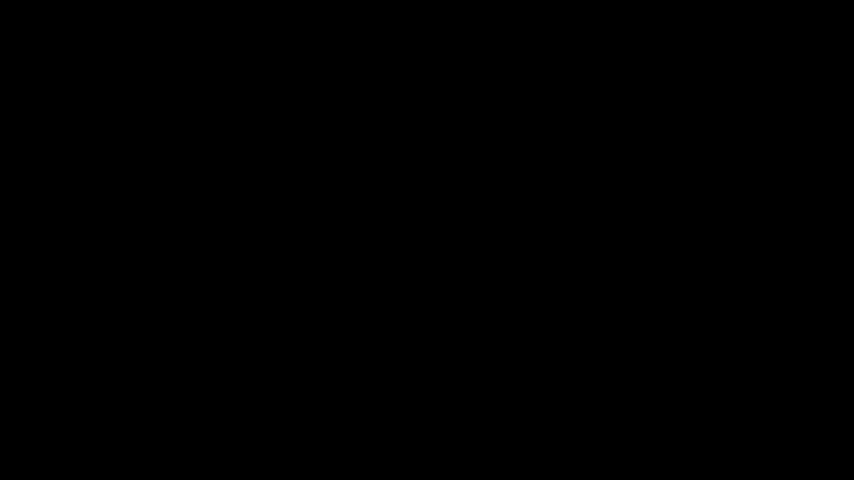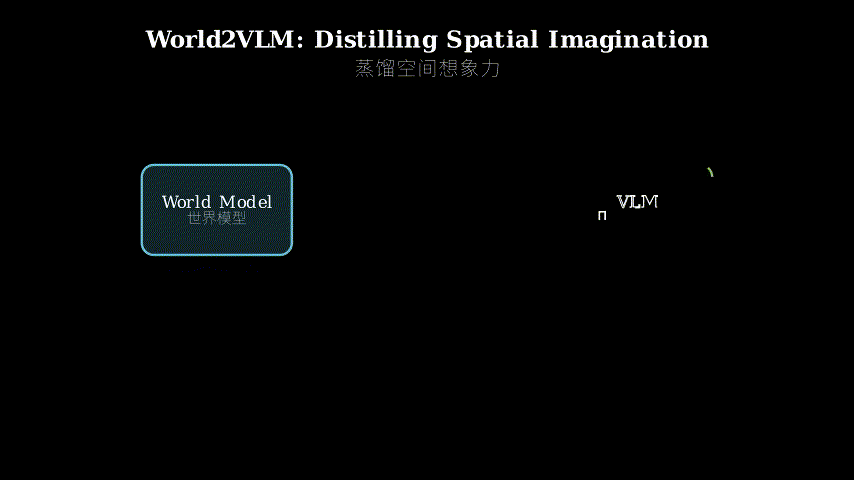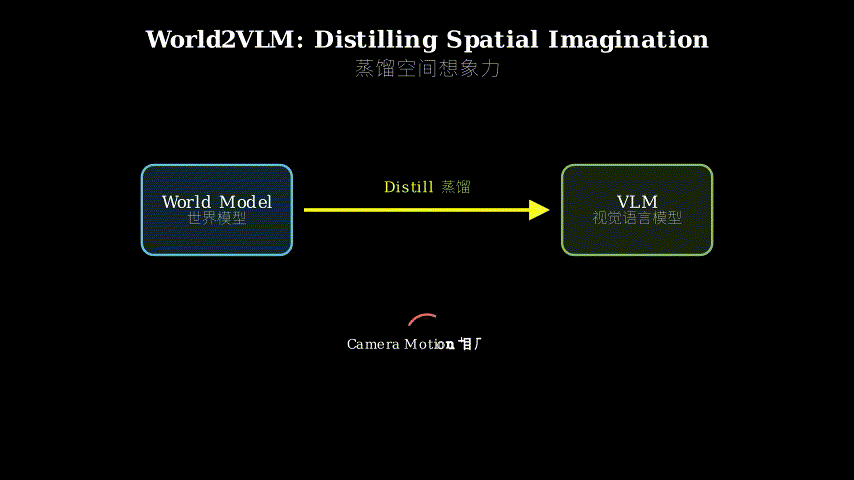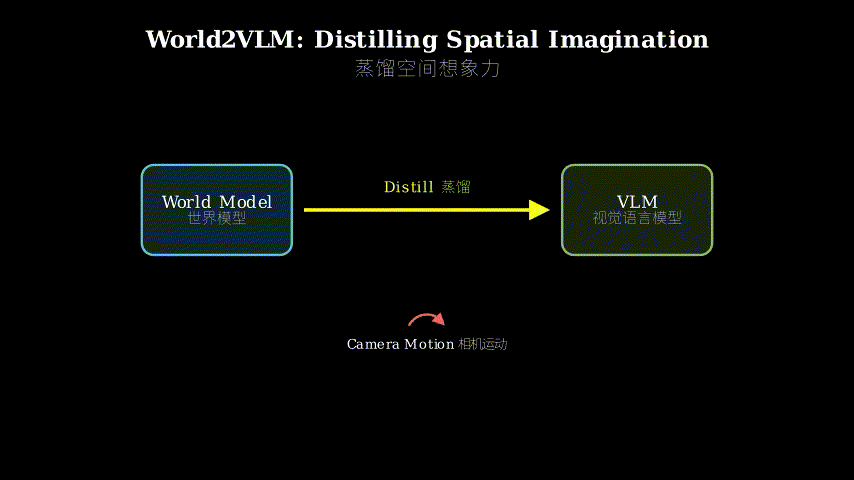
From runtime dependency to training-time knowledge transfer, the core shift is moving the world model from inference partner to training teacher.
Expert Assessment
Problem choice: Real gap. VLMs demonstrably struggle with spatial reasoning (well-documented in SAT, VSI-Bench benchmarks), and the two existing solutions have clear tradeoffs. This isn’t manufactured—it’s a natural next step after observing that inference-time coupling works but doesn’t scale.
Method maturity: Clever insight with solid execution. The two-stage training (forward then inverse) shows thoughtful design—inverse reasoning is harder and benefits from forward priming. The use of a view-consistent world model (not just any video generator) is the right tool for the job. However, the paper doesn’t explore whether simpler motion models (e.g., depth-based warping) could provide similar supervision at lower cost. That’s a missed ablation.
Experimental integrity: Baselines are fair and comprehensive (base VLM, synthetic data scaling, inference-time coupling). The improvements are consistent across four benchmarks, which is strong evidence. One concern: the world model quality ceiling—if the teacher hallucinates geometry, does the student learn bad habits? The paper doesn’t deeply probe failure modes or show where distillation degrades the world model’s knowledge.
Writing quality: The method section is clear, but the related work undersells the novelty. The paper frames this as “distillation” but it’s really cross-modal capability transfer, which is conceptually richer. The ablation section (if expanded) could show which components matter most—is it the view consistency, the two-stage training, or the inverse tasks?
Verdict: weak accept — Solid contribution that advances VLM spatial reasoning with a practical training recipe, though the evaluation could probe failure modes more deeply and the method could be positioned more boldly.
Takeaways
The two-stage training recipe (forward then inverse) is immediately transferable to other domains where you want to teach a model bidirectional reasoning—train prediction first, then diagnosis. The broader idea: if you have a strong simulator (world model, physics engine, theorem prover) that’s too slow for inference, use it to generate structured training data that encodes its knowledge, then distill that into a faster model. This is more efficient than either ignoring the simulator or running it at inference. Specifically for robotics or embodied AI: this pattern of using generative models as training-time teachers rather than inference-time tools could unlock better sample efficiency.
论文: 2604.26934 作者: Wanyue Zhang, Wenxiang Wu, Wang Xu, Jiaxin Luo, Helu Zhi, Yibin Huang, Shuo Ren, Zitao Liu, Jiajun Zhang 分类: cs.CV
缺口
视觉语言模型擅长描述静态图像,但如果问”我向前走2米会看到什么?”就抓瞎了。
两派人试图修复: (1) 合成数据扩展派生成更多训练样本,但不显式建模运动如何变换场景;
(2) 推理时耦合派在每次查询时挂一个世界模型实时生成未来视图,有效但烧算力。
缺口在于: VLM缺乏内化的空间想象力,现有修复要么跳过运动物理,要么在运行时付出沉重代价。
问题: VLM无法想象运动下的场景演化
   |
   v
假设: 世界模型懂运动物理,VLM需要把这知识烤进去
   |
   v
方法: 训练时用世界模型当老师,而非推理时当拐杖
   |
   v
证据: 零推理成本达到推理时耦合的性能
   |
   v
结论: 蒸馏把空间想象力转移到VLM权重里
增量
一句话: 之前VLM要么瞎猜空间结果要么推理时需要世界模型陪跑;
之后它们在训练时内化运动条件推理,直接回答空间查询。
核心机制
World2VLM分三阶段。
第一阶段,视图一致世界模型(在视频数据上训练)接收初始图像和相机轨迹,生成几何对齐的未来帧序列,展示该运动后你会看到什么。
第二阶段,框架从这些合成序列中提取两类监督: 正向推理(给定动作预测结果)和逆向推理(给定结果推断动作)。
第三阶段,VLM经历两阶段后训练——先在正向任务上学习动作到结果的映射,再在逆向任务上学习结果到动作的推断。
阶段1: 世界模型生成
   [初始图像] + [相机轨迹]
          |
          v
   [世界模型] --> [未来视图序列]
          |
          v
   几何一致的帧

阶段2: 监督提取
   [未来视图] --> 正向: (动作, 初始) -> 结果
              --> 逆向: (结果, 初始) -> 动作

阶段3: VLM后训练
   第1阶段: 正向推理任务
   第2阶段: 逆向推理任务
          |
          v
   [内化空间想象力的VLM]
把它想象成通过心理模拟教人导航。
世界模型是经验丰富的向导,能生动描述每个拐角后的景象。
与其让向导永远陪着学生走(推理时耦合),不如让向导创建一个训练课程,包含详细的”如果你在这里左转会看到X”场景。
学生练习这些场景直到能自己心理模拟转弯。
正向任务像”我左转——会看到什么?”逆向任务像”我看到红门——什么转弯让我到这?”练够了,学生内化空间逻辑,不再需要向导在场。
关键概念
- 视图一致世界模型: 在视频上训练的生成模型,不只是预测任何合理的下一帧,而是专门预测与指定相机运动保持几何一致的帧。
如果你说”向前移动1米”,它生成的帧中物体的缩放和位移完全符合该运动,而非只是视觉上合理但几何上随意的场景。
这很关键,因为空间推理需要几何精度,不只是视觉连贯性。
- 正向vs逆向空间推理: 正向推理是”给定动作,什么结果?”(预测性)。
逆向推理是”给定结果,什么动作导致?”(诊断性)。
多数先前工作只关注正向,但逆向推理对”我该往哪个方向走才能看到喷泉?”这类任务至关重要。
VLM需要双向才能构建完整的空间心智模型。
- 蒸馏即内化: 传统蒸馏把大模型压缩成小模型。
这里蒸馏是把能力(空间想象)从一种模态(生成式世界模型)转移到另一种(视觉语言模型)。
世界模型推理时从不运行——它纯粹是创建训练数据编码其空间知识的老师。
VLM学会通过自己的参数复现那些知识。
框架转变
之前(主流方法):                  之后(本文方法):

单独VLM:                         训练时:
[图像] -> [VLM] -> [瞎猜]        [图像] + [轨迹]
   ^                                  |
   |                                  v
   无运动模型                    [世界模型教师]
                                      |
或                                    v
                                 [合成视图]
推理时耦合:                           |
[图像] + [动作]                       v
   |                             [正向+逆向任务]
   v                                  |
[世界模型] -> [未来视图]              v
   |                             [VLM后训练]
   v                                  |
[VLM] -> [答案]                       v
   ^                             推理时:
   |                             [图像] + [查询]
   每次查询都昂贵                     |
                                      v
                                 [VLM] -> [答案]
                                      ^
                                      |
                                 知识已烤入
从运行时依赖到训练时知识转移,核心转变是把世界模型从推理伙伴变成训练教师。
专家评审
选题眼光: 真缺口。
VLM在空间推理上的挣扎有充分记录(SAT、VSI-Bench基准测试),现有两种解决方案有明显权衡。
这不是人造的——观察到推理时耦合有效但不可扩展后,这是自然的下一步。
方法成熟度: 巧妙洞察加扎实执行。
两阶段训练(先正向后逆向)显示深思熟虑的设计——逆向推理更难,受益于正向打底。
使用视图一致世界模型(而非随便什么视频生成器)是正确的工具选择。
但论文没探索更简单的运动模型(如基于深度的变形)能否以更低成本提供类似监督。
这是缺失的消融实验。
实验诚意: 基线公平且全面(基础VLM、合成数据扩展、推理时耦合)。
四个基准测试上的改进一致,是强有力的证据。
一个担忧: 世界模型质量天花板——如果教师产生几何幻觉,学生会学到坏习惯吗?论文没深入探究失败模式或展示蒸馏在哪里降解世界模型的知识。
写作功力: 方法部分清晰,但相关工作低估了新颖性。
论文把这框定为”蒸馏”,但实际是跨模态能力转移,概念上更丰富。
消融部分(如果扩展)能展示哪些组件最重要——是视图一致性、两阶段训练还是逆向任务?
判决: 弱接收——用实用训练配方推进VLM空间推理的扎实贡献,但评估可以更深入探究失败模式,方法可以定位得更大胆。
要点总结
两阶段训练配方(先正向后逆向)可直接迁移到其他想教模型双向推理的领域——先训练预测,再训练诊断。
更广泛的想法: 如果你有强大但推理太慢的模拟器(世界模型、物理引擎、定理证明器),用它生成编码其知识的结构化训练数据,然后蒸馏到更快的模型。
这比忽略模拟器或推理时运行它都更高效。
具体到机器人或具身AI: 这种用生成模型当训练时教师而非推理时工具的模式,可能解锁更好的样本效率。