Paper: 2602.21189 Authors: Anas Barakat, Souradip Chakraborty, Khushbu Pahwa, Amrit Singh Bedi Categories: cs.LG, cs.AI
Abstract
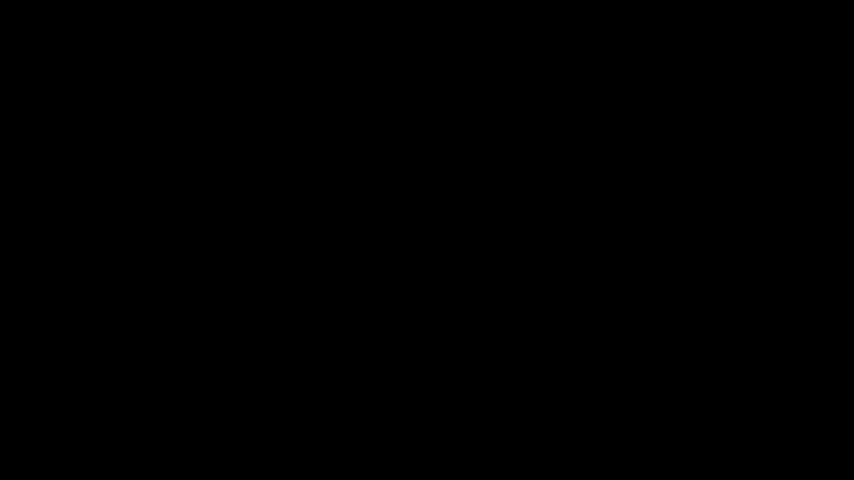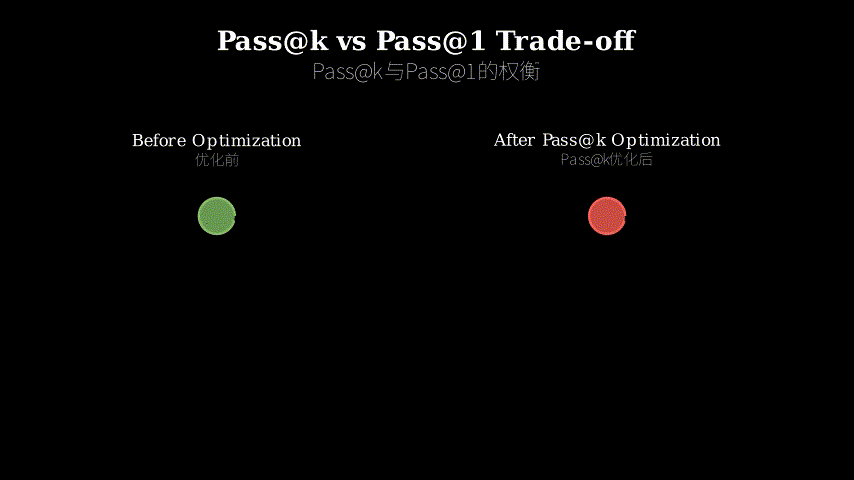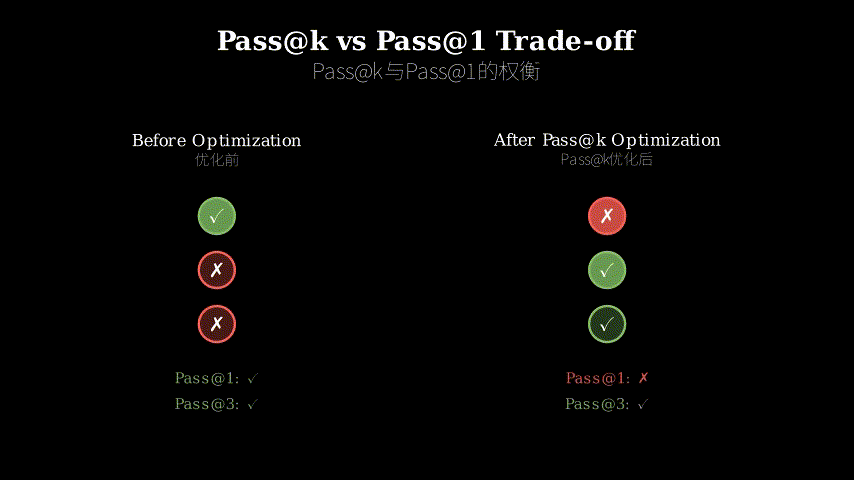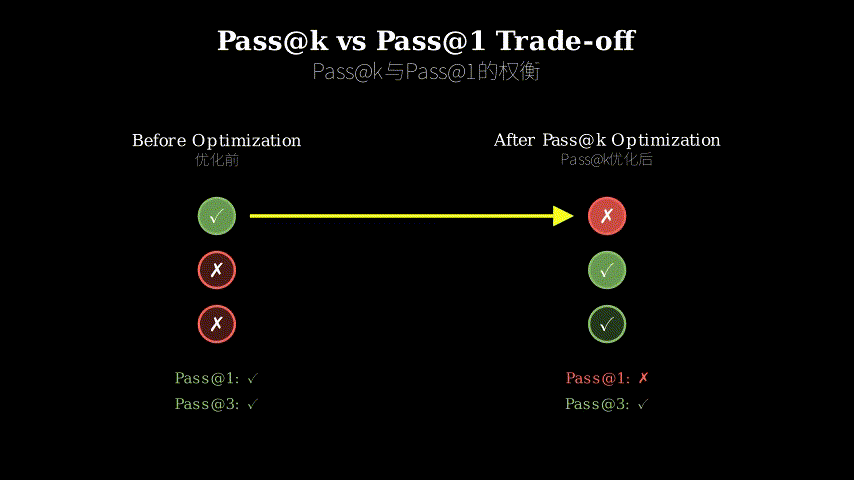
Pass@k is a critical evaluation metric for verifiable LLM tasks such as mathematical reasoning, code generation, and short-answer problems, where success is achieved if any of independently sampled solutions passes verification. While this metric has inspired inference-aware fine-tuning methods that directly optimize pass@k performance, a persistent paradox has emerged: improvements in pass@k often come at the cost of degraded pass@1 performance. This paper provides the first theoretical characterization of this trade-off, demonstrating that pass@k policy optimization can reduce pass@1 through gradient conflicts induced by prompt interference. The authors show that pass@k optimization implicitly reweights the training distribution toward low-success prompts, and when these prompts exhibit negative interference properties, the resulting gradient updates can diverge from the pass@1 optimization direction.
Key Contributions
- Theoretical Framework: Establishes a formal characterization of when and why pass@k optimization degrades pass@1 performance through gradient conflict analysis
- Prompt Interference Concept: Introduces the notion of “negatively interfering prompts” that cause gradient directions to diverge between pass@k and pass@1 objectives
- Implicit Reweighting Mechanism: Reveals that pass@k optimization inherently upweights difficult, low-success prompts in the gradient computation
- Empirical Validation: Demonstrates theoretical predictions on mathematical reasoning tasks using large language models
The Pass@k vs Pass@1 Trade-off
The pass@k metric evaluates whether at least one solution among samples succeeds, making it particularly relevant for scenarios where multiple attempts are feasible. However, pass@1 remains operationally critical due to:
- Latency constraints: Generating multiple samples increases inference time
- Cost considerations: Each additional sample incurs computational expense
- Verifier limitations: Not all tasks have perfect automated verifiers
- Fallback requirements: Systems need reliable single-shot performance
The paper formalizes this tension by analyzing the policy gradient objectives. For pass@1, the gradient encourages increasing the probability of correct solutions. For pass@k, the gradient is weighted by , where is the success probability. This weighting factor is larger for prompts with lower success rates, effectively prioritizing improvement on difficult examples.
Gradient Conflict and Prompt Interference
The core theoretical insight centers on gradient conflict between pass@k and pass@1 objectives. The authors prove that pass@k gradients can point away from pass@1 gradients when:
This occurs through prompt interference: when optimizing on a mixture of prompts, gradients from different prompts can conflict. Specifically, “negatively interfering prompts” are those where improving performance on one prompt degrades performance on another. Since pass@k optimization upweights low-success prompts, if these prompts negatively interfere with high-success prompts, the overall gradient update can harm pass@1 performance.
The mathematical formulation shows that the pass@k gradient can be decomposed as:
where assigns higher weight to prompts with lower success probability . When these heavily weighted prompts have gradients that conflict with the pass@1 direction, degradation occurs.
Experimental Validation
The authors validate their theoretical predictions through experiments on mathematical reasoning tasks using large language models. Key findings include:
- Observed Trade-off: Pass@k optimization consistently improves pass@k metrics while degrading pass@1 performance across different model sizes and datasets
- Gradient Analysis: Empirical measurements confirm negative cosine similarity between pass@k and pass@1 gradients during training
- Prompt-Level Effects: Low-success prompts indeed receive disproportionate gradient weight, and their optimization conflicts with high-success prompt optimization
- Magnitude of Degradation: The pass@1 degradation is not negligible, often representing several percentage points of accuracy loss
Takeaways
-
Optimizing pass@k directly can harm pass@1 performance due to fundamental gradient conflicts, not implementation issues or hyperparameter choices.
-
The root cause is prompt interference: pass@k optimization implicitly reweights toward difficult prompts, and when these prompts negatively interfere with easier ones, gradient directions diverge.
-
Pass@1 remains practically essential despite the appeal of pass@k metrics, as real-world deployments face latency, cost, and verifier coverage constraints.
-
Future optimization methods should explicitly address this trade-off, potentially through multi-objective optimization, prompt-aware gradient balancing, or constrained optimization that maintains pass@1 performance.
-
The theoretical framework generalizes beyond specific tasks, applying to any verifiable LLM application where multi-sample inference is considered.
论文: 2602.21189 作者: Anas Barakat, Souradip Chakraborty, Khushbu Pahwa, Amrit Singh Bedi 分类: cs.LG, cs.AI
摘要
Pass@k是可验证大语言模型任务的关键评估指标,广泛应用于数学推理、代码生成和简答题等场景,其定义为在个独立采样的解决方案中至少有一个通过验证即为成功。虽然这一指标激发了直接优化pass@k性能的推理感知微调方法,但一个持续存在的悖论浮现出来:pass@k的提升往往以pass@1性能下降为代价。本文首次从理论上刻画了这种权衡关系,证明pass@k策略优化可以通过提示干扰引发的梯度冲突来降低pass@1性能。作者表明,pass@k优化隐式地将训练分布重新加权到低成功率提示上,当这些提示表现出负干扰特性时,产生的梯度更新会偏离pass@1优化方向。
主要贡献
- 理论框架: 建立了pass@k优化何时以及为何通过梯度冲突分析降低pass@1性能的形式化刻画
- 提示干扰概念: 引入”负干扰提示”的概念,这类提示导致pass@k和pass@1目标之间的梯度方向发散
- 隐式重加权机制: 揭示pass@k优化在梯度计算中固有地提升困难、低成功率提示的权重
- 实证验证: 在使用大语言模型的数学推理任务上验证理论预测
Pass@k与Pass@1的权衡
Pass@k指标评估个样本中是否至少有一个成功,这使其特别适用于允许多次尝试的场景。然而,pass@1在操作层面仍然至关重要,原因包括:
- 延迟约束: 生成多个样本会增加推理时间
- 成本考虑: 每个额外样本都会产生计算开销
- 验证器局限: 并非所有任务都有完美的自动验证器
- 后备需求: 系统需要可靠的单次性能
论文通过分析策略梯度目标形式化了这种张力。对于pass@1,梯度鼓励增加正确解的概率。对于pass@k,梯度由加权,其中是成功概率。这个加权因子对于成功率较低的提示更大,实际上优先改进困难样本。
梯度冲突与提示干扰
核心理论洞察集中在pass@k和pass@1目标之间的梯度冲突上。作者证明,当满足以下条件时,pass@k梯度可能指向与pass@1梯度相反的方向:
这通过提示干扰发生:在混合提示上优化时,来自不同提示的梯度可能冲突。具体而言,“负干扰提示”是指在一个提示上提升性能会降低另一个提示性能的情况。由于pass@k优化提升了低成功率提示的权重,如果这些提示与高成功率提示负干扰,整体梯度更新可能损害pass@1性能。
数学表述显示pass@k梯度可以分解为:
其中为成功概率较低的提示分配更高权重。当这些高权重提示的梯度与pass@1方向冲突时,就会发生性能退化。
实验验证
作者通过在数学推理任务上使用大语言模型的实验验证了理论预测。主要发现包括:
- 观察到的权衡: 在不同模型规模和数据集上,pass@k优化持续改进pass@k指标,同时降低pass@1性能
- 梯度分析: 实证测量证实训练期间pass@k和pass@1梯度之间存在负余弦相似度
- 提示级效应: 低成功率提示确实获得不成比例的梯度权重,其优化与高成功率提示优化冲突
- 退化幅度: pass@1退化并非微不足道,通常代表几个百分点的准确率损失
要点总结
-
直接优化pass@k可能损害pass@1性能, 这是由于基本的梯度冲突,而非实现问题或超参数选择。
-
根本原因是提示干扰: pass@k优化隐式地重新加权到困难提示,当这些提示与简单提示负干扰时,梯度方向发散。
-
Pass@1在实践中仍然至关重要, 尽管pass@k指标很有吸引力,但现实部署面临延迟、成本和验证器覆盖约束。
-
未来的优化方法应明确处理这种权衡, 可能通过多目标优化、提示感知梯度平衡或维持pass@1性能的约束优化。
-
理论框架超越特定任务, 适用于任何考虑多样本推理的可验证大语言模型应用。