Paper: 2605.00817 Authors: Sailesh Panda, Pritam Kadasi, Abhishek Upperwal, Mayank Singh Categories: cs.CL
The Gap
Existing LLM evaluation focuses on final-answer accuracy on reasoning benchmarks like GSM8K or MATH. Models score 80-90% on these tasks, leading to claims about emergent reasoning abilities. But final correctness doesn’t reveal whether models actually follow the procedure specified in the prompt, or just pattern-match their way to plausible answers.
Prior work on chain-of-thought and step-by-step reasoning assumes that if a model produces intermediate steps and gets the right answer, it must be executing the procedure. No one systematically tested whether models can faithfully execute explicit, step-by-step algorithms when the procedure itself is the constraint, not just a scaffold for reasoning.
Problem: High benchmark scores hide execution failures
   |
   v
Assumption: Final accuracy != procedural faithfulness
   |
   v
Method: Controlled diagnostic with explicit algorithms
   |         (simple ops, variable length, dependencies)
   v
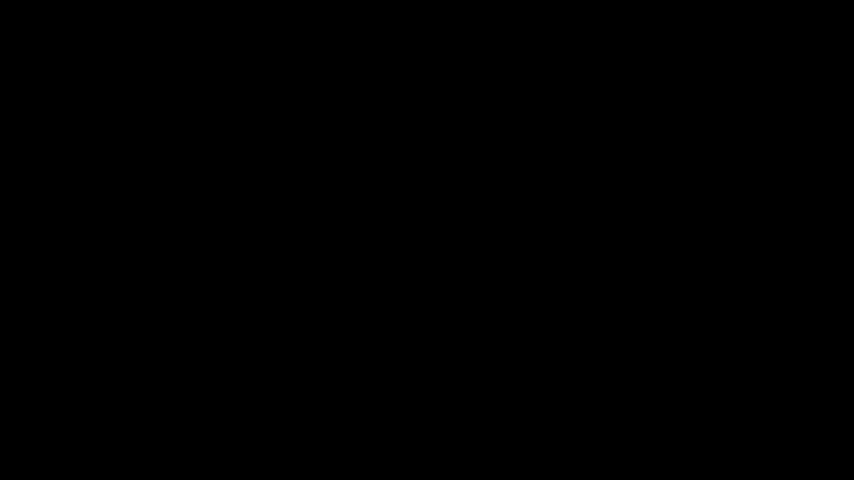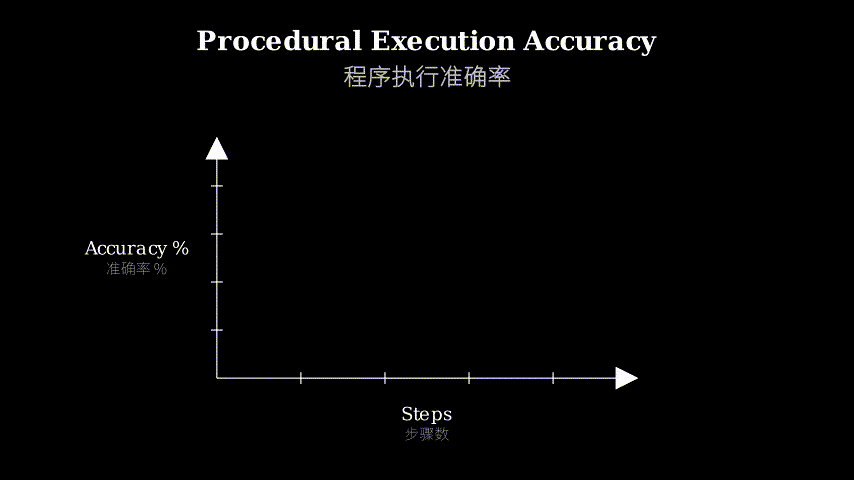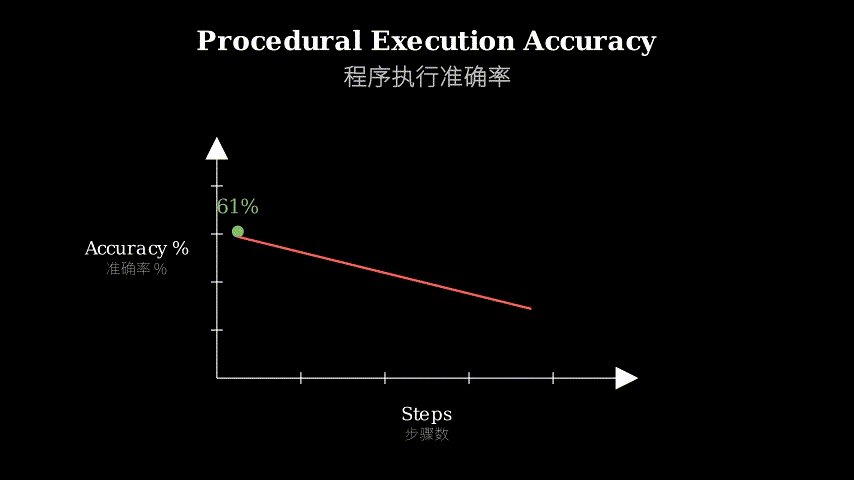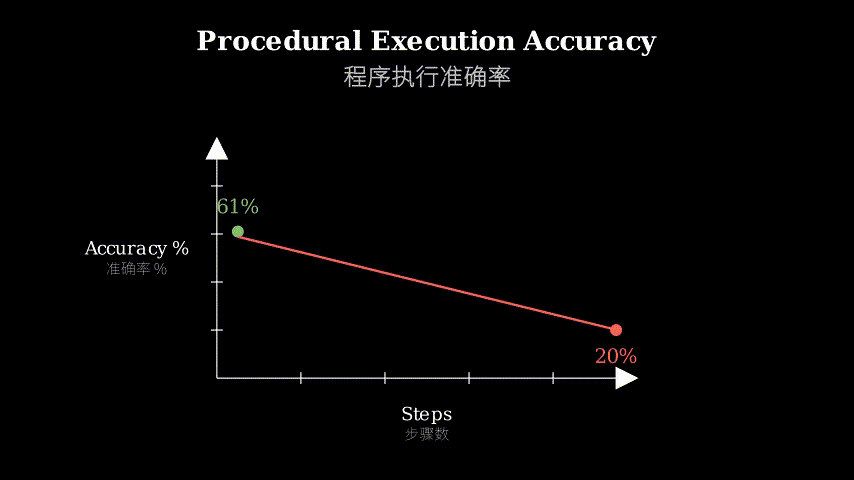
Evidence: 61% -> 20% accuracy as steps increase 5 -> 95
   |         Missing answers, premature stops, hallucinations
   v
Conclusion: Reasoning ability masks instruction-following weakness
The Increment
One sentence: Before this paper, we measured whether LLMs get the right answer; after, we know they systematically fail to execute the procedure that produces it.
Core Mechanism
The benchmark constructs algorithmic procedures from simple arithmetic operations (add, subtract, multiply, divide, modulo). Each algorithm takes two numeric inputs and produces a final value through a sequence of steps. Steps reference intermediate variables from earlier in the procedure, creating look-back dependencies.
Complexity scales along two axes: algorithm length (5 to 95 steps) and dependency depth (how far back a step must look to find its operands). The operations themselves remain trivial—third-grade arithmetic—so failure cannot be blamed on mathematical difficulty. The challenge is pure procedural execution: read the algorithm, track variables, apply operations in order, return the final value.
The authors test 14 models across 55 datasets, analyzing not just final accuracy but generation-level failures: missing answers (model stops without output), premature answers (returns a value mid-procedure), self-correction (gives wrong answer, then corrects it), under-execution (skips steps), and hallucinated extra steps.
Input Algorithm:
  Step 1: a = input1 + input2
  Step 2: b = a * 3
  Step 3: c = b - input1
  Step 4: return c
         |
         v
    [LLM processes]
         |
         v
   Generation trace:
   "Step 1: a = 5 + 3 = 8
    Step 2: b = 8 * 3 = 24
    Step 3: c = 24 - 5 = 19
    Answer: 19"
         |
         v
   Diagnostic analysis:
   - Correct final answer?
   - All steps present?
   - Steps in order?
   - Correct intermediate values?
   - Premature termination?
   - Hallucinated steps?
Think of this like testing a sous chef. You don’t just taste the final dish and declare them competent. You hand them a recipe with explicit steps—dice onions, sauté for 3 minutes, add garlic, deglaze with wine—and watch whether they follow it. The recipe uses basic techniques (chopping, heating), so failure means they can’t follow instructions, not that the techniques are too hard.
The benchmark is the recipe. The arithmetic operations are the basic techniques. The model is the sous chef. And the diagnostic reveals that as recipes get longer, the chef starts skipping steps, adding random ingredients, or serving the dish before it’s done—even though each individual technique is trivial.
Key Concepts
-
Procedural faithfulness: The model’s ability to execute the exact sequence of operations specified in a prompt, independent of whether the final answer is correct. A model can get the right answer through shortcuts or pattern matching without following the procedure. Conversely, it can follow every step correctly but make an arithmetic error. Faithfulness measures adherence to process, not outcome. Example: If the prompt says “multiply by 3, then add 5,” a faithful model must perform those operations in that order, even if it could reach the same result by adding 5 first and then multiplying.
-
Look-back dependencies: When a step in an algorithm references variables computed in earlier steps, it creates a dependency chain. Step 5 might use the result from Step 2 and Step 4. As dependency depth increases (referencing steps further back), the model must maintain a longer working memory of intermediate values. This is distinct from algorithm length—a 10-step procedure where each step only uses the previous step has shallow dependencies, while a 10-step procedure where Step 10 uses Step 1 has deep dependencies.
-
Generation-level failure modes: Beyond binary correct/incorrect, the paper categorizes how models fail during generation. Missing answers: the model produces reasoning steps but never outputs a final value. Premature answers: it returns a value before completing all steps. Self-correction: it gives an answer, then continues generating and changes it. Under-execution: it skips steps in the middle. Hallucinated steps: it invents operations not in the algorithm. These patterns reveal that models don’t just make calculation errors—they lose track of the procedural structure itself.
Framework Shift
Before (mainstream evaluation):        After (this paper):

Prompt: "Solve this problem"          Prompt: "Execute this algorithm"
   |                                      |
   v                                      v
[LLM generates reasoning]              Step 1: a = x + y
   |                                   Step 2: b = a * 2
   v                                   Step 3: return b
Final answer: 42                          |
   |                                      v
   v                                   [LLM must follow exactly]
Metric: Is 42 correct?                    |
   |                                      v
   v                                   Metrics:
Conclusion: Model can reason           - Correct final value?
                                       - All steps executed?
                                       - Correct order?
                                       - No hallucinations?
                                          |
                                          v
                                       Conclusion: Model struggles
                                       with procedural control
From outcome-based evaluation to process-based diagnosis, the core shift is separating “getting the right answer” from “following the instructions.”
Expert Assessment
Problem choice: This is a real gap. The field has been measuring reasoning through final-answer accuracy on increasingly complex benchmarks, but no one isolated procedural execution as a distinct capability. The problem sits at a critical juncture—as we deploy LLMs for tasks requiring faithful instruction-following (code execution, tool use, multi-step workflows), we need to know whether high benchmark scores reflect genuine procedural competence or clever pattern matching. The authors didn’t manufacture this gap; they exposed an assumption everyone was making.
Method maturity: Elegant in its simplicity. Using trivial arithmetic operations removes confounding factors (mathematical difficulty, domain knowledge) and isolates procedural control. The two-axis scaling (length and dependency depth) is well-motivated. However, the paper could have explored whether failure modes differ across operation types or whether certain dependency patterns are harder than others. The diagnostic categories (missing answers, premature answers, etc.) are useful but somewhat ad-hoc—a more principled taxonomy of failure modes would strengthen the analysis.
Experimental integrity: Baselines are fair—14 models spanning different architectures and sizes, 55 datasets with controlled variation. The numbers are stark and consistent across models, which increases confidence. One concern: all algorithms are deterministic and have a single correct answer. Real-world procedures often involve conditional logic, loops, or ambiguous specifications. The paper’s scope is narrow by design, but this limits generalization. The generation-level analysis is thorough, though manual inspection of failure modes on a subset of outputs introduces some subjectivity.
Writing quality: The paper is clear and well-structured. The introduction motivates the problem effectively, and the results section presents findings without overselling. The weakest section is the discussion—it gestures at implications for reasoning and instruction-following but doesn’t deeply engage with why models fail this way or what architectural changes might help. Rewriting the discussion to propose mechanistic hypotheses (attention span limitations? training data biases toward shortcuts?) would elevate the paper from diagnostic to generative.
Verdict: weak accept — Identifies a real and underexplored weakness in LLMs with a clean experimental design, but stops short of explaining why the weakness exists or how to fix it.
Takeaways
If you’re building systems that rely on LLMs to follow multi-step procedures—agents, workflow automation, code interpreters—don’t trust final-answer accuracy as a proxy for faithful execution. Test explicitly for procedural adherence, especially as task length increases.
The failure modes (premature answers, under-execution, hallucinations) suggest that LLMs lose track of procedural state as context grows. If your application requires long procedures, consider breaking them into smaller sub-procedures with explicit checkpoints, or use external state management (a scratchpad, a database) rather than relying on the model’s context window.
The diagnostic framework itself is portable: take a capability you care about, design a minimal test that isolates it from confounding factors, and scale complexity along controlled axes. This paper’s value isn’t the specific finding about arithmetic procedures—it’s the template for exposing gaps between benchmark performance and actual capability.
论文: 2605.00817 作者: Sailesh Panda, Pritam Kadasi, Abhishek Upperwal, Mayank Singh 分类: cs.CL
缺口
现有的大语言模型评估聚焦于推理基准(如GSM8K或MATH)上的最终答案准确率。
模型在这些任务上得分80-90%,导致关于”涌现推理能力”的说法。
但最终正确性并不能揭示模型是否真的遵循了提示中指定的程序,还是只是模式匹配出了看似合理的答案。
关于思维链和逐步推理的先前工作假设:如果模型产生中间步骤并得到正确答案,它一定在执行程序。
没有人系统地测试过,当程序本身是约束(而非仅仅是推理的脚手架)时,模型能否忠实执行明确的、逐步的算法。
问题:高基准分数掩盖了执行失败
   |
   v
假设:最终准确率 != 程序忠实度
   |
   v
方法:用明确算法进行受控诊断
   |    (简单操作、可变长度、依赖关系)
   v
证据:随步骤从5增至95,准确率从61%降至20%
   |    缺失答案、提前停止、幻觉
   v
结论:推理能力掩盖了指令遵循的弱点
增量
一句话:这篇论文之前,我们测量大模型是否得到正确答案;之后,我们知道它们系统性地无法执行产生答案的程序。
核心机制
该基准从简单的算术运算(加、减、乘、除、取模)构建算法程序。
每个算法接受两个数字输入,通过一系列步骤产生最终值。
步骤引用程序中较早的中间变量,创建回溯依赖。
复杂度沿两个轴扩展:算法长度(5到95步)和依赖深度(一个步骤必须回溯多远才能找到其操作数)。
操作本身保持简单——小学三年级算术——因此失败不能归咎于数学难度。
挑战是纯粹的程序执行:读取算法、跟踪变量、按顺序应用操作、返回最终值。
作者在55个数据集上测试了14个模型,不仅分析最终准确率,还分析生成级别的失败:缺失答案(模型停止而不输出)、提前答案(在程序中途返回值)、自我纠正(给出错误答案后纠正)、执行不足(跳过步骤)和幻觉额外步骤。
输入算法:
  步骤1:a = input1 + input2
  步骤2:b = a * 3
  步骤3:c = b - input1
  步骤4:返回 c
         |
         v
    [大模型处理]
         |
         v
   生成轨迹:
   "步骤1:a = 5 + 3 = 8
    步骤2:b = 8 * 3 = 24
    步骤3:c = 24 - 5 = 19
    答案:19"
         |
         v
   诊断分析:
   - 最终答案正确?
   - 所有步骤都存在?
   - 步骤顺序正确?
   - 中间值正确?
   - 提前终止?
   - 幻觉步骤?
把这想象成测试一个副厨师。
你不只是品尝最终的菜肴就宣布他们称职。
你递给他们一份有明确步骤的食谱——切洋葱丁、炒3分钟、加蒜、用酒收汁——然后观察他们是否遵循。
食谱使用基本技术(切、加热),所以失败意味着他们不能遵循指令,而不是技术太难。
基准就是食谱。
算术运算是基本技术。
模型是副厨师。
诊断揭示:随着食谱变长,厨师开始跳过步骤、添加随机配料,或在菜做好之前就上菜——尽管每个单独的技术都很简单。
关键概念
- 程序忠实度:模型执行提示中指定的确切操作序列的能力,独立于最终答案是否正确。
模型可以通过捷径或模式匹配得到正确答案而不遵循程序。
相反,它可以正确遵循每一步但犯算术错误。
忠实度衡量对过程的遵守,而非结果。
例如:如果提示说”乘以3,然后加5”,忠实的模型必须按该顺序执行这些操作,即使它可以通过先加5再乘以达到相同结果。
- 回溯依赖:当算法中的一个步骤引用较早步骤中计算的变量时,它创建了一个依赖链。
步骤5可能使用步骤2和步骤4的结果。
随着依赖深度增加(引用更早的步骤),模型必须维护更长的中间值工作记忆。
这与算法长度不同——一个10步程序,每步只使用前一步,具有浅依赖,而一个10步程序,步骤10使用步骤1,具有深依赖。
- 生成级别的失败模式:除了二元的正确/错误,论文对模型在生成过程中如何失败进行分类。
缺失答案:模型产生推理步骤但从不输出最终值。
提前答案:在完成所有步骤之前返回值。
自我纠正:给出答案,然后继续生成并更改它。
执行不足:跳过中间步骤。
幻觉步骤:发明算法中没有的操作。
这些模式揭示模型不只是犯计算错误——它们失去了对程序结构本身的跟踪。
框架转变
之前(主流评估):                之后(本文方法):

提示:"解决这个问题"             提示:"执行这个算法"
   |                                |
   v                                v
[大模型生成推理]                  步骤1:a = x + y
   |                              步骤2:b = a * 2
   v                              步骤3:返回 b
最终答案:42                         |
   |                                v
   v                             [大模型必须精确遵循]
指标:42正确吗?                     |
   |                                v
   v                             指标:
结论:模型能推理                  - 最终值正确?
                                 - 所有步骤执行?
                                 - 顺序正确?
                                 - 无幻觉?
                                    |
                                    v
                                 结论:模型在程序
                                 控制上挣扎
从基于结果的评估到基于过程的诊断,核心转变是将”得到正确答案”与”遵循指令”分离。
专家评审
选题眼光:这是一个真实的缺口。
该领域一直通过越来越复杂的基准上的最终答案准确率来衡量推理,但没有人将程序执行作为一种独特的能力来隔离。
这个问题处于关键节点——当我们部署大模型用于需要忠实指令遵循的任务(代码执行、工具使用、多步骤工作流)时,我们需要知道高基准分数是否反映真正的程序能力还是巧妙的模式匹配。
作者没有制造这个缺口;他们揭露了每个人都在做的假设。
方法成熟度:简洁优雅。
使用简单的算术运算消除了混淆因素(数学难度、领域知识),隔离了程序控制。
双轴扩展(长度和依赖深度)动机充分。
然而,论文可以探索失败模式是否在不同操作类型之间有所不同,或某些依赖模式是否比其他模式更难。
诊断类别(缺失答案、提前答案等)有用但有些临时——更有原则的失败模式分类法会加强分析。
实验诚意:基线公平——14个模型跨越不同架构和规模,55个数据集具有受控变化。
数字鲜明且在模型间一致,这增加了信心。
一个担忧:所有算法都是确定性的,有单一正确答案。
现实世界的程序通常涉及条件逻辑、循环或模糊规范。
论文的范围设计上是狭窄的,但这限制了泛化。
生成级别分析很彻底,尽管对输出子集的失败模式进行人工检查引入了一些主观性。
写作功力:论文清晰且结构良好。
引言有效地激发了问题,结果部分呈现发现而不过度推销。
最弱的部分是讨论——它暗示了对推理和指令遵循的影响,但没有深入探讨模型为何以这种方式失败或什么架构变化可能有帮助。
重写讨论以提出机制假设(注意力跨度限制?训练数据对捷径的偏见?)会将论文从诊断提升到生成性。
判决:弱接收 — 用干净的实验设计识别了大模型中一个真实且未充分探索的弱点,但未能解释弱点存在的原因或如何修复。
要点总结
如果你正在构建依赖大模型遵循多步骤程序的系统——智能体、工作流自动化、代码解释器——不要相信最终答案准确率可以代表忠实执行。
明确测试程序遵守性,特别是随着任务长度增加。
失败模式(提前答案、执行不足、幻觉)表明大模型随着上下文增长而失去对程序状态的跟踪。
如果你的应用需要长程序,考虑将它们分解为带有明确检查点的较小子程序,或使用外部状态管理(草稿本、数据库)而不是依赖模型的上下文窗口。
诊断框架本身是可移植的:选择你关心的能力,设计一个将其与混淆因素隔离的最小测试,并沿受控轴扩展复杂度。
这篇论文的价值不是关于算术程序的具体发现——而是揭示基准性能与实际能力之间差距的模板。