Paper: 2604.25872 Authors: Shuning Shang, Hubert Strauss, Stanley Wei, Sanjeev Arora, Noam Razin Categories: cs.LG, cs.AI, stat.ML
The Gap
RLHF for language models relies on proxy rewards (like reward models trained on human preferences) because true rewards are unavailable. The field evaluates these proxies using ranking accuracy: how often does the proxy rank outputs in the same order as ground truth? This treats all reward errors equally — any deviation from ground truth is considered harmful.
But this is wrong. When you run policy gradient, not all outputs matter equally. The algorithm increases probability mass on high-reward outputs. If your proxy reward is wrong about outputs the policy rarely visits, who cares? If it’s wrong about outputs the policy is about to exploit, that’s a problem. Standard metrics ignore this interaction between reward errors and policy dynamics.
Problem: Proxy rewards have errors
         |
         v
Current approach: Measure ranking accuracy
         |                (treats all errors equally)
         v
Gap: Errors matter differently depending on
     which outputs the policy is moving toward
         |
         v
This paper: Categorize errors by their effect
            on policy gradient dynamics
         |
         v
Evidence: Theory + experiments show some errors
          are benign/beneficial
         |
         v
Conclusion: New metrics that weight errors by
            their impact on learning
The Increment
One sentence: Before this paper, reward errors were uniformly bad; after, we distinguish harmful errors (on outputs the policy exploits) from benign/beneficial ones (on outputs the policy avoids or escapes).
Core Mechanism
The method starts by analyzing what policy gradient actually does. During training, the algorithm samples outputs from the current policy, evaluates them with the proxy reward, and increases probability on high-reward outputs. The key insight: only outputs that (1) have non-negligible probability under the current policy AND (2) receive high proxy reward will attract probability mass.
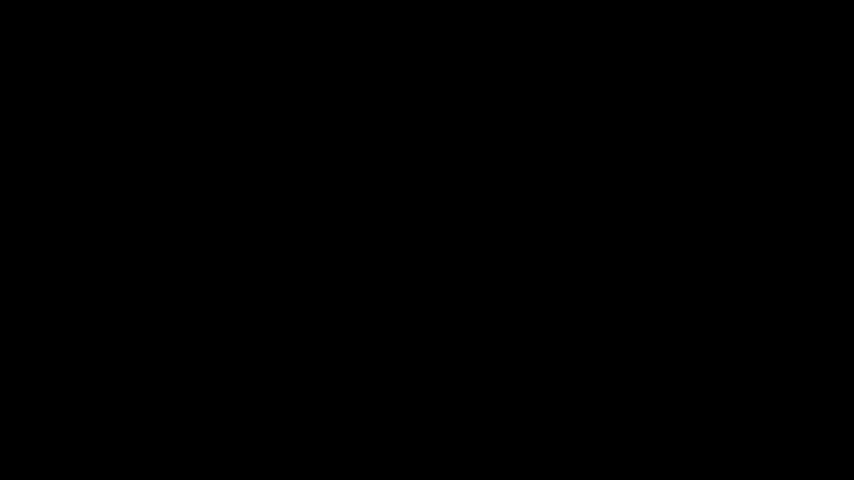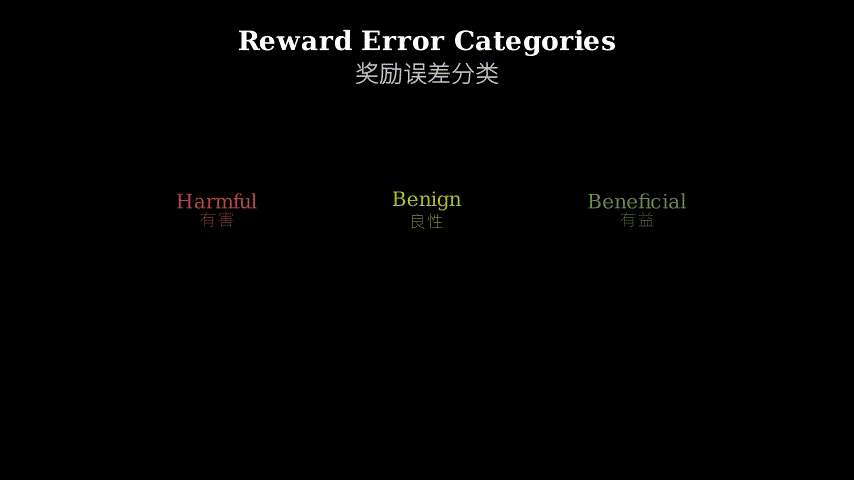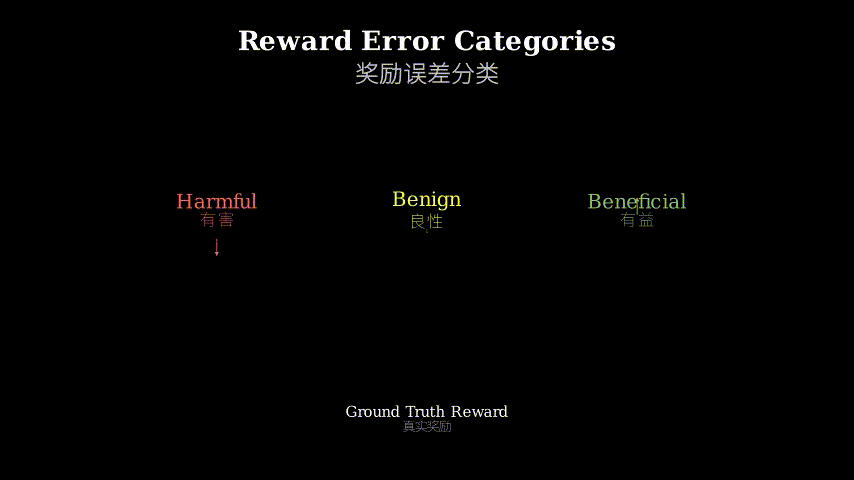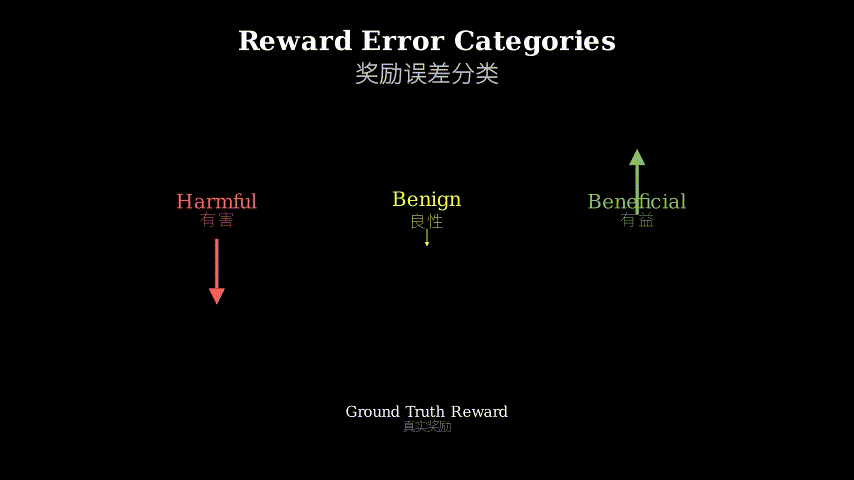
The authors categorize reward errors into three types based on their effect on ground truth reward improvement. Harmful errors occur when the proxy assigns high reward to outputs with low ground truth reward that the policy would otherwise avoid — these pull the policy toward bad outputs. Benign errors happen on outputs the policy already avoids or will avoid regardless — these don’t change the policy’s trajectory. Beneficial errors occur when the proxy underrates mediocre outputs, preventing the policy from stalling on local optima and pushing it to explore further.
Policy gradient flow:

Current policy π_t
    |
    | sample outputs
    v
Outputs {y1, y2, ...}
    |
    | evaluate with proxy reward r^
    v
Weighted by: π_t(y) * r^(y)
    |
    | gradient step
    v
Updated policy π_{t+1}
    |
    v
Probability shifts toward high-r^ outputs

Error impact depends on:
- Is π_t(y) significant? (Does policy visit this output?)
- Is r^(y) high? (Does proxy encourage this output?)
- What's the true reward R(y)?
Think of policy gradient as water flowing downhill on a landscape shaped by the proxy reward. The current policy is a probability distribution — a cloud of water droplets spread across the landscape. Policy gradient pushes water toward valleys (high proxy reward regions). Now imagine the proxy reward landscape is a distorted version of the true reward landscape.
If there’s a fake valley (high proxy reward, low true reward) where no water currently sits, it doesn’t matter — the water won’t flow there from its current position. That’s a benign error. If there’s a fake valley where water is already pooling, that’s harmful — the water gets trapped in the wrong place. But if there’s a fake hill (low proxy reward) where water is pooling at a mediocre true reward, that’s beneficial — it forces the water to keep flowing instead of settling for “good enough.” The landscape’s distortions only matter where the water actually flows.
Key Concepts
-
Probability mass concentration: Policy gradient doesn’t uniformly improve all outputs. It concentrates probability on outputs that are both (1) reachable from the current policy (non-negligible π(y)) and (2) encouraged by the reward (high r(y)). This creates a “selection effect” — only errors on outputs satisfying both conditions affect learning. An output with 0.0001% probability won’t attract mass even if the reward is wrong about it, because the policy rarely samples it. An output with 10% probability but low reward won’t attract mass either, because the gradient pushes away from it. The danger zone is outputs with moderate probability AND high proxy reward but low true reward.
-
Beneficial errors as escape mechanisms: Standard RL theory assumes more accurate rewards are always better. But when the true reward landscape has plateaus (many outputs with similar mediocre reward), an accurate proxy can trap the policy. If the proxy slightly underrates these mediocre outputs, it creates artificial gradient that pushes the policy to keep exploring. This is beneficial because the policy escapes local optima it would otherwise settle into. The key condition: the underrated outputs must have mediocre true reward, and there must exist better outputs the policy can reach. If you underrate the globally optimal output, that’s just harmful.
-
Ranking accuracy vs. learning-weighted accuracy: Ranking accuracy asks: “Do you rank output A above output B correctly?” It treats all pairs equally. But policy gradient cares more about pairs where both outputs have significant probability under the current policy. Learning-weighted accuracy weights each pair by how much it affects the policy update. A pair (A, B) matters if the policy might choose between them during training. If both have negligible probability, getting their ranking wrong is harmless. This explains why reward models with similar ranking accuracy can produce very different RLHF outcomes — they differ on the pairs that matter for learning.
Framework Shift
Before (standard view):              After (this paper):

Reward error = bad                   Reward error = context-dependent

Ground truth reward R                Ground truth reward R
Proxy reward r^                      Proxy reward r^

Evaluate: |R - r^|                   Evaluate: Effect on policy
(absolute deviation)                 gradient trajectory

All errors weighted equally          Errors weighted by:
                                     - Current policy π(y)
                                     - Proxy reward r^(y)
                                     - True reward R(y)

Goal: Minimize ranking errors        Goal: Minimize harmful errors,
                                     tolerate/exploit benign/beneficial
[One sentence: From treating all reward errors as uniformly harmful to recognizing that error impact depends on the policy’s current state and learning dynamics.]
Expert Assessment
Problem choice: This is a real gap. RLHF practitioners have noticed that reward model accuracy doesn’t predict downstream performance well, but the field lacked a principled explanation. The problem sits at a productive intersection — it’s theoretically interesting (challenges standard RL assumptions) and practically relevant (RLHF is everywhere). The framing as “errors can be beneficial” is slightly provocative but earned.
Method maturity: The theoretical analysis is solid but not groundbreaking — it’s a careful application of policy gradient theory to the proxy reward setting. The categorization (harmful/benign/beneficial) is the main conceptual contribution, and it’s genuinely useful. The proposed metrics (learning-weighted accuracy) are straightforward once you accept the framework. No major technical innovations, but the insight is valuable. One weakness: the beneficial error story relies on the policy being able to escape mediocre regions, which assumes sufficient exploration. In practice, policies often get stuck anyway.
Experimental integrity: The experiments are honest but limited. The RLHF experiments (Section 5.1) show the new metrics correlate better with downstream performance than ranking accuracy, but the improvement is modest and dataset-dependent. The synthetic experiments (Section 5.2) cleanly demonstrate the theory but use simplified settings. The paper acknowledges that “gaps remain in robustly evaluating reward models” — this is refreshingly honest. Baselines are fair. The main concern: the experiments don’t test whether practitioners can actually use these insights to design better reward functions, only that the theory explains observed phenomena.
Writing quality: The paper is well-structured and clearly written. The theory section (Section 3) is dense but necessary. The practical implications (Section 5) feel somewhat disconnected from the theory — the metrics are proposed but not deeply validated. The related work section is thorough. If I were revising, I’d expand Section 5.2 to show concrete reward design strategies that exploit beneficial errors, not just demonstrate they exist. The current version proves the concept but leaves practitioners without clear guidance on “now what?”
Verdict: weak accept — Solid theoretical contribution that reframes how we think about proxy rewards, with honest experimental validation showing modest practical gains. The insight is valuable even if the immediate applications are limited.
Takeaways
For RLHF practitioners: When evaluating reward models, don’t just look at overall ranking accuracy. Compute accuracy on the subset of output pairs your policy is likely to encounter (high probability under current policy). This is more predictive of downstream performance. If you have access to the policy during reward model training, you can weight training data by policy probability to focus the reward model on decision-relevant regions.
For reward design: If your policy is stuck on mediocre outputs, consider intentionally underrating them in your reward function to force exploration. This is risky (you might push the policy toward worse outputs), but in domains with verifiable rewards where you can detect and correct mistakes, it’s a viable strategy. The key condition: you need confidence that better outputs exist and are reachable.
For RL theory: The interaction between reward function and initial policy matters more than we typically acknowledge. Two reward functions with the same ranking accuracy can produce wildly different learning trajectories depending on where the policy starts. This suggests we need policy-conditional notions of reward quality, not just static metrics.
Transferable technique: The “learning-weighted evaluation” idea applies beyond rewards. Anytime you’re evaluating a proxy signal (value function, advantage estimate, uncertainty estimate), weight your evaluation by how much that signal affects the learning algorithm’s decisions. Errors on rarely-visited states don’t matter; errors on decision boundaries do.
论文: 2604.25872 作者: Shuning Shang, Hubert Strauss, Stanley Wei, Sanjeev Arora, Noam Razin 分类: cs.LG, cs.AI, stat.ML
缺口
语言模型的RLHF依赖代理奖励(如基于人类偏好训练的奖励模型),因为真实奖励无法获得。
该领域用排序准确率评估这些代理:代理将输出排序与真实排序一致的频率有多高?
这种方法将所有奖励误差一视同仁——任何偏离真实值的情况都被视为有害。
但这是错的。
当你运行策略梯度时,并非所有输出都同等重要。
算法会增加高奖励输出的概率质量。
如果你的代理奖励在策略很少访问的输出上出错,谁在乎?
如果它在策略即将利用的输出上出错,那就是问题。
标准指标忽略了奖励误差与策略动态之间的交互。
问题:代理奖励存在误差
         |
         v
当前方法:测量排序准确率
         |        (将所有误差一视同仁)
         v
缺口:误差的重要性取决于
     策略正在向哪些输出移动
         |
         v
本文:根据误差对策略梯度
      动态的影响进行分类
         |
         v
证据:理论+实验表明某些误差
      无害甚至有益
         |
         v
结论:新指标根据误差对学习的
      影响进行加权
增量
一句话: 这篇论文之前,奖励误差一律有害;
之后,我们区分有害误差(在策略利用的输出上)和无害/有益误差(在策略避免或逃离的输出上)。
核心机制
该方法从分析策略梯度的实际行为开始。
训练期间,算法从当前策略采样输出,用代理奖励评估它们,并增加高奖励输出的概率。
关键洞察:只有满足以下条件的输出才会吸引概率质量:(1) 在当前策略下有非可忽略的概率 且 (2) 获得高代理奖励。
作者根据误差对真实奖励改进的影响,将奖励误差分为三类。
有害误差发生在代理给低真实奖励的输出分配高奖励时,而策略本来会避免这些输出——这会将策略拉向坏输出。
无害误差发生在策略已经避免或无论如何都会避免的输出上——这些不会改变策略的轨迹。
有益误差发生在代理低估平庸输出时,防止策略在局部最优处停滞,推动它进一步探索。
策略梯度流程:

当前策略 π_t
    |
    | 采样输出
    v
输出 {y1, y2, ...}
    |
    | 用代理奖励 r^ 评估
    v
加权:π_t(y) * r^(y)
    |
    | 梯度步
    v
更新后的策略 π_{t+1}
    |
    v
概率向高 r^ 输出转移

误差影响取决于:
- π_t(y) 显著吗?(策略访问这个输出吗?)
- r^(y) 高吗?(代理鼓励这个输出吗?)
- 真实奖励 R(y) 是多少?
把策略梯度想象成水在由代理奖励塑造的地形上向下流动。
当前策略是一个概率分布——一团水滴散布在地形上。
策略梯度将水推向山谷(高代理奖励区域)。
现在想象代理奖励地形是真实奖励地形的扭曲版本。
如果有一个假山谷(高代理奖励,低真实奖励),但目前没有水在那里,那就无所谓——水不会从当前位置流到那里。
这是无害误差。
如果有一个假山谷,水已经在那里聚集,那就有害——水被困在错误的地方。
但如果有一个假山丘(低代理奖励),水在一个平庸的真实奖励处聚集,那就有益——它迫使水继续流动,而不是满足于”足够好”。
地形的扭曲只在水实际流动的地方才重要。
关键概念
- 概率质量集中:策略梯度不会均匀改进所有输出。
它将概率集中在同时满足以下条件的输出上:(1) 从当前策略可达(非可忽略的 π(y))且 (2) 被奖励鼓励(高 r(y))。
这产生了”选择效应”——只有满足两个条件的输出上的误差才会影响学习。
概率为 0.0001% 的输出即使奖励判断错误也不会吸引质量,因为策略很少采样它。
概率为 10% 但奖励低的输出也不会吸引质量,因为梯度会推离它。
危险区是概率适中且代理奖励高但真实奖励低的输出。
- 有益误差作为逃逸机制:标准强化学习理论假设更准确的奖励总是更好。
但当真实奖励地形有平台(许多输出具有相似的平庸奖励)时,准确的代理会困住策略。
如果代理稍微低估这些平庸输出,它会创造人工梯度,推动策略继续探索。
这是有益的,因为策略逃离了本来会停留的局部最优。
关键条件:被低估的输出必须具有平庸的真实奖励,且必须存在策略可以到达的更好输出。
如果你低估全局最优输出,那就只是有害。
- 排序准确率 vs. 学习加权准确率:排序准确率问:“你是否正确地将输出 A 排在输出 B 之上?”
它平等对待所有配对。
但策略梯度更关心两个输出在当前策略下都有显著概率的配对。
学习加权准确率根据每个配对对策略更新的影响程度进行加权。
如果策略在训练期间可能在它们之间选择,配对 (A, B) 就很重要。
如果两者概率都可忽略,排序错误是无害的。
这解释了为什么具有相似排序准确率的奖励模型可以产生非常不同的 RLHF 结果——它们在对学习重要的配对上有差异。
框架转变
之前(标准观点):              之后(本文):

奖励误差 = 坏                   奖励误差 = 依赖上下文

真实奖励 R                      真实奖励 R
代理奖励 r^                     代理奖励 r^

评估:|R - r^|                  评估:对策略梯度
(绝对偏差)                    轨迹的影响

所有误差权重相等                误差加权依据:
                                - 当前策略 π(y)
                                - 代理奖励 r^(y)
                                - 真实奖励 R(y)

目标:最小化排序错误            目标:最小化有害误差,
                                容忍/利用无害/有益误差
[一句话:从将所有奖励误差视为一律有害,到认识到误差影响取决于策略的当前状态和学习动态。
]
专家评审
选题眼光:这是真实的缺口。
RLHF 实践者已经注意到奖励模型准确率不能很好地预测下游性能,但该领域缺乏原则性解释。
这个问题处于一个富有成效的交叉点——它在理论上有趣(挑战标准强化学习假设)且在实践中相关(RLHF 无处不在)。
将其框定为”误差可能有益”略带挑衅性,但这是赢得的。
方法成熟度:理论分析扎实但不算突破性——它是策略梯度理论在代理奖励设置中的仔细应用。
分类(有害/无害/有益)是主要的概念贡献,确实有用。
提出的指标(学习加权准确率)一旦接受框架就很直接。
没有重大技术创新,但洞察有价值。
一个弱点:有益误差的故事依赖于策略能够逃离平庸区域,这假设有足够的探索。
实践中,策略经常还是会卡住。
实验诚意:实验诚实但有限。
RLHF 实验(第 5.1 节)显示新指标比排序准确率更好地关联下游性能,但改进适度且依赖数据集。
合成实验(第 5.2 节)清晰地展示了理论,但使用简化设置。
论文承认”在稳健评估奖励模型方面仍存在差距”——这令人耳目一新地诚实。
基线公平。
主要担忧:实验没有测试实践者是否真的可以使用这些洞察来设计更好的奖励函数,只是理论解释了观察到的现象。
写作功力:论文结构良好,表述清晰。
理论部分(第 3 节)密集但必要。
实际意义(第 5 节)感觉与理论有些脱节——提出了指标但没有深入验证。
相关工作部分很全面。
如果我修订,我会扩展第 5.2 节,展示利用有益误差的具体奖励设计策略,而不仅仅是证明它们存在。
当前版本证明了概念,但让实践者没有”现在怎么办?“的明确指导。
判决:弱接收——扎实的理论贡献,重新框定了我们对代理奖励的思考方式,诚实的实验验证显示适度的实际收益。
即使直接应用有限,洞察也是有价值的。
要点总结
对 RLHF 实践者:评估奖励模型时,不要只看整体排序准确率。
计算策略可能遇到的输出配对子集(当前策略下高概率)的准确率。
这更能预测下游性能。
如果在奖励模型训练期间可以访问策略,可以根据策略概率对训练数据加权,使奖励模型专注于决策相关区域。
对奖励设计:如果策略卡在平庸输出上,考虑在奖励函数中故意低估它们以强制探索。
这有风险(可能将策略推向更差的输出),但在具有可验证奖励的领域,你可以检测和纠正错误,这是可行的策略。
关键条件:你需要确信存在更好的输出且可达。
对强化学习理论:奖励函数与初始策略之间的交互比我们通常承认的更重要。
具有相同排序准确率的两个奖励函数可以产生截然不同的学习轨迹,取决于策略从哪里开始。
这表明我们需要策略条件的奖励质量概念,而不仅仅是静态指标。
可迁移技术:“学习加权评估”的想法适用于奖励之外。
每当你评估代理信号(价值函数、优势估计、不确定性估计)时,根据该信号对学习算法决策的影响程度进行加权评估。
很少访问的状态上的误差不重要;
决策边界上的误差才重要。