Paper: 2602.22145 Authors: Satyam Kumar Navneet, Joydeep Chandra, Yong Zhang Categories: cs.HC, cs.AI, cs.CL
Abstract
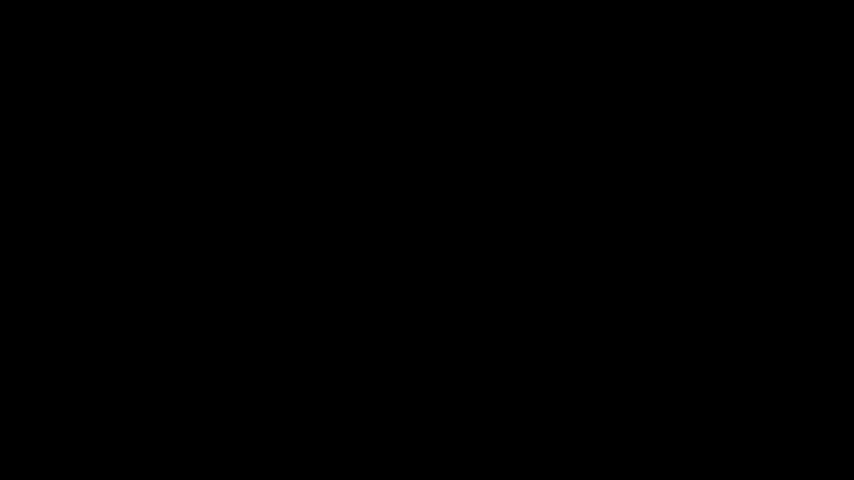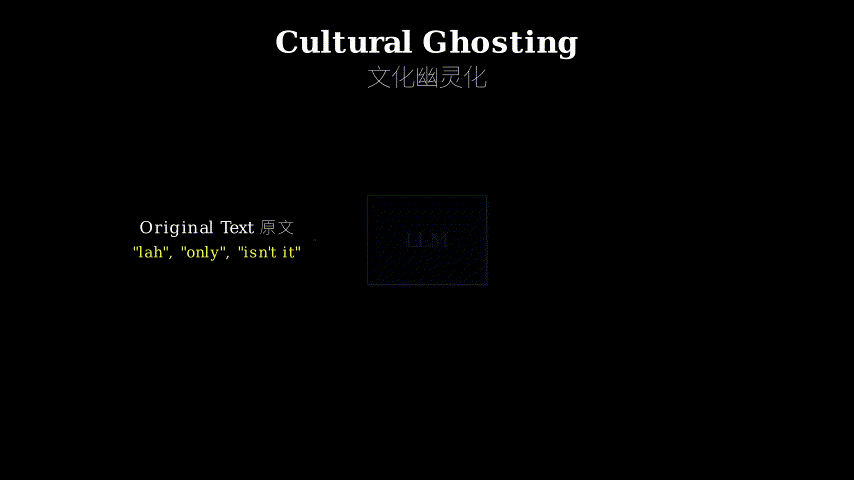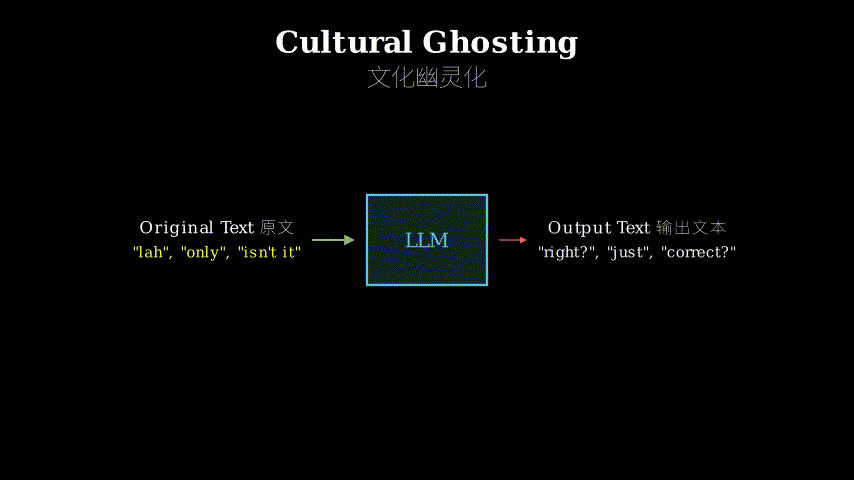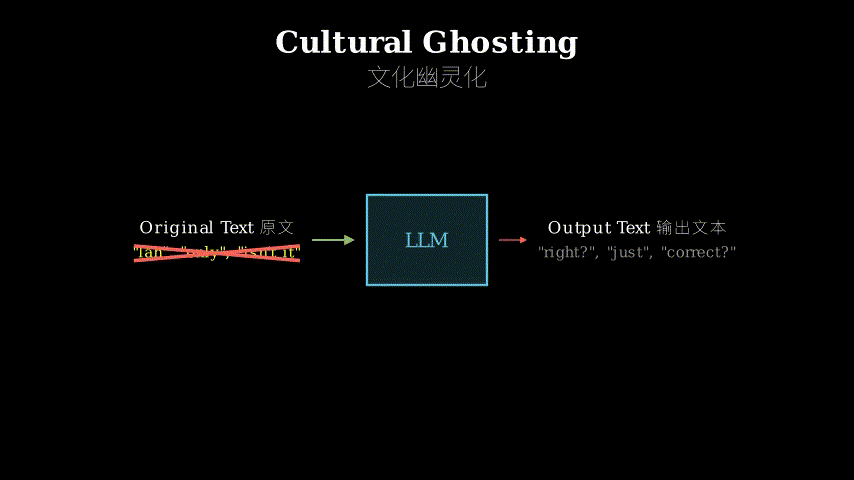
As LLMs become ubiquitous tools for “professionalizing” workplace communication, they inadvertently homogenize linguistic diversity. This research introduces the concept of Cultural Ghosting - the systematic erasure of linguistic markers that distinguish non-native English varieties during AI-mediated text processing. Through comprehensive analysis of 22,350 LLM outputs across five models processing 1,490 culturally marked texts from Indian, Singaporean, and Nigerian English varieties, the authors quantify this phenomenon using two novel metrics: Identity Erasure Rate (IER) and Semantic Preservation Score (SPS). The findings reveal an overall IER of 10.26% with significant model variation (3.5% to 20.5%), and identify a critical Semantic Preservation Paradox where models maintain high semantic similarity (mean SPS = 0.748) while systematically removing cultural markers. Pragmatic markers prove 1.9× more vulnerable than lexical markers to erasure, though explicit cultural-preservation prompts can reduce erasure by 29%.
Key Contributions
- Conceptual Framework: Introduction of “Cultural Ghosting” as a measurable phenomenon in LLM text processing, providing vocabulary for discussing linguistic identity loss in AI systems
- Novel Metrics: Development of Identity Erasure Rate (IER) and Semantic Preservation Score (SPS) to quantify cultural marker retention and semantic fidelity simultaneously
- Large-Scale Empirical Study: Analysis of 22,350 outputs across five LLMs (GPT-4, Claude, Gemini, Llama, Mistral) under three prompt conditions, establishing baseline erasure patterns
- Marker Taxonomy: Systematic categorization of cultural markers into lexical and pragmatic types, revealing differential vulnerability (71.5% vs. 37.1% erasure rates)
- Mitigation Strategy: Demonstration that explicit cultural-preservation prompts reduce erasure by 29% without compromising semantic quality or task performance
Methodology and Experimental Design
The research employs a rigorous three-stage methodology. First, the authors curated a dataset of 1,490 authentic texts representing three World English varieties: Indian English (characterized by markers like “do the needful,” “prepone”), Singaporean English (featuring “lah,” “can or not”), and Nigerian English (including “I dey come,” “no wahala”). These texts span professional contexts including emails, reports, and workplace communications.
The experimental design tests five state-of-the-art LLMs under three prompt conditions: (1) Neutral prompts requesting text improvement without cultural guidance, (2) Professional prompts explicitly requesting “professional” or “formal” output, and (3) Cultural-preservation prompts instructing models to maintain regional linguistic characteristics. Each text-model-prompt combination generates outputs that are then analyzed using automated detection algorithms supplemented by human validation.
The IER metric is calculated as:
Meanwhile, SPS employs sentence-transformer embeddings to measure semantic similarity between input and output, with scores ranging from 0 (completely different) to 1 (semantically identical).
Results and the Semantic Preservation Paradox
The empirical findings reveal striking patterns. Across all conditions, the mean IER reaches 10.26%, but model-level variation spans a 5.9× range - from GPT-4’s relatively conservative 3.5% to Mistral’s aggressive 20.5% erasure rate. This variation suggests that cultural sensitivity is not uniformly distributed across model architectures or training regimes.
The Semantic Preservation Paradox emerges as the study’s most provocative finding: models achieve high semantic similarity scores (mean SPS = 0.748) while simultaneously erasing cultural markers. This indicates that LLMs successfully preserve propositional content and communicative intent while systematically removing the linguistic features that signal cultural identity. The paradox challenges assumptions that semantic fidelity equates to faithful reproduction - meaning is preserved, but voice is lost.
Marker type analysis reveals differential vulnerability. Pragmatic markers - including politeness conventions, discourse particles, and interactional patterns - suffer 71.5% erasure rates, nearly double the 37.1% rate for lexical markers (vocabulary items, idioms, syntactic patterns). This asymmetry suggests that models more readily identify and “correct” pragmatic features, possibly because they’re perceived as stylistic rather than semantic.
Prompt engineering demonstrates measurable impact. Cultural-preservation prompts reduce overall IER from 12.8% (professional prompts) to 9.1%, a 29% reduction. Critically, this reduction occurs without degrading semantic quality - SPS remains stable at 0.745-0.750 across prompt conditions. This finding suggests that cultural erasure is not an inevitable byproduct of text improvement but rather a default behavior that can be modified through explicit instruction.
Implications for AI Ethics and Linguistic Justice
The research carries profound implications for AI ethics, workplace equity, and linguistic justice. As LLMs mediate increasing volumes of professional communication, Cultural Ghosting risks creating a linguistic monoculture where only standardized varieties are deemed “professional.” This has material consequences: speakers of World English varieties may face pressure to suppress linguistic identity to appear competent, reinforcing colonial language hierarchies that position native-speaker norms as superior.
The findings challenge the notion of “neutral” AI assistance. When models systematically erase cultural markers while claiming to merely “improve” text, they encode specific ideologies about linguistic legitimacy. The high erasure rates for pragmatic markers are particularly concerning, as these features often carry crucial social information about relationships, respect, and cultural context that may be invisible to models trained predominantly on standardized English.
From a design perspective, the success of cultural-preservation prompts suggests actionable interventions. LLM interfaces could implement opt-in cultural preservation modes, provide transparency about marker modification, or offer users control over which linguistic features to retain. However, the burden should not fall entirely on users to defend their linguistic identity - model training and evaluation must incorporate cultural sensitivity as a core objective.
The research also highlights gaps in current AI evaluation frameworks. Standard benchmarks emphasize semantic accuracy, fluency, and task completion but rarely assess cultural marker preservation. The IER and SPS metrics provide a template for more holistic evaluation that considers both what is preserved and what is lost in AI-mediated communication.
Takeaways
-
Cultural Ghosting is pervasive: LLMs erase 10.26% of cultural markers on average, with some models removing over 20%, systematically homogenizing linguistic diversity in professional contexts.
-
The Semantic Preservation Paradox reveals a critical gap: Models maintain high semantic similarity (74.8%) while erasing cultural identity, demonstrating that “meaning” and “voice” are distinct dimensions that current systems conflate.
-
Pragmatic markers are disproportionately vulnerable: Politeness conventions and discourse particles face 1.9× higher erasure rates than lexical markers, suggesting models treat cultural pragmatics as stylistic noise rather than meaningful communication.
-
Prompt engineering offers partial mitigation: Explicit cultural-preservation instructions reduce erasure by 29% without compromising semantic quality, indicating that Cultural Ghosting is modifiable behavior rather than inevitable technical limitation.
-
Model variation suggests training matters: The 5.9× range in erasure rates across models (3.5% to 20.5%) indicates that architectural choices, training data composition, and fine-tuning objectives significantly impact cultural sensitivity.
-
Evaluation frameworks need expansion: Current AI benchmarks inadequately assess linguistic identity preservation, necessitating new metrics like IER and SPS that measure both semantic fidelity and cultural marker retention simultaneously.
论文: 2602.22145 作者: Satyam Kumar Navneet, Joydeep Chandra, Yong Zhang 分类: cs.HC, cs.AI, cs.CL
摘要
随着大语言模型成为职场沟通”专业化”的普遍工具,它们在无意中同质化了语言多样性。本研究提出文化幽灵化(Cultural Ghosting)概念——AI介导的文本处理过程中系统性地消除区分非母语英语变体的语言标记现象。通过对五个模型处理1,490个具有文化标记的文本(印度英语、新加坡英语和尼日利亚英语)生成的22,350个输出进行综合分析,作者使用两个新指标量化这一现象:身份消除率(IER)和语义保留分数(SPS)。研究发现总体IER为10.26%,模型间差异显著(3.5%至20.5%),并识别出关键的语义保留悖论——模型在保持高语义相似度(平均SPS = 0.748)的同时系统性地移除文化标记。语用标记比词汇标记更易被消除(消除率71.5% vs. 37.1%,相差1.9倍),但显式的文化保留提示可将消除率降低29%。
主要贡献
- 概念框架: 提出”文化幽灵化”作为LLM文本处理中的可测量现象,为讨论AI系统中的语言身份丢失提供术语体系
- 新颖指标: 开发身份消除率(IER)和语义保留分数(SPS),同时量化文化标记保留度和语义保真度
- 大规模实证研究: 分析五个LLM(GPT-4、Claude、Gemini、Llama、Mistral)在三种提示条件下的22,350个输出,建立消除模式基线
- 标记分类体系: 系统性地将文化标记分为词汇型和语用型,揭示差异化脆弱性(消除率71.5% vs. 37.1%)
- 缓解策略: 证明显式文化保留提示可在不损害语义质量或任务性能的情况下将消除率降低29%
方法论与实验设计
研究采用严谨的三阶段方法论。首先,作者策划了包含1,490个真实文本的数据集,代表三种世界英语变体:印度英语(特征标记如”do the needful”、“prepone”)、新加坡英语(包含”lah”、“can or not”)和尼日利亚英语(包括”I dey come”、“no wahala”)。这些文本涵盖专业场景,包括电子邮件、报告和职场沟通。
实验设计在三种提示条件下测试五个最先进的LLM:(1)中性提示——要求改进文本但不提供文化指导,(2)专业提示——明确要求”专业”或”正式”输出,(3)文化保留提示——指示模型保持区域语言特征。每个文本-模型-提示组合生成的输出随后使用自动检测算法分析,并辅以人工验证。
IER指标计算公式为:
同时,SPS采用句子转换器嵌入来测量输入与输出之间的语义相似度,分数范围从0(完全不同)到1(语义完全相同)。
研究结果与语义保留悖论
实证发现揭示了显著模式。在所有条件下,平均IER达到10.26%,但模型层面的变化跨越5.9倍范围——从GPT-4相对保守的3.5%到Mistral激进的20.5%消除率。这种变化表明文化敏感性在模型架构或训练机制中分布并不均匀。
语义保留悖论作为研究最具挑战性的发现:模型在实现高语义相似度分数(平均SPS = 0.748)的同时系统性地消除文化标记。这表明LLM成功保留了命题内容和交际意图,同时系统性地移除了标志文化身份的语言特征。这一悖论挑战了语义保真度等同于忠实再现的假设——意义被保留,但声音却丢失了。
标记类型分析揭示了差异化脆弱性。语用标记——包括礼貌惯例、话语小品词和互动模式——遭受71.5%的消除率,几乎是词汇标记(词汇项、习语、句法模式)37.1%消除率的两倍。这种不对称性表明模型更容易识别并”纠正”语用特征,可能因为它们被视为风格性而非语义性的。
提示工程展示了可测量的影响。文化保留提示将总体IER从12.8%(专业提示)降低到9.1%,减少29%。关键的是,这种减少在不降低语义质量的情况下发生——SPS在各提示条件下保持稳定在0.745-0.750。这一发现表明文化消除不是文本改进的必然副产品,而是可以通过显式指令修改的默认行为。
对AI伦理与语言正义的启示
该研究对AI伦理、职场公平和语言正义具有深远影响。随着LLM介导越来越多的专业沟通,文化幽灵化有可能创造一种语言单一文化,其中只有标准化变体被视为”专业”。这具有实质性后果:世界英语变体的使用者可能面临压力,需要压制语言身份以显得称职,强化了将母语者规范定位为优越的殖民语言等级制度。
研究结果挑战了”中性”AI辅助的概念。当模型在声称仅”改进”文本的同时系统性地消除文化标记时,它们编码了关于语言合法性的特定意识形态。语用标记的高消除率尤其令人担忧,因为这些特征通常承载关于关系、尊重和文化语境的关键社会信息,而这些信息对于主要在标准化英语上训练的模型可能是不可见的。
从设计角度看,文化保留提示的成功表明了可行的干预措施。LLM界面可以实现选择性文化保留模式,提供关于标记修改的透明度,或为用户提供对保留哪些语言特征的控制。然而,捍卫语言身份的负担不应完全落在用户身上——模型训练和评估必须将文化敏感性纳入核心目标。
研究还突出了当前AI评估框架的差距。标准基准强调语义准确性、流畅性和任务完成度,但很少评估文化标记保留。IER和SPS指标为更全面的评估提供了模板,考虑AI介导沟通中保留了什么和丢失了什么。
要点总结
-
文化幽灵化普遍存在: LLM平均消除10.26%的文化标记,某些模型移除超过20%,在专业场景中系统性地同质化语言多样性。
-
语义保留悖论揭示关键差距: 模型在保持高语义相似度(74.8%)的同时消除文化身份,表明”意义”和”声音”是当前系统混淆的不同维度。
-
语用标记不成比例地脆弱: 礼貌惯例和话语小品词面临比词汇标记高1.9倍的消除率,表明模型将文化语用视为风格噪音而非有意义的交际。
-
提示工程提供部分缓解: 显式文化保留指令在不损害语义质量的情况下将消除率降低29%,表明文化幽灵化是可修改的行为而非不可避免的技术限制。
-
模型差异表明训练很重要: 模型间消除率的5.9倍范围(3.5%至20.5%)表明架构选择、训练数据组成和微调目标显著影响文化敏感性。
-
评估框架需要扩展: 当前AI基准不充分评估语言身份保留,需要像IER和SPS这样同时测量语义保真度和文化标记保留的新指标。