Paper: 2605.31564 Authors: Qing Wang, Jacob Devasier, Chengkai Li Categories: cs.CL, cs.AI
The Gap
Graph-to-text generation has been dominated by autoregressive LLMs that generate text left-to-right, token by token. Masked diffusion language models (MDLMs) offer an alternative: they start with all tokens masked and iteratively unmask them in parallel. But nobody has systematically studied what order MDLMs choose to unmask tokens when generating from structured graph inputs, or whether this order matters for quality.
Prior work on MDLMs focused on general text generation. When applied to graph-to-text tasks (converting knowledge graphs to natural language descriptions), researchers assumed standard supervised fine-tuning (SFT) would work. The gap: no analysis of how MDLMs’ decoding strategy interacts with graph structure, and no investigation of whether SFT preserves or disrupts the model’s natural generation priorities.
Problem: Graph-to-text needs structured reasoning
         Autoregressive = forced left-to-right order
         MDLMs = flexible unmasking order (unexplored)
            |
            v
Assumption: MDLMs might naturally align with graph structure
            SFT might interfere with this alignment
            |
            v
Method: 1. Analyze unmasking trajectories (what gets decoded first?)
        2. Identify SFT failure mode (premature structural anchoring)
        3. Propose lambda-scaled structural decoding (inference fix)
        4. Test Graph-LLaDA (explicit graph integration)
            |
            v
Evidence: MDLMs naturally decode entities > relations > structure
          SFT forces early sentence-ending tokens (fixes length prematurely)
          Lambda-scaling recovers +9.4 BLEU-4
          Graph-LLaDA generalizes better across datasets
            |
            v
Conclusion: MDLMs have implicit graph-aware decoding strategy
            Standard SFT breaks it
            Simple inference-time fix restores performance
The Increment
One sentence: Before this paper, we didn’t know MDLMs had a natural entity-first decoding strategy for graphs, or that SFT destroys it by prematurely anchoring sentence structure—now we have a training-free fix and evidence that explicit graph encoding helps generalization.
Core Mechanism
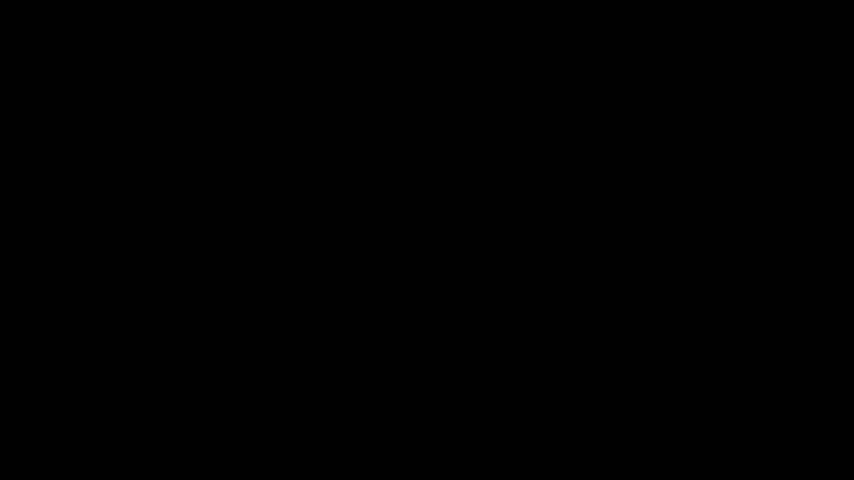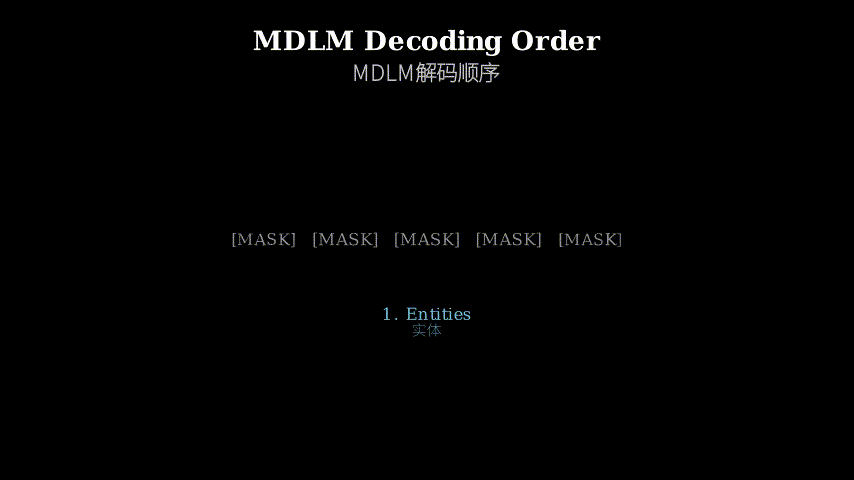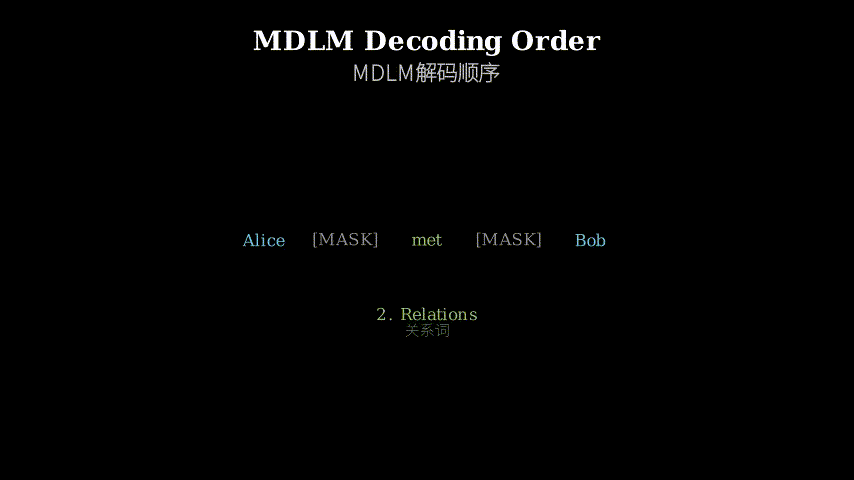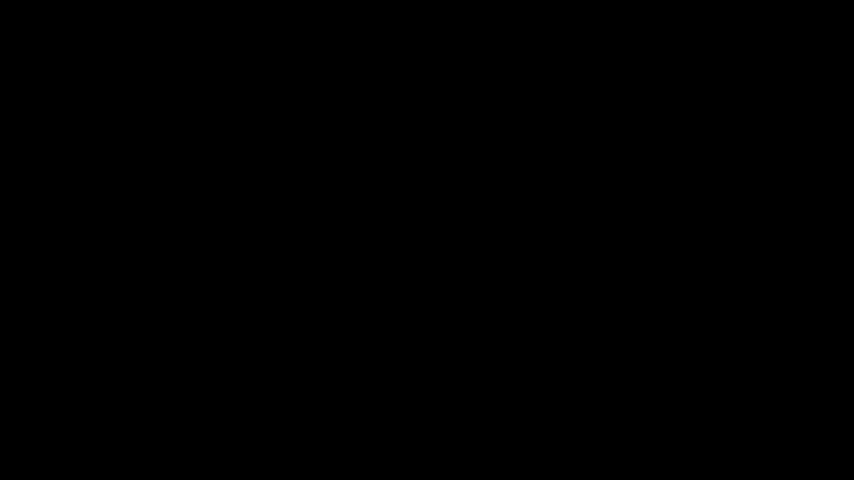
Masked diffusion models start with all tokens replaced by [MASK]. At each decoding step, the model predicts confidence scores for what each mask should be, then unmasks the highest-confidence tokens. This repeats until all masks are resolved. The key insight: the order matters.
The authors discovered MDLMs naturally follow a three-stage trajectory: (1) unmask content words (entities, attributes), (2) unmask relational and function words (prepositions, verbs), (3) unmask structural tokens (periods, sentence boundaries). This aligns with how humans might describe a graph: establish what entities exist, then explain relationships, then wrap up the sentence structure.
But supervised fine-tuning disrupts this. SFT trains the model to match reference texts exactly, which means it learns to predict sentence-ending tokens (like periods) with high confidence early in decoding. This prematurely fixes the output length before all graph content is processed, leading to omitted facts or hallucinated filler.
MDLM Decoding (one iteration):

  Input:  [MASK] [MASK] [MASK] [MASK] [MASK]
           |      |      |      |      |
           v      v      v      v      v
  Model predicts confidence for each position
           |
           v
  Unmask top-k highest confidence tokens
           |
           v
  Output: [MASK] "Paris" [MASK] "France" [MASK]

  Repeat until no masks remain
Structural metaphor: Think of assembling a jigsaw puzzle. The natural strategy: find corner and edge pieces first (entities—the anchors), then fill in the middle connections (relations), then trim the border to final size (structural tokens). Supervised fine-tuning is like someone insisting you cut the border to exact size *before placing all the pieces. You’re forced to either leave pieces out or cram in pieces that don’t belong, because the frame is already fixed.
Lambda-scaled structural decoding is like giving yourself permission to ignore the pre-cut frame early on. You downweight the confidence of structural tokens (multiply by lambda < 1) during early decoding steps, letting content tokens unmask first. Only in later steps do you let structural tokens compete fairly. The frame adjusts to fit the content, not vice versa.
Graph-LLaDA goes further: instead of relying on implicit graph understanding from text, it explicitly encodes the graph structure with a Graph Transformer, then conditions the MDLM decoder on these graph-aware representations. It’s like having the puzzle box image visible while assembling—you know what the final structure should look like before placing pieces.
Key Concepts
-
Unmasking trajectory: In masked diffusion models, tokens aren’t generated in reading order (left-to-right). Instead, the model iteratively reveals tokens based on confidence. The *trajectory is the sequence in which tokens get unmasked across decoding steps. For example, in “Paris is the capital of France.”, the trajectory might be: step 1 unmasks “Paris” and “France” (high-confidence entities), step 2 unmasks “capital” (relation), step 3 unmasks “is”, “the”, “of” (function words), step 4 unmasks ”.” (structure). The trajectory reveals the model’s implicit generation strategy—what it considers most certain first.
-
Structural anchoring: When a model predicts sentence-ending tokens (periods, question marks) with high confidence early in decoding, it effectively commits to a specific output length before processing all input information. This is “anchoring” because subsequent decoding must fit within that pre-determined structure. In graph-to-text, if the model unmasks a period after 10 tokens but the graph contains 15 facts, the model must either omit 5 facts or hallucinate filler to reach the period. The anchor constrains content generation.
-
Lambda-scaling: A simple inference-time trick to delay structural token unmasking. For each structural token (periods, commas, etc.), multiply its predicted confidence by a factor lambda (e.g., 0.3). This makes structural tokens artificially less confident, so they get unmasked later. No retraining needed—just scale the logits before selecting which tokens to unmask. As decoding progresses, you can gradually increase lambda back toward 1.0, allowing structure to finalize once content is mostly resolved.
Framework Shift
Before (Autoregressive LLMs):        After (MDLMs with trajectory analysis):

Graph --> Encoder                    Graph --> Encoder
           |                                    |
           v                                    v
    Left-to-right decoding            Parallel confidence prediction
    "Paris" -> "is" -> "the"                   |
    -> "capital" -> "of"                       v
    -> "France" -> "."               Unmask by priority:
           |                          Step 1: "Paris", "France" (entities)
    Fixed generation order            Step 2: "capital" (relation)
    (structure mixed with content)    Step 3: "is", "the", "of" (function)
                                      Step 4: "." (structure)
                                               |
                                      Content-first, structure-last
One sentence: From forced sequential generation that mixes content and structure, to confidence-driven parallel unmasking that naturally separates semantic content from syntactic scaffolding.
Expert Assessment
Problem choice: Real gap. Graph-to-text is a well-studied task, but the interaction between MDLMs’ parallel decoding and structured inputs was genuinely unexplored. The trajectory analysis is novel and reveals something non-obvious: MDLMs have an implicit bias toward content-first generation that aligns with graph structure. Not a manufactured problem.
Method maturity: Lambda-scaling is almost embarrassingly simple—just multiply some logits by 0.3. But that’s a feature, not a bug. The authors identified a specific failure mode (premature structural anchoring) and proposed the minimal intervention to fix it. Graph-LLaDA is more involved but still straightforward: plug a Graph Transformer encoder into an existing MDLM architecture. No exotic training procedures or architectural gymnastics. The simplicity suggests the authors understood the problem deeply enough to avoid overengineering.
Experimental integrity: Baselines are fair. The cross-dataset evaluation (LAGRANGE benchmark) is the paper’s strongest move—it exposes that prior methods overfit to dataset-specific patterns, while LLM/MDLM approaches generalize better. The +9.4 BLEU-4 gain from lambda-scaling is substantial and reproducible (training-free, so no hyperparameter luck). One minor concern: the paper doesn’t deeply investigate *why SFT causes premature anchoring (is it the loss function? the reference text distribution?), but the empirical evidence is solid.
Writing quality: The trajectory analysis section is excellent—clear visualizations of unmasking order across decoding steps. The related work section is thin; the authors could have better positioned MDLMs relative to other non-autoregressive generation methods (insertion-based, iterative refinement). The ablation studies are thorough but buried in the appendix—some should be promoted to the main text. Overall, the paper front-loads the key insight (trajectory analysis) effectively, but the latter half feels rushed.
Verdict: Weak accept — Solid empirical contribution with a novel analysis angle (unmasking trajectories), but the theoretical understanding of *why SFT breaks the strategy is shallow, and the writing could be tighter. The simplicity of the fix (lambda-scaling) is both a strength (practical) and a weakness (feels incremental). Graph-LLaDA’s generalization results elevate the paper above a pure analysis piece.
Takeaways
For practitioners: If you’re fine-tuning masked diffusion models on structured generation tasks (not just graphs—think tables, code, formal languages), check whether your model is prematurely committing to output structure. Log the unmasking order during inference. If structural tokens (punctuation, delimiters, closing brackets) appear early, try confidence downweighting as a quick fix before retraining.
For researchers: The trajectory analysis method is transferable. Any iterative decoding model (not just MDLMs—think speculative decoding, iterative refinement) has an implicit generation order. Analyzing that order can reveal misalignments between the model’s strategy and the task structure. The gap between “what the model naturally wants to do” and “what supervised training forces it to do” is underexplored.
Specific technique: Lambda-scaled decoding is a zero-cost inference trick. If you have a set of tokens that should be resolved late (structure, formatting, metadata), just scale their logits down early in decoding and gradually restore them. No retraining, no architecture changes. Works for any model that outputs per-token confidences.
论文: 2605.31564 作者: Qing Wang, Jacob Devasier, Chengkai Li 分类: cs.CL, cs.AI
缺口
图到文本生成一直由自回归大语言模型主导,这些模型从左到右逐个生成词元。
掩码扩散语言模型(MDLMs)提供了另一种方案:它们从所有词元都被掩码的状态开始,迭代地并行解除掩码。
但没有人系统研究过,当从结构化图输入生成文本时,MDLMs 会选择以什么顺序解除掩码,或者这个顺序是否影响生成质量。
此前关于 MDLMs 的工作聚焦于通用文本生成。
当应用到图到文本任务(将知识图谱转换为自然语言描述)时,研究者假设标准的监督微调(SFT)就能奏效。
缺口在于:没有人分析 MDLMs 的解码策略如何与图结构交互,也没有人研究 SFT 是否保留或破坏了模型的自然生成优先级。
问题:图到文本需要结构化推理
      自回归 = 强制从左到右的顺序
      MDLMs = 灵活的解码顺序(未被探索)
         |
         v
假设:MDLMs 可能天然地与图结构对齐
      SFT 可能干扰这种对齐
         |
         v
方法:1. 分析解码轨迹(什么先被解码?)
      2. 识别 SFT 失效模式(过早的结构锚定)
      3. 提出 lambda 缩放结构解码(推理时修复)
      4. 测试 Graph-LLaDA(显式图集成)
         |
         v
证据:MDLMs 自然地解码 实体 > 关系 > 结构
      SFT 强制早期句尾词元(过早固定长度)
      Lambda 缩放恢复 +9.4 BLEU-4
      Graph-LLaDA 跨数据集泛化更好
         |
         v
结论:MDLMs 有隐式的图感知解码策略
      标准 SFT 破坏了它
      简单的推理时修复恢复了性能
增量
一句话: 这篇论文之前,我们不知道 MDLMs 对图有天然的实体优先解码策略,也不知道 SFT 会通过过早锚定句子结构来破坏它——现在我们有了一个无需训练的修复方法,以及显式图编码有助于泛化的证据。
核心机制
掩码扩散模型从所有词元都被替换为 [MASK] 的状态开始。
在每个解码步骤,模型预测每个掩码应该是什么的置信度分数,然后解除置信度最高的词元的掩码。
这个过程重复进行,直到所有掩码都被解决。
关键洞察:顺序很重要。
作者发现 MDLMs 自然地遵循三阶段轨迹:(1) 解除内容词的掩码(实体、属性),(2) 解除关系词和功能词的掩码(介词、动词),(3) 解除结构词元的掩码(句号、句子边界)。
这与人类描述图的方式一致:先确定存在哪些实体,然后解释关系,最后完善句子结构。
但监督微调破坏了这一点。
SFT 训练模型精确匹配参考文本,这意味着它学会在解码早期就以高置信度预测句尾词元(如句号)。
这在所有图内容被处理之前就过早地固定了输出长度,导致遗漏事实或产生幻觉填充。
MDLM 解码(一次迭代):

  输入:  [MASK] [MASK] [MASK] [MASK] [MASK]
           |      |      |      |      |
           v      v      v      v      v
  模型预测每个位置的置信度
           |
           v
  解除 top-k 最高置信度词元的掩码
           |
           v
  输出: [MASK] "巴黎" [MASK] "法国" [MASK]

  重复直到没有掩码
核喻:想象拼拼图。
自然策略是:先找角落和边缘的拼块(实体——锚点),然后填充中间的连接(关系),最后修整边框到最终尺寸(结构词元)。
监督微调就像有人坚持你在放置所有拼块之前就把边框裁剪到精确尺寸。
你被迫要么遗漏拼块,要么塞入不属于的拼块,因为框架已经固定了。
Lambda 缩放结构解码就像允许你在早期忽略预裁剪的框架。
你在早期解码步骤中降低结构词元的置信度(乘以 lambda < 1),让内容词元先解除掩码。
只有在后期步骤中,你才让结构词元公平竞争。
框架调整以适应内容,而不是反过来。
Graph-LLaDA 更进一步:它不依赖从文本中隐式理解图,而是用图变换器显式编码图结构,然后让 MDLM 解码器以这些图感知表示为条件。
这就像在拼图时能看到盒子上的图像——在放置拼块之前就知道最终结构应该是什么样子。
关键概念
- 解码轨迹:在掩码扩散模型中,词元不是按阅读顺序(从左到右)生成的。
相反,模型根据置信度迭代地揭示词元。
轨迹是词元在解码步骤中被解除掩码的序列。
例如,在”巴黎是法国的首都。
“中,轨迹可能是:步骤1解除”巴黎”和”法国”的掩码(高置信度实体),步骤2解除”首都”的掩码(关系),步骤3解除”是”、“的”(功能词),步骤4解除”。
“(结构)。
轨迹揭示了模型的隐式生成策略——它认为什么最确定就先生成什么。
- 结构锚定:当模型在解码早期就以高置信度预测句尾词元(句号、问号)时,它实际上在处理所有输入信息之前就承诺了特定的输出长度。
这是”锚定”,因为后续解码必须适应那个预先确定的结构。
在图到文本中,如果模型在10个词元后解除句号的掩码,但图包含15个事实,模型必须要么遗漏5个事实,要么产生幻觉填充以到达句号。
锚点约束了内容生成。
- Lambda 缩放:一个简单的推理时技巧,用于延迟结构词元的解码。
对于每个结构词元(句号、逗号等),将其预测置信度乘以因子 lambda(例如0.3)。
这使结构词元人为地变得不那么自信,所以它们被更晚解除掩码。
不需要重新训练——只需在选择解除哪些词元的掩码之前缩放 logits。
随着解码进行,你可以逐渐将 lambda 增加回1.0,允许结构在内容大部分解决后最终确定。
框架转变
之前(自回归 LLMs):              之后(带轨迹分析的 MDLMs):

图 --> 编码器                      图 --> 编码器
        |                                   |
        v                                   v
  从左到右解码                      并行置信度预测
  "巴黎" -> "是" -> "的"                    |
  -> "首都" -> "法国"                       v
  -> "。"                          按优先级解除掩码:
        |                          步骤1:"巴黎"、"法国"(实体)
  固定生成顺序                      步骤2:"首都"(关系)
  (结构与内容混合)                步骤3:"是"、"的"(功能)
                                   步骤4:"。"(结构)
                                            |
                                   内容优先,结构最后
一句话:从强制顺序生成(混合内容和结构),到置信度驱动的并行解码(自然地分离语义内容和句法脚手架)。
专家评审
选题眼光:真实缺口。
图到文本是一个研究充分的任务,但 MDLMs 的并行解码与结构化输入的交互确实未被探索。
轨迹分析是新颖的,揭示了一些非显而易见的东西:MDLMs 有一个隐式的内容优先生成偏好,与图结构对齐。
不是人造问题。
方法成熟度:Lambda 缩放简单得几乎令人尴尬——只是把一些 logits 乘以0.3。
但这是优点,不是缺点。
作者识别了一个特定的失效模式(过早的结构锚定)并提出了最小干预来修复它。
Graph-LLaDA 更复杂但仍然直接:将图变换器编码器插入现有的 MDLM 架构。
没有奇特的训练程序或架构体操。
简单性表明作者对问题的理解足够深入,避免了过度工程化。
实验诚意:基线公平。
跨数据集评估(LAGRANGE 基准)是论文最强的一招——它暴露了先前方法过拟合到数据集特定模式,而 LLM/MDLM 方法泛化更好。
Lambda 缩放带来的 +9.4 BLEU-4 增益是实质性的且可复现的(无需训练,所以没有超参数运气)。
一个小担忧:论文没有深入研究为什么 SFT 导致过早锚定(是损失函数?参考文本分布?),但实证证据是扎实的。
写作功力:轨迹分析部分很出色——清晰地可视化了解码步骤中的解码顺序。
相关工作部分较薄;作者本可以更好地将 MDLMs 相对于其他非自回归生成方法(基于插入、迭代精炼)定位。
消融研究很彻底但埋在附录中——一些应该提升到正文。
总体而言,论文有效地前置了关键洞察(轨迹分析),但后半部分感觉仓促。
判决:弱接收 — 扎实的实证贡献,具有新颖的分析角度(解码轨迹),但对**为什么* SFT 破坏策略的理论理解较浅,写作可以更紧凑。
修复方法的简单性(lambda 缩放)既是优点(实用)也是缺点(感觉增量)。
Graph-LLaDA 的泛化结果将论文提升到纯分析作品之上。
要点总结
对实践者:如果你在结构化生成任务(不仅是图——想想表格、代码、形式语言)上微调掩码扩散模型,检查你的模型是否过早地承诺输出结构。
在推理期间记录解码顺序。
如果结构词元(标点、分隔符、闭合括号)出现得早,在重新训练之前尝试置信度降权作为快速修复。
对研究者:轨迹分析方法是可迁移的。
任何迭代解码模型(不仅是 MDLMs——想想推测解码、迭代精炼)都有隐式的生成顺序。
分析那个顺序可以揭示模型策略与任务结构之间的不对齐。
“模型自然想做什么”和”监督训练强制它做什么”之间的差距是未被充分探索的。
具体技术:Lambda 缩放解码是一个零成本的推理技巧。
如果你有一组应该晚解决的词元(结构、格式、元数据),只需在解码早期缩小它们的 logits 并逐渐恢复它们。
不需要重新训练,不需要架构更改。
适用于任何输出每词元置信度的模型。