
Paper: What Drives Representation Steering? A Mechanistic Case Study on Steering Refusal Authors: Stephen Cheng, Sarah Wiegreffe, Dinesh Manocha Categories: cs.LG
The Gap
Steering vectors have become a popular lightweight technique for aligning LLMs—you add a vector to the model’s hidden states at inference time to encourage or discourage specific behaviors like refusal, hallucination, or persona. They work remarkably well in practice, achieving competitive performance against fine-tuning and prompting. But we have no mechanistic understanding of how they work. Which internal circuits do they activate? How do they interact with attention and MLPs? Without this understanding, we can’t assess robustness, diagnose failures, or design better steering interventions.
This paper conducts the first comprehensive mechanistic analysis of steering vectors, focusing on refusal steering—a critical safety capability where steering has proven highly effective at both inducing and bypassing refusal responses.
[ Steering Vectors ] -> [ Add to Hidden States ] -> [ Behavior Changes ]
         |                        |                          |
         v                        v                          v
[ Problem: Black Box ] -> [ Unknown: Which    ] -> [ Method: Activation ]
[  Mechanism Unknown  ]    [ Circuits Matter?  ]    [ Patching Framework ]
         |                        |                          |
         v                        v                          v
[ Evidence: Refusal  ] <--- [ ~10% of Edges    ] <--- [ Result: OV Circuit ]
[  Steering Works    ]      [ Recover Behavior ]      [ Dominates Effect   ]
The Increment
One sentence: Before this paper, steering vectors were effective but opaque interventions; after this paper, we know they operate through highly localized circuits (~10% of model edges), interact primarily with attention’s OV circuit while largely ignoring the QK circuit, and can be sparsified by 90-99% while retaining performance.
Core Mechanism
The authors extend traditional mechanistic interpretability techniques (typically applied only to standard inference) to steered inference runs. They propose a multi-token activation patching framework that identifies which model components are causally responsible for propagating steering effects across generated sequences.
The key findings:
-
Circuit Localization: Only ~10% of model edges are needed to recover 85% of steering behavior. Different steering methods (Difference-in-Means, Next Token Prediction, Preference Optimization) leverage functionally interchangeable circuits with >90% overlap.
-
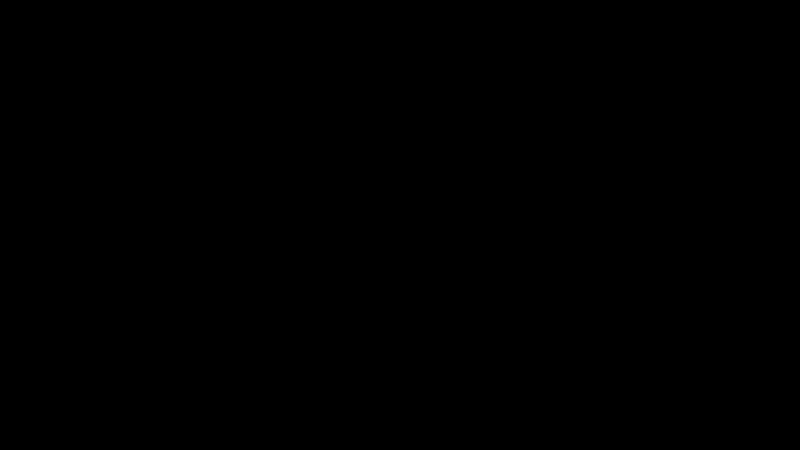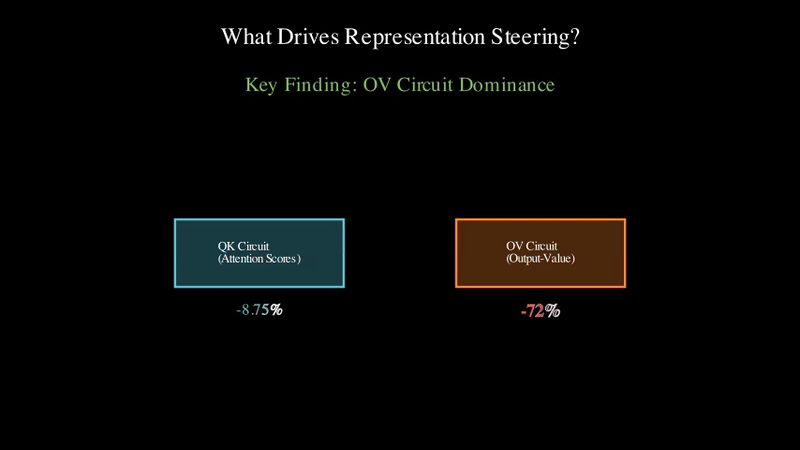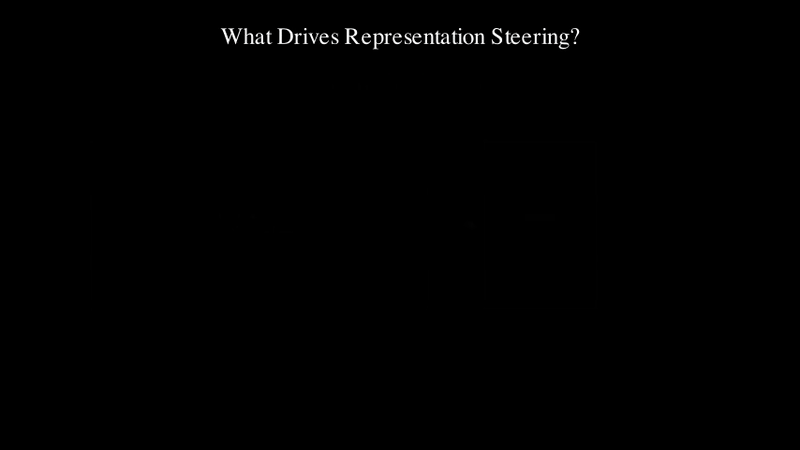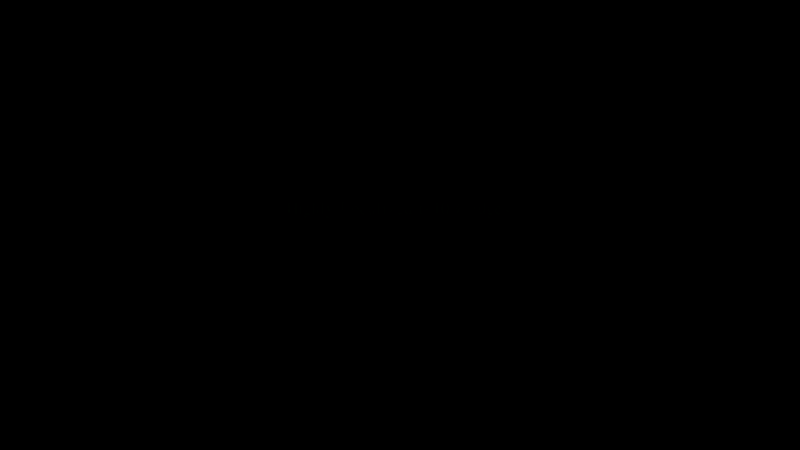
OV Circuit Dominance: Steering vectors primarily interact with attention through the OV (output-value) circuit. Freezing all attention scores (the QK circuit) drops performance by only ~8.75%, while freezing the OV circuit drops it by ~72%.
-
Steering Value Vector (svv) Decomposition: The authors mathematically decompose the direct effect of steering on attention heads, revealing a “steering value vector” for each head. Using logit lens on these svvs surfaces semantically interpretable tokens related to refusal and harmfulness—even when the raw steering vector itself is not interpretable.
-
Extreme Sparsity: Steering vectors can be sparsified to 90-99% zeros while mostly retaining performance. Different steering methods converge on a shared low-dimensional subspace of important dimensions.
Steering Vector s
       |
       v
[ Layer ℓ ] --> [ Attention ] --> [ OV Circuit ] --> svv_h = (s ⊙ γ)W_OV^h
       |              |                                      |
       |              v                                      v
       |        [ QK Circuit ]                    [ Logit Lens Reveals ]
       |        (Frozen: -8.75%)                  [ "forbidden", "illegal" ]
       |                                          [ "dangerous", "unsafe" ]
       v
    [ MLP ]
(Direct Effect: -44.5%)
Think of steering like adjusting a sound equalizer. The steering vector is like boosting certain frequency bands. The OV circuit acts as the main amplifier that propagates these adjustments through the audio chain, while the QK circuit (which determines attention patterns) is like the speaker placement—it matters, but the core signal modification happens elsewhere. The svv decomposition is like analyzing which specific frequencies got boosted, revealing interpretable concepts even when the raw equalizer settings look like random numbers.
Key Concepts
-
Activation Patching: A causal intervention technique that replaces activations from a “corrupted” run with those from a “clean” run to measure which components matter. The authors adapt this to compare steered vs. unsteered generations.
-
EAP-IG (Edge Attribution Patching with Integrated Gradients): An efficient approximation method that computes importance scores for edges in the model’s computational graph by taking gradients with linearly increasing steering coefficients.
-
Circuit Interchangeability: High overlap doesn’t just mean circuits share edges—it means a circuit discovered for one steering method faithfully recovers behavior when using a different steering method’s vector.
-
Gradient-Based Sparsification: Zeroing out dimensions where the ratio of importance score to steering coefficient is below a threshold, effectively keeping only dimensions with high normalized contributions.
Framework Shift
Before (Steering as Black Box):        After (Mechanistic Understanding):
[ Steering Vector ]                    [ Steering Vector ]
        |                                      |
   [Add to h_ℓ]                          [Decompose Effect]
        |                                      |
   [??? Magic ???]                        [~10% Circuit]
        |                                 /          \
   [Behavior Change]              [OV: 72%]    [QK: 8.75%]
                                       |              |
                                   [svv_h]      [Frozen Scores]
                                       |
                                [Interpretable]
                                ["forbidden"]
One sentence: From treating steering as an empirical trick to understanding it as a targeted intervention on specific attention circuits, with the ability to decompose, interpret, and sparsify the mechanism.
Expert Assessment
Problem choice: Excellent. Steering vectors are increasingly used in production systems, but their opacity is a genuine safety concern. Focusing on refusal steering is smart—it’s both safety-critical and has clear success metrics (Attack Success Rate).
Method maturity: The multi-token activation patching framework is a solid extension of existing techniques. The svv decomposition is mathematically clean and provides a reusable tool for future work. The experimental design is thorough—testing multiple steering methods, two model families (Gemma 2 2B, Llama 3.2 3B), and multiple datasets.
Experimental integrity: Strong. The circuit faithfulness metrics are well-defined, the interchangeability tests are convincing (random circuits fail as expected), and the sparsification results are validated across unseen benchmarks. The statistical significance testing on IoU (p<1e-10) is rigorous.
Writing quality: Clear and well-structured. The paper builds from circuit discovery to attention analysis to sparsification in a logical progression. The visualizations (especially Figure 1 showing frozen QK generations) effectively communicate the findings.
Limitations acknowledged: The authors are honest about not deeply analyzing MLPs (which do appear in circuits), only evaluating one steering layer per model, and focusing solely on refusal (though they justify this choice well).
Verdict: Strong Accept — This is foundational work for mechanistic interpretability of steering vectors. The tools (multi-token patching, svv decomposition, gradient-based sparsification) will be widely reused, and the findings have immediate practical implications for making steering more robust and efficient.
Takeaways
Practitioners can immediately apply gradient-based sparsification to compress steering vectors by 90%+ without significant performance loss. This reduces memory overhead and potentially improves robustness by removing noisy dimensions.
The OV circuit dominance finding suggests that future steering methods should focus on how they interact with value projections rather than trying to reshape attention patterns. This could inform more targeted interventions.
The svv decomposition provides a debugging tool: if your steering vector isn’t working, project its effect through individual attention heads to see which concepts are being expressed (or suppressed). This can reveal inefficiencies where some heads work against others.
More broadly, the finding that different steering methods converge to similar circuits and sparse subspaces suggests there may be a “natural” low-dimensional representation of concepts like refusal in LLMs—a promising direction for more principled alignment techniques.
论文: What Drives Representation Steering? A Mechanistic Case Study on Steering Refusal 作者: Stephen Cheng, Sarah Wiegreffe, Dinesh Manocha 分类: cs.LG
缺口
引导向量(Steering Vectors)已成为一种流行的轻量级大语言模型对齐技术——在推理时向模型的隐藏状态添加一个向量,以鼓励或抑制特定行为,如拒绝、幻觉或人格特征。它们在实践中效果显著,性能可与微调和提示工程相媲美。但我们对其工作机制缺乏机制化理解。它们激活了哪些内部电路?如何与注意力和 MLP 交互?缺乏这种理解,我们就无法评估鲁棒性、诊断失败案例,或设计更好的引导干预。
本文对引导向量进行了首次全面的机制化分析,聚焦于拒绝引导——这是一项关键的安全能力,引导技术在诱导和绕过拒绝响应方面都被证明高度有效。
[ 引导向量 ] -> [ 添加到隐藏状态 ] -> [ 行为改变 ]
      |                |                    |
      v                v                    v
[ 问题:黑箱 ] -> [ 未知:哪些    ] -> [ 方法:激活 ]
[ 机制未知   ]    [ 电路起作用?  ]    [ 修补框架   ]
      |                |                    |
      v                v                    v
[ 证据:拒绝 ] <--- [ 约 10% 的边  ] <--- [ 结果:OV 电路 ]
[ 引导有效   ]      [ 恢复行为     ]      [ 主导效应       ]
增量
一句话: 在这篇论文之前,引导向量是有效但不透明的干预手段;在这篇论文之后,我们知道它们通过高度局部化的电路(约 10% 的模型边)运作,主要与注意力的 OV 电路交互,而基本忽略 QK 电路,并且可以稀疏化 90-99% 同时保持性能。
核心机制
作者将传统的机制化可解释性技术(通常仅应用于标准推理)扩展到引导推理运行。他们提出了一个多令牌激活修补框架,识别哪些模型组件对在生成序列中传播引导效应负有因果责任。
关键发现:
-
电路局部化: 仅需约 10% 的模型边即可恢复 85% 的引导行为。不同的引导方法(均值差分、下一令牌预测、偏好优化)利用功能上可互换的电路,重叠度超过 90%。
-
OV 电路主导: 引导向量主要通过 OV(输出-值)电路与注意力交互。冻结所有注意力分数(QK 电路)仅使性能下降约 8.75%,而冻结 OV 电路则使其下降约 72%。
-
引导值向量(svv)分解: 作者数学化地分解了引导对注意力头的直接效应,揭示了每个头的”引导值向量”。对这些 svv 使用 logit lens 可以显示与拒绝和有害性相关的语义可解释令牌——即使原始引导向量本身不可解释。
-
极端稀疏性: 引导向量可以稀疏化到 90-99% 的零值,同时基本保持性能。不同的引导方法收敛到一个共享的低维重要维度子空间。
引导向量 s
       |
       v
[ 层 ℓ ] --> [ 注意力 ] --> [ OV 电路 ] --> svv_h = (s ⊙ γ)W_OV^h
       |          |                                    |
       |          v                                    v
       |    [ QK 电路 ]                      [ Logit Lens 揭示 ]
       |    (冻结: -8.75%)                   [ "forbidden", "illegal" ]
       |                                     [ "dangerous", "unsafe" ]
       v
    [ MLP ]
(直接效应: -44.5%)
可以把引导想象成调整音频均衡器。引导向量就像提升某些频段。OV 电路充当主放大器,将这些调整传播到整个音频链,而 QK 电路(决定注意力模式)就像扬声器的位置——它很重要,但核心信号修改发生在别处。svv 分解就像分析哪些特定频率被提升了,揭示可解释的概念,即使原始均衡器设置看起来像随机数字。
关键概念
-
激活修补(Activation Patching): 一种因果干预技术,用”干净”运行的激活替换”损坏”运行的激活,以测量哪些组件重要。作者将其适配为比较引导与非引导生成。
-
EAP-IG(带积分梯度的边归因修补): 一种高效的近似方法,通过对线性增加的引导系数取梯度,计算模型计算图中边的重要性分数。
-
电路可互换性: 高重叠度不仅意味着电路共享边——它意味着为一种引导方法发现的电路在使用不同引导方法的向量时能忠实地恢复行为。
-
基于梯度的稀疏化: 将重要性分数与引导系数的比率低于阈值的维度归零,有效地只保留具有高归一化贡献的维度。
框架转变
之前(引导作为黑箱):              之后(机制化理解):
[ 引导向量 ]                        [ 引导向量 ]
      |                                  |
  [添加到 h_ℓ]                      [分解效应]
      |                                  |
  [??? 魔法 ???]                     [约 10% 电路]
      |                             /          \
  [行为改变]                   [OV: 72%]    [QK: 8.75%]
                                    |              |
                                [svv_h]      [冻结分数]
                                    |
                             [可解释的]
                             ["forbidden"]
一句话:从将引导视为经验技巧,到理解它是对特定注意力电路的针对性干预,具备分解、解释和稀疏化机制的能力。
专家评审
选题眼光: 优秀。引导向量在生产系统中的使用越来越多,但其不透明性是真正的安全隐患。聚焦于拒绝引导很明智——它既关乎安全又有明确的成功指标(攻击成功率)。
方法成熟度: 多令牌激活修补框架是对现有技术的扎实扩展。svv 分解在数学上很简洁,为未来工作提供了可重用的工具。实验设计很全面——测试了多种引导方法、两个模型家族(Gemma 2 2B、Llama 3.2 3B)和多个数据集。
实验诚意: 强。电路忠实度指标定义明确,可互换性测试令人信服(随机电路如预期般失败),稀疏化结果在未见过的基准上得到验证。对 IoU 的统计显著性检验(p<1e-10)很严格。
写作功力: 清晰且结构良好。论文从电路发现到注意力分析再到稀疏化,逻辑递进。可视化(特别是图 1 显示冻结 QK 的生成)有效地传达了发现。
承认的局限性: 作者诚实地承认没有深入分析 MLP(尽管它们确实出现在电路中),每个模型只评估一个引导层,以及仅关注拒绝(尽管他们很好地证明了这一选择的合理性)。
判决: 强接收 — 这是引导向量机制化可解释性的基础性工作。这些工具(多令牌修补、svv 分解、基于梯度的稀疏化)将被广泛重用,研究发现对使引导更加鲁棒和高效具有直接的实践意义。
要点总结
实践者可以立即应用基于梯度的稀疏化,将引导向量压缩 90% 以上而不会显著损失性能。这减少了内存开销,并可能通过去除噪声维度来提高鲁棒性。
OV 电路主导的发现表明,未来的引导方法应该关注它们如何与值投影交互,而不是试图重塑注意力模式。这可以为更有针对性的干预提供信息。
svv 分解提供了一个调试工具:如果你的引导向量不起作用,将其效应投影到各个注意力头,看看哪些概念被表达(或抑制)。这可以揭示一些头相互对抗的低效情况。
更广泛地说,不同引导方法收敛到相似电路和稀疏子空间的发现表明,在大语言模型中可能存在像拒绝这样的概念的”自然”低维表示——这是更有原则的对齐技术的一个有前景的方向。