Paper: 2604.09529 Authors: Wenyi Xiao, Xinchi Xu, Leilei Gan Categories: cs.CV, cs.AI, cs.CL
The Gap
Existing confidence calibration methods for LVLMs treat confidence as a single number: “How sure are you?” But when a model says “The cat is on the roof” with 90% confidence and gets it wrong, we don’t know if it misidentified a dog as a cat (vision problem) or correctly saw a cat but hallucinated the roof (reasoning problem). Prior work from text-only LLMs uses binary correctness (right/wrong) to train a holistic confidence score, which collapses these distinct failure modes into one signal. This matters because visual uncertainty often gets drowned out by strong language priors—the model “knows” cats sit on things, so it confidently hallucinates even when the image is ambiguous.
Problem: LVLM wrong answer (high confidence)
         |
         v
    Two failure paths:
    /              \
Vision failed    Vision OK, reasoning failed
(blurry image)   (hallucinated context)
         \              /
          v            v
    Prior work: Single confidence score
                (can't distinguish causes)
         |
         v
    This paper: Decouple into visual + reasoning confidence
         |
         v
    Evidence: Improved calibration + accuracy on 13 benchmarks
         |
         v
    Conclusion: Separating confidence sources reduces hallucinations
The Increment
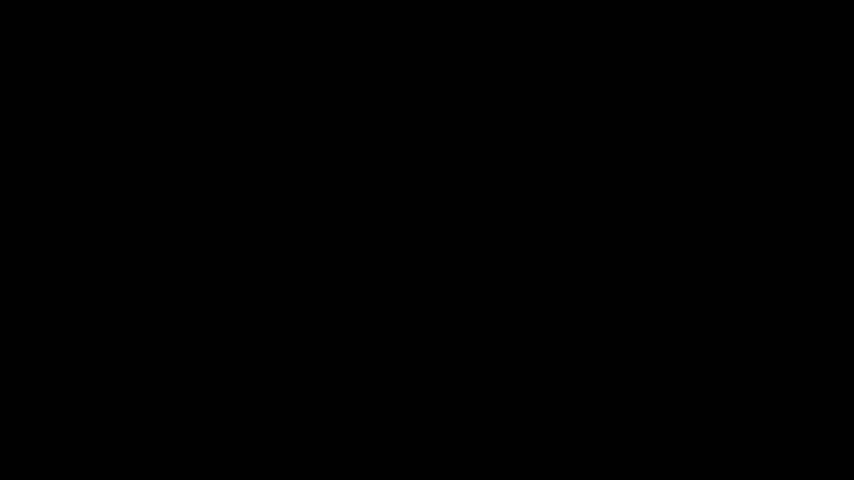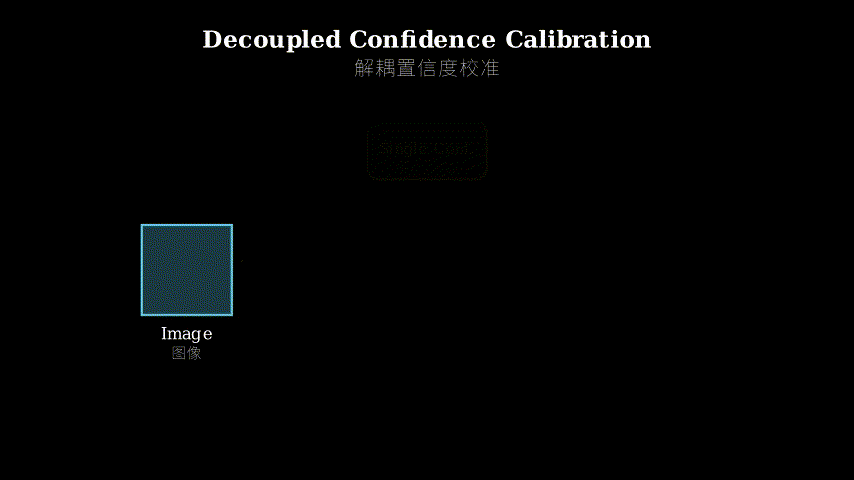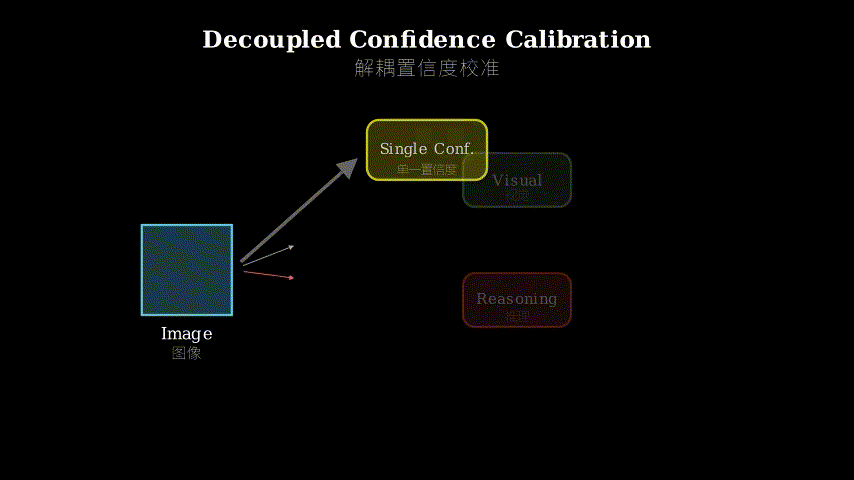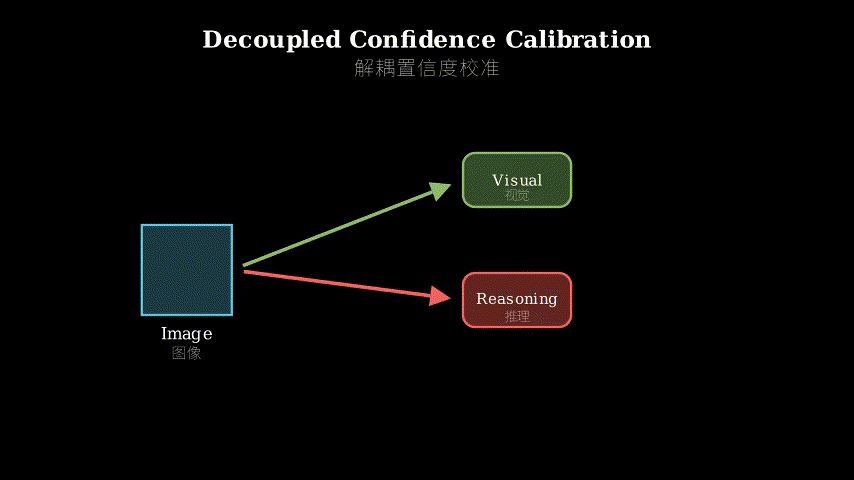
One sentence: Before this paper, LVLMs had one confidence knob for everything; after, they have separate knobs for “did I see it right” and “did I reason correctly,” which lets them catch visual hallucinations without crippling valid reasoning.
Core Mechanism
VL-Calibration adds two confidence heads to an LVLM: one for visual confidence, one for reasoning confidence. During inference, the model generates both an answer and these two confidence scores. The training uses reinforcement learning (specifically PPO) with a reward that checks if the final answer is correct. But here’s the trick: instead of treating all tokens equally, the framework estimates which tokens depend heavily on visual grounding versus which are pure reasoning.
For visual confidence supervision, the paper introduces an intrinsic visual certainty metric combining two signals: (1) visual grounding measured by how much the model’s attention changes when you perturb the image (KL-divergence), and (2) internal certainty measured by token entropy. High grounding + low entropy = visually certain. This metric doesn’t need ground-truth perception labels—it’s self-supervised.
The RL optimization uses token-level advantage reweighting: tokens with high visual certainty get more weight when training visual confidence, while tokens with low visual certainty (likely hallucinated) get suppressed. This prevents the model from confidently asserting things it didn’t actually see, while preserving its ability to reason confidently about what it did see.
Input: Image + Question
         |
         v
    LVLM backbone
         |
    +----+----+
    |         |
    v         v
Visual     Reasoning
confidence confidence
head       head
    |         |
    +----+----+
         |
         v
    Answer + two confidence scores

Training loop (RL):
    Reward = answer correctness
    Visual certainty = grounding (KL) + entropy
    Token weight = f(visual certainty)
    Update heads with weighted advantages
Think of it like a witness testifying in court. The old approach asks: “How confident are you in your testimony?” The witness gives one number, but you don’t know if they’re unsure because the lighting was bad (vision) or because they’re fuzzy on the timeline (reasoning). VL-Calibration asks two questions: “How clearly did you see it?” and “How sure are you about what it means?” Now when the witness says “I’m 90% sure I saw it clearly, but only 40% sure about the timeline,” you know where the uncertainty lives. The visual certainty metric is like checking if the witness squints when describing details (low grounding) or hesitates between words (high entropy)—signs they’re filling in gaps rather than reporting what they saw.
Key Concepts
-
Decoupled Confidence: Instead of one confidence score for the entire answer, split it into visual confidence (how well did I perceive the image) and reasoning confidence (how sound is my logic given what I perceived). This matters because an LVLM might correctly identify objects but hallucinate their relationships, or misidentify objects but reason correctly about what it thinks it saw. A single confidence score can’t capture this—it’s like averaging your vision prescription with your IQ score. Decoupling lets the model say “I saw this clearly but I’m unsure about the conclusion” or “I’m confident in my reasoning but the image was ambiguous.”
-
Intrinsic Visual Certainty: A self-supervised metric that estimates how grounded a token is in the actual image, without needing human labels for what the model “should” have seen. It combines two signals: (1) If you slightly perturb the image (add noise, crop), does the model’s attention distribution change a lot? High change = low grounding. (2) Is the model’s token probability distribution sharp (low entropy) or diffuse (high entropy)? Low entropy = more certain. Together, these catch when the model is “making stuff up”—if attention doesn’t change with image perturbations, the token is driven by language priors, not vision. If entropy is high, the model itself is uncertain. This is like checking if someone’s description changes when you show them the photo from different angles—if it doesn’t, they’re not really looking at the photo.
-
Token-Level Advantage Reweighting: In reinforcement learning, the “advantage” tells you how much better an action was than expected. Standard RL treats all tokens equally when updating the model. This paper weights each token’s advantage by its visual certainty—tokens that are visually grounded get more influence on the visual confidence head, while uncertain tokens (likely hallucinations) get downweighted. This focuses the optimization: “Learn to be confident about what you actually saw, and learn to be uncertain about what you’re guessing.” Without this, the model might learn to be confident about hallucinations if they happen to produce correct answers by luck, reinforcing bad behavior.
Framework Shift
Before (mainstream approach):        After (this paper):

Image + Question                     Image + Question
      |                                    |
      v                                    v
   LVLM                                 LVLM
      |                                    |
      v                              +-----+-----+
   Answer                            |           |
      |                              v           v
      v                          Visual      Reasoning
Single confidence <--RL--      confidence   confidence
"How sure?"                        |           |
                                   +-----+-----+
Binary reward:                           |
correct/incorrect                        v
                                     Answer
                                        |
                                        v
                                   Weighted RL:
                                   - Visual certainty metric
                                   - Token-level reweighting
                                   - Separate head updates
From monolithic confidence to diagnostic confidence, the core shift is treating uncertainty as a structured signal with identifiable sources rather than a scalar summary.
Expert Assessment
Problem choice: This is a real gap. LVLMs hallucinate confidently, and existing calibration methods from text-only LLMs don’t account for the vision-language interface. The problem sits at a critical juncture—LVLMs are being deployed in high-stakes domains (medical imaging, autonomous vehicles) where distinguishing “I can’t see” from “I don’t know” matters. The framing is sharp: prior work conflates failure modes, this paper separates them.
Method maturity: The intrinsic visual certainty metric is clever—using KL-divergence under perturbations to measure grounding is elegant and doesn’t require perception labels. However, the method is somewhat complex (two confidence heads, RL with custom reweighting, multiple hyperparameters). A simpler baseline would be: just train a visual confidence head with image perturbation consistency as supervision, no RL. The paper doesn’t explore this, which makes me wonder if the RL machinery is necessary or if it’s solving a problem that could be addressed more directly.
Experimental integrity: Thirteen benchmarks is thorough. The baselines include recent verbalized confidence methods (Self-Consistency, P(True), etc.), which is fair. The ablations show each component contributes, though I’d like to see failure case analysis—when does decoupling hurt? The out-of-distribution generalization is a strong signal. One red flag: no comparison to simpler non-RL approaches (e.g., just training visual confidence with perturbation loss). The numbers look good, but the paper doesn’t prove RL is essential versus just having two heads.
Writing quality: The abstract and intro are clear. The method section gets dense—Figure 2 tries to show everything at once and ends up cluttered. The intrinsic visual certainty metric is buried in Section 3.2 when it’s actually the key insight; it should be front and center. The related work section is thorough but reads like a checklist. If I were rewriting, I’d lead with a concrete failure example (show an LVLM hallucinating confidently), then introduce decoupled confidence as the solution, then dive into how to train it without perception labels. The current structure makes you work to see why this matters.
Verdict: weak accept — Solid contribution with clear improvements, but the method complexity and lack of simpler baselines leave questions about what’s essential versus what’s engineering.
Takeaways
The intrinsic visual certainty metric (KL-divergence under perturbations + token entropy) is immediately useful beyond this paper. If you’re working with any vision-language model and want to detect hallucinations without ground-truth labels, this gives you a self-supervised signal. The broader idea—decomposing confidence by failure mode—transfers to other multimodal settings: audio-text models could separate acoustic confidence from linguistic confidence, robotics could separate perception confidence from planning confidence. The token-level reweighting trick is also portable: whenever you’re doing RL on sequences and some tokens are more trustworthy than others, weight the advantages accordingly. Don’t just copy the two-head architecture; steal the diagnostic mindset: when a model fails, ask “which component failed?” and design confidence to answer that question.
论文: 2604.09529 作者: Wenyi Xiao, Xinchi Xu, Leilei Gan 分类: cs.CV, cs.AI, cs.CL
缺口
现有的大型视觉-语言模型(LVLM)置信度校准方法把置信度当作一个数字:“你有多确定?“但当模型以90%的置信度说”猫在屋顶上”却错了时,我们不知道是把狗误认成猫了(视觉问题),还是正确看到了猫但幻觉出了屋顶(推理问题)。
此前从纯文本大语言模型借鉴来的方法用二元正确性(对/错)训练一个整体置信度分数,这把两种不同的失败模式压缩成了一个信号。
这很重要,因为视觉不确定性常常被强语言先验淹没——模型”知道”猫会坐在东西上,所以即使图像模糊,它也会自信地产生幻觉。
问题:LVLM 错误答案(高置信度)
         |
         v
    两条失败路径:
    /              \
视觉失败          视觉正常,推理失败
(图像模糊)      (幻觉出上下文)
         \              /
          v            v
    此前工作:单一置信度分数
              (无法区分原因)
         |
         v
    本文:解耦为视觉置信度 + 推理置信度
         |
         v
    证据:13个基准上校准和准确率均提升
         |
         v
    结论:分离置信度来源可减少幻觉
增量
一句话: 这篇论文之前,LVLM只有一个管所有事的置信度旋钮;之后,它们有了两个独立旋钮——“我看对了吗”和”我推理对了吗”,这让模型能捕捉视觉幻觉而不削弱有效推理。
核心机制
VL-Calibration给LVLM加了两个置信度头:一个管视觉置信度,一个管推理置信度。
推理时,模型生成答案和这两个置信度分数。
训练用强化学习(具体是PPO),奖励检查最终答案是否正确。
但关键在于:框架不是平等对待所有token,而是估计哪些token严重依赖视觉定位,哪些是纯推理。
对于视觉置信度的监督,论文引入了内在视觉确定性指标,结合两个信号:(1)视觉定位,通过扰动图像时模型注意力变化程度(KL散度)来衡量;(2)内部确定性,通过token熵来衡量。
高定位度 + 低熵 = 视觉确定。
这个指标不需要真实感知标签——它是自监督的。
强化学习优化使用token级优势重加权:视觉确定性高的token在训练视觉置信度时权重更大,而视觉确定性低的token(可能是幻觉)被抑制。
这防止模型对它实际没看到的东西自信断言,同时保留对它确实看到的东西进行自信推理的能力。
输入:图像 + 问题
         |
         v
    LVLM 主干
         |
    +----+----+
    |         |
    v         v
视觉置信度  推理置信度
头部        头部
    |         |
    +----+----+
         |
         v
    答案 + 两个置信度分数

训练循环(强化学习):
    奖励 = 答案正确性
    视觉确定性 = 定位度(KL)+ 熵
    Token权重 = f(视觉确定性)
    用加权优势更新头部
把它想象成法庭上的证人作证。
旧方法问:“你对证词有多确定?“证人给一个数字,但你不知道他们不确定是因为光线不好(视觉)还是时间线记不清(推理)。
VL-Calibration问两个问题:“你看得多清楚?“和”你对它的含义有多确定?“现在当证人说”我90%确定看得很清楚,但对时间线只有40%把握”时,你就知道不确定性在哪里。
视觉确定性指标就像检查证人描述细节时是否眯眼(低定位度)或说话时犹豫(高熵)——这些是他们在填补空白而非报告所见的迹象。
关键概念
- 解耦置信度: 不是给整个答案一个置信度分数,而是拆分成视觉置信度(我对图像的感知有多好)和推理置信度(基于我的感知,我的逻辑有多可靠)。
这很重要,因为LVLM可能正确识别物体但幻觉出它们的关系,或者误识别物体但对它认为看到的东西推理正确。
单一置信度分数无法捕捉这一点——就像把你的视力处方和智商分数平均一样。
解耦让模型能说”我看得很清楚但对结论不确定”或”我对推理有信心但图像模糊”。
- 内在视觉确定性: 一个自监督指标,估计token在多大程度上基于实际图像,不需要人工标注模型”应该”看到什么。
它结合两个信号:(1)如果你轻微扰动图像(加噪声、裁剪),模型的注意力分布变化大吗?变化大 = 定位度低。
(2)模型的token概率分布是尖锐的(低熵)还是分散的(高熵)?低熵 = 更确定。
两者结合能捕捉模型何时在”编造”——如果注意力不随图像扰动变化,token是由语言先验驱动的,不是视觉。
如果熵高,模型自己也不确定。
这就像检查某人从不同角度看照片时描述是否改变——如果不变,他们其实没在看照片。
- Token级优势重加权: 在强化学习中,“优势”告诉你一个动作比预期好多少。
标准强化学习更新模型时平等对待所有token。
本文用视觉确定性给每个token的优势加权——视觉定位好的token对视觉置信度头影响更大,而不确定的token(可能是幻觉)被降权。
这聚焦优化:“学会对你真正看到的东西自信,对你猜测的东西不确定。
“没有这个,模型可能学会对幻觉自信,如果它们碰巧产生正确答案,从而强化坏行为。
框架转变
之前(主流方法):                之后(本文方法):

图像 + 问题                       图像 + 问题
      |                                |
      v                                v
   LVLM                              LVLM
      |                                |
      v                          +-----+-----+
   答案                          |           |
      |                          v           v
      v                      视觉置信度  推理置信度
单一置信度 <--强化学习--            |           |
"有多确定?"                    +-----+-----+
                                     |
二元奖励:                           v
正确/错误                         答案
                                     |
                                     v
                                加权强化学习:
                                - 视觉确定性指标
                                - Token级重加权
                                - 分别更新头部
从整体置信度到诊断式置信度,核心转变是把不确定性当作有结构的、来源可识别的信号,而非标量摘要。
专家评审
选题眼光: 这是真缺口。
LVLM会自信地产生幻觉,而从纯文本大语言模型来的现有校准方法不考虑视觉-语言接口。
问题处于关键节点——LVLM正被部署到高风险领域(医学影像、自动驾驶),区分”看不清”和”想不通”很重要。
问题框定清晰:此前工作混淆失败模式,本文分离它们。
方法成熟度: 内在视觉确定性指标很巧妙——用扰动下的KL散度衡量定位度很优雅,不需要感知标签。
但方法有些复杂(两个置信度头、带自定义重加权的强化学习、多个超参数)。
一个更简单的基线是:只用图像扰动一致性作为监督训练视觉置信度头,不用强化学习。
论文没探索这个,让我怀疑强化学习机制是否必要,还是它在解决一个可以更直接处理的问题。
实验诚意: 十三个基准很全面。
基线包括最近的语言化置信度方法(Self-Consistency、P(True)等),这很公平。
消融实验显示每个组件都有贡献,但我想看失败案例分析——解耦何时有害?分布外泛化是强信号。
一个警示:没有与更简单的非强化学习方法比较(例如只用扰动损失训练视觉置信度)。
数字看起来不错,但论文没证明强化学习是必需的,还是只是有两个头就够了。
写作功力: 摘要和引言清晰。
方法部分变得密集——图2试图一次展示所有内容,结果显得杂乱。
内在视觉确定性指标埋在3.2节,而它实际是关键洞见;应该放在前面中心位置。
相关工作部分很全面但读起来像清单。
如果我重写,我会先展示一个具体失败例子(展示LVLM自信地产生幻觉),然后引入解耦置信度作为解决方案,再深入如何在没有感知标签的情况下训练它。
当前结构让你费力才能看出为什么这重要。
判决: 弱接收 — 扎实的贡献,有明确改进,但方法复杂性和缺乏更简单基线留下了关于什么是必需的、什么是工程的问题。
要点总结
内在视觉确定性指标(扰动下的KL散度 + token熵)在本文之外立即有用。
如果你在做任何视觉-语言模型,想在没有真实标签的情况下检测幻觉,这给你一个自监督信号。
更广泛的想法——按失败模式分解置信度——可迁移到其他多模态场景:音频-文本模型可以分离声学置信度和语言置信度,机器人可以分离感知置信度和规划置信度。
Token级重加权技巧也可移植:每当你对序列做强化学习,某些token比其他token更可信时,相应地加权优势。
不要只复制双头架构;偷走诊断思维:当模型失败时,问”哪个组件失败了?“并设计置信度来回答这个问题。