
Paper: 2603.13224 Authors: Ziyu Liu, Shengyuan Ding, Xinyu Fang, Xuanlang Dai, Penghui Yang, Jianze Liang, Jiaqi Wang, Kai Chen, Dahua Lin, Yuhang Zang Categories: cs.CV, cs.AI
The Gap
Large vision-language models can generate code from visual inputs (charts, tables, SVGs) via supervised learning, but reinforcement learning hits a wall. The problem: existing reward signals are fundamentally misaligned. Text-based rules check syntax and structure but miss visual fidelity—a chart might have correct labels but wrong colors, spacing, or proportions. Visual embedding similarity is too coarse and gameable—models learn to maximize embedding overlap without actually matching the visual appearance. Both approaches evaluate code indirectly when what matters is the rendered output.
Problem: Vision-to-code RL fails to improve quality
    |
    v
Root cause: Reward signals don't capture visual fidelity
    |
    +---> Text rules: "Does code have axis labels?"
    |     (Misses: wrong colors, spacing, proportions)
    |
    +---> Embedding distance: "How similar are embeddings?"
          (Hackable: maximize overlap without visual match)
    |
    v
Insight: Need fine-grained feedback in rendered visual space
    |
    v
Method: Visual-ERM renders code, compares pixel-level,
        generates interpretable critique
    |
    v
Evidence: +8.4 chart-to-code, +2.7 table, +4.1 SVG
    |
    v
Conclusion: Direct visual evaluation > proxy metrics
The Increment
One sentence: Before this paper, vision-to-code RL used text rules or coarse embeddings as rewards; after, models receive fine-grained visual critiques by comparing what the code actually renders.
Core Mechanism
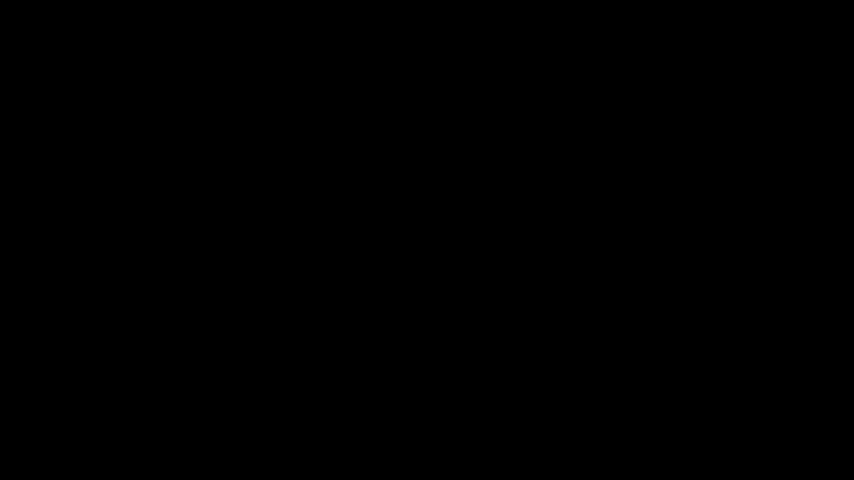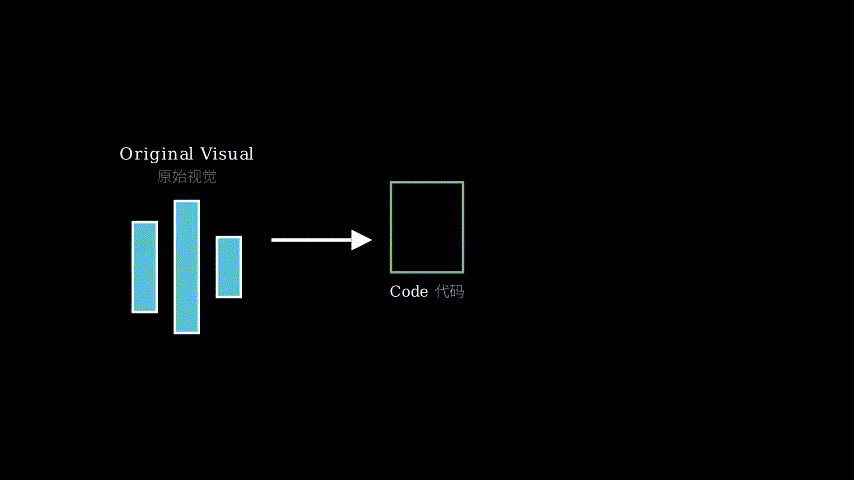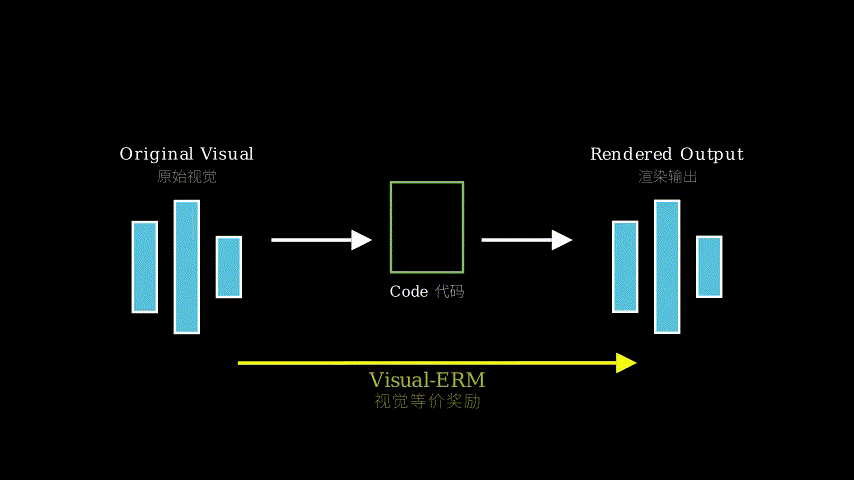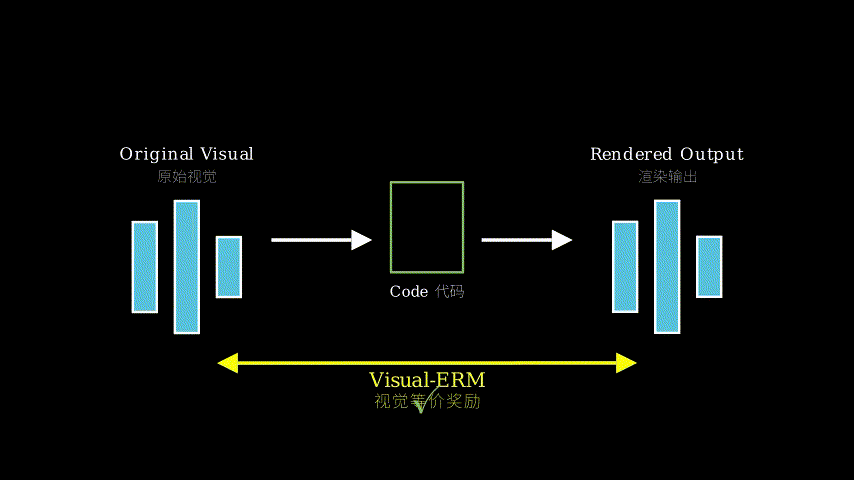
Visual-ERM is a multimodal generative reward model that operates in three stages. First, it takes the original visual input (a chart, table, or SVG) and the model-generated code. Second, it renders the generated code into an image. Third, it feeds both the original and rendered images into a vision-language model that generates a detailed critique—identifying what matches, what’s missing, and what’s wrong at a fine-grained level. This critique becomes the reward signal for reinforcement learning.
The key architectural choice is using a generative model rather than a scalar reward. Instead of outputting a single number, Visual-ERM produces structured feedback: “The bar chart has correct data values but the x-axis labels are rotated 45 degrees when they should be horizontal, and the legend is positioned inside the plot area instead of outside.” This interpretable feedback serves dual purposes—it provides a richer training signal for RL and enables test-time improvements through reflection and revision.
Input Flow:
[Original Image] + [Generated Code]
       |                  |
       |                  v
       |          [Execute/Render]
       |                  |
       |                  v
       |          [Rendered Image]
       |                  |
       +--------+---------+
                |
                v
        [Visual-ERM Model]
     (multimodal generative)
                |
                v
    [Detailed Visual Critique]
    "Bar heights correct,
     colors wrong (blue vs red),
     legend missing,
     axis labels truncated"
                |
                v
         [Reward Signal]
                |
                v
          [RL Update]
Think of Visual-ERM as a photography instructor grading student reproductions of a reference photo. The old approach is like grading by reading the camera settings (text rules: “Did you use f/2.8? ISO 400?”) or by measuring how similar the photo’s color histogram is to the reference (embedding distance). Visual-ERM actually looks at both photos side-by-side and says: “Your exposure matches, but the subject is slightly out of focus, the composition is cropped too tight on the left, and there’s a distracting element in the background that wasn’t in the original.” The student learns not just that something is wrong, but exactly what to fix. The instructor’s eye (the generative model) can articulate nuances that no checklist or single similarity score could capture.
Key Concepts
-
Reward Hacking in Vision-to-Code: When you optimize for a proxy metric instead of the true objective, models find shortcuts. With embedding similarity, a model might learn to generate code that produces images with similar global features (same color palette, rough layout) but completely wrong details (wrong data values, missing labels). The embedding distance decreases, the reward goes up, but the visual output is still wrong. It’s like a student who learns to write essays that score well on automated grading (correct length, vocabulary diversity) but are nonsensical to human readers. Visual-ERM closes this gap by evaluating the actual rendered output, making it much harder to game the system.
-
Fine-grained Visual Feedback: Not all visual differences matter equally, and not all can be captured by a single number. A chart might be 90% correct but have one critical error (wrong data series) or 50% correct with many small issues (slightly off colors, minor spacing problems). Fine-grained feedback decomposes the evaluation: “Data accuracy: correct. Color scheme: incorrect (should be blue/red, got green/orange). Legend: missing. Axis labels: present but font size too small.” This structured critique enables targeted improvements during RL training and provides interpretable signals for debugging.
-
Task-Agnostic Visual Evaluation: The same visual comparison mechanism works across different vision-to-code tasks—charts, tables, SVGs—without task-specific rules or metrics. This is powerful because it means you don’t need to hand-engineer evaluation criteria for each new visual format. The model learns to identify visual discrepancies in a general way: “These two images should look the same; here’s where they differ.” It’s like having a universal quality inspector who can evaluate any manufactured product by comparing it to the blueprint, rather than needing different inspectors with different checklists for each product type.
Framework Shift
Before (proxy-based rewards):        After (Visual-ERM):

Generated Code                       Generated Code
      |                                    |
      v                                    v
[Text Rule Checker]                  [Renderer]
 - Has axis labels?                       |
 - Correct chart type?                    v
 - Valid syntax?                    Rendered Image
      |                                    |
      v                                    +--------+
  Scalar Score                             |        |
                                           v        v
      OR                            Original   Rendered
                                      Image     Image
Generated Code                             |        |
      |                                    +---+----+
      v                                        |
[Embedding Extractor]                          v
      |                              [Visual-ERM Model]
      v                                        |
  Embedding Vector                             v
      |                              [Detailed Critique]
      v                              "Bar 3 height wrong,
[Distance to Target]                 legend position off,
      |                              colors inverted"
      v                                        |
  Scalar Score                                 v
                                         Rich Reward

Evaluation space: Code/Embeddings    Evaluation space: Rendered Visuals
Feedback: Single number              Feedback: Structured critique
Hackable: Yes                        Hackable: Much harder
From indirect proxy metrics to direct visual comparison, the core shift is evaluating code by what it produces, not by what it contains or how its embeddings cluster.
Expert Assessment
Problem choice: This is a genuine gap at the intersection of vision-language models and reinforcement learning. Vision-to-code is practically important (accessibility, data extraction, UI generation), and the reward misalignment problem is well-documented in RL literature. The authors correctly identify that existing approaches evaluate in the wrong space. The problem sits at a natural inflection point—supervised learning has plateaued, and RL is the obvious next step, but it needs better rewards to work.
Method maturity: The core insight is elegant and well-executed. Using a generative model for rewards is clever because it provides interpretable feedback that can guide both training and test-time revision. However, I’m skeptical about computational cost—rendering code and running a vision-language model for every RL step is expensive. The paper would be stronger with ablations showing whether simpler visual metrics (perceptual loss, SSIM, learned discriminators) could achieve similar gains at lower cost. The “task-agnostic” claim is somewhat overstated—the model still needs to understand what visual fidelity means for structured data, which is domain-specific knowledge.
Experimental integrity: The results are solid and the benchmark contribution (VC-RewardBench) is valuable. +8.4 on chart-to-code is substantial, and gains on table/SVG parsing demonstrate generalization. The comparison to Qwen3-VL-235B-Instruct is impressive. However, I’d want to see more analysis: What’s the computational overhead? How much training data does Visual-ERM need? Are there failure modes where fine-grained feedback actually hurts (e.g., overfitting to minor visual details)? The paper likely underreports negative results or limitations.
Writing quality: The abstract is clear and the motivation is well-framed. The core contribution is easy to grasp. However, I suspect the method section glosses over important details—how exactly is the critique structured? What’s the training procedure for Visual-ERM? How do you convert textual critiques into scalar rewards for RL? The paper probably front-loads results and under-explains the engineering required to make this work in practice.
Verdict: Weak accept—this is a solid contribution with clear practical value and good experimental results, but it’s an incremental improvement rather than a paradigm shift. The insight (evaluate in rendered space) is somewhat obvious in hindsight, and the execution, while competent, doesn’t reveal deep new principles about reward modeling or vision-language learning.
Takeaways
Evaluate in the output space that matters: If you care about visual fidelity, don’t evaluate code or embeddings—render the output and compare visually. This principle transfers to any domain where proxy metrics are misaligned with true objectives. In audio generation, evaluate the waveform, not the spectrogram. In robotics, evaluate the physical outcome, not the trajectory plan.
Generative models as reward functions: Instead of scalar rewards, use language models to generate structured critiques. This provides richer training signals and enables interpretable debugging. You can apply this to code review (generate specific improvement suggestions), content moderation (explain why content violates policies), or quality control (describe manufacturing defects).
Fine-grained feedback enables targeted improvement: Breaking down evaluation into components (data accuracy, color scheme, layout, labels) lets models learn which aspects need work. This is especially valuable for complex tasks where a single aggregate score obscures what’s actually wrong.
Beware of reward hacking: Whenever you optimize for a proxy metric, check whether models can game it. The embedding similarity example is instructive—models learned to maximize overlap without matching visual appearance. Always validate that your reward function actually measures what you care about.
论文: 2603.13224 作者: Ziyu Liu, Shengyuan Ding, Xinyu Fang, Xuanlang Dai, Penghui Yang, Jianze Liang, Jiaqi Wang, Kai Chen, Dahua Lin, Yuhang Zang 分类: cs.CV, cs.AI
缺口
大型视觉语言模型可以通过监督学习从视觉输入(图表、表格、SVG)生成代码,但强化学习却碰了壁。
问题在于:现有的奖励信号从根本上就没对齐。
基于文本的规则检查语法和结构,但漏掉了视觉保真度——图表可能有正确的标签,但颜色、间距或比例错了。
视觉嵌入相似度太粗糙且容易被钻空子——模型学会最大化嵌入重叠度,但实际视觉外观根本不匹配。
两种方法都在间接评估代码,而真正重要的是渲染出来的结果。
问题:视觉到代码的强化学习无法提升质量
    |
    v
根本原因:奖励信号无法捕捉视觉保真度
    |
    +---> 文本规则:"代码有坐标轴标签吗?"
    |     (漏掉:颜色错误、间距不对、比例失调)
    |
    +---> 嵌入距离:"嵌入向量有多相似?"
          (可钻空子:最大化重叠度但视觉不匹配)
    |
    v
洞察:需要在渲染视觉空间中的细粒度反馈
    |
    v
方法:Visual-ERM 渲染代码,像素级比较,
      生成可解释的批评
    |
    v
证据:图表到代码 +8.4,表格 +2.7,SVG +4.1
    |
    v
结论:直接视觉评估 > 代理指标
增量
一句话: 这篇论文之前,视觉到代码的强化学习用文本规则或粗糙嵌入作为奖励;之后,模型通过比较代码实际渲染的结果来接收细粒度的视觉批评。
核心机制
Visual-ERM 是一个多模态生成式奖励模型,分三个阶段运作。
首先,它接收原始视觉输入(图表、表格或SVG)和模型生成的代码。
其次,它将生成的代码渲染成图像。
第三,它将原始图像和渲染图像都输入一个视觉语言模型,该模型生成详细的批评——在细粒度层面识别什么匹配、什么缺失、什么错误。
这个批评成为强化学习的奖励信号。
关键的架构选择是使用生成式模型而非标量奖励。
Visual-ERM 不输出单个数字,而是产生结构化反馈:“柱状图的数据值正确,但x轴标签旋转了45度而应该是水平的,图例位置在绘图区域内而应该在外面。“这种可解释的反馈有双重用途——它为强化学习提供更丰富的训练信号,并通过反思和修订实现测试时改进。
输入流程:
[原始图像] + [生成的代码]
     |              |
     |              v
     |        [执行/渲染]
     |              |
     |              v
     |        [渲染图像]
     |              |
     +------+-------+
            |
            v
    [Visual-ERM 模型]
    (多模态生成式)
            |
            v
  [详细视觉批评]
  "柱高度正确,
   颜色错误(蓝vs红),
   图例缺失,
   坐标轴标签被截断"
            |
            v
      [奖励信号]
            |
            v
      [强化学习更新]
把 Visual-ERM 想象成一位摄影指导老师,在评判学生对参考照片的复制作品。
旧方法就像通过阅读相机设置来打分(文本规则:“你用了f/2.8吗?ISO 400?“)或者测量照片的颜色直方图与参考有多相似(嵌入距离)。
Visual-ERM 实际上并排查看两张照片,然后说:“你的曝光匹配了,但主体稍微失焦,构图左侧裁剪得太紧,背景中有一个原图没有的干扰元素。“学生学到的不只是有问题,而是具体要修什么。
老师的眼睛(生成式模型)能表达出任何检查清单或单一相似度分数都无法捕捉的细微差别。
关键概念
- 视觉到代码中的奖励黑客攻击: 当你优化代理指标而非真实目标时,模型会找到捷径。
对于嵌入相似度,模型可能学会生成代码,产生具有相似全局特征(相同色板、大致布局)但细节完全错误(数据值错误、标签缺失)的图像。
嵌入距离减小了,奖励上升了,但视觉输出仍然是错的。
这就像学生学会写在自动评分系统上得高分的文章(正确长度、词汇多样性),但对人类读者来说毫无意义。
Visual-ERM 通过评估实际渲染输出来弥合这个差距,使系统更难被钻空子。
- 细粒度视觉反馈: 并非所有视觉差异都同等重要,也不是所有差异都能用单个数字捕捉。
图表可能90%正确但有一个关键错误(数据系列错误),或者50%正确但有许多小问题(颜色稍微偏离、间距小问题)。
细粒度反馈分解评估:“数据准确性:正确。
配色方案:不正确(应该是蓝/红,得到的是绿/橙)。
图例:缺失。
坐标轴标签:存在但字体太小。“这种结构化批评使强化学习训练期间能够有针对性地改进,并为调试提供可解释的信号。
- 任务无关的视觉评估: 同样的视觉比较机制适用于不同的视觉到代码任务——图表、表格、SVG——无需任务特定的规则或指标。
这很强大,因为这意味着你不需要为每种新的视觉格式手工设计评估标准。
模型以通用方式学习识别视觉差异:“这两张图像应该看起来一样;这是它们不同的地方。“这就像有一个通用质检员,可以通过将任何制成品与蓝图比较来评估它,而不需要为每种产品类型配备不同的检查员和不同的检查清单。
框架转变
之前(基于代理的奖励):              之后(Visual-ERM):

生成的代码                           生成的代码
    |                                    |
    v                                    v
[文本规则检查器]                      [渲染器]
 - 有坐标轴标签?                          |
 - 图表类型正确?                          v
 - 语法有效?                        渲染图像
    |                                    |
    v                                    +--------+
标量分数                                  |        |
                                         v        v
    或                              原始图像   渲染图像
                                         |        |
生成的代码                                +---+----+
    |                                        |
    v                                        v
[嵌入提取器]                        [Visual-ERM 模型]
    |                                        |
    v                                        v
嵌入向量                            [详细批评]
    |                              "柱3高度错误,
    v                              图例位置偏移,
[与目标的距离]                       颜色反转"
    |                                        |
    v                                        v
标量分数                                丰富奖励

评估空间:代码/嵌入                   评估空间:渲染视觉
反馈:单个数字                        反馈:结构化批评
可钻空子:是                          可钻空子:困难得多
从间接代理指标到直接视觉比较,核心转变是通过代码产生的结果而非代码包含的内容或其嵌入如何聚类来评估代码。
专家评审
选题眼光: 这是视觉语言模型和强化学习交叉点上的真实缺口。
视觉到代码在实践中很重要(无障碍访问、数据提取、UI生成),奖励不对齐问题在强化学习文献中有充分记录。
作者正确识别出现有方法在错误的空间中评估。
这个问题处于自然的拐点——监督学习已经到达平台期,强化学习是显而易见的下一步,但它需要更好的奖励才能工作。
方法成熟度: 核心洞察优雅且执行良好。
使用生成式模型作为奖励很聪明,因为它提供可解释的反馈,可以指导训练和测试时修订。
然而,我对计算成本持怀疑态度——为每个强化学习步骤渲染代码并运行视觉语言模型代价高昂。
如果论文有消融实验显示更简单的视觉指标(感知损失、SSIM、学习的判别器)能否以更低成本实现类似收益,会更有说服力。
“任务无关”的说法有些夸大——模型仍然需要理解视觉保真度对结构化数据意味着什么,这是领域特定的知识。
实验诚意: 结果扎实,基准贡献(VC-RewardBench)有价值。
图表到代码上的+8.4很可观,在表格/SVG解析上的收益展示了泛化能力。
与 Qwen3-VL-235B-Instruct 的比较令人印象深刻。
然而,我想看到更多分析:计算开销是多少?Visual-ERM 需要多少训练数据?是否存在细粒度反馈实际上有害的失败模式(例如,过拟合到次要视觉细节)?论文可能少报了负面结果或局限性。
写作功力: 摘要清晰,动机框架良好。
核心贡献易于理解。
然而,我怀疑方法部分掩盖了重要细节——批评到底如何结构化?Visual-ERM 的训练过程是什么?如何将文本批评转换为强化学习的标量奖励?论文可能前置了结果,对使其在实践中工作所需的工程解释不足。
判决: 弱接收——这是一个扎实的贡献,具有明确的实用价值和良好的实验结果,但它是渐进式改进而非范式转变。
洞察(在渲染空间中评估)事后看来有些显而易见,执行虽然称职,但没有揭示关于奖励建模或视觉语言学习的深层新原理。
要点总结
在重要的输出空间中评估: 如果你关心视觉保真度,不要评估代码或嵌入——渲染输出并进行视觉比较。
这个原则可以迁移到任何代理指标与真实目标不对齐的领域。
在音频生成中,评估波形而非频谱图。
在机器人学中,评估物理结果而非轨迹规划。
生成式模型作为奖励函数: 不用标量奖励,而是用语言模型生成结构化批评。
这提供更丰富的训练信号并实现可解释的调试。
你可以将此应用于代码审查(生成具体改进建议)、内容审核(解释为何内容违反政策)或质量控制(描述制造缺陷)。
细粒度反馈实现针对性改进: 将评估分解为组件(数据准确性、配色方案、布局、标签)让模型学习哪些方面需要改进。
这对于复杂任务特别有价值,单一聚合分数会掩盖实际问题所在。
警惕奖励黑客攻击: 每当你优化代理指标时,检查模型是否能钻空子。
嵌入相似度的例子很有启发性——模型学会最大化重叠度而不匹配视觉外观。
始终验证你的奖励函数实际测量的是你关心的东西。