Paper: 2608.11201 Authors: Bowei Liu, Zheng Lu, Yuhan Bian, Xinchen Zhang, Xingming Shui, Yuesheng Huang, Xuhuan Li, Zihao Liu, Yifan Yang, Jun Zhou Categories: cs.CV
The Gap
The current state of AI-generated video detection with MLLMs is basically two recipes. Recipe one: supervised fine-tuning on real/fake labels, sometimes with GPT-written explanations attached. Recipe two: R1-style RL where the reward is “did you output the correct label.” Both give the model exactly one bit of supervision per video, and one bit is not enough to specify what to look at. The model is free to satisfy that bit by latching onto whatever correlates with “fake” in the training set — a particular generator’s color grading, a resolution artifact, a prompt-distribution smell. That works beautifully in-distribution and collapses the moment a new video generator ships, which in this field is roughly monthly.
The obvious fix is to demand evidence, not just verdicts. But the obvious evidence — a textual rationale like “the fingers warp around frame 40” — has a nasty property: to reward it you need a judge, and the judge is another model. Now your training signal inherits that model’s hallucinations and its semantic priors about what fakes “look like.” You have made supervision richer and less trustworthy at the same time.
The paper’s move is to find evidence that is checkable by construction. If you build your fake videos by cutting out a time interval and regenerating it, you know the tampered interval exactly — no judge required. Temporal grounding becomes a verifiable reward in the RLVR sense, like a unit test rather than a peer review.
PROBLEM: MLLM detectors output "fake" but cannot say where
   |
   v
DIAGNOSIS: label-only supervision (SFT or label-level RL)
   is one bit per video -- model satisfies it with
   generator fingerprints -- breaks on unseen generators
   |
   v
FIRST INSTINCT: reward textual rationales too
   |
   +--> blocked: rationale needs an external judge model
   |             hallucination + semantic bias leak into reward
   |
   v
INSIGHT: choose evidence that is verifiable by construction
   tampered time span is KNOWN if you built the fake yourself
   |
   v
METHOD: (a) pipeline: real video -- swap a segment via
             boundary-frame-conditioned generation
             ==> paired real / fake with exact span label
        (b) Evidence-Guided Reward Redistribution inside RL
   |
   v
EVIDENCE: better generalization to unseen generators
          plus usable temporal localization for free
   |
   v
CLAIM: for forensics RL, verifiable evidence beats verbal evidence
The Increment
One sentence: Before, an RL-trained video forensics model was rewarded for guessing right; after, it is rewarded for guessing right *and, among the responses that guessed right, for pointing at the actual tampered seconds — with a reward that no external judge model had to invent.
Core Mechanism
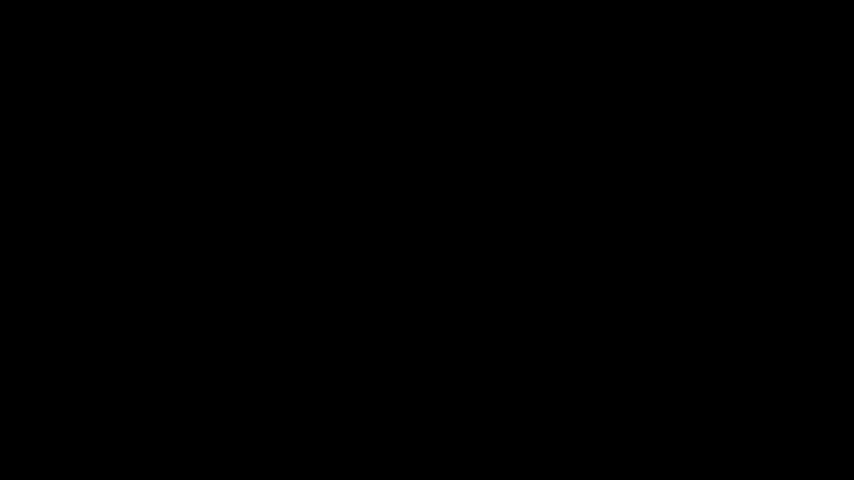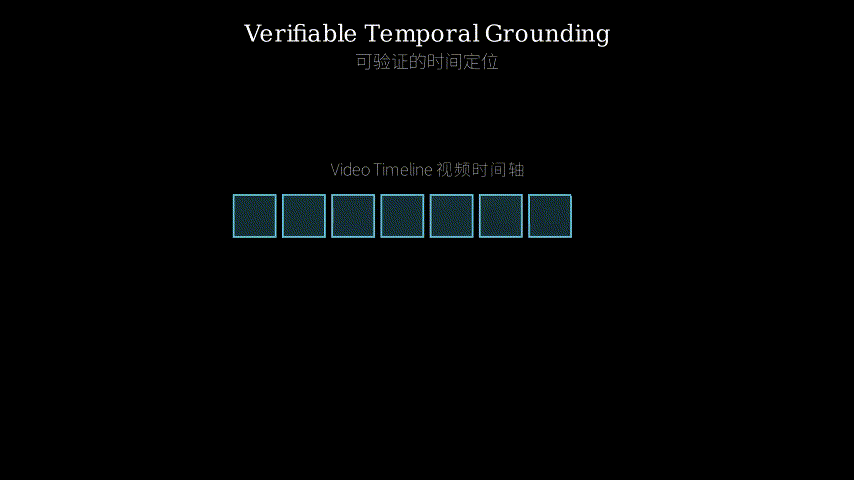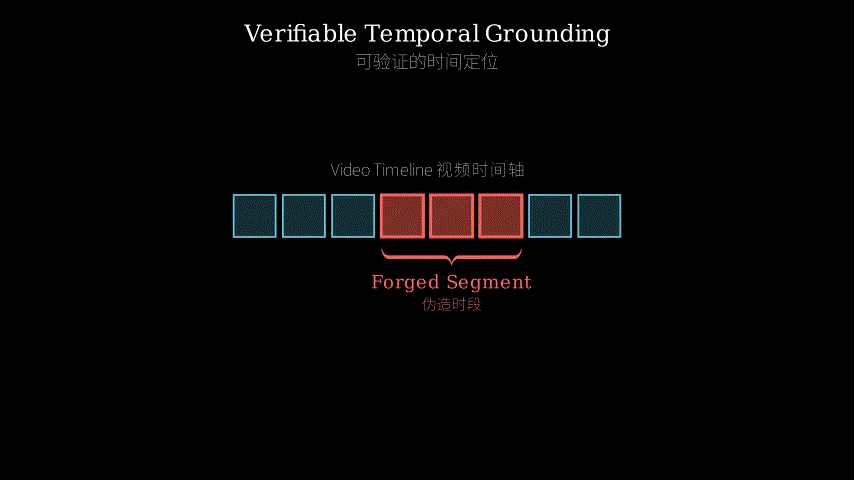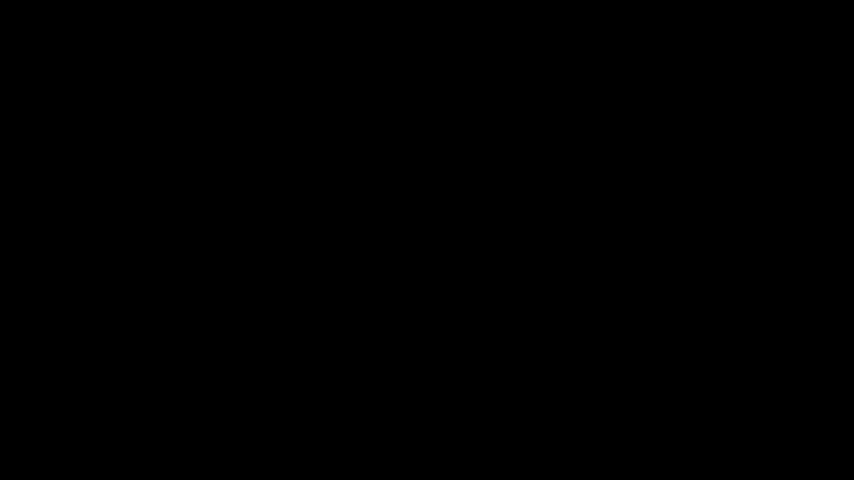
Two pieces, and they are co-dependent. The first is a data factory. Take a real video, pick an interval, throw away the frames inside it, keep the two boundary frames, and hand those to a boundary-frame-conditioned generator (an interpolation-style video model) to hallucinate a bridge between them. The output is a video that is real everywhere except a known span, paired with its own original. That pairing matters: the model cannot win by comparing “this video’s overall vibe is synthetic,” because the same video with the same subject, lighting, and camera exists in the real half of the pair. The only distinguishing information is local and temporal. And crucially, the answer key (label, [t1, t2]) is a byproduct of construction, not an annotation.
The second piece is how that evidence enters the objective. The naive move — add an IoU term to the reward — is dangerous: a response that says “real” but happens to emit a plausible-looking span could out-score a response that correctly says “fake” with a sloppy span, and the label signal gets diluted. Evidence-Guided Reward Redistribution avoids this by working within correctness strata. Sample a group of rollouts for the same video (GRPO-style). Partition them by label correctness. The total reward mass assigned to the label-correct group stays fixed; inside that group, the mass is redistributed according to temporal IoU with the answer key. So evidence quality never changes whether being right beats being wrong — it only decides who among the right answers gets the biggest advantage. It is credit assignment layered under an unchanged label ordering.
The effect on gradients is what you want: the policy still learns the coarse decision boundary from the label term, but the fine-grained pressure inside the winning group pushes it toward representations that can actually localize the artifact. Localization is not the deliverable; it is the mechanism that forces the features to be local.
DATA FACTORY
  [ real video V ]
      |
      +--> choose span [t1 t2]
      |        |
      |        +--> keep frames at t1 and t2 -- drop the middle
      |                 |
      |                 v
      |        boundary-frame-conditioned video generator
      |                 |
      |                 v
      +--> [ fake video V' ] :: answer key = (fake  span=[t1 t2])
      +--> [ real video V  ] :: answer key = (real  span=none)

TRAINING LOOP
  video + prompt
      |
      v
  MLLM policy -- sample G responses
      |
      v
  response_i = <label_i> + <span_i>
      |
      v
  +--------------------------------------+
  | stratify by label correctness        |
  +--------------------------------------+
      |                          |
  label WRONG                label RIGHT
      |                          |
  low reward                 fixed reward mass R
  (no evidence credit)           |
                                 v
                    rank by IoU(span_i  key)
                                 |
                    r_i = g(IoU_i) rescaled so
                    sum_i r_i == R
                                 |
                                 v
                  group-relative advantage -- policy update
The metaphor: this is a physics teacher grading with a two-stage rubric.
The teacher writes the exam herself by taking a correct derivation and deliberately corrupting three lines of it — that is the data factory. Because she made the corruption, she knows exactly which lines are wrong; she does not have to ask a colleague to guess, which is the textual-rationale approach and is exactly how grading disputes start.
Each student hands in an answer sheet with a box for the final answer (“this derivation is flawed”) and a margin where they circle the offending lines. Stage one: the teacher sorts sheets into two piles by the answer box only. Wrong box, no credit, and it does not matter how beautifully you circled things. Stage two: the correct-box pile has a fixed number of points to hand out — say 100 total — and she distributes those 100 among that pile by how precisely each student circled the right lines. The class rank between “right answer” and “wrong answer” can never invert. But within the right-answer pile, the student who circled exactly lines 7–9 walks away with more than the student who circled the whole page and got lucky.
The pedagogical consequence is the point: students stop pattern-matching on “derivations that look sketchy” and start reading line by line, because that is the only way to win the second stage. The detector does the same — it stops sniffing generator style and starts watching frames.
Key Concepts
-
Meta-detection: normally a detector outputs one thing: a verdict. Meta-detection means the model must output the verdict *plus the artifact that justifies it, and both are optimized jointly. Think of the difference between a smoke detector that beeps and a fire marshal who writes “ignition at the junction box, 02
.” The beep is unfalsifiable; the report can be checked, and a system whose reports get checked has to actually understand the fire. The word “meta” here is doing modest work — it means “detection plus a claim about the detection” — but the operational content is real: two outputs, two graded quantities, one policy. -
Verifiable evidence vs. verbal evidence: a reward is verifiable if a short program can compute it.
IoU([t1,t2], [t1_hat,t2_hat])is twelve lines of Python and is never wrong. “Does this sentence correctly describe the artifact?” requires a language model and is sometimes wrong in ways that correlate with the very biases you are trying to remove — if your judge believes fakes have shimmery hands, the reward teaches your detector to see shimmery hands whether or not they are there. The paper’s whole design hinges on trading expressive-but-unverifiable evidence for narrow-but-airtight evidence. The cost is real: temporal spans cannot describe *what is wrong, only when. The authors bet that “when” is enough to force the right features. -
Reward redistribution as stratified credit assignment: in group-relative RL you sample several answers and score them against each other, so what matters is *ordering within the group, not absolute reward values. That gives you a free lever: you can shuffle reward inside any subset of the group without touching the relationship between subsets. Redistributing among label-correct responses leaves the “correct beats incorrect” gap untouched while creating a whole new gradient among the correct ones. Concretely, if four rollouts are correct and share 100 points, giving them 40/30/20/10 by IoU rather than 25 each means the best-localizing rollout is now the one the policy chases — but “correct” still dominates “incorrect” by exactly as much as before. It is a way to add a second objective that provably cannot hijack the first.
Framework Shift
Before (mainstream approach):          After (this paper):

  video                                  video
    |                                      |
    v                                      v
  MLLM                                   MLLM
    |                                      |
    v                                      v
  "fake"                                 "fake" + [t1 t2]
    |                                      |          |
    v                                      v          v
  reward = 1 if label right              tier 1: label correct?
                                           |          |
  evidence: unconstrained                  |          v
  or judged by another LLM                 |     IoU vs answer key
    |                                      |     (checkable code
    v                                      |      no judge model)
  gradient says only                       v          |
  "output this token"                 fixed mass R    |
                                      split inside <--+
  model may satisfy it with           the correct pile
  generator fingerprints                   |
                                           v
                                  gradient says
                                  "be right AND be local"
From label-level RL to evidence-stratified RL, the core shift is that the supervision target moved from the answer to the answer plus a machine-checkable pointer, and the reward was restructured so the pointer sharpens the answer instead of competing with it.
Expert Assessment
Problem choice: Real gap, and well-timed. Generalization to unseen generators is *the open problem in synthetic media forensics — every benchmark shows in-domain AUC near ceiling and cross-generator AUC falling off a cliff — and the field has been circling “make the model justify itself” for two years without solving the reward-reliability problem. Choosing temporal grounding because it is cheap to verify is the kind of constraint-driven design choice that separates a real contribution from a prompt-engineering paper. That said, the “first to introduce meta-detection” claim is framing, not fact: image forgery localization with grounded MLLMs (FakeShield-style work) and R1-style detectors with localization rewards already occupy adjacent ground. The genuinely new bit is the temporal axis plus the redistribution scheme, not the idea that evidence should be graded.
Method maturity: Clever, and the cleverness is in noticing that group-relative RL gives you a free stratification lever. EGRR is a small, principled modification with a clear invariant (label ordering preserved), which is much better engineering than the usual “add a weighted term and tune lambda.” My worry is upstream, in the data factory. Every training fake is built by boundary-frame-conditioned interpolation, which is a *specific corruption mode with its own signature — temporal-boundary discontinuities and interpolation smoothness. A model trained to localize that will get very good at finding interpolation seams. Fully synthetic videos (text-to-video, no real frames at all) have no tampered span, so the evidence signal is structurally undefined for the most important threat class, and the paper’s framing does not resolve how those are handled at training time. There is also a simpler baseline the paper needs to kill convincingly: multi-task SFT on the same paired data with a span-prediction head. If the constructed data is doing most of the work, EGRR is decoration.
Experimental integrity: I can only judge the claims as stated, and “extensive experiments demonstrate robust and generalizable detection” is exactly the sentence that hides the interesting details. The tests I would demand: (1) cross-generator held-out evaluation where the *data-construction generator never appears at test time — otherwise the win is partly leakage; (2) evaluation on fully-generated videos, not just segment-swapped ones, since that is the realistic misinformation case; (3) an ablation isolating EGRR from the paired-data pipeline; (4) the localization numbers reported honestly, because if IoU is low but detection improved, the story becomes “the auxiliary task regularizes” rather than “the model learned to localize,” which is a different and less exciting paper. The paired-real-fake design is a genuine strength for fairness — it removes content confounds that plague most deepfake benchmarks.
Writing quality: The abstract is unusually well-argued; the logical chain from “labels are too coarse” to “rationales need a judge” to “spans are verifiable” is the cleanest motivation I have read in this subarea, and the authors clearly know why they made each choice. The corner-cutting is in vagueness at the boundaries: no acknowledgment that their construction covers only partial manipulation, and the reward-redistribution function is described qualitatively (“according to evidence quality”) where the exact shape almost certainly matters. The section I would rewrite is the generalization analysis — the paper’s entire claim is about unseen generators, so an honest failure-mode section showing where localization breaks would raise this from a solid systems paper to one people cite for its insight.
Verdict: weak accept — a well-motivated, cleanly designed use of verifiable rewards in a domain that badly needs them, held back by a training-data distribution that may quietly define the very artifacts the model learns to find.
Takeaways
- Choose your evidence for verifiability, not expressiveness. If you want an auxiliary supervision signal in an RLVR setup, ask “can I compute this reward with code I trust?” before asking “is this signal informative?” A narrow airtight signal usually beats a rich judged one, because a judged reward imports the judge’s biases directly into your policy. This transfers to any domain where people are currently using LLM-as-judge for intermediate reasoning quality.
- Manufacture the ground truth instead of annotating it. The trick of building the corruption so the answer key falls out for free is broadly reusable: synthetic bug injection for code repair with known fault lines, synthetic document tampering for provenance, injected contradictions for fact-checking with known contradiction spans. Whenever you would otherwise pay for localization labels, ask if you can construct the data backwards.
- Group-relative RL gives you free stratified levers. Because GRPO-family methods only care about within-group ordering, you can add a secondary objective *inside a correctness stratum and mathematically guarantee it cannot invert the primary one. This is a general recipe for “I want to reward style/format/rigor without risking correctness” — much safer than a weighted reward sum, and it needs no lambda tuning.
- Paired real/fake data as a confound killer. Generating the fake from the same source clip removes content, lighting, and subject confounds. Any detection benchmark you build should consider this; it is cheap and it makes your numbers mean something.
- Watch out for the mirror trap (the caution to steal): if you construct training corruptions with generator G, your detector may learn G’s seams rather than the general concept of synthesis. Always hold out the construction tool itself.
论文: 2608.11201 作者: Bowei Liu, Zheng Lu, Yuhan Bian, Xinchen Zhang, Xingming Shui, Yuesheng Huang, Xuhuan Li, Zihao Liu, Yifan Yang, Jun Zhou 分类: cs.CV
缺口
现在用多模态大模型做 AI 生成视频检测,基本只有两条路。
一条是拿真假标签做监督微调,有时再挂上 GPT 写的解释文本。
另一条是 R1 式强化学习,奖励就是「标签对不对」。
两条路的共同点:每条视频只给模型一个比特的监督。
一个比特远远不足以指定「该看哪里」。
模型完全可以靠训练集里任何与「假」相关的东西来满足这一个比特——某个生成器特有的色调、分辨率痕迹、prompt 分布的气味。
结果就是同分布内 AUC 顶天,换一个新发布的视频生成模型立刻崩,而这个领域大约每个月就有新模型发布。
显然的解法是:要求模型给证据,不只给判决。
但最显然的那种证据——「第 40 帧附近手指扭曲」这类文字理由——有个很讨厌的性质:要给它打分,你需要一个裁判,而裁判是另一个模型。
于是训练信号继承了那个模型的幻觉,以及它对「假视频长什么样」的语义先验。
你把监督变丰富了,同时也变得不可信了。
本文的动作是去找一种构造上就可验证的证据。
如果你造假的方式是把一段时间区间剪掉再重新生成,那么被篡改的区间你本来就知道得一清二楚——不需要裁判。
时间定位于是变成了 RLVR 意义上的可验证奖励:像单元测试,而不像同行评审。
PROBLEM: MLLM 能说 "fake" 但说不出 where
   |
   v
DIAGNOSIS: 只有标签监督 (SFT / label-level RL)
   = 每条视频一个比特 -- 模型用生成器指纹就能满足
   -- 换生成器即崩
   |
   v
FIRST INSTINCT: 那就顺便奖励文字理由
   |
   +--> 此路不通: 文字理由需要外部裁判模型
   |             幻觉 + 语义偏见直接漏进奖励
   |
   v
INSIGHT: 选一种「构造上可验证」的证据
   自己造的假 -- 篡改时段本来就是已知的
   |
   v
METHOD: (a) 数据流水线: 真视频 -- 用边界帧条件生成
             替换某个时段 ==> 成对真/假 + 精确时段答案
        (b) RL 内部的 Evidence-Guided Reward Redistribution
   |
   v
EVIDENCE: 对未见生成器的泛化提升
          外加白送的时间定位能力
   |
   v
CLAIM: 做鉴伪 RL -- 可验证证据 > 可言说证据
增量
一句话:以前,强化学习训出的视频鉴伪模型只因为「猜对了」而拿奖励;现在,它要猜对,并且在所有猜对的回答里,还要因为「指出了真正被篡改的那几秒」而拿到更多奖励——而这份奖励完全不需要外部裁判模型来编。
核心机制
两个部件,而且互相依赖。
第一个是数据工厂。
拿一条真视频,挑一段区间,把区间内的帧全扔掉,只留下两端的边界帧,交给一个边界帧条件的视频生成模型(插帧式的视频模型)去幻想中间的桥段。
产出是一条「除了某个已知时段外全是真的」视频,并且与它的原版成对存在。
这个「成对」很关键:模型没法靠「这条视频整体气质很合成」取胜,因为同样的人物、光照、机位在这一对的真侧也存在。
唯一可区分的信息是局部的、时间上的。
而且更关键的是,答案 (label, [t1, t2]) 是构造的副产品,不是标注出来的。
第二个部件是这份证据如何进入优化目标。
最朴素的做法——往奖励里加一项 IoU——是危险的:一个说「真」但恰好吐出个像样区间的回答,可能压过一个正确说「假」但区间画得糙的回答,标签信号就被稀释了。
Evidence-Guided Reward Redistribution 的办法是只在「正确性分层」内部动手。
对同一条视频采一组 rollout(GRPO 式),按标签对错分层。
分给「标签正确」这一层的奖励总量固定不变;在这一层内部,按与答案的时间 IoU 重新分配这份总量。
于是证据质量永远不会改变「对 vs 错」的高低关系——它只决定在对的那批里谁的优势最大。
这是在「标签排序不变」这个约束下,加了一层更细的信用分配。
对梯度的效果正是你想要的:策略仍然从标签项学到粗粒度决策边界,但获胜组内部的细粒度压力会把它推向真正能定位痕迹的表征。
定位本身不是交付物,它是逼迫特征变成局部特征的手段。
DATA FACTORY
  [ real video V ]
      |
      +--> 选定时段 [t1 t2]
      |        |
      |        +--> 保留 t1 与 t2 处的帧 -- 丢掉中间
      |                 |
      |                 v
      |        boundary-frame-conditioned video generator
      |                 |
      |                 v
      +--> [ fake video V' ] :: 答案 = (fake  span=[t1 t2])
      +--> [ real video V  ] :: 答案 = (real  span=none)

TRAINING LOOP
  video + prompt
      |
      v
  MLLM policy -- 采样 G 个回答
      |
      v
  response_i = <label_i> + <span_i>
      |
      v
  +--------------------------------------+
  | 按 label 是否正确分层                |
  +--------------------------------------+
      |                          |
  label 错                    label 对
      |                          |
  低奖励                     固定奖励总量 R
  (不给证据分)                   |
                                 v
                    按 IoU(span_i  答案) 排序
                                 |
                    r_i = g(IoU_i) 归一化使
                    sum_i r_i == R
                                 |
                                 v
                  group-relative advantage -- 更新策略
核喻:这就是一位物理老师用「两段式评分表」批卷。
老师自己出卷:拿一份正确推导,故意改错其中三行——这就是数据工厂。
因为错是她亲手改的,她精确知道哪三行有问题;她不需要请同事来猜,而「请同事来猜」就是文字理由那条路,也正是评分争议的起点。
每个学生交上来的答卷有两部分:一个最终答案框(「这份推导有问题」),以及页边空白处圈出的可疑行号。
第一段评分:老师只看答案框,把卷子分成两堆。
答案框错了,零分,圈得多漂亮都不算。
第二段评分:答案框正确那一堆有固定的分数池——比如总共 100 分——她按「圈得多准」把这 100 分分配下去。
「答对」和「答错」之间的排序永远不会翻转。
但在答对的那一堆里,精确圈出第 7 到 9 行的学生,拿的分数就比把整页都圈上、纯靠蒙的学生多。
教学效果才是重点:学生不再靠「这份推导看起来就很可疑」做模式匹配,而开始逐行读,因为那是赢下第二段的唯一办法。
检测器也一样——它不再嗅生成器风格,而开始真的看帧。
关键概念
-
元检测(meta-detection):普通检测器只输出一个东西:判决。
元检测要求模型输出判决加上支撑它的痕迹,并且两者联合优化。
想想烟感器和火灾调查员的差别:烟感器只会叫,调查员会写「起火点在配电箱,02:14」。
叫声无法被证伪;报告可以被核查,而一个报告会被核查的系统,必须真的理解这场火。
这里的「元」这个字承担的工作其实不多——就是「检测 + 关于检测的一个可核查断言」——但操作层面的内容是实的:两个输出、两个被评分的量、一个策略。
-
可验证证据 vs 可言说证据:一个奖励是「可验证」的,当且仅当一段短程序能算出它。
IoU([t1,t2], [t1_hat,t2_hat])是十二行 Python,永远不会算错。而「这句话对痕迹的描述正确吗」需要一个语言模型,而且它出错的方式往往正好与你想消除的偏见相关——如果裁判相信假视频的手会发虚,这份奖励就会教你的检测器去看手发虚,不管手到底虚不虚。
本文整个设计都押在这个取舍上:用「窄但铁」的证据换掉「丰富但不可验证」的证据。
代价是真实存在的:时间区间只能说「什么时候」不对,说不出「什么」不对。
作者赌的是,「什么时候」已经足够逼出正确的特征。
-
奖励重分配 = 分层信用分配:在 group-relative RL 里,你采若干个回答互相比较,真正起作用的是组内排序,不是奖励的绝对值。
这给了你一个免费的杠杆:你可以在组内任一子集里随意搬动奖励,而不触碰子集之间的关系。
在「标签正确」子集内重分配,就既保住了「对压倒错」的那个落差,又在正确回答之间造出了一条全新的梯度。
具体说:四个 rollout 都答对、共享 100 分,按 IoU 分成 40/30/20/10 而不是各 25,那么定位最准的那个就成了策略追逐的目标——但「对」相对「错」的优势,还是和原来一模一样。
这是一种「可证明无法劫持主目标」的加第二目标的方式。
框架转变
之前(主流方法):                    之后(本文方法):

  video                                  video
    |                                      |
    v                                      v
  MLLM                                   MLLM
    |                                      |
    v                                      v
  "fake"                                 "fake" + [t1 t2]
    |                                      |          |
    v                                      v          v
  reward = label 对就给 1               第一层: label 对吗
                                           |          |
  证据: 不受约束                           |          v
  或由另一个 LLM 评判                      |     与答案算 IoU
    |                                      |     (代码可算
    v                                      |      无需裁判模型)
  梯度只说                                 v          |
  "输出这个 token"                    固定总量 R      |
                                      在正确层内 <----+
  模型可以靠生成器指纹                重新分配
  来满足它                                 |
                                           v
                                  梯度说的是
                                  "既要对 也要局部"
一句话:从 label-level RL 到 evidence-stratified RL,核心转变是监督目标从「答案」变成「答案 + 一个机器可核查的指针」,并且把奖励重构成让指针去磨利答案、而不是和答案抢梯度。
专家评审
选题眼光:真缺口,而且时机对。
对未见生成器的泛化是合成媒体鉴伪的头号未解问题——所有 benchmark 都是同域 AUC 顶天、跨生成器 AUC 断崖——而这个领域围着「让模型自证」转了两年,始终没解决「奖励是否可信」这一环。
因为「便宜且可验证」而选择时间定位,是那种由约束驱动的设计决策,这才是真贡献与 prompt 工程论文的分界线。
不过「首次引入元检测」是一种叙事框架,不是事实:图像篡改定位 + grounded MLLM(FakeShield 那一路)以及带定位奖励的 R1 式检测器,已经占住了紧邻的地盘。
真正新的是「时间轴」加「重分配机制」,不是「证据该被打分」这个想法本身。
方法成熟度:巧劲,而且巧在看出 group-relative RL 白送了一个分层杠杆。
EGRR 是个小而有原则的改动,带一个清晰的不变量(标签排序保持不变),这比常见的「加个加权项然后调 lambda」工程质量高得多。
我担心的在上游,在数据工厂。
所有训练用的假视频都由边界帧条件插帧生成,这是一种特定的篡改模式,自带签名——时间边界不连续、插帧过度平滑。
被训练去定位它的模型,会变得极擅长找插帧接缝。
而完全合成的视频(纯文生视频,一帧真的都没有)根本不存在「被篡改时段」,证据信号在结构上就是未定义的——而这恰恰是最重要的威胁类别,论文的叙述没有交代训练时怎么处理这类样本。
另外有一个更简单的基线必须被干净地击败:用同样的成对数据做多任务 SFT,加一个区间预测头。
如果构造出的数据本身贡献了大部分收益,EGRR 就只是装饰。
实验诚意:我只能就其陈述来判断,而「大量实验证明鲁棒且可泛化」正是那种把有意思的细节全藏起来的句子。
我会要求看到的:(1) 跨生成器留出评测,且用于造数据的那个生成器绝不出现在测试端——否则收益里有一部分是泄漏;(2) 在完全生成视频上的评测,而非只在换段视频上,因为前者才是真实的误信息场景;(3) 把 EGRR 和成对数据流水线拆开的消融;(4) 诚实报告定位指标,因为如果 IoU 其实很低但检测变好了,故事就变成「辅助任务起了正则化作用」而不是「模型学会了定位」——那是另一篇论文,也没那么激动人心。
成对真假的设计本身是公平性上的实打实优势:它消掉了折磨大多数 deepfake benchmark 的内容混淆因子。
写作功力:摘要论证得异常清楚;从「标签太粗」到「文字理由需要裁判」到「时间区间可验证」这条链,是我在这个子方向读到最干净的动机叙述,作者显然知道自己每一步为什么这么选。
偷懒的地方在边界处的含混:没有承认他们的构造只覆盖「局部篡改」,而奖励重分配函数只有定性描述(「按证据质量」),可具体形状几乎必然重要。
我会重写的是泛化分析那一节——整篇论文的主张就是关于未见生成器的,所以一段诚实的失效模式分析(定位在哪里崩)能把它从一篇扎实的系统论文,提到一篇因洞见而被引用的论文。
判决:弱接收 —— 在一个急需可验证奖励的领域里,动机充分、设计干净地用上了它;短板是训练数据分布可能悄悄定义了模型学会去找的那类痕迹。
要点总结
- 选证据要按「可验证性」选,不是按「表达力」选。 在 RLVR 里加辅助监督信号时,先问「这份奖励我能用自己信得过的代码算出来吗」,再问「这个信号信息量大吗」。窄而铁的信号通常胜过丰富而被评判的信号,因为被评判的奖励会把裁判的偏见直接搬进你的策略。这一条可迁移到任何目前在用 LLM-as-judge 打中间推理质量分的场景。
- 不要标注真值,去制造真值。 「造破坏的时候答案自动落地」这个技巧复用性极广:给代码修复注入已知故障行的合成 bug、为溯源做已知篡改区域的合成文档、为事实核查注入已知矛盾片段。凡是你打算花钱买定位标注的地方,先问一句能不能倒着构造数据。
- Group-relative RL 白送你分层杠杆。 因为 GRPO 一族只在乎组内排序,你可以在某个「正确性层」内部加第二目标,并在数学上保证它无法翻转主目标。这是「我想奖励风格/格式/严谨性但不敢拿正确性冒险」的通用配方——比加权求和安全得多,而且不需要调 lambda。
- 成对真假数据是混淆因子杀手。 从同一段源视频生成假样本,消掉了内容、光照、人物这些混淆项。你自己建 benchmark 时都该考虑这一点;成本很低,却能让数字真的有意义。
- 警惕「照镜子陷阱」(这条是拿来自用的警告):如果你用生成器 G 构造训练破坏,你的检测器可能学的是 G 的接缝,而不是「合成」这个一般概念。永远把构造工具本身留出来做测试。