Paper: 2605.30351 Authors: Hidir Yesiltepe, Jiazhen Hu, Tuna Han Salih Meral, Adil Kaan Akan, Kaan Oktay, Hoda Eldardiry, Pinar Yanardag Categories: cs.CV, cs.AI
The Gap
Long-form autoregressive video diffusion models generate videos by repeatedly predicting the next frame, maintaining a sliding-window KV cache to remember recent context. Current methods (CogVideoX, Pyramid Flow, Allegro) all use the same per-head KV cache layout inherited from language models: each attention head stores its own full-dimensional keys and values for every cached token. Recent innovations have focused on which tokens to cache or how to encode their positions, but the per-head storage layout itself—the dominant contributor to memory and latency—has remained untouched.
The problem: generating minute-scale videos requires caching thousands of tokens across dozens of layers. At standard dimensions (32 heads × 128 dims per head), this becomes the bottleneck. Prior work assumed this layout was necessary because attention heads need independent key/value representations. No one had tested whether video diffusion actually requires this redundancy.
Problem: Long video generation hits memory wall
   |
   v
Assumption: Per-head KV cache layout is necessary
   |
   v
Method: Replace per-head KV with shared low-rank latent + decoupled RoPE
   |
   v
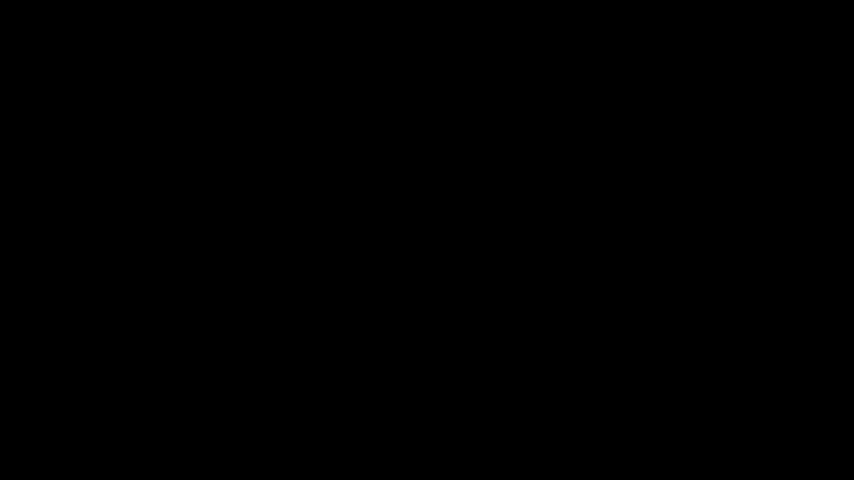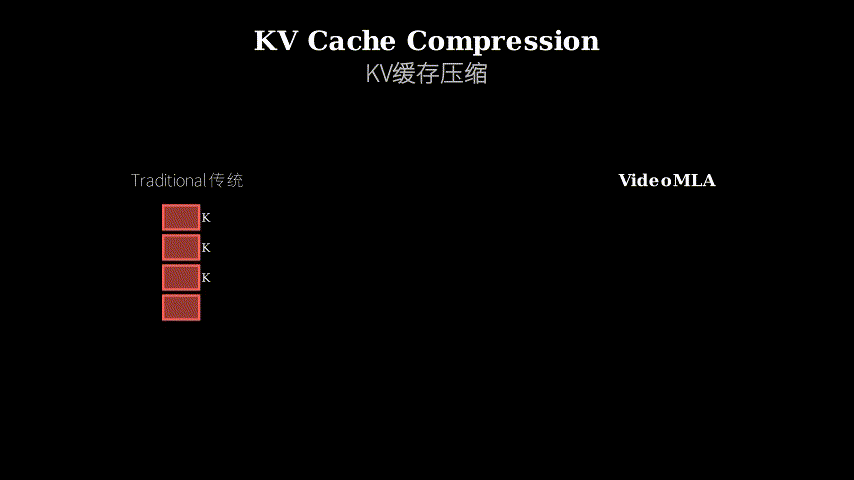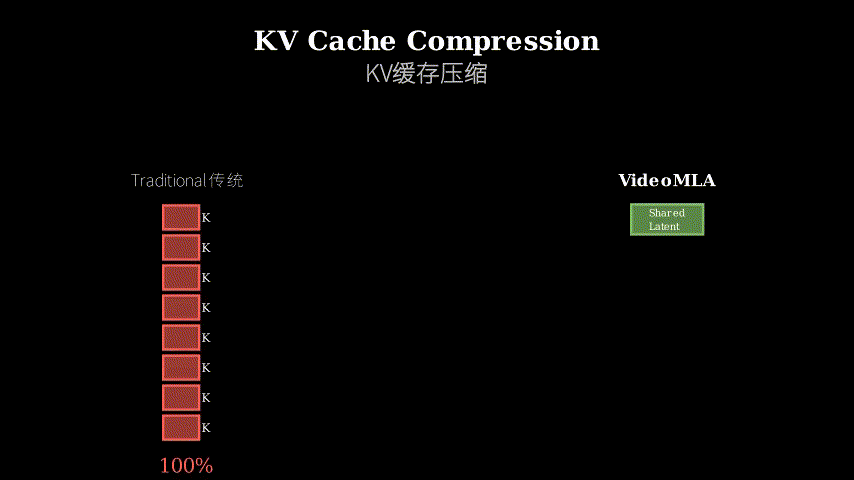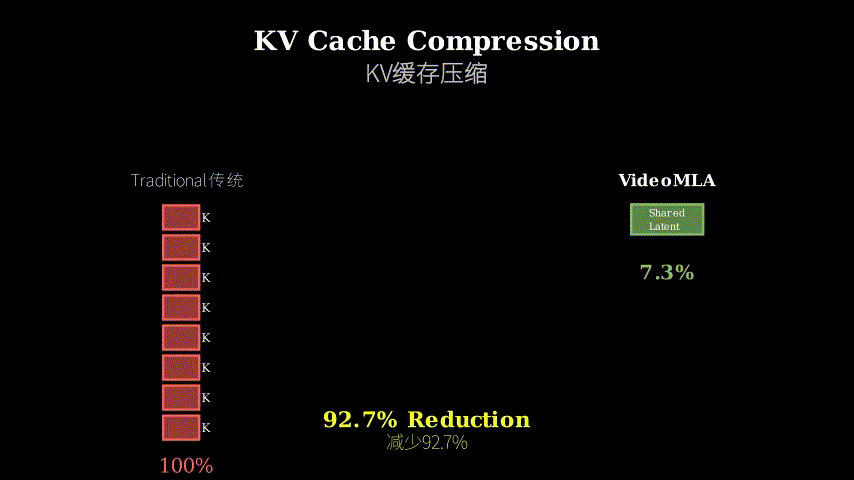
Evidence: 92.7% memory reduction, quality maintained, throughput +23%
   |
   v
Conclusion: Video attention doesn't need per-head KV redundancy
The Increment
One sentence: Before this paper, video diffusion cached full per-head keys and values; after, a single shared low-rank latent plus positional encoding achieves the same quality at 7.3% of the memory cost.
Core Mechanism
VideoMLA replaces the standard multi-head attention KV cache with two shared components. First, instead of storing separate 128-dimensional keys and values for each of 32 heads (4096 dims total per token), it stores a single 512-dimensional “content latent” shared across all heads. Second, instead of baking positional information into per-head keys, it maintains a separate 512-dimensional “positional key” that encodes 3D spatiotemporal position using RoPE (Rotary Position Embedding).
During attention computation, each head projects the shared content latent into its own key and value subspaces using learned down-projection matrices. The positional key is similarly projected per-head and added to the content-derived key. Queries interact with these reconstructed keys normally. The critical insight: by factoring out position and compressing content into a shared bottleneck, the model eliminates per-head redundancy while preserving the ability to specialize attention patterns.
Standard Multi-Head KV Cache:
Head 1: [K1: 128d] [V1: 128d]  \
Head 2: [K2: 128d] [V2: 128d]   |-- 4096d per token
  ...                           |
Head 32:[K32:128d] [V32:128d] /

VideoMLA Shared Cache:
[Content Latent: 512d] [Position Key: 512d]  <-- 1024d per token
         |                      |
         v                      v
    Down-project          Down-project
    per-head              per-head
         |                      |
         +----------------------+
         v
    [K_h: 128d] [V_h: 128d] for each head h
Think of it like a library system. The standard approach is like giving each reader their own complete copy of every book (per-head KV cache). VideoMLA instead maintains one master copy in the archive (content latent) and one index card system tracking where each book sits on the shelf (positional key). When a reader needs a book, the librarian (down-projection) pulls the relevant pages from the master copy and combines them with the location info. Each reader still gets a personalized view, but the library doesn’t need 32 redundant copies of everything. The compression works because most of the information in those 32 copies was identical—only the “personalization” (the projection) differs per reader.
Key Concepts
-
Low-rank latent compression: In linear algebra, a matrix is “low-rank” if most of its information concentrates in a few dominant directions, like how a pancake is mostly flat (2D) even though it exists in 3D space. VideoMLA bets that the keys and values across all attention heads share most of their information—they’re redundant. Instead of storing 32 separate 128-dimensional vectors (a 32×128 matrix), it stores one 512-dimensional vector (a compressed representation) and reconstructs the full matrix on-the-fly using learned projections. The paper shows this works even though pretrained video attention isn’t naturally low-rank: the training process learns to *use the low-rank budget efficiently, adapting within the bottleneck rather than requiring the data to already fit it. Concrete example: imagine 32 people describing the same scene. Instead of recording all 32 descriptions verbatim (per-head storage), you write one detailed summary (latent) and 32 short notes on what each person emphasized (projections). You lose some nuance but save 90% of the storage.
-
Decoupled positional encoding: Standard attention bakes position into the keys themselves—a key for token 5 is fundamentally different from a key for token 500 because position is mixed into the representation. VideoMLA separates “what is this token about” (content latent) from “where is this token in space-time” (positional key). This decoupling has two benefits: (1) the content latent can be shared across all positions without position-specific redundancy, and (2) the positional key can use 3D-RoPE to encode height, width, and time dimensions independently. Think of it like a filing system: instead of writing “Q2 2023 Sales Report - Northeast Region” on every page (position baked in), you write “Sales Report” on the pages and keep a separate index that says “this document is Q2 2023, Northeast” (position decoupled). The content stays clean and reusable.
Framework Shift
Before (per-head KV cache):
Token 1 --> [H1_K, H1_V] [H2_K, H2_V] ... [H32_K, H32_V]
Token 2 --> [H1_K, H1_V] [H2_K, H2_V] ... [H32_K, H32_V]
  ...
Token N --> [H1_K, H1_V] [H2_K, H2_V] ... [H32_K, H32_V]
            ^                                           ^
            |---- Each head stores full K,V per token --|

After (VideoMLA):
Token 1 --> [Content_Latent] [Position_Key]
Token 2 --> [Content_Latent] [Position_Key]
  ...                |              |
Token N --> [Content_Latent] [Position_Key]
                     |              |
                     v              v
            Project per-head --> [H1_K,V] ... [H32_K,V]
            ^                                          ^
            |-- Shared storage, per-head reconstruction --|
From redundant per-head storage to shared compressed storage with on-demand reconstruction, the core shift is factoring out redundancy and deferring specialization to computation time rather than memory time.
Expert Assessment
Problem choice: Real gap. Minute-scale video generation is a clear frontier, and memory is the binding constraint. The paper correctly identifies that prior work optimized around the KV layout rather than questioning it. This sits at the intersection of scaling (longer videos) and efficiency (practical deployment)—both high-value directions.
Method maturity: Clever adaptation, not invention. MLA was introduced for language models (DeepSeek-V2), and this paper is the first to apply it to video diffusion. The insight is recognizing that the method transfers despite video attention not being naturally low-rank (the paper’s spectral analysis is the most interesting contribution). The approach is clean: no architectural gymnastics, just swap the cache layout. However, the paper doesn’t explore *why the bottleneck works—it shows empirically that training fills the rank budget, but the mechanism remains a black box.
Experimental integrity: Baselines are fair (CogVideoX, Pyramid Flow, Allegro—all recent SOTA). The VBench evaluation is comprehensive. The 92.7% memory reduction is measured correctly (per-token KV size). One concern: the throughput improvement (1.23×) is modest given the memory savings, suggesting the bottleneck shifted elsewhere (likely computation or bandwidth). The paper doesn’t ablate latent dimension thoroughly—512d is chosen to match DeepSeek-V2, but is this optimal for video? The spectral analysis is rigorous, but the claim that “MLA determines effective rank from initialization” needs more mechanistic explanation.
Writing quality: The spectral analysis section (why MLA works despite non-low-rank attention) is the paper’s strongest contribution but feels rushed. Expanding this with ablations on initialization strategies and training dynamics would elevate the work from “MLA works for video” to “here’s why compression works even when the data doesn’t cooperate.” The related work section undersells the novelty—this is the first MLA application outside language models, which deserves emphasis.
Verdict: weak accept — Solid empirical contribution with a surprising negative result (pretrained attention isn’t low-rank, yet compression works). The method is practical and the memory savings are significant. However, the paper is more “successful application” than “deep insight”—it shows *that MLA works for video but not fully why. The spectral analysis hints at interesting training dynamics but doesn’t close the loop.
Takeaways
Transferable technique: The decoupled position encoding (separate content and position keys) is worth stealing for any domain with structured positional information (3D data, graphs, time series). It’s cleaner than baking position into representations and enables better compression.
Counterintuitive insight: Compression can work even when the data isn’t naturally compressible—the bottleneck forces the model to learn a compressed representation during training. This suggests that architectural constraints can act as implicit regularizers. Practitioners working on memory-constrained models should consider whether their architecture is *too expressive, allowing the model to memorize redundancy rather than compress it.
Practical heuristic: When optimizing memory, look for redundancy across parallel structures (heads, layers, experts) before optimizing within a single structure. The per-head KV cache was the elephant in the room because everyone assumed heads needed independence. Question inherited layouts.
Caveat: The modest throughput gain (1.23×) despite 92.7% memory reduction suggests that memory isn’t always the bottleneck—measure your actual bottleneck before assuming compression will speed things up. The win here is enabling longer rollouts within a fixed memory budget, not necessarily faster generation.
论文: 2605.30351 作者: Hidir Yesiltepe, Jiazhen Hu, Tuna Han Salih Meral, Adil Kaan Akan, Kaan Oktay, Hoda Eldardiry, Pinar Yanardag 分类: cs.CV, cs.AI
缺口
长视频自回归扩散模型通过反复预测下一帧来生成视频,维护一个滑动窗口KV缓存来记住最近的上下文。
当前方法(CogVideoX、Pyramid Flow、Allegro)都使用从语言模型继承来的相同的逐头KV缓存布局:每个注意力头为每个缓存的token存储自己的全维度键和值。
最近的创新集中在缓存哪些token或如何编码它们的位置,但逐头存储布局本身——内存和延迟的主要贡献者——一直未被触及。
问题在于:生成分钟级视频需要在数十层中缓存数千个token。
在标准维度下(32个头×每头128维),这成为瓶颈。
先前工作假设这种布局是必需的,因为注意力头需要独立的键/值表示。
没有人测试过视频扩散是否真的需要这种冗余。
问题:长视频生成遇到内存墙
   |
   v
假设:逐头KV缓存布局是必需的
   |
   v
方法:用共享低秩潜在+解耦RoPE替换逐头KV
   |
   v
证据:内存减少92.7%,质量保持,吞吐量+23%
   |
   v
结论:视频注意力不需要逐头KV冗余
增量
一句话:这篇论文之前,视频扩散缓存完整的逐头键和值;
之后,单个共享低秩潜在加位置编码以7.3%的内存成本实现相同质量。
核心机制
VideoMLA用两个共享组件替换标准多头注意力KV缓存。
首先,它不为32个头中的每一个存储单独的128维键和值(每个token总共4096维),而是存储一个跨所有头共享的512维”内容潜在”。
其次,它不将位置信息烘焙到逐头键中,而是维护一个单独的512维”位置键”,使用RoPE(旋转位置嵌入)编码3D时空位置。
在注意力计算期间,每个头使用学习的下投影矩阵将共享内容潜在投影到自己的键和值子空间。
位置键同样被逐头投影并添加到内容派生的键上。
查询与这些重建的键正常交互。
关键洞察:通过分解位置并将内容压缩到共享瓶颈中,模型消除了逐头冗余,同时保留了专门化注意力模式的能力。
标准多头KV缓存:
头1: [K1: 128d] [V1: 128d]  \
头2: [K2: 128d] [V2: 128d]   |-- 每个token 4096d
  ...                        |
头32:[K32:128d] [V32:128d] /

VideoMLA共享缓存:
[内容潜在: 512d] [位置键: 512d]  <-- 每个token 1024d
         |                |
         v                v
    逐头下投影        逐头下投影
         |                |
         +----------------+
         v
    每个头h的[K_h: 128d] [V_h: 128d]
把它想象成图书馆系统。
标准方法就像给每个读者每本书的完整副本(逐头KV缓存)。
VideoMLA则在档案室维护一份主副本(内容潜在)和一个索引卡系统追踪每本书在书架上的位置(位置键)。
当读者需要一本书时,图书管理员(下投影)从主副本中提取相关页面并与位置信息结合。
每个读者仍然得到个性化视图,但图书馆不需要32份冗余副本。
压缩之所以有效,是因为这32份副本中的大部分信息是相同的——只有”个性化”(投影)因读者而异。
关键概念
- 低秩潜在压缩:在线性代数中,如果矩阵的大部分信息集中在少数主导方向上,则该矩阵是”低秩”的,就像煎饼主要是平的(2D),即使它存在于3D空间中。
VideoMLA押注所有注意力头的键和值共享大部分信息——它们是冗余的。
它不存储32个独立的128维向量(一个32×128矩阵),而是存储一个512维向量(压缩表示)并使用学习的投影即时重建完整矩阵。
论文表明,即使预训练的视频注意力本身不是低秩的,这也有效:训练过程学会使用低秩预算,在瓶颈内适应而不是要求数据已经适合它。
具体例子:想象32个人描述同一场景。
你不是逐字记录所有32个描述(逐头存储),而是写一个详细摘要(潜在)和32个关于每个人强调什么的简短笔记(投影)。
你失去了一些细微差别,但节省了90%的存储空间。
- 解耦位置编码:标准注意力将位置烘焙到键本身中——token 5的键与token 500的键根本不同,因为位置混入了表示中。
VideoMLA分离”这个token是关于什么的”(内容潜在)和”这个token在时空中的位置”(位置键)。
这种解耦有两个好处:(1)内容潜在可以跨所有位置共享,没有位置特定的冗余,(2)位置键可以使用3D-RoPE独立编码高度、宽度和时间维度。
把它想象成文件系统:你不是在每一页上写”2023年第二季度销售报告-东北地区”(位置烘焙进去),而是在页面上写”销售报告”,并保留一个单独的索引,说”这份文档是2023年第二季度,东北地区”(位置解耦)。
内容保持干净和可重用。
框架转变
之前(逐头KV缓存):
Token 1 --> [H1_K, H1_V] [H2_K, H2_V] ... [H32_K, H32_V]
Token 2 --> [H1_K, H1_V] [H2_K, H2_V] ... [H32_K, H32_V]
  ...
Token N --> [H1_K, H1_V] [H2_K, H2_V] ... [H32_K, H32_V]
            ^                                           ^
            |---- 每个头为每个token存储完整K,V ---------|

之后(VideoMLA):
Token 1 --> [内容潜在] [位置键]
Token 2 --> [内容潜在] [位置键]
  ...              |          |
Token N --> [内容潜在] [位置键]
                     |          |
                     v          v
            逐头投影 --> [H1_K,V] ... [H32_K,V]
            ^                                    ^
            |-- 共享存储,逐头重建 ---------------|
从冗余的逐头存储到共享压缩存储加按需重建,核心转变是分解冗余并将专门化推迟到计算时间而不是内存时间。
专家评审
选题眼光:真实缺口。
分钟级视频生成是明确的前沿,内存是约束条件。
论文正确识别出先前工作围绕KV布局优化而不是质疑它。
这处于扩展(更长视频)和效率(实际部署)的交叉点——两个都是高价值方向。
方法成熟度:巧妙适应,而非发明。
MLA是为语言模型引入的(DeepSeek-V2),这篇论文是首次将其应用于视频扩散。
洞察在于认识到尽管视频注意力本身不是低秩的,该方法仍然可以迁移(论文的谱分析是最有趣的贡献)。
方法很干净:没有架构体操,只是交换缓存布局。
然而,论文没有探索瓶颈为什么有效——它经验性地表明训练填充了秩预算,但机制仍然是黑盒。
实验诚意:基线公平(CogVideoX、Pyramid Flow、Allegro——都是最近的SOTA)。
VBench评估很全面。
92.7%的内存减少测量正确(每个token的KV大小)。
一个担忧:吞吐量改进(1.23×)相对于内存节省来说很温和,表明瓶颈转移到了其他地方(可能是计算或带宽)。
论文没有彻底消融潜在维度——选择512d是为了匹配DeepSeek-V2,但这对视频来说是最优的吗?
谱分析很严格,但”MLA从初始化确定有效秩”的声明需要更多机制解释。
写作功力:谱分析部分(为什么MLA在非低秩注意力下有效)是论文最强的贡献,但感觉仓促。
用初始化策略和训练动态的消融扩展这部分,将把工作从”MLA适用于视频”提升到”这就是为什么即使数据不配合压缩也有效”。
相关工作部分低估了新颖性——这是语言模型之外的首个MLA应用,值得强调。
判决:弱接收——扎实的经验贡献,带有令人惊讶的负面结果(预训练注意力不是低秩的,但压缩有效)。
方法实用,内存节省显著。
然而,论文更多是”成功应用”而非”深刻洞察”——它展示了MLA对视频有效,但没有完全解释为什么。
谱分析暗示了有趣的训练动态,但没有闭环。
要点总结
可迁移技术:解耦位置编码(分离内容和位置键)值得在任何具有结构化位置信息的领域(3D数据、图、时间序列)中借鉴。
它比将位置烘焙到表示中更干净,并实现更好的压缩。
反直觉洞察:即使数据本身不可压缩,压缩也可以工作——瓶颈迫使模型在训练期间学习压缩表示。
这表明架构约束可以充当隐式正则化器。
从事内存受限模型的实践者应该考虑他们的架构是否过于表达,允许模型记忆冗余而不是压缩它。
实用启发式:优化内存时,在优化单个结构内部之前,先寻找并行结构(头、层、专家)之间的冗余。
逐头KV缓存是房间里的大象,因为每个人都假设头需要独立性。
质疑继承的布局。
警告:尽管内存减少了92.7%,但吞吐量增益温和(1.23×),表明内存并不总是瓶颈——在假设压缩会加速之前测量你的实际瓶颈。
这里的胜利是在固定内存预算内实现更长的展开,而不一定是更快的生成。