Paper: 2603.08210 Authors: Zexi Wu, Qinghe Wang, Jing Dai, Baolu Li, Yiming Zhang, Yue Ma, Xu Jia, Hongming Xu Categories: cs.CV
The Gap
Video generation has reached a point where we can control outputs through various conditions — depth maps, pose skeletons, edge maps, you name it. But here’s the problem: methods using explicit structural guidance (like ControlNet) lock you into rigid spatial constraints. Want to generate a video that follows the semantic meaning of a reference but not its exact pixel layout? Tough luck. Meanwhile, specialized models trained for individual control types (depth-only, pose-only) can’t talk to each other. You need a separate model for each condition, and they don’t generalize to new control types without retraining.
The field has been stuck in a false dichotomy: either you get precise spatial control but lose semantic flexibility, or you train a zoo of specialized models that can’t adapt. This paper asks: can we have semantic alignment without spatial rigidity, and unified control without per-condition training?
Problem: Rigid spatial control OR isolated per-condition models
    |
    v
Assumption: Semantic info can be encoded as adaptive LoRA weights
    |
    v
Method: Hypernetwork predicts LoRA per reference video
    |
    v
Evidence: <150MB model handles diverse conditions + zero-shot generalization
    |
    v
Conclusion: Unified semantic control without per-condition training
The Increment
One sentence: Before Video2LoRA, you needed either rigid spatial control or a separate model per condition; after, one lightweight hypernetwork adapts to any semantic reference on the fly.
Core Mechanism
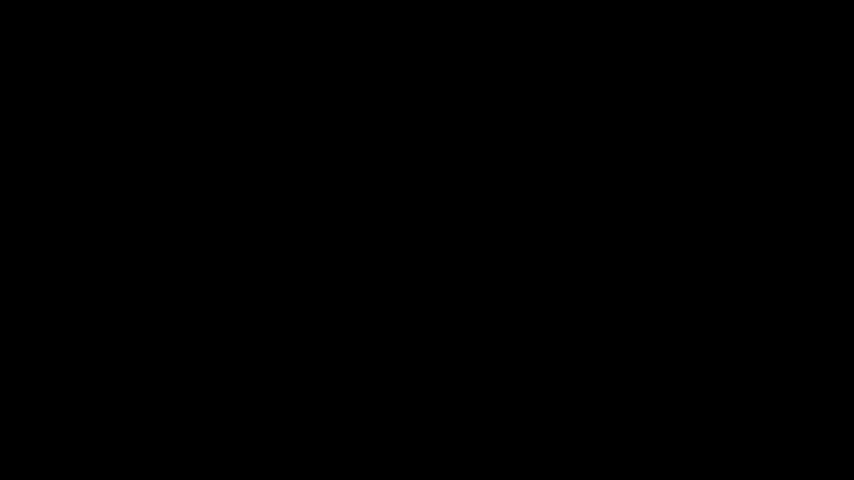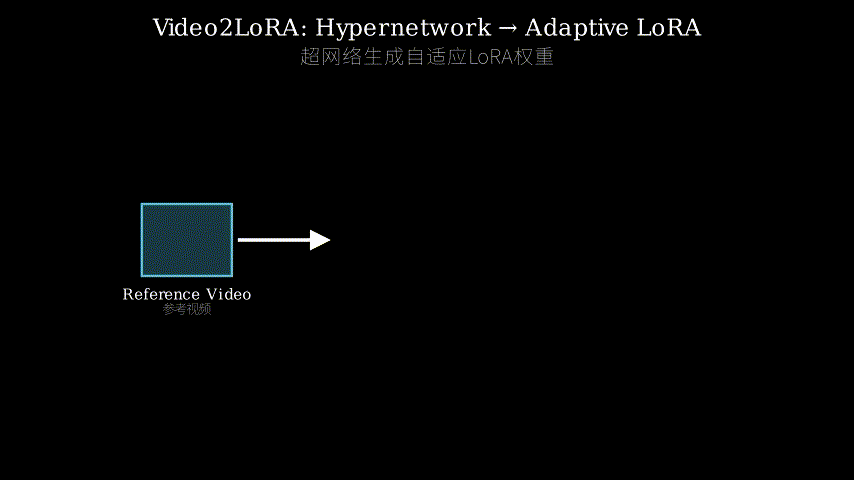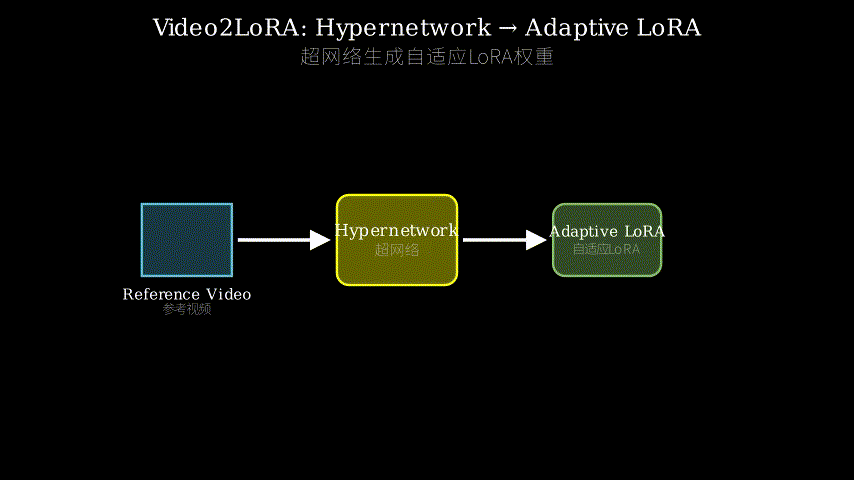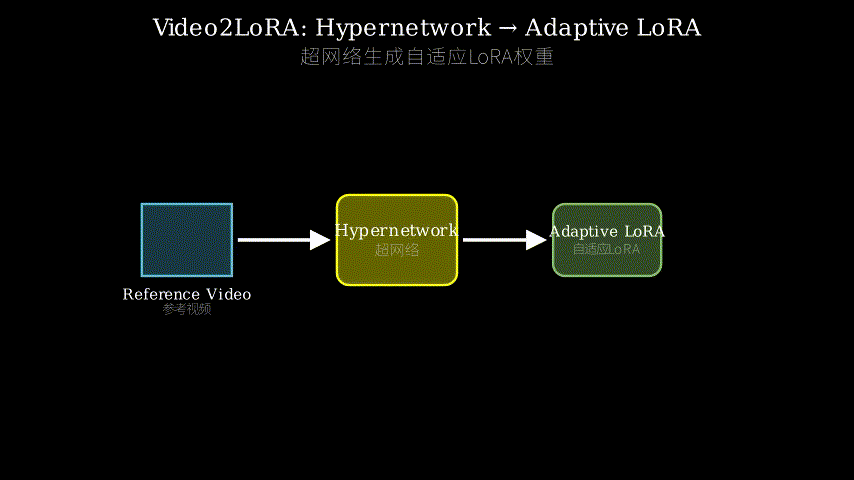
Video2LoRA has three main components working in sequence. First, a reference video (your semantic condition — could be depth, pose, whatever) gets encoded into a compact representation. Second, a lightweight hypernetwork takes this encoding and predicts personalized LoRA weights specific to that reference. Third, these predicted weights combine with auxiliary matrices to form adaptive LoRA modules that plug into a frozen diffusion backbone.
Here’s the data flow: your reference video enters as pixels, gets compressed into semantic features, flows through the hypernetwork which outputs LoRA weight predictions, these weights merge with learned auxiliary matrices, and the resulting adaptive LoRA modules modulate the frozen diffusion model’s attention and feedforward layers. The diffusion backbone never changes — all adaptation happens through these dynamically generated LoRA modules.
The clever bit is the auxiliary matrices. Instead of the hypernetwork predicting full LoRA weights (which would be huge), it predicts compact weight deltas that combine with pre-learned auxiliary matrices. Think of it as the hypernetwork saying “take this base pattern and shift it this way for this specific reference.” This keeps the hypernetwork tiny while maintaining expressiveness.
Reference Video
    |
    v
[Encoder] --> Semantic Features
    |
    v
[Hypernetwork] --> Predicted LoRA Weights (compact)
    |
    v
[Combine with Auxiliary Matrices] --> Adaptive LoRA Modules
    |
    v
[Frozen Diffusion Backbone + Adaptive LoRA] --> Generated Video
Think of Video2LoRA like a tailor’s shop. The frozen diffusion model is your standard mannequin — it doesn’t change. The auxiliary matrices are pre-made pattern templates hanging on the wall. When a customer (reference video) walks in, the hypernetwork is the tailor who quickly measures them and says “take pattern #3, adjust the shoulders this much, taper the waist that much.” The tailor doesn’t sew a whole new outfit from scratch (that would be predicting full LoRA weights), just marks up an existing pattern with specific alterations. The final garment (adaptive LoRA module) fits this customer perfectly, but the tailor can do this for any customer without retraining — they just need good measurement skills and a library of base patterns.
Key Concepts
-
LoRA (Low-Rank Adaptation): Imagine you have a massive neural network with millions of parameters, and you want to adapt it to a new task. Retraining everything is expensive. LoRA says: keep the original weights frozen, and add small “adapter” matrices that modify the network’s behavior. These adapters are low-rank (think: compressed), so they’re tiny compared to the full network. Concrete example: your base model knows how to generate generic videos. A LoRA module might encode “make it look like a watercolor painting” by tweaking just 0.1% of the parameters. Video2LoRA takes this further — instead of hand-crafting LoRA weights, it predicts them on the fly for each reference video.
-
Hypernetwork: A network that generates weights for another network. Sounds meta, but it’s practical. Instead of storing separate model weights for every possible condition (which would be massive), you store one small hypernetwork that can produce appropriate weights given any condition. Think of it like a function: input is “what kind of control do I need?”, output is “here are the weights to achieve that control.” Video2LoRA’s hypernetwork takes a reference video’s semantic encoding and outputs LoRA weights tailored to that specific reference.
-
Semantic vs Structural Control: Structural control means “put a person’s arm exactly here at pixel (x,y).” Semantic control means “there should be an arm doing a waving motion, but I don’t care about exact pixel positions.” Previous methods conflated these — if you gave them a pose skeleton, they’d force the generated video to match that skeleton’s exact spatial layout. Video2LoRA decouples them: it learns the semantic meaning (what’s happening) without enforcing rigid spatial constraints (where exactly it happens).
Framework Shift
Before (mainstream approach):        After (this paper):

Condition Type A                     Any Reference Video
    |                                     |
    v                                     v
[Specialized Model A]                [Hypernetwork]
    |                                     |
    v                                     v
[Frozen Diffusion]                   [Predict LoRA Weights]
    |                                     |
    v                                     v
Generated Video                      [Frozen Diffusion + Adaptive LoRA]
                                          |
Condition Type B                          v
    |                                Generated Video
    v
[Specialized Model B]
    |
    v
[Frozen Diffusion]
    |
    v
Generated Video

(Need separate model                 (One model handles all,
 per condition type)                  adapts on the fly)
From training a model zoo where each species handles one condition type, to one chameleon that adapts its colors based on whatever reference you show it.
Expert Assessment
Problem choice: This is a real gap, not manufactured. The field genuinely struggles with the tradeoff between control precision and semantic flexibility. The proliferation of condition-specific models is a practical pain point for deployment. However, the problem sits in the “incremental improvement” zone rather than “paradigm shift” territory — we’re optimizing existing diffusion pipelines, not rethinking video generation fundamentally.
Method maturity: The hypernetwork-predicts-LoRA idea is clever but not groundbreaking — it’s a natural evolution of existing techniques. The auxiliary matrices trick to keep the hypernetwork small is smart engineering. What’s missing: the paper doesn’t deeply explore why this particular factorization (hypernetwork + auxiliary matrices) is optimal. Are there simpler decompositions? The design feels somewhat empirically driven rather than principled.
Experimental integrity: The <150MB model size is impressive and well-documented. The zero-shot generalization claims need scrutiny — “unseen semantics” is vague. Are we talking about interpolation within the training distribution or true extrapolation? The paper would benefit from stress-testing on genuinely out-of-distribution conditions. Baselines seem fair, though I’d want to see comparisons with more recent unified control methods if they exist.
Writing quality: The abstract and introduction are solid. The method section gets dense quickly — the auxiliary matrix formulation could use a clearer motivation before diving into equations. The results section leans heavily on qualitative examples; more quantitative analysis of semantic alignment vs spatial fidelity tradeoffs would strengthen claims. The related work section does its job but doesn’t position the work sharply enough against recent hypernetwork and adapter literature.
Verdict: weak accept — Solid engineering contribution with practical value, but the conceptual novelty is incremental and the experimental validation could be more rigorous on the zero-shot claims.
Takeaways
The hypernetwork-generates-adapter-weights pattern is worth stealing. If you’re building any system where you need to adapt a frozen model to many different conditions, consider: instead of training separate adapters for each condition, train one hypernetwork that predicts adapter weights given a condition encoding. The auxiliary matrix trick (hypernetwork predicts deltas, not full weights) is a practical way to keep the hypernetwork small.
More broadly, this paper demonstrates that semantic control doesn’t require structural control. If you’re working on conditional generation, ask: am I enforcing spatial constraints because my task requires them, or because my method can’t separate semantic from structural information? There might be room to decouple these.
The <150MB model size for unified control is a concrete benchmark. If your multi-condition model is significantly larger, you’re probably doing something inefficient.
论文: 2603.08210 作者: Zexi Wu, Qinghe Wang, Jing Dai, Baolu Li, Yiming Zhang, Yue Ma, Xu Jia, Hongming Xu 分类: cs.CV
缺口
视频生成已经能通过各种条件控制输出——深度图、姿态骨架、边缘图,应有尽有。
但问题来了:使用显式结构引导的方法(比如ControlNet)会把你锁死在刚性的空间约束里。
想生成一个遵循参考视频语义含义但不照搬其像素布局的视频?没门。
与此同时,为单一控制类型训练的专用模型(只做深度、只做姿态)彼此无法互通。
每种条件需要一个单独模型,而且不重新训练就无法泛化到新控制类型。
这个领域一直困在一个虚假的二元对立里:要么获得精确的空间控制但失去语义灵活性,要么训练一堆无法适应的专用模型。
这篇论文问:我们能否在没有空间刚性的情况下实现语义对齐,在不做针对性训练的情况下实现统一控制?
问题: 刚性空间控制 或 孤立的单条件模型
    |
    v
假设: 语义信息可编码为自适应LoRA权重
    |
    v
方法: 超网络为每个参考视频预测LoRA
    |
    v
证据: <150MB模型处理多样条件+零样本泛化
    |
    v
结论: 无需针对性训练的统一语义控制
增量
一句话: Video2LoRA之前,你需要刚性空间控制或每个条件一个模型;之后,一个轻量超网络即时适应任何语义参考。
核心机制
Video2LoRA有三个主要组件按顺序工作。
首先,参考视频(你的语义条件——可以是深度、姿态,什么都行)被编码成紧凑表示。
其次,轻量超网络接收这个编码,预测针对该参考的个性化LoRA权重。
第三,这些预测权重与辅助矩阵结合,形成自适应LoRA模块,插入冻结的扩散主干。
数据流是这样的:参考视频以像素形式进入,被压缩成语义特征,流经超网络输出LoRA权重预测,这些权重与学习到的辅助矩阵合并,生成的自适应LoRA模块调制冻结扩散模型的注意力层和前馈层。
扩散主干从不改变——所有适应都通过这些动态生成的LoRA模块发生。
巧妙之处在于辅助矩阵。
超网络不预测完整LoRA权重(那会很庞大),而是预测与预学习辅助矩阵结合的紧凑权重增量。
可以理解为超网络在说”拿这个基础模式,针对这个特定参考往这个方向调整”。
这让超网络保持微小的同时维持表达力。
参考视频
    |
    v
[编码器] --> 语义特征
    |
    v
[超网络] --> 预测的LoRA权重(紧凑)
    |
    v
[与辅助矩阵结合] --> 自适应LoRA模块
    |
    v
[冻结扩散主干 + 自适应LoRA] --> 生成视频
把Video2LoRA想象成裁缝店。
冻结的扩散模型是标准人台——它不变。
辅助矩阵是挂在墙上的预制版型模板。
当顾客(参考视频)走进来,超网络是裁缝,快速量体后说”拿3号版型,肩部这样调,腰部那样收”。
裁缝不从头缝制全新衣服(那相当于预测完整LoRA权重),只在现有版型上标注具体改动。
最终成衣(自适应LoRA模块)完美贴合这位顾客,但裁缝可以为任何顾客做这件事而无需重新培训——他们只需要好的量体技能和一套基础版型库。
关键概念
- LoRA(低秩适应): 想象你有一个拥有数百万参数的巨型神经网络,想让它适应新任务。
重新训练所有参数代价高昂。
LoRA说:保持原始权重冻结,添加小型”适配器”矩阵来修改网络行为。
这些适配器是低秩的(可理解为:压缩的),所以相比完整网络非常微小。
具体例子:你的基础模型知道如何生成通用视频。
一个LoRA模块可能通过调整仅0.1%的参数来编码”让它看起来像水彩画”。
Video2LoRA更进一步——不是手工制作LoRA权重,而是为每个参考视频即时预测它们。
- 超网络: 为另一个网络生成权重的网络。
听起来很元,但很实用。
与其为每个可能的条件存储单独的模型权重(那会很庞大),不如存储一个小型超网络,它能根据任何条件产生适当权重。
把它想成函数:输入是”我需要什么样的控制?“,输出是”这是实现该控制的权重”。
Video2LoRA的超网络接收参考视频的语义编码,输出为该特定参考定制的LoRA权重。
- 语义控制vs结构控制: 结构控制意味着”把人的手臂精确放在像素(x,y)这里”。
语义控制意味着”应该有一只手臂做挥手动作,但我不在乎确切像素位置”。
以前的方法混淆了这两者——如果你给它们姿态骨架,它们会强制生成视频匹配该骨架的精确空间布局。
Video2LoRA将它们解耦:学习语义含义(发生了什么)而不强制刚性空间约束(确切发生在哪里)。
框架转变
之前(主流方法):                  之后(本文方法):

条件类型A                         任意参考视频
    |                                 |
    v                                 v
[专用模型A]                       [超网络]
    |                                 |
    v                                 v
[冻结扩散]                        [预测LoRA权重]
    |                                 |
    v                                 v
生成视频                          [冻结扩散 + 自适应LoRA]
                                      |
条件类型B                             v
    |                             生成视频
    v
[专用模型B]
    |
    v
[冻结扩散]
    |
    v
生成视频

(每种条件类型                    (一个模型处理所有,
 需要单独模型)                    即时适应)
从训练模型动物园(每个物种处理一种条件类型),到一只变色龙(根据你展示的任何参考调整颜色)。
专家评审
选题眼光: 这是真缺口,不是人造的。
该领域确实在控制精度和语义灵活性的权衡上挣扎。
条件特定模型的激增对部署来说是实际痛点。
然而,这个问题处于”渐进改进”区而非”范式转变”领域——我们在优化现有扩散管线,而非从根本上重新思考视频生成。
方法成熟度: 超网络预测LoRA的想法巧妙但不算开创性——它是现有技术的自然演进。
用辅助矩阵技巧保持超网络小型化是聪明的工程。
缺失的是:论文没有深入探讨为什么这种特定分解(超网络+辅助矩阵)是最优的。
有没有更简单的分解?设计感觉更多是经验驱动而非原则驱动。
实验诚意: <150MB模型大小令人印象深刻且有充分记录。
零样本泛化声明需要审视——“未见语义”很模糊。
我们说的是训练分布内的插值还是真正的外推?论文需要在真正分布外条件上进行压力测试。
基线看起来公平,但如果存在更新的统一控制方法,我想看到与它们的比较。
写作功力: 摘要和引言扎实。
方法部分很快变得密集——辅助矩阵公式在深入方程前需要更清晰的动机。
结果部分严重依赖定性示例;更多关于语义对齐vs空间保真度权衡的定量分析会强化声明。
相关工作部分尽职,但没有针对近期超网络和适配器文献足够尖锐地定位工作。
判决: 弱接收——具有实用价值的扎实工程贡献,但概念新颖性是渐进的,零样本声明的实验验证可以更严格。
要点总结
超网络生成适配器权重的模式值得借鉴。
如果你在构建任何需要让冻结模型适应许多不同条件的系统,考虑:与其为每个条件训练单独适配器,不如训练一个超网络,根据条件编码预测适配器权重。
辅助矩阵技巧(超网络预测增量而非完整权重)是保持超网络小型化的实用方法。
更广泛地说,这篇论文证明语义控制不需要结构控制。
如果你在做条件生成,问问:我强制空间约束是因为任务需要,还是因为方法无法分离语义和结构信息?可能有解耦的空间。
统一控制的<150MB模型大小是具体基准。
如果你的多条件模型显著更大,你可能在做低效的事。