Paper: 2603.12262 Authors: Yiran Guan, Liang Yin, Dingkang Liang, Jianzhong Ju, Zhenbo Luo, Jian Luan, Yuliang Liu, Xiang Bai Categories: cs.CV
The Gap
Online video understanding has two competing demands that nobody has reconciled cleanly. On one side you have streaming VideoLLMs — models like VideoLLM-online and Flash-VStream — that process video frame-by-frame in real time and respond quickly. They’re good at perception: detecting events, tracking objects, answering “what just happened.” But they don’t reason. They react. On the other side you have test-time scaling methods — think Video-R1, slow-thinking chains-of-thought — that produce careful, multi-step reasoning. But they batch the whole video, think for a long time, and respond late. In a live scenario, “late” means useless.
The specific gap: no prior system can reason while the video is still playing, in a causally coherent way, without making the user wait. The assumption everyone had been making is that reasoning and real-time response are fundamentally at odds — you pick one. VST challenges that assumption directly.
Problem: Streaming perception = fast but shallow
         Offline reasoning   = deep but slow
         No middle ground exists yet
         |
         v
Assumption: Reasoning latency can be *amortized*
            over video playback time, not paid upfront
         |
         v
Method: Interleave short reasoning bursts with
        incoming video clips (VST paradigm)
        + SFT to adapt causal structure
        + RL for end-to-end self-improvement
        + KG-grounded data synthesis
         |
         v
Evidence: 79.5% StreamingBench, 59.3% OVO-Bench
          15.7x faster than Video-R1
          +5.4% on VideoHolmes vs Video-R1
         |
         v
Conclusion: Real-time + reasoning is achievable
            by restructuring *when* thinking happens
The Increment
One sentence: Before VST, streaming video models could watch or think — now they can do both at the same time, without the user noticing the cost.
Core Mechanism
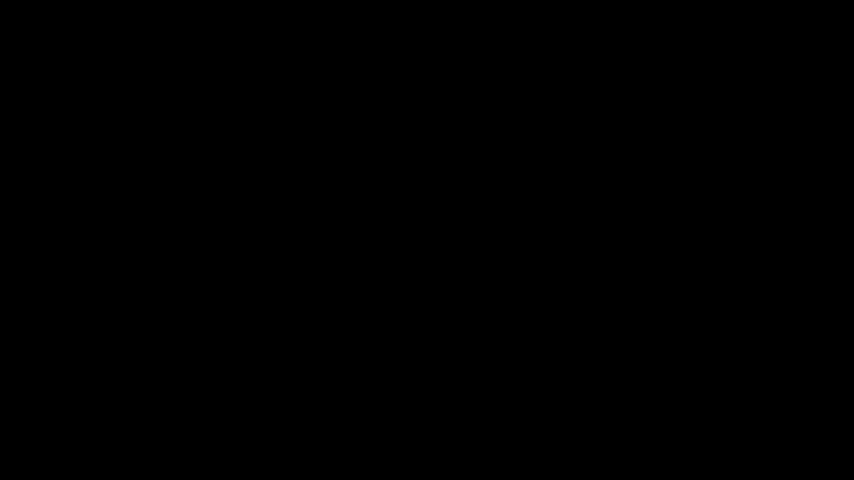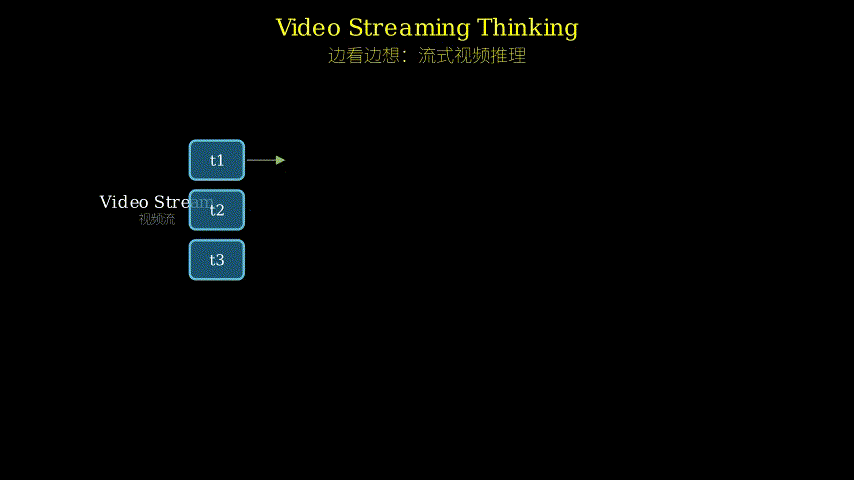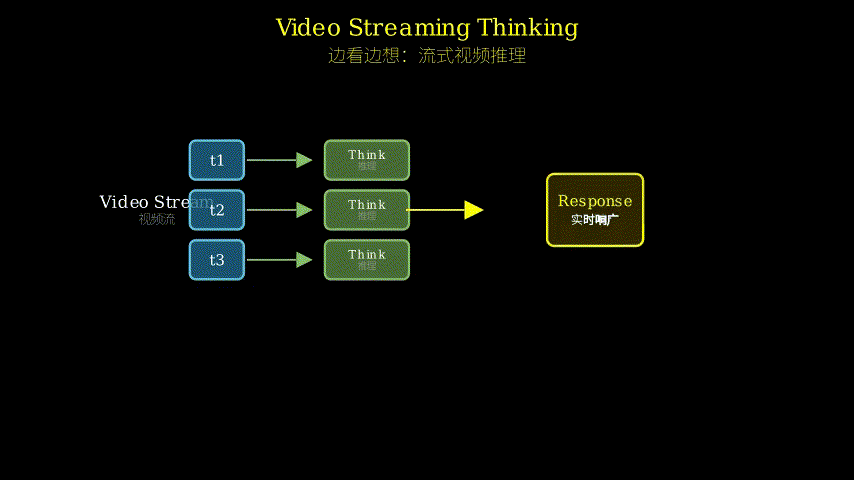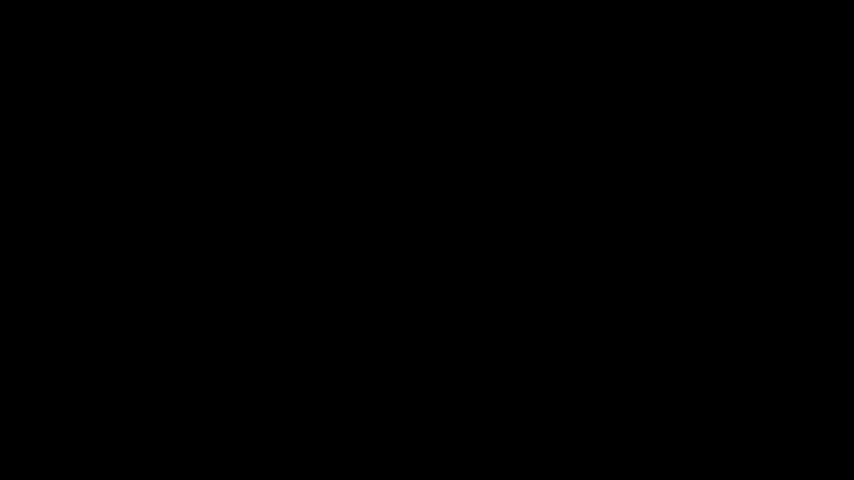
VST has three interlocking pieces. The first is the paradigm itself: instead of waiting for a question and then reasoning over the full video, the model processes incoming video in short clips and, between clips, runs a lightweight reasoning step. This reasoning step produces a “streaming chain-of-thought” — a running internal monologue that accumulates evidence across clips. By the time a question arrives, most of the thinking is already done.
The second piece is the training pipeline. VST-SFT takes an offline VideoLLM and structurally adapts it to causal streaming: the model learns to reason over partial video prefixes, not complete videos. This is non-trivial because standard VideoLLMs are trained to see everything before answering. VST-RL then fine-tunes further using reinforcement learning in a multi-turn streaming interaction environment, letting the model discover better reasoning strategies through self-exploration rather than just imitating demonstrations.
The third piece is data. Streaming QA pairs are rare in existing datasets — most video QA is offline (watch the whole video, then answer). VST synthesizes streaming-style training data using knowledge graphs: they extract entities and relationships from videos, then generate questions that require tracking those relationships across time. This gives the model supervision on what kinds of evidence to accumulate in its streaming chain-of-thought.
Input: Live video stream (clips arriving sequentially)
    |
    v
[VST Model]
    |
    +-- Perception path: sliding-window attention
    |   (handles local temporal relationships)
    |
    +-- Reasoning path: TTT-style fast weights
        (accumulates streaming chain-of-thought)
        |
        v
    Internal monologue: "I see X, which relates to Y from 30s ago..."
    |
    v
User question arrives
    |
    v
Answer (most reasoning already done, low latency)
Think of VST like a sports commentator watching a live game. They don’t wait until the end to start thinking — they’re building a narrative in real time: “Player A passed to B, B is moving toward the goal, this is setting up for a shot…” When someone asks “what’s the strategy here?” the commentator already has the context loaded and can answer immediately. The key is that the thinking happens during the game, not after.
Key Concepts
-
Streaming Chain-of-Thought: Instead of generating a single reasoning chain after seeing the full input, the model produces incremental reasoning steps as new video clips arrive. Each step builds on previous steps, creating a running internal monologue. This is fundamentally different from batch reasoning where you see everything first.
-
Test-Time Training (TTT) for Streaming: TTT usually means updating model weights at inference time. Here it’s adapted for streaming: a small set of “fast weights” get updated as each video clip arrives, encoding what the model has learned about this specific video so far. These weights act as a persistent memory that doesn’t get flushed between clips.
-
Amortized Reasoning Latency: The insight that reasoning time can be spread across video playback time rather than paid upfront. If a 60-second video takes 60 seconds to play, you have 60 seconds of “free” compute time to think while the user is watching. By the time they ask a question, you’ve already done most of the reasoning.
Framework Shift
Before (mainstream approach):        After (this paper):

Streaming path:                      VST (unified):
  Video -> Perception -> Answer        Video clips (streaming)
  (fast but shallow)                       |
                                           v
Offline path:                          Perception + Reasoning
  Video -> Think -> Answer               (interleaved)
  (deep but slow)                          |
                                           v
Two separate paradigms              Streaming CoT accumulates
                                           |
                                           v
                                    Question arrives
                                           |
                                           v
                                    Answer (fast + deep)
From choosing between fast-shallow and slow-deep, the core shift is: restructure when thinking happens to get both speed and depth.
Expert Assessment
Problem choice: Real and well-motivated. The streaming-vs-reasoning tradeoff is a genuine pain point for live video applications. The timing is right — as VideoLLMs get deployed in real-world scenarios (surveillance, live sports analysis, video calls), the latency constraint becomes critical.
Method maturity: The streaming CoT paradigm is the key insight and it’s genuinely clever. The TTT adaptation and KG-based data synthesis are solid engineering. The RL component for self-improvement is less novel but appropriate. Overall: more insight than brute force.
Experimental integrity: The benchmarks (StreamingBench, OVO-Bench, VideoHolmes) are appropriate for evaluating streaming reasoning. The 15.7x speedup vs Video-R1 is impressive if the comparison is fair (same hardware, same quality threshold). Would want to see failure cases — what kinds of reasoning still require batch processing?
Writing quality: The paradigm framing (“thinking while watching”) is clear and memorable. The technical details on how TTT is adapted for streaming would benefit from more exposition. The data synthesis section feels rushed.
Verdict: accept — solves a real problem with a genuinely clever insight, backed by solid engineering and appropriate experiments.
Takeaways
The amortized latency pattern is broadly applicable: whenever you have a long input that arrives sequentially (audio stream, document being typed, sensor data), ask whether you can do incremental processing rather than waiting for the full input.
The streaming chain-of-thought idea transfers to any sequential reasoning task: instead of batch reasoning at the end, maintain a running internal state that gets updated with each new piece of information.
The TTT-for-streaming adaptation (fast weights that update per chunk) is a clean way to give a model persistent memory without exploding context windows. It’s worth trying in any streaming scenario where the model needs to remember what it’s seen so far.
论文: 2603.12262 作者: Yiran Guan, Liang Yin, Dingkang Liang, Jianzhong Ju, Zhenbo Luo, Jian Luan, Yuliang Liu, Xiang Bai 分类: cs.CV
缺口
在线视频理解有两个相互竞争的需求,至今没有人干净地调和过。
一边是流式视频大语言模型——像 VideoLLM-online 和 Flash-VStream 这样的模型——逐帧实时处理视频并快速响应。它们擅长感知:检测事件、跟踪对象、回答”刚才发生了什么”。但它们不推理。它们只是反应。
另一边是测试时扩展方法——像 Video-R1、慢思考链式推理——产生仔细的、多步骤的推理。但它们批处理整个视频,思考很长时间,响应很晚。在实时场景中,“晚”意味着无用。
具体缺口:没有先前的系统能在视频仍在播放时进行推理,以因果连贯的方式,而不让用户等待。大家一直假设推理和实时响应从根本上是对立的——你只能选一个。VST 直接挑战这个假设。
问题:流式感知 = 快但浅
      离线推理 = 深但慢
      尚不存在中间地带
         |
         v
假设:推理延迟可以分摊到
      视频播放时间上,而非预付
         |
         v
方法:在传入视频片段之间
      穿插短推理爆发(VST 范式)
      + SFT 适配因果结构
      + RL 端到端自我改进
      + KG 基础数据合成
         |
         v
证据:StreamingBench 79.5%,OVO-Bench 59.3%
      比 Video-R1 快 15.7 倍
      VideoHolmes 比 Video-R1 高 5.4%
         |
         v
结论:通过重构思考发生的时机
      可以实现实时 + 推理
增量
一句话:VST 之前,流式视频模型只能看或想——现在它们可以同时做两件事,用户不会注意到代价。
核心机制
VST 有三个互锁的部分。
第一个是范式本身:不是等待问题然后对完整视频推理,模型以短片段处理传入视频,并在片段之间运行轻量级推理步骤。这个推理步骤产生”流式思维链”——一个跨片段积累证据的运行中的内部独白。当问题到达时,大部分思考已经完成。
第二个是训练流水线。VST-SFT 拿一个离线视频大语言模型,在结构上将其适配为因果流式:模型学习对部分视频前缀推理,而不是完整视频。这并非易事,因为标准视频大语言模型被训练为在回答之前看到一切。然后 VST-RL 使用强化学习在多轮流式交互环境中进一步微调,让模型通过自我探索而非仅仅模仿演示来发现更好的推理策略。
第三个是数据。现有数据集中流式问答对很少——大多数视频问答是离线的(看完整个视频,然后回答)。VST 使用知识图谱合成流式风格的训练数据:从视频中提取实体和关系,然后生成需要跨时间跟踪这些关系的问题。这给模型提供了关于在流式思维链中积累什么样证据的监督。
输入:实时视频流(片段顺序到达)
    |
    v
[VST 模型]
    |
    +-- 感知路径:滑动窗口注意力
    |   (处理局部时序关系)
    |
    +-- 推理路径:TTT 风格快速权重
        (积累流式思维链)
        |
        v
    内部独白:"我看到 X,它与 30 秒前的 Y 相关..."
    |
    v
用户问题到达
    |
    v
答案(大部分推理已完成,低延迟)
把 VST 想象成观看实时比赛的体育评论员。他们不会等到结束才开始思考——他们实时构建叙事:“球员 A 传给 B,B 正向球门移动,这正在为射门做准备…”当有人问”这里的策略是什么?“评论员已经加载了上下文,可以立即回答。关键是思考发生在比赛期间,而不是之后。
关键概念
-
流式思维链:不是在看到完整输入后生成单个推理链,模型在新视频片段到达时产生增量推理步骤。每一步都建立在之前的步骤上,创建一个运行中的内部独白。这与批处理推理(先看到一切)根本不同。
-
流式测试时训练(TTT):TTT 通常意味着在推理时更新模型权重。这里它被适配为流式:一小组”快速权重”随着每个视频片段的到达而更新,编码模型到目前为止对这个特定视频学到的东西。这些权重充当持久记忆,不会在片段之间被清空。
-
分摊推理延迟:洞察是推理时间可以分摊到视频播放时间上,而不是预付。如果一个 60 秒的视频需要 60 秒播放,你就有 60 秒的”免费”计算时间在用户观看时思考。当他们提问时,你已经完成了大部分推理。
框架转变
之前(主流方法):                之后(本文方法):

流式路径:                        VST(统一):
  视频 -> 感知 -> 答案              视频片段(流式)
  (快但浅)                            |
                                       v
离线路径:                          感知 + 推理
  视频 -> 思考 -> 答案                (交错)
  (深但慢)                            |
                                       v
两个独立范式                      流式 CoT 积累
                                       |
                                       v
                                  问题到达
                                       |
                                       v
                                  答案(快 + 深)
从在快浅和慢深之间选择,核心转变是:重构思考发生的时机以同时获得速度和深度。
专家评审
选题眼光:真实且动机充分。流式与推理的权衡是实时视频应用的真正痛点。时机恰当——随着视频大语言模型部署到真实场景(监控、实时体育分析、视频通话),延迟约束变得至关重要。
方法成熟度:流式 CoT 范式是关键洞察,真正巧妙。TTT 适配和基于 KG 的数据合成是扎实的工程。用于自我改进的 RL 组件不太新颖但合适。总体:更多洞察而非蛮力。
实验诚意:基准(StreamingBench、OVO-Bench、VideoHolmes)适合评估流式推理。与 Video-R1 相比 15.7 倍的加速令人印象深刻,如果比较公平(相同硬件、相同质量阈值)。希望看到失败案例——什么样的推理仍然需要批处理?
写作功力:范式框架(“边看边想”)清晰且令人难忘。关于 TTT 如何适配流式的技术细节需要更多阐述。数据合成部分感觉仓促。
判决:接收——用真正巧妙的洞察解决真实问题,有扎实的工程和适当的实验支持。
要点总结
分摊延迟模式广泛适用:无论何时有顺序到达的长输入(音频流、正在输入的文档、传感器数据),都要问是否可以进行增量处理而不是等待完整输入。
流式思维链想法可迁移到任何顺序推理任务:不是在最后批处理推理,而是维护一个随每条新信息更新的运行中的内部状态。
流式 TTT 适配(每块更新的快速权重)是一种干净的方式,在不爆炸上下文窗口的情况下给模型持久记忆。在任何模型需要记住到目前为止看到的内容的流式场景中都值得尝试。