Paper: 2603.30043 Authors: Kaleb Newman, Tyler Zhu, Olga Russakovsky Categories: cs.CV
The Gap
Video diffusion models can solve mazes and puzzles, but we don’t understand how they reason during generation. Prior work treats these models as black boxes that magically produce solutions. The specific limitation: we can’t predict when they’ll fail, can’t improve their reliability, and waste compute on doomed generation attempts. This paper cracks open the black box to study internal planning dynamics.
Problem: Video models solve mazes, but we don't know HOW
         |
         v
Assumption: Planning happens gradually across all denoising steps
         |
         v
Method: Probe internal states during denoising + measure when plans form
         |
         v
Evidence: Plans commit in first ~5 steps, path length predicts failure
         |
         v
Conclusion: Only compute on good early plans + chain short segments
The Increment
One sentence: Before this paper, video models were opaque maze solvers that sometimes worked; after, we know they commit to plans early and can exploit this to solve 10x longer mazes by chaining.
Core Mechanism
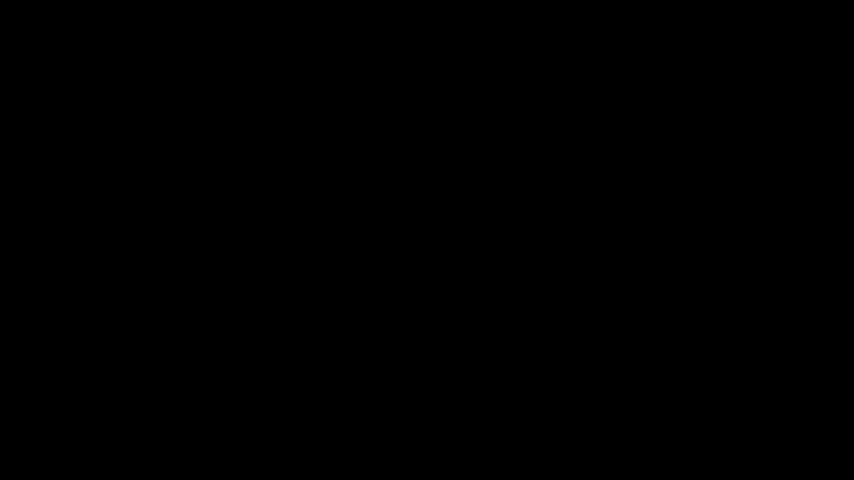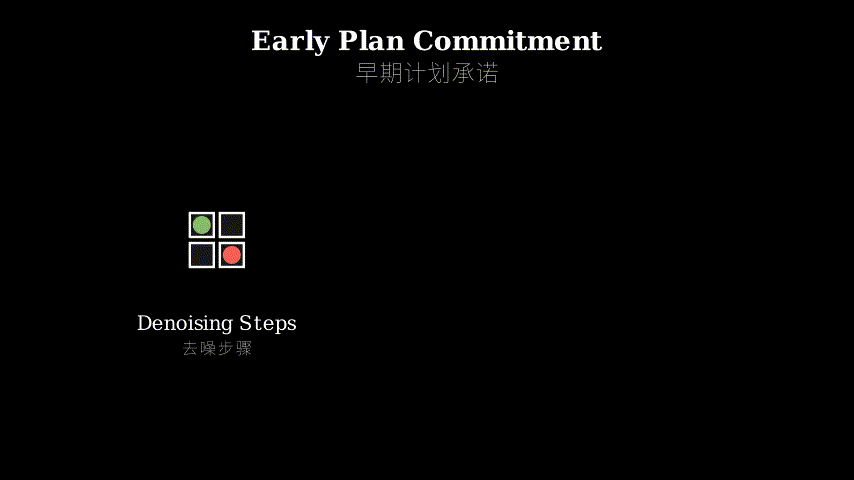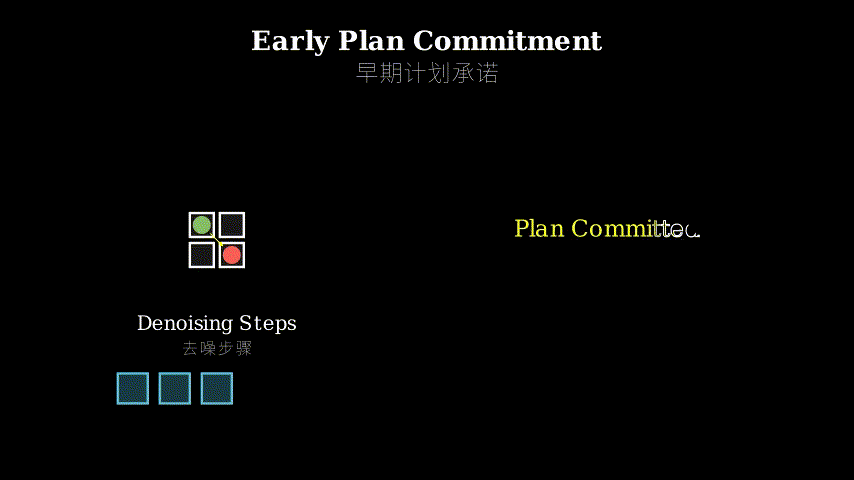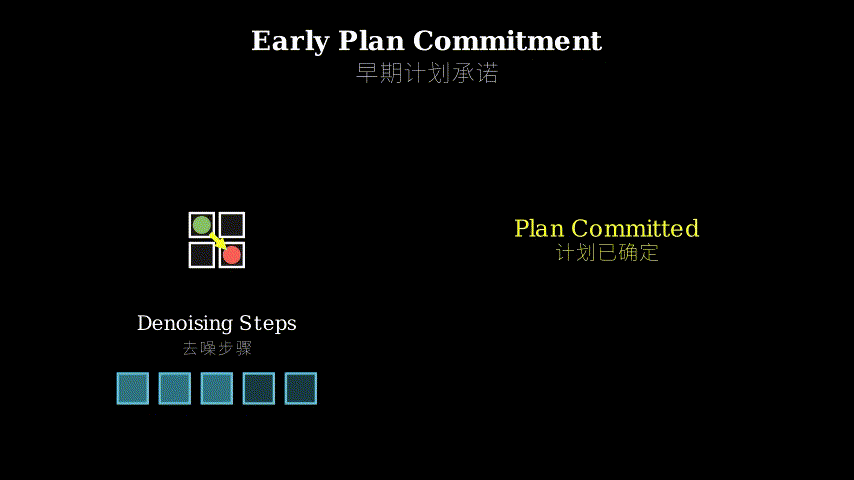
The method has two phases: diagnosis and exploitation. In diagnosis, they freeze a video diffusion model at different denoising timesteps and measure when the trajectory becomes fixed. They discover that by step 5 out of 50, the high-level path is already determined—later steps only refine visual details. They also test mazes of varying complexity and find that path length (not obstacle density) predicts failure, with a sharp threshold at 12 steps.
In exploitation, they build ChEaP (Chaining with Early Planning). For each generation seed, they run only the first 5 denoising steps, check if the emerging plan looks promising, and discard bad seeds early. For long mazes, they chain multiple short generations: solve the first segment, use the endpoint as the new start, repeat. This turns an impossible 30-step maze into three manageable 10-step problems.
ChEaP Architecture:

Seed pool (N=100)
    |
    v
[Early Planning Filter]  <-- Run only 5 denoising steps
    |                         Check trajectory quality
    +---> Discard 93 bad seeds
    |
    v
Keep 7 promising seeds
    |
    v
[Full Generation] --> 10-step segment solved
    |
    v
[Chaining Logic] --> Use endpoint as new start --> Repeat
    |
    v
Complete 30-step maze (3 chains of 10 steps each)
Think of video generation like a sculptor working with clay. Most people assume the sculptor gradually refines the shape throughout the entire process—first rough form, then medium detail, then fine touches. But this paper discovers that sculptors actually commit to the pose in the first few hammer strikes. After that, they’re just smoothing surfaces and adding texture. The pose is locked in.
ChEaP exploits this by watching the sculptor’s first few strikes. If the emerging pose looks wrong (arm at a bad angle), stop immediately and try a new block of clay. Don’t waste time smoothing a fundamentally flawed sculpture. For complex poses that require multiple figures, sculpt them separately and connect them—don’t try to sculpt a 10-person group in one go.
Key Concepts
-
Early Plan Commitment: Video diffusion models work by gradually removing noise over 50 steps. Conventional wisdom says each step contributes equally to the final result. But these models actually make the critical decision—which path to take through the maze—in the first 10% of steps. The remaining 90% of compute just fills in visual details like texture and lighting. It’s like a chess player deciding their strategy in the opening moves, then spending the rest of the game executing tactics that follow from that early commitment. The model can’t change its mind about the fundamental trajectory once those early steps are done.
-
Path Length Dominance: When testing what makes mazes hard, the intuitive answer is “more walls and obstacles.” But the data shows something different: a maze with 100 obstacles but only 8 steps to the goal is easier than a maze with 10 obstacles but 15 steps. The model has a working memory limit—it can track about 12 steps of sequential reasoning. Beyond that, accuracy collapses from 80% to 7%. This isn’t about visual complexity; it’s about how many future states the model must hold in its internal representation simultaneously.
Framework Shift
Before (mainstream approach):        After (this paper):

[Black Box]                          [Transparent Planning]
Input --> [50 steps] --> Output      Input --> [5 steps: PLAN FORMS]
          all equal                           [45 steps: visual polish]

Single generation:                   Chained generation:
[====== 30 steps ======]            [=10=] -> [=10=] -> [=10=]
     (fails)                              (succeeds)

Uniform compute:                     Adaptive compute:
Seed1 [====================]        Seed1 [===] X (bad plan, stop)
Seed2 [====================]        Seed2 [===] X
Seed3 [====================]        Seed3 [====================] ✓
  (waste on bad seeds)                (focus on good seeds)
From treating generation as a uniform process to recognizing it as early commitment + refinement, the core shift is exploiting temporal structure in the denoising process.
Expert Assessment
Problem choice: This is a real gap with broader implications. Understanding when and how models commit to plans matters beyond mazes—it applies to any sequential reasoning task (code generation, robotic planning, story writing). The maze testbed is clever because it’s simple enough to analyze but complex enough to reveal genuine reasoning dynamics. Sits at the intersection of interpretability and inference-time scaling, both hot areas.
Method maturity: The diagnostic approach (probing at different timesteps) is straightforward but effective. ChEaP is more engineering than algorithmic innovation—it’s beam search with early stopping plus chaining. That said, the simplicity is a feature: the insights are robust and the method is practical. No obvious simpler approach was overlooked; they did the legwork to establish the 12-step threshold empirically.
Experimental integrity: Baselines are fair (standard sampling, best-of-N). The 7% → 67% improvement is dramatic but comes from combining two effects (early filtering + chaining), making it hard to isolate contributions. The sharp threshold at 12 steps is suspicious—feels too clean. I’d want to see error bars and tests on more diverse maze topologies. The VR-Bench and Frozen Lake results (2.5x improvement) are more convincing because they’re out-of-distribution validation.
Writing quality: The paper front-loads results well, but the “why does early commitment happen?” question is underexplored. Section 4.2 on path length vs. obstacle density is the strongest part—clear hypothesis, clean experiment. The related work section is thin; they could better position this against chain-of-thought prompting and iterative refinement methods in LLMs. Rewriting the discussion to connect early planning to attention mechanisms would elevate the work from empirical observation to mechanistic insight.
Verdict: weak accept — Solid empirical contribution with practical impact, but lacks depth on the “why” behind early commitment. The chaining idea is useful but not novel. Still, the 12-step threshold finding is valuable and the method works.
Takeaways
Practitioners can steal three things:
-
Early stopping for generative models: Don’t run full inference on every seed. If you’re doing best-of-N sampling, check quality at 10% progress and kill bad candidates. This applies beyond video—try it with LLM code generation (check syntax after first 20 tokens) or image generation (check composition after early steps).
-
Chaining for long-horizon tasks: When a model has a working memory limit, don’t fight it—work with it. Break 30-step problems into three 10-step problems. This is obvious in hindsight but underutilized. Applies to robotic planning, long-form writing, multi-step math problems.
-
Path length as a complexity metric: For sequential reasoning tasks, count the number of dependent steps, not the amount of information. A 1000-line codebase with 5 function calls is easier than a 100-line codebase with 20 nested conditionals. Use this to predict when your model will struggle and when to switch strategies.
论文: 2603.30043 作者: Kaleb Newman, Tyler Zhu, Olga Russakovsky 分类: cs.CV
缺口
视频扩散模型能解迷宫和谜题,但我们不理解它们在生成过程中如何推理。
此前的工作把这些模型当黑盒,认为它们神奇地产出答案。
具体的局限是:我们无法预测它们何时失败,无法提高可靠性,还在注定失败的生成尝试上浪费算力。
这篇论文打开黑盒,研究内部规划动态。
问题: 视频模型能解迷宫,但不知道HOW
         |
         v
假设: 规划在所有去噪步骤中逐渐发生
         |
         v
方法: 探测去噪过程中的内部状态 + 测量计划何时形成
         |
         v
证据: 计划在前5步就确定,路径长度预测失败
         |
         v
结论: 只对好的早期计划投入算力 + 链接短片段
增量
一句话: 这篇论文之前,视频模型是不透明的迷宫求解器,有时灵有时不灵;之后,我们知道它们早期就承诺计划,可以利用这点通过链接解决10倍长的迷宫。
核心机制
方法分两个阶段:诊断和利用。
在诊断阶段,他们在不同去噪时间步冻结视频扩散模型,测量轨迹何时固定。
他们发现在50步中的第5步,高层路径就已经确定——后续步骤只是细化视觉细节。
他们还测试不同复杂度的迷宫,发现路径长度(而非障碍密度)预测失败,在12步处有一个陡峭的阈值。
在利用阶段,他们构建ChEaP(带早期规划的链接)。
对每个生成种子,只运行前5步去噪,检查新出现的计划是否有希望,早早丢弃坏种子。
对长迷宫,他们链接多个短生成:解决第一段,用终点作为新起点,重复。
这把不可能的30步迷宫变成三个可控的10步问题。
ChEaP 架构:

种子池 (N=100)
    |
    v
[早期规划过滤器]  <-- 只运行5步去噪
    |                  检查轨迹质量
    +---> 丢弃93个坏种子
    |
    v
保留7个有希望的种子
    |
    v
[完整生成] --> 10步片段解决
    |
    v
[链接逻辑] --> 用终点作为新起点 --> 重复
    |
    v
完成30步迷宫 (3条10步的链)
把视频生成想象成雕塑家用泥巴工作。
大多数人以为雕塑家在整个过程中逐渐细化形状——先粗糙形态,再中等细节,最后精修。
但这篇论文发现雕塑家其实在最初几锤就确定了姿态。
之后只是打磨表面和添加纹理。
姿态已经锁定。
ChEaP利用这点,观察雕塑家的前几锤。
如果新出现的姿态看起来不对(手臂角度不好),立即停止,换一块新泥巴。
不要浪费时间打磨一个根本有缺陷的雕塑。
对需要多个人物的复杂姿态,分别雕刻再连接——不要试图一次雕出10个人的群像。
关键概念
- 早期计划承诺: 视频扩散模型通过50步逐渐去噪工作。
传统观点认为每步贡献相等。
但这些模型实际上在前10%的步骤中做出关键决策——在迷宫中走哪条路。
剩下90%的算力只是填充视觉细节,比如纹理和光照。
就像棋手在开局阶段决定策略,然后用剩余时间执行遵循早期承诺的战术。
一旦早期步骤完成,模型无法改变对基本轨迹的想法。
- 路径长度主导: 测试什么让迷宫变难时,直觉答案是”更多墙和障碍”。
但数据显示不同:一个有100个障碍但只需8步到达目标的迷宫,比一个有10个障碍但需15步的迷宫更容易。
模型有工作记忆限制——它能追踪约12步的顺序推理。
超过这个限制,准确率从80%崩溃到7%。
这不是视觉复杂度的问题;而是模型必须在内部表示中同时保持多少未来状态。
框架转变
之前(主流方法):                  之后(本文方法):

[黑盒]                           [透明规划]
输入 --> [50步] --> 输出          输入 --> [5步: 计划形成]
         全部平等                         [45步: 视觉打磨]

单次生成:                        链式生成:
[====== 30步 ======]            [=10=] -> [=10=] -> [=10=]
     (失败)                           (成功)

均匀算力:                        自适应算力:
种子1 [====================]    种子1 [===] X (坏计划,停止)
种子2 [====================]    种子2 [===] X
种子3 [====================]    种子3 [====================] ✓
  (浪费在坏种子上)                 (聚焦好种子)
从把生成当作均匀过程到认识到它是早期承诺+细化,核心转变是利用去噪过程中的时间结构。
专家评审
选题眼光: 这是真缺口,有更广泛的意义。
理解模型何时以及如何承诺计划,不只关乎迷宫——它适用于任何顺序推理任务(代码生成、机器人规划、故事写作)。
迷宫测试平台很聪明,因为它足够简单可以分析,又足够复杂能揭示真实的推理动态。
处于可解释性和推理时扩展的交叉点,两者都是热门领域。
方法成熟度: 诊断方法(在不同时间步探测)直接但有效。
ChEaP更多是工程而非算法创新——它是带早停的束搜索加链接。
话虽如此,简单性是优点:洞见稳健,方法实用。
没有明显被忽略的更简单方法;他们做了实证工作确立12步阈值。
实验诚意: 基线公平(标准采样、best-of-N)。
7%→67%的提升很戏剧化,但来自组合两个效应(早期过滤+链接),难以隔离贡献。
12步的陡峭阈值可疑——感觉太干净。
我想看误差条和更多样化迷宫拓扑的测试。
VR-Bench和Frozen Lake的结果(2.5倍提升)更有说服力,因为它们是分布外验证。
写作功力: 论文前置结果做得好,但”为什么发生早期承诺?”这个问题探索不足。
4.2节关于路径长度vs障碍密度是最强部分——清晰假设,干净实验。
相关工作部分单薄;他们可以更好地将此与LLM中的思维链提示和迭代细化方法对比。
重写讨论部分,将早期规划与注意力机制联系起来,能把工作从经验观察提升到机制洞见。
判决: 弱接收 — 扎实的经验贡献,有实际影响,但缺乏对早期承诺背后”为什么”的深度。
链接想法有用但不新颖。
尽管如此,12步阈值的发现有价值,方法有效。
要点总结
实践者能偷走三样东西:
- 生成模型的早停: 不要对每个种子运行完整推理。
如果你在做best-of-N采样,在10%进度时检查质量,杀掉坏候选。
这超越视频——试试LLM代码生成(前20个token后检查语法)或图像生成(早期步骤后检查构图)。
- 长期任务的链接: 当模型有工作记忆限制时,不要对抗它——顺应它。
把30步问题拆成三个10步问题。
这事后看来显而易见但利用不足。
适用于机器人规划、长文写作、多步数学问题。
- 路径长度作为复杂度指标: 对顺序推理任务,数依赖步骤的数量,而非信息量。
一个有5次函数调用的1000行代码库,比一个有20个嵌套条件的100行代码库更容易。
用这个预测你的模型何时会挣扎,何时该切换策略。