Paper: 2606.12373 Authors: Hao Xiang, Qiaoyu Tang, Le Yu, Yaojie Lu, Xianpei Han, Ben He, Le Sun, Bowen Yu, Peng Wang, Hongyu Lin Categories: cs.CL
The Gap
Existing work on Reinforcement Learning (RL) with verifiable environments (e.g., math or code) shows that scaling the number of environments improves LLM reasoning. But those environments are constructed individually by hand or through narrow automation — each new environment is a separate effort. This leads to a linear scaling limit: you need O(N) manual labor to get N environments, and the diversity of reasoning patterns is constrained by human design.
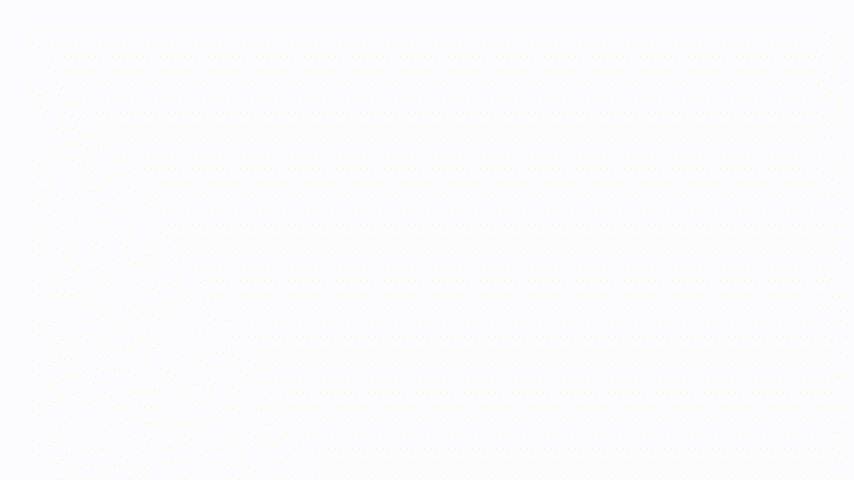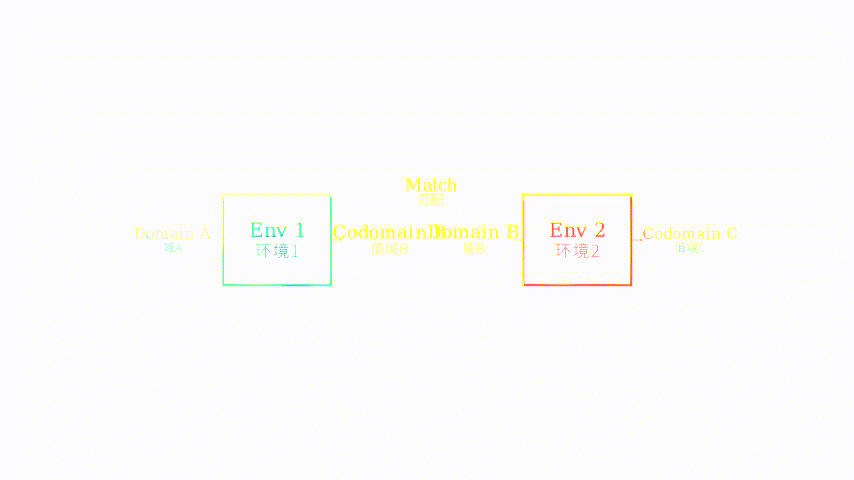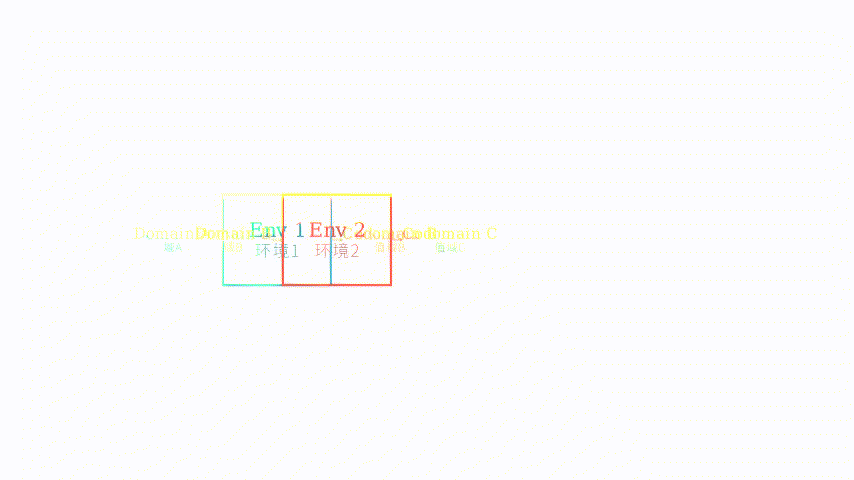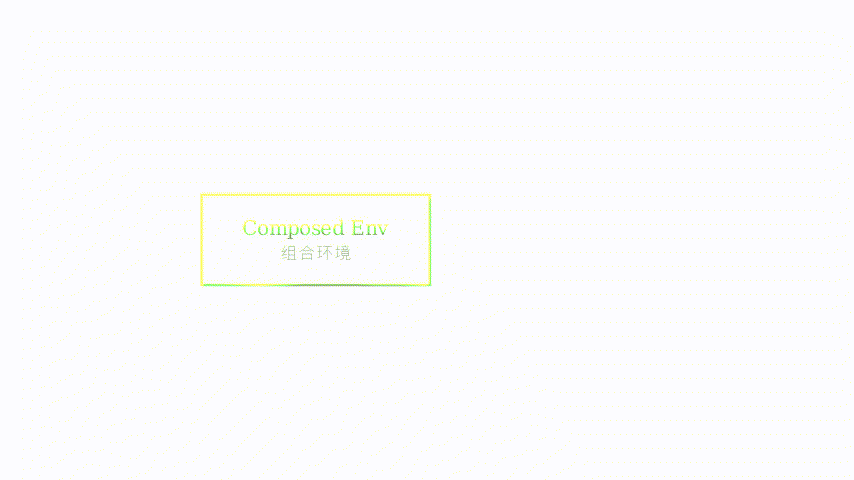
RACES breaks this limit by treating environments as composable building blocks. The gap is simple: why start from scratch each time when you can combine existing environments like LEGO bricks? The paper shows that if the output type (codomain) of one environment matches the input type (domain) of another, they can be fused automatically into a new verifiable environment — and this can be done recursively.
[Problem: linear scaling of manual environments]
     |
     v
[Assumption: type-compatible envs can be composed automatically]
     |
     v
[Method: RACES with recursive composition operators]
     |
     v
[Evidence: +3.1 pts on Qwen-14B (48.2 -> 51.3) on 6 unseen benchmarks]
     |
     v
[Conclusion: composition enables efficient, scalable RL]
The Increment
One sentence: Before RACES, scaling RL for reasoning meant linearly increasing the number of hand-crafted verifiable environments; after RACES, environments become LEGO bricks — automatically composable — so you achieve better generalization with fewer base pieces.
Core Mechanism
RACES starts with a library of 300 individual environments, each tagged with an explicit input type (domain) and output type (codomain). For example, a simple arithmetic env might take a number (input) and produce a sum (output). The key is that environment composition is driven by these type signatures.
The framework defines four composition operators:
SEQUENTIAL: plug the output of one env into the input of another.PARALLEL: run multiple environments side-by-side and combine their outputs.SORT: sort the outputs of a set of environments based on a scoring function.SELECT: choose one among several environment outputs based on a condition.
These operators can be nested recursively — a composite environment becomes a new building block that can itself be composed further. During RL training, agents (LLMs) see these composite environments, which force them to perform multi-step reasoning, combinatorial search, or conditional branching — patterns rarely seen in single standalone environments.
[Base Environments (300)]  --- type signatures (domain, codomain)
         |
         +-- [Operator: SEQUENTIAL] --> chain: env1 -> env2 -> env3
         +-- [Operator: PARALLEL]    --> merge: envA || envB
         +-- [Operator: SORT]        --> order outputs by score
         +-- [Operator: SELECT]      --> choose among candidates
         |
         v
   [Composite Environments] (recursive, diverse reasoning patterns)
Structural metaphor: LEGO bricks. Each base environment is a brick with studs (input type) and bottom holes (output type). A SEQUENTIAL composition is like stacking a 2x2 brick on top of a 1x1 — the studs (output) of the lower brick must fit the holes (input) of the upper. A PARALLEL operator is like placing two bricks side-by-side on a baseplate; their outputs are combined (e.g., summed). SORT is a sorting tray that rearranges the bricks by size. SELECT is a filter that picks the brick that meets a certain color or shape condition. When you build a complex model (the composite environment), the LLM must navigate the entire assembly — each joint forces a reasoning step. The more diverse the composite structures, the more transferable reasoning skills the LLM learns.
Key Concepts
- Verifiable Environment: A task where the correct answer is known programmatically (e.g., evaluating a mathematical expression). In RL, this provides automatic reward without human annotation. The environment becomes a “circuit” that takes input, executes a process, and verifies the output.
- Domain/Codomain Matching: Think of a USB cable: the plug (output type) must match the port (input type). In RACES, every environment declares its input and output types (e.g.,
int -> int,string -> bool). Only environments with matching types can be composed via SEQUENTIAL. This ensures composability without runtime errors. - Recursive Composition: A composite environment is itself a new environment with its own domain/codomain. You can compose composites: e.g.,
SEQUENTIAL( SEQUENTIAL(A,B), C). This allows exponential growth in complexity from a small set of base bricks — the paper shows that 50 base environments can yield training diversity comparable to 300 individually crafted ones.
Framework Shift
The shift is from manual, atomized environments to automated, compositional environment generation.
Before (mainstream approach):        After (this paper):
[Env1] [Env2] ... [Env300]          [Base Env A] [Base Env B] [Base Env C]
  each handcrafted                    \         |          /
  no reuse between envs               [Operators: SEQ, PAR, SORT, SEL]
  scaling = more manual work                \    |    /
                                           [Composite Envs]
                                         (recurse on composites)
One sentence: From atomized manual construction to type-driven recursive composition, the core shift is that diversity of reasoning patterns comes from combining a small set of primitives, not from designing each task individually.
Expert Assessment
Problem choice: Real gap. The RL+verifiable environment line is hot right now (e.g., DeepSeek-R1, AlphaProof), and the manual scaling bottleneck is indeed limiting. The paper targets a structural inefficiency, not a manufactured issue.
Method maturity: Clever but not deep. The type-matching insight is straightforward once stated; the main engineering effort is in defining the composition operators and maintaining the 300 base environments. There might be simpler approaches (e.g., random concatenation of problems without type checking), but the recursive composition with explicit types ensures correctness and enables the diverse reasoning patterns. The method is solidly practical.
Experimental integrity: Baselines seem fair — they compare RACES (trained on composite environments) against standard RL training on individual environments. The results show clear gains on 6 unseen benchmarks. However, I would want to see more details: are the training steps and compute equal between conditions? The paper claims efficiency (50 base envs get same performance as 300 individual) — that metric is valuable but needs validation on computational cost, not just environment count. No obvious red flags, but reproducibility would depend on the public release of the environment library.
Writing quality: Clear and well-structured. The LEGO analogy is well used. The weakness is in the experimental section: they could better explain why the 4 operators were chosen, and provide ablation studies (e.g., what if you only use SEQUENTIAL?). Also, the related work section is thin — a few more citations would contextualize the contribution.
Verdict: weak accept — a practical, well-executed contribution that advances the tooling of RL for LLM reasoning. It is not a theoretical breakthrough, but it solves an immediate engineering bottleneck with a simple, reusable idea.
Takeaways
- Define type signatures for your tasks: Whether you’re building RL environments, robotic control sequences, or data pipelines, explicit input/output type matching unlocks automatic composition.
- Use a small set of generic composition operators: SEQUENTIAL, PARALLEL, SORT, SELECT cover many reasoning patterns. You can likely apply similar operators in any domain that involves multi-step processing.
- Recursion amplifies diversity: Starting from even a handful of base building blocks, recursive composition can generate combinatorially many training examples — this is a principle that generalizes well beyond this paper (e.g., to curriculum learning or automated prompt engineering).
论文: 2606.12373 作者: Hao Xiang, Qiaoyu Tang, Le Yu, Yaojie Lu, Xianpei Han, Ben He, Le Sun, Bowen Yu, Peng Wang, Hongyu Lin 分类: cs.CL
缺口
现有研究使用可验证环境(如数学题、代码题)进行强化学习来提升LLM推理能力。 他们发现,增加环境数量能提升性能。 但每个环境都是人工或半自动单独构建的——新增一个环境就是一次新的劳动。 这导致线性扩展瓶颈:要获得N个环境,需要O(N)的人工投入,并且推理模式的多样性受限于人类设计。
RACES通过把环境视为可组合的积木打破了这一瓶颈。 核心洞察是:如果一个环境的输出类型(值域)与另一个环境的输入类型(定义域)匹配,它们就能自动融合成一个新的可验证环境——而且这个过程可以递归进行。
[问题:手工环境的线性扩展限制]
     |
     v
[假设:类型兼容的环境可以自动组合]
     |
     v
[方法:RACES递归组合算子]
     |
     v
[证据:在6个未见基准上Qwen-14B提升3.1分(48.2->51.3)]
     |
     v
[结论:组合带来高效、可扩展的强化学习]
增量
一句话: RACES之前,扩展强化学习环境需要线性增加手工环境; RACES之后,环境变成了乐高积木——可以自动组合——用更少的基础积木实现更好的推理泛化。
核心机制
RACES首先构建了一个包含300个基础环境的库。 每个环境都标注了明确的输入类型(定义域)和输出类型(值域)。 例如,一个简单算术环境接受数字(输入),产生和(输出)。 关键点在于,环境组合由这些类型签名驱动。
框架定义了四种组合算子:
SEQUENTIAL(顺序):将一个环境的输出插入另一个环境的输入。PARALLEL(并行):同时运行多个环境,合并输出。SORT(排序):根据评分函数对一组环境的输出排序。SELECT(选择):根据条件从多个环境输出中选择一个。
这些算子可以递归嵌套——组合后的环境本身成为一个新的积木,可以继续被组合。 在强化学习训练中,智能体(LLM)面对这些组合环境,被迫执行多步推理、组合搜索或条件分支——这些模式在单个孤立环境中很少出现。
[基础环境(300)]  --- 类型签名(定义域/值域)
         |
         +-- [算子: SEQUENTIAL] --> 链: env1 -> env2 -> env3
         +-- [算子: PARALLEL]    --> 合并: envA || envB
         +-- [算子: SORT]        --> 按分数排序输出
         +-- [算子: SELECT]      --> 从候选中选择
         |
         v
   [组合环境] (递归,多样的推理模式)
结构比喻:乐高积木。每个基础环境是一块积木,上面有凸点(输入类型),下面有凹槽(输出类型)。
SEQUENTIAL组合就像把一块2x2积木叠在1x1积木上——下面积木的凸点必须匹配上面积木的凹槽。
PARALLEL算子在底板上并排放两块积木,它们的输出被合并(比如求和)。
SORT是一个按大小排序的整理盘。
SELECT是一个过滤器,选出符合颜色或形状条件的积木。
当你搭建一个复杂的模型(组合环境)时,LLM必须穿行整个装配体——每一个接合处强制产生一个推理步骤。
组合结构越多样,LLM学到的推理技能迁移性越强。
关键概念
- 可验证环境: 一种任务,其正确答案可以通过编程方式确定(例如,计算数学表达式的值)。 在强化学习中,它提供自动奖励,无需人工标注。 环境就像一个”电路”,接收输入,执行过程,验证输出。
- 定义域/值域匹配: 想象一个USB数据线:插头(输出类型)必须匹配接口(输入类型)。
在RACES中,每个环境声明自己的输入和输出类型(例如
int -> int,string -> bool)。 只有类型匹配的环境才能通过SEQUENTIAL组合。 这保证了组合的正确性,无需运行时检查。 - 递归组合: 组合后的环境本身也是一个新环境,有自己的定义域和值域。
你可以继续组合组合体:例如
SEQUENTIAL( SEQUENTIAL(A,B), C)。 这使得从少量基础积木出发,复杂度指数级增长——论文显示,50个基础环境产生的训练多样性可以媲美300个手工环境。
框架转变
转变是从手工、原子的环境构建到自动化、组合式的环境生成。
之前(主流方法):              之后(本文方法):
[环境1] [环境2]...[环境300]     [基础A] [基础B] [基础C]
  各自手工构建                       \     |     /
  环境之间无复用                    [算子: SEQ, PAR, SORT, SEL]
  扩展 = 更多手工                     \   |   /
                                    [组合环境]
                                   (对组合体递归)
一句话:从原子化手工构建到类型驱动的递归组合,核心转变是:推理模式的多样性来自少量基元的组合,而不是为每个任务单独设计。
专家评审
选题眼光: 真缺口。 RL+可验证环境这一路线当前很热门(如DeepSeek-R1, AlphaProof),手工扩展的限制确实存在。 作者瞄准的是一个结构性的效率瓶颈,而非人为制造的问题。
方法成熟度: 巧劲而非蛮力。 类型匹配的洞察一旦说出就很简单;主要工程在于定义组合算子和维护300个基础环境。 可能还有更简单的方法(例如随机拼接问题而不做类型检查),但带显式类型的递归组合保证了正确性并实现了多样化的推理模式。 该方法可靠且实用。
实验诚意: 基线看似公平——他们将RACES(在组合环境上训练)与标准RL(在单个环境上训练)进行了比较。 在6个未见基准上,RACES有明确提升。 但我希望看到更多细节:两种条件的训练步数和计算资源是否相同? 论文声称50个基础环境达到300个手工环境的性能——这一指标有价值,但需要验证实际计算成本,而非仅环境数量。 没有明显的危险信号,但可复现性取决于环境库是否公开。
写作功力: 清晰且结构良好。 乐高比喻用得很好。 实验部分有改进空间:可以更详细解释为什么选择这4种算子,并增加消融实验(例如只用SEQUENTIAL会如何)。 另外,相关工作部分较薄弱——多一些引用能更好地定位该贡献。
判决: 弱接收——一个实用、执行良好的贡献,推进了RL for LLM推理的工具集。 它不是一个理论突破,但它用一个简单、可复用的想法解决了一个即时的工程瓶颈。
要点总结
- 为你的任务定义类型签名:无论你是在构建RL环境、机器人控制序列还是数据流水线,显式的输入/输出类型匹配都能解锁自动组合。
- 使用少量通用组合算子:SEQUENTIAL、PARALLEL、SORT、SELECT覆盖了多种推理模式。 你很可能能将类似的算子应用到任何涉及多步处理的领域。
- 递归放大多样性:即使只有少数几个基础积木,递归组合也能生成组合级的训练样例——这是一个超越本论文的通用原则(例如,可以用于课程学习或自动化提示工程)。