Paper: 2608.12282 Authors: Ankita Rajaram Naik, Anupama Murthi, Benjamin Elder, Siyu Huo, Raavi Gupta, Abhinav Jain, Praveen Venkateswaran, Abdulhamid Adebayo, Danish Contractor Categories: cs.AI
The Gap
Agent evaluation has quietly split into two disjoint literatures. On one side, tool-use benchmarks (BFCL-style function-calling suites, API-Bank, ToolBench, NESTFUL, AppWorld, ToolSandbox) ask: given a user request and a set of schemas, does the model emit the right call with the right arguments? On the other side, multi-hop retrieval benchmarks (HotpotQA, MuSiQue, MultiHop-RAG, FRAMES) ask: given a document collection, can the model chain evidence across passages? A third, smaller strand — τ-bench and its descendants — adds policy compliance, but typically in one or two hand-built domains (retail, airline).
The enterprise agent nobody has been benchmarking is the one that needs all three at once: pull a customer record from a CRM API, cross-reference it against a policy document written in prose, discover the request is not permitted, and say so. Each existing benchmark, by construction, hands the agent one modality and removes the ambiguity that comes from having to decide where an answer lives.
There’s a second, more technical gap: grading. Most tool benchmarks compare against a single gold trajectory or gold call string, which punishes an agent for finding a different-but-valid route through the API surface. Most RAG benchmarks compare answer strings or use an LLM judge, which is noisy and blind to whether the agent actually did the work.
VAKRA’s bet is that if you close both gaps — one environment, execution-based grading — the failure profile that emerges won’t be about tool-calling mechanics at all.
PROBLEM: an enterprise agent needs APIs + docs + prose rules at once
   |
   +-- prior line A: tool-call benches .... APIs only  [gold call string]
   +-- prior line B: multi-hop RAG ........ docs only  [string / judge]
   +-- prior line C: policy sims .......... 1-2 domains [narrow]
   |
   v
ASSUMPTION: the bottleneck is language-mediated glue
            (which entity / which source / which rule)
            not the mechanics of emitting a well-formed call
   |
   v
METHOD: one live environment
        8000+ executable APIs across 62 domains
        + document corpus + natural-language tool-use policies
        3 settings of rising difficulty
        graded by RE-EXECUTION so many valid paths count
   |
   v
EVIDENCE: best model 70.4 on single-hop endpoint-style
          50-51 on compositional APIs
          > 50 pct relative drop as hop depth grows
          as low as 2.4 on unanswerable-under-policy
   |
   v
CONCLUSION: errors concentrate at entity disambiguation
            and cross-source grounding
            == more tools and better schemas do not fix this
The Increment
One sentence: Before this paper, you could report that your model was good at calling tools *and good at multi-hop retrieval and nobody could check whether it was good at doing both in the same breath under rules it had to read; after it, there’s a single executable environment where that composite skill is measured and the answer is “much worse than you’d guess.”
Core Mechanism
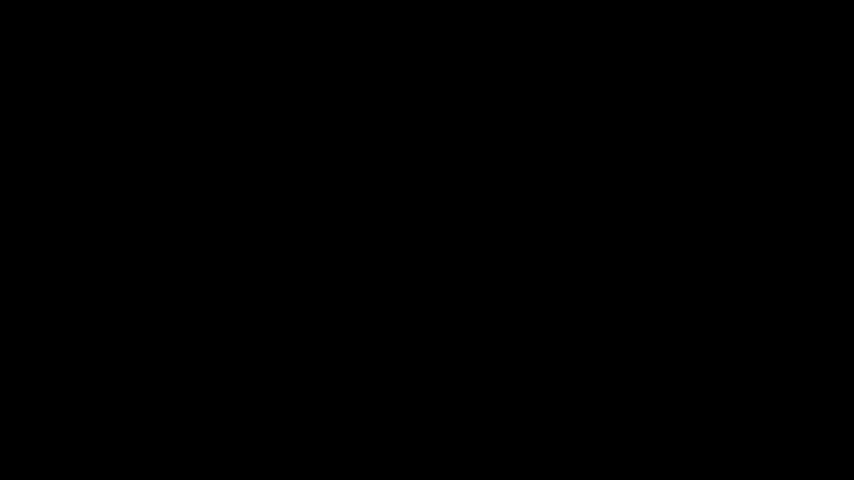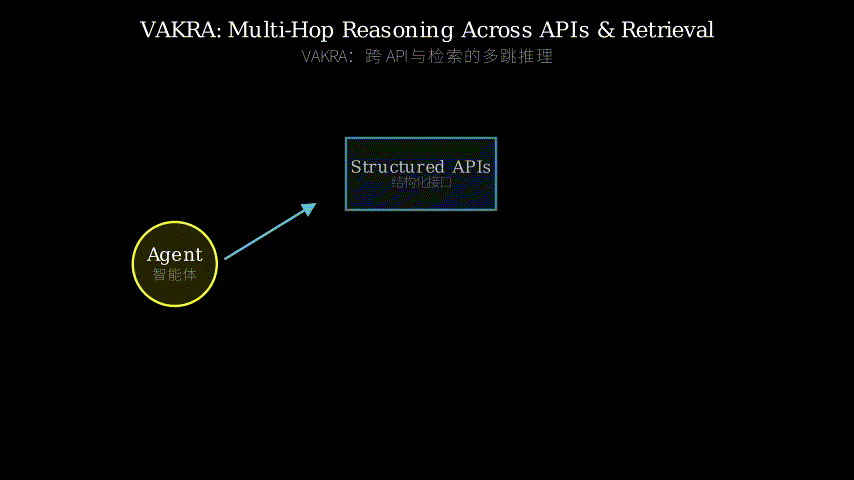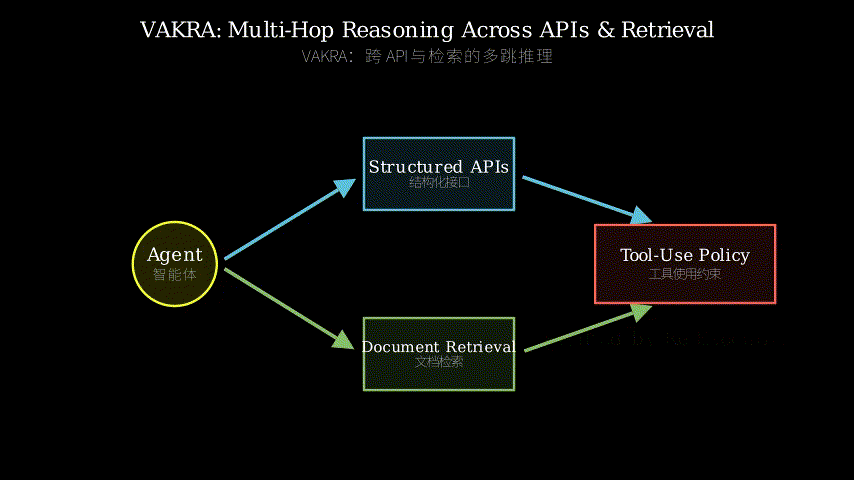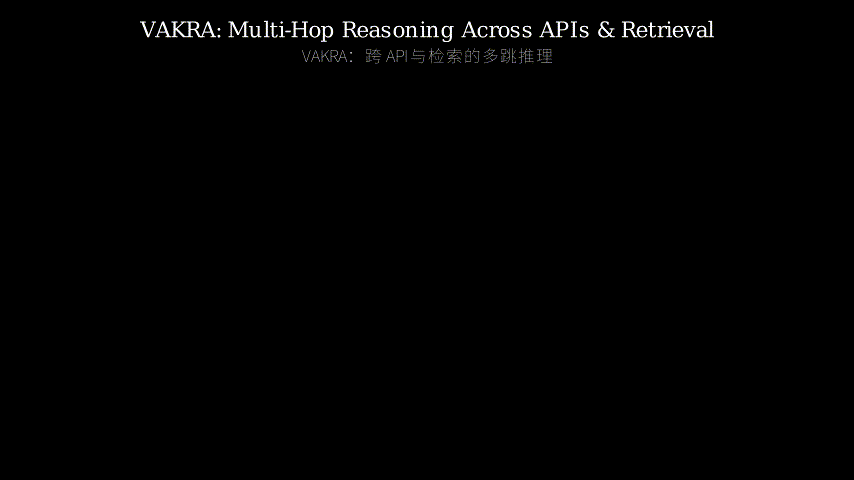
VAKRA is three things stacked. The base layer is a large executable API surface — over 8,000 endpoints spanning 62 domains — plus a document corpus and a set of tool-use policies expressed in natural language rather than code (“do not issue a refund without checking eligibility first,” “if the account is not found, do not infer it from the name”). Sitting on top is a task suite organized into three settings of increasing difficulty: (S1) single-hop calls that probe API interaction style, notably the difference between narrow endpoint-style APIs and compositional ones; (S2) multi-hop chains where the output of one call is the input to the next; (S3) multi-source tasks that require reading documents and APIs together while obeying the stated policies — including queries that are deliberately unanswerable or forbidden, where the correct behavior is refusal or escalation.
The evaluation layer is the piece worth stealing. Instead of comparing the predicted trajectory to a reference trajectory, VAKRA takes the agent’s predicted tool calls and re-executes them against the live APIs, then compares the resulting observable outcome to the reference outcome. Two different call sequences that reach the same end state both get credit. This dissolves the perennial complaint about tool benchmarks — that they reward memorizing one canonical path — and turns correctness into something closer to an integration test than a string match.
The third choice is methodological: every model runs inside the same fixed ReAct loop (thought, action, observation, repeat). No per-model scaffolding, no bespoke planners, no retry policies tuned per system. The claim is that this isolates model capability from agent architecture. It also means the absolute numbers are a floor, not a ceiling — more on that below.
        [ task generator ]
               |
   +-----------+-------------+
   |           |             |
[ APIs ]   [ doc corpus ] [ policy text ]
 8000+        prose         prose rules
 62 domains
   |           |             |
   +-----------+-------------+
               |
        [ query + setting ]
      S1 interaction styles ..... endpoint vs compositional
      S2 multi-hop over APIs .... depth 2 3 4 ...
      S3 multi-source + policy .. incl. unanswerable
               |
               v
      [ fixed ReAct harness ]
       thought -> action -> observation
               ^        |
               +--loop--+
               |
               v
      [ predicted tool calls ]
               |
               v
   [ RE-EXECUTE against live APIs ]
               |
        compare observable outcome vs reference
               |
        +------+-------+
        |              |
     [ match ]     [ mismatch ] -> trace triage:
      credit                       . wrong entity picked
      any valid path                . wrong source consulted
                                    . policy ignored
                                    . malformed call  (rare)
Think of it as the first week of a new hire at a large company, and every part maps.
The 8,000 APIs across 62 domains are the company’s internal systems — HR portal, inventory, billing, ticketing — far more than any one person has seen. Endpoint-style APIs are the single-purpose forms where one button does one thing; compositional APIs are the multi-tab workflows where you must assemble the request yourself. The document corpus is the shared drive and the wiki. The policy text is the employee handbook: prose, not a config file, and it sometimes forbids the obvious shortcut. Multi-hop tasks are the ones where you can’t look up an employee’s manager until you’ve first found their employee ID.
The unanswerable queries are the trap requests every new hire gets — a manager asks for a number that simply isn’t in any system, and the right answer is “I can’t get that,” not a confidently fabricated figure. And the grading is what a good manager actually does: they don’t read your notes to see whether you followed the documented procedure, they re-run your steps and check whether the end state is right. Any route that lands correctly counts. Finally, the fixed ReAct harness is everyone getting the same laptop with the same software — no bringing your own macros — so the review compares people, not tooling.
The paper’s punchline in this metaphor: the new hires can all fill in forms correctly. They fail because they look up the wrong Jane Smith, or they answer from the wiki when the wiki is stale and the API is authoritative, or they never open the handbook.
Key Concepts
-
Endpoint-style vs compositional APIs: Two ways to expose the same functionality. An endpoint-style API gives you
getOrderStatus(order_id)— one call, one answer, the server did the thinking. A compositional API gives youqueryTable(table, filters, join, projection)— powerful, but *you have to know that order status lives in tableORD_HDR, joins toSHIP_EVTonorder_key, and that the status you want is the max timestamp row. Same task, radically different burden on the caller. VAKRA finds the gap is roughly 20 points (70.4 to 50-51) for the best model, which tells you something concrete: if you’re designing an API surface for agents to consume, agent-shaped endpoints buy you accuracy that no prompt engineering will recover. -
Execution-based verification with path equivalence: Suppose the task is “cancel the most recent order for user X.” One agent calls
listOrders(user=X), sorts, thencancel(id). Another callsgetLatestOrder(user=X)thencancel(id). Trajectory matching marks one wrong; VAKRA re-runs both and observes the same order got cancelled, so both are right. The subtlety is that this only works cleanly when the environment can be reset and outcomes are observable — which constrains how state-changing APIs can be designed and is the part of the paper I’d most want to see spelled out. -
Unanswerability under policy: There are two distinct reasons an agent should decline. *Epistemic: the information doesn’t exist in any available source. Deontic: the information exists but the handbook forbids this route to it — say, retrieving salary data without an approval token. Both require the model to notice an absence, which is much harder than noticing a presence: nothing in the context screams “stop.” A 2.4% score here means models essentially always find something to say. For anyone shipping an agent, this is the number that should keep you up at night, because in production the fabricated answer is the expensive failure mode, not the missing one.
Framework Shift
Before (mainstream approach):        After (this paper):

 [ tool-use bench ]                  [ one environment ]
   APIs only                          APIs + docs + handbook
   one gold call string                       |
       |                                      v
   exact match                        agent plans and calls
       |                                      |
   score A                                    v
                                      RE-RUN those calls
 [ multi-hop RAG bench ]                      |
   docs only                                  v
   one gold answer string             compare END STATE
       |                              any working path counts
   F1 or LLM judge                            |
       |                                      v
   score B                            one score + trace triage
                                      . mechanics errors  (few)
 two leaderboards                     . entity errors     (many)
 no rules to obey                     . grounding errors  (many)
 refusal rarely scored                . policy errors     (many)
                                      refusal is a scored answer
From can the model produce the right call to can the model decide which world the answer lives in and whether it is allowed to go there, the core shift is that correctness moves from the syntax of the action to the semantics of the choice.
Expert Assessment
Problem choice: The gap is real, not manufactured. Anyone who has built an enterprise agent knows the failure mode: structured systems and prose knowledge coexist, and the agent’s job is largely arbitration between them. That said, “unified benchmark that merges subfield X and subfield Y” is a crowded and somewhat safe genre in 2026, and the API-scale claim (8,000 endpoints, 62 domains) is the least interesting axis — breadth is cheap when APIs are generated. The genuinely differentiated contribution is the policy-constrained and unanswerable slice. I’d have led with that.
Method maturity: Mostly careful engineering rather than a new idea. Execution-based grading with path equivalence is inherited from the AppWorld / ToolSandbox lineage; the compositional-vs-endpoint contrast is a nice, sharp experimental design choice that costs nothing and yields the paper’s most actionable finding. The overlooked simpler alternative is scale: 100 realistic APIs from actual enterprise systems would likely support the same conclusions with far more external validity than 8,000 synthetic ones. Synthetic API surfaces have a characteristic flatness — naming is too consistent, schemas too regular, documentation too complete — that makes disambiguation both easier (uniform conventions) and harder (near-duplicate endpoints) than reality in ways that don’t cancel out.
Experimental integrity: The fixed-ReAct decision is defensible and clearly stated, but it does real work on the headline numbers. Models trained hard on native function-calling APIs behave differently when squeezed into a text-based ReAct loop, so the ranking may partly measure ReAct-compatibility rather than agentic capability. The 2.4% on unanswerable queries is the number I trust least: abstention rates are notoriously sensitive to system-prompt phrasing, and a single sentence like “if the required information is unavailable, say so explicitly” can move this metric by tens of points. Without a prompt-sensitivity ablation, that figure is a property of the harness as much as of the models. Two more things I’d want and don’t see in the abstract: a human or expert-agent baseline to establish the ceiling, and a discussion of how re-execution handles non-idempotent, state-mutating calls. The claim that failures are language-mediated rather than mechanical is credible and matches my own experience, but it rests on a trace analysis whose taxonomy and inter-annotator agreement need to be visible.
Writing quality: The abstract is disciplined — concrete numbers, no overclaiming about “solving” anything. The corner-cutting is almost certainly in two places: API provenance (how the 8,000 endpoints were generated and validated, and how realistic they are) and the trace taxonomy. The trace analysis is the paper’s intellectual payload — it’s the difference between “here is another leaderboard” and “here is where to spend your research effort” — and in benchmark papers that section is habitually compressed into half a page of pie charts. Rewriting it with worked failure examples, per-category counts, and honest annotation methodology would lift the whole paper a tier.
Verdict: weak accept — a well-constructed and genuinely needed environment whose most quotable numbers are more harness-dependent than the framing admits, but whose diagnostic finding (failures are semantic, not syntactic) is worth having on the record with evidence behind it.
Takeaways
Concrete things to steal:
-
Grade agents by re-execution, not trajectory match. If you’re building internal evals, stop maintaining gold call sequences. Snapshot the environment, run the agent, re-run its calls, diff the observable end state. Your eval stops rejecting correct-but-different solutions and stops needing an update every time you refactor an endpoint.
-
Design agent-shaped endpoints. The 20-point endpoint-vs-compositional gap is a product decision disguised as a benchmark result. If your agent is hitting a generic query interface or a raw SQL-ish surface, you’re paying a large accuracy tax. Wrapping the top twenty task-level operations as first-class endpoints is cheaper than any model upgrade.
-
Split your failure taxonomy along the mechanics/semantics line. Instrument your traces to distinguish malformed calls, wrong-entity selections, wrong-source selections, and policy violations. The paper’s finding is that the first bucket is nearly empty and the rest are full — which means schema polish and JSON-mode fixes have hit diminishing returns, and your effort belongs in disambiguation (ask the user which Jane Smith) and source arbitration (declare which source is authoritative for which field).
-
Make abstention a first-class, separately scored metric — and prompt for it explicitly. Any eval suite without an unanswerable subset is measuring only half the safety-relevant behavior. Corollary from my own skepticism above: since abstention is so prompt-sensitive, that’s also good news operationally — it’s one of the cheapest fixes available to you, and you should ablate it before believing any published abstention number about your model.
-
Fix your harness when comparing models; vary it when forecasting product quality. Conflating the two is how teams end up choosing a model on ReAct-loop numbers and then shipping it in a native-function-calling pipeline where the ranking inverts.
论文: 2608.12282 作者: Ankita Rajaram Naik, Anupama Murthi, Benjamin Elder, Siyu Huo, Raavi Gupta, Abhinav Jain, Praveen Venkateswaran, Abdulhamid Adebayo, Danish Contractor 分类: cs.AI
缺口
智能体评测已经悄然分裂成两条互不相交的文献线。
一边是工具调用类基准(BFCL 系列、API-Bank、ToolBench、NESTFUL、AppWorld、ToolSandbox):给定用户请求和一堆 schema,模型能不能吐出参数正确的那次调用。
另一边是多跳检索类基准(HotpotQA、MuSiQue、MultiHop-RAG、FRAMES):给定文档集合,模型能不能跨段落串联证据。
还有一条较小的支线,τ-bench 及其后继,加入了策略遵从,但通常只在一两个手工构造的领域里(零售、航空)。
真正没人测的,恰恰是企业里那种智能体:它必须同时干这三件事——从 CRM API 取客户记录,对照一份用散文写成的政策文档,发现这个请求其实不被允许,然后如实说出来。
现有基准的构造方式,本质上都是先把模态收窄到一个,从而消除了「答案到底住在哪里」这个歧义。
还有第二个更技术性的缺口:判分。
大多数工具基准拿单一黄金轨迹或黄金调用字符串比对,于是智能体只要走了另一条同样正确的路,就要挨罚。
大多数 RAG 基准比答案字符串或用 LLM 当裁判,噪声大,而且完全看不见智能体是否真的干了活。
VAKRA 的赌注是:如果把这两个缺口一起补上——一个统一环境、执行式判分——浮现出来的错误画像根本不在工具调用机制上。
PROBLEM: 企业智能体要同时用 APIs + 文档 + 散文规则
   |
   +-- 前人 A: 工具调用基准 ... 只有 API   [黄金调用串]
   +-- 前人 B: 多跳 RAG ....... 只有文档   [字符串 / 裁判]
   +-- 前人 C: 策略模拟 ....... 1-2 个领域 [太窄]
   |
   v
ASSUMPTION: 瓶颈在语言层面的粘合
            (选哪个实体 / 查哪个来源 / 守哪条规则)
            而不是把一次调用写得合法
   |
   v
METHOD: 一个可执行环境
        62 个领域 8000+ 个真实可跑的 API
        + 文档语料 + 自然语言工具使用策略
        3 档递增难度
        用 RE-EXECUTION 判分 == 多条有效路径都算对
   |
   v
EVIDENCE: 最好模型 单跳 endpoint 式 70.4
          组合式 API 50-51
          跳数增加相对下降 > 50 pct
          策略下的不可答问题 低至 2.4
   |
   v
CONCLUSION: 错误集中在实体消歧与跨源接地
            == 堆更多工具 修更好 schema 都治不了
增量
一句话:在这篇论文之前,你可以同时宣称模型「工具调用很强」和「多跳检索很强」,却没人能验证它在同一口气里、还要读懂规则的情况下到底行不行;在它之后,有了一个可执行环境专门量这项复合能力,答案是「比你猜的差得多」。
核心机制
VAKRA 是三层叠起来的。
底层是一个大规模可执行 API 面:62 个领域、8000 多个端点,加上一个文档语料,再加一组用自然语言而非代码写的工具使用策略(「未查资格前不得发起退款」、「账户查不到时不得凭姓名推断」)。
上面架着三档难度递增的任务:S1 单跳调用,专门探测 API 交互风格,重点是窄口径 endpoint 式 API 与组合式 API 的差别;S2 多跳链条,前一次调用的输出是后一次的输入;S3 多源任务,必须同时读文档和调 API,并遵守写明的策略——其中故意混入不可答或被禁止的问题,正确行为是拒答或上报。
最值得偷的是判分层。
它不拿预测轨迹去对齐参考轨迹,而是把智能体预测出的工具调用在活的 API 上重新执行一遍,然后比较可观测的结果与参考结果。
两条不同的调用序列只要落到同一个终态,都给分。
这一下就化解了工具基准的那个老毛病——只奖励背下唯一正确路径——并把「正确性」变成了更接近集成测试的东西,而不是字符串匹配。
第三个选择是方法论上的:所有模型都跑在同一个固定 ReAct 循环里(思考、行动、观察、再循环)。
没有针对单个模型的脚手架,没有定制 planner,没有逐系统调过的重试策略。
作者的主张是这样能把模型能力从智能体架构中隔离出来。
代价是绝对数字变成了下界而非上界——下面细说。
        [ 任务生成器 ]
               |
   +-----------+-------------+
   |           |             |
[ APIs ]   [ 文档语料 ]  [ 策略文本 ]
 8000+       散文           散文规则
 62 领域
   |           |             |
   +-----------+-------------+
               |
        [ 问题 + 难度档 ]
      S1 交互风格 ....... endpoint 对 组合式
      S2 API 多跳 ....... 深度 2 3 4 ...
      S3 多源 + 策略 .... 含不可答
               |
               v
      [ 固定 ReAct 外壳 ]
       thought -> action -> observation
               ^        |
               +--loop--+
               |
               v
      [ 预测出的工具调用 ]
               |
               v
   [ 在活 API 上 RE-EXECUTE ]
               |
        比较可观测终态 vs 参考终态
               |
        +------+-------+
        |              |
     [ 一致 ]      [ 不一致 ] -> 轨迹归因:
      给分                        . 实体选错
      任何有效路径                . 来源选错
                                  . 策略被无视
                                  . 调用写坏  (少见)
把它想成大公司新员工的第一周,每个零件都能对上。
62 个领域 8000 个 API 就是公司的内部系统——HR 门户、库存、账务、工单——多到没有任何一个人全见过。
endpoint 式 API 是那种一个按钮干一件事的单一用途表单;组合式 API 是多标签页工作流,请求要你自己拼。
文档语料是共享盘和 wiki。
策略文本是员工手册:散文写的,不是配置文件,而且它时不时就禁掉那条最顺手的捷径。
多跳任务就是那种「查不到工号就查不到他的主管」的活。
不可答问题是每个新人都会碰上的坑:主管张口要一个任何系统里都没有的数字,正确答案是「我拿不到」,不是自信地编一个。
判分方式正是一个好主管真正会做的事:他不会读你的笔记看你有没有按流程走,他会把你的步骤重跑一遍,看终态对不对。
任何落对的路线都算过关。
最后,固定 ReAct 外壳就是所有人用同一台笔记本、同一套软件——不许自带宏——这样考评比的是人,不是工具。
论文的笑点落在这个比喻里就是:新人们填表都填得挺对。
他们栽在查错了那个「张伟」,栽在 wiki 已经过期而 API 才是权威时却去信了 wiki,栽在压根没翻开员工手册。
关键概念
-
endpoint 式 API 对 组合式 API:同一份能力的两种暴露方式。
endpoint 式给你
getOrderStatus(order_id)——一次调用一个答案,思考在服务端做完了。组合式给你
queryTable(table, filters, join, projection)——很强,但你得自己知道订单状态在ORD_HDR表、按order_key连到SHIP_EVT、你要的状态是时间戳最大那一行。同一个任务,调用方的负担天差地别。
VAKRA 测出最强模型这里差约 20 分(70.4 掉到 50-51),这给出一条很具体的结论:如果你在为智能体设计 API 面,做成智能体形状的端点能换来的准确率,靠提示工程是补不回来的。
-
带路径等价的执行式验证:假设任务是「取消用户 X 最近的一笔订单」。
一个智能体调
listOrders(user=X)、排序、再cancel(id);另一个调getLatestOrder(user=X)再cancel(id)。轨迹匹配会判其中一个错;VAKRA 把两条都重跑,观察到取消的是同一笔订单,于是都算对。
微妙之处在于:这只有在环境可重置、结果可观测时才干净成立——这反过来约束了改状态的 API 该怎么设计,也是我最想看论文把细节讲清楚的地方。
-
策略下的不可答性:智能体该拒答有两种截然不同的理由。
认知性:任何可用来源里都不存在这个信息。
规范性:信息存在,但手册禁止走这条路——比如没有审批令牌就不许取薪酬数据。
两者都要求模型注意到一种「缺席」,这比注意到「在场」难得多:上下文里没有任何东西会喊「停」。
2.4% 意味着模型几乎总能找出点什么来说。
对任何要把智能体推上生产线的人,这才是该让你睡不着的数字——线上真正贵的失败是编出来的答案,不是缺掉的答案。
框架转变
之前(主流方法):                之后(本文方法):

 [ 工具调用基准 ]                  [ 一个统一环境 ]
   只有 API                         API + 文档 + 手册
   唯一黄金调用串                          |
       |                                   v
   精确匹配                          智能体规划并调用
       |                                   |
   分数 A                                  v
                                    把这些调用重跑一遍
 [ 多跳 RAG 基准 ]                         |
   只有文档                                v
   唯一黄金答案串                    比较 终 态
       |                            任何跑得通的路都算
   F1 或 LLM 裁判                          |
       |                                   v
   分数 B                            一个分数 + 轨迹归因
                                     . 机制类错误  (很少)
 两个排行榜                          . 实体类错误  (很多)
 没有规则要守                        . 接地类错误  (很多)
 拒答几乎不计分                      . 策略类错误  (很多)
                                     拒答本身是要判分的答案
一句话:从「模型能不能产出正确的调用」到「模型能不能判断答案住在哪个世界、以及它是否被允许过去」,核心转变是正确性从动作的语法搬到了选择的语义。
专家评审
选题眼光:缺口是真的,不是造出来的。
任何搭过企业智能体的人都熟悉那个失败模式:结构化系统和散文知识并存,智能体的活儿大半就是在两者之间做仲裁。
但也得说,「把子领域 X 和子领域 Y 合成一个统一基准」在 2026 年是个拥挤且偏安全的体裁,而 API 规模那条(8000 端点、62 领域)恰恰是最不有趣的一维——当 API 是生成的,广度很便宜。
真正有区分度的贡献是策略约束与不可答那一块。换我会把它放在最前面讲。
方法成熟度:更多是扎实工程,不是新想法。
带路径等价的执行式判分继承自 AppWorld / ToolSandbox 一脉;endpoint 对组合式的对照是个很漂亮、很锋利的实验设计,成本为零,却给出了全文最可操作的发现。
被忽略的更简单方案恰恰是「减少规模」:从真实企业系统里取 100 个 API,很可能支撑同样的结论,而外部效度远高于 8000 个合成的。
合成 API 面有一种特征性的「过于平整」——命名太一致、schema 太规整、文档太完整——这会让消歧同时变容易(约定统一)和变难(近重复端点),且两者并不互相抵消。
实验诚意:固定 ReAct 这个决定站得住,也说明白了,但它对头条数字的影响是实打实的。
那些在原生 function calling 上重训过的模型,被塞进纯文本 ReAct 循环时表现会不一样,所以排名可能部分在量「ReAct 兼容性」而不是智能体能力。
我最不信的数字是不可答那 2.4%:拒答率对系统提示的措辞出名地敏感,一句「若所需信息不可得请明确说明」就可能把这个指标拉动几十分。
没有提示敏感性消融,这个数字是外壳的属性和模型的属性各占一半。
摘要里还看不到、但我很想要的两样:一个人类或专家智能体基线来确立上界;以及重放判分怎么处理非幂等、会改状态的调用。
「失败是语言中介的而非机制性的」这个论断可信,也和我自己的经验相符,但它压在一份轨迹分析上——那份分析的错误类别定义和标注者一致性必须摆出来。
写作功力:摘要很克制——给具体数字,不吹「解决了」什么。
偷懒几乎必然在两处:API 的来源与验证(8000 个端点怎么生成、怎么校验、有多真实),以及轨迹错误分类法。
轨迹分析是全文的智力载荷——它决定这篇是「又一个排行榜」还是「告诉你研究力气该往哪儿花」——而基准类论文的习惯是把这节压缩成半页饼图。
把它重写成带完整失败样例、逐类别计数、诚实标注方法学的一节,能让整篇论文升一档。
判决:弱接收 —— 环境构造扎实且确实是领域需要的,但最好引用的那几个数字对外壳的依赖比论文框架承认的更强;不过它的诊断性发现(失败在语义而不在语法)值得带着证据被记录下来。
要点总结
可以直接偷走的东西:
-
用重放执行判分,别用轨迹匹配。 在做内部 eval 的话,别再维护黄金调用序列了。
快照环境、跑智能体、重放它的调用、diff 可观测终态。
你的 eval 从此不再误杀「对但不同」的解,也不用每次重构端点就跟着改一遍。
-
设计智能体形状的端点。 endpoint 对组合式那 20 分差距,是一个伪装成基准结果的产品决策。
如果你的智能体在打通用查询接口或裸 SQL 式接口,你正在交一笔很重的准确率税。
把最常用的二十个任务级操作包成一等端点,比任何模型升级都便宜。
-
让错误分类沿「机制 / 语义」这条线劈开。 给轨迹打点,区分调用写坏、实体选错、来源选错、策略违反四类。
本文的发现是第一类几乎为空,后三类全满——这意味着修 schema、修 JSON mode 已经边际收益递减,力气该花在消歧(直接问用户是哪个张伟)和来源仲裁(明确宣告哪个字段以哪个来源为权威)。
-
把拒答做成一等、单独计分的指标——并且在提示里显式要求它。 任何没有不可答子集的 eval,只测了安全相关行为的一半。
顺着我上面的怀疑还有一条推论:正因为拒答对提示极其敏感,这在工程上是好消息——它是你手上最便宜的修法之一,而且在相信任何已发表的拒答数字之前,先自己做一遍消融。
-
比模型时锁死外壳,预测产品质量时才去变外壳。 把这两件事混在一起,团队就会用 ReAct 循环的数字选出一个模型,然后把它塞进原生 function calling 流水线,发现排名反过来了。