Paper: 2605.30343 Authors: Lukas Aichberger, Sepp Hochreiter Categories: cs.CL, cs.AI
The Gap
Current methods scale test-time reasoning by generating intermediate tokens—chain-of-thought prompting, self-consistency, tree search over reasoning paths. This works, but it conflates two distinct activities: internal computation (figuring out the answer) and external communication (showing your work). Every reasoning step burns autoregressive generation cost. The model must “think out loud” even when the intermediate steps add no value to the final answer.
Prior latent reasoning attempts (hidden states, learned embeddings) struggled because they lacked a training curriculum to ground the latent representations. The gap: no method successfully decouples reasoning from token generation while maintaining competitive performance.
Problem: Reasoning = Autoregressive Generation
   |
   v
Assumption: LLMs have latent working memory capacity
   |
   v
Method: Fixed memory blocks + two-stage curriculum
   |
   v
Evidence: Matches CoT performance, 1 forward pass vs N
   |
   v
Conclusion: Reasoning can be internalized without generation
The Increment
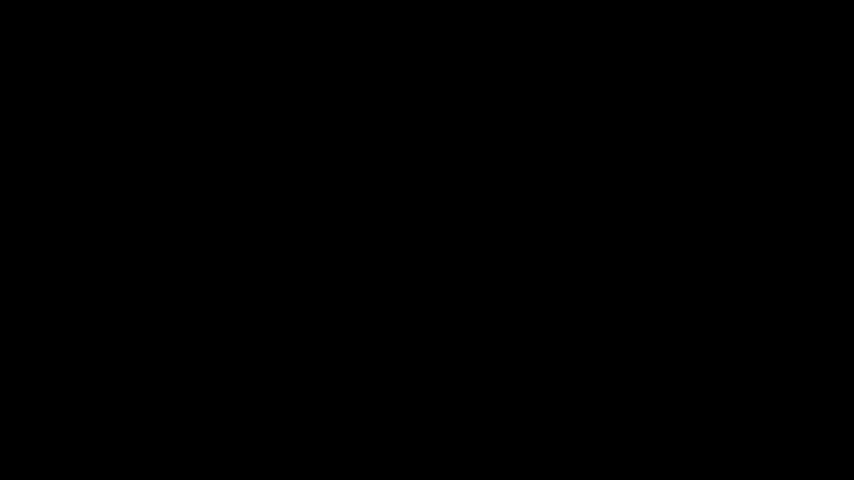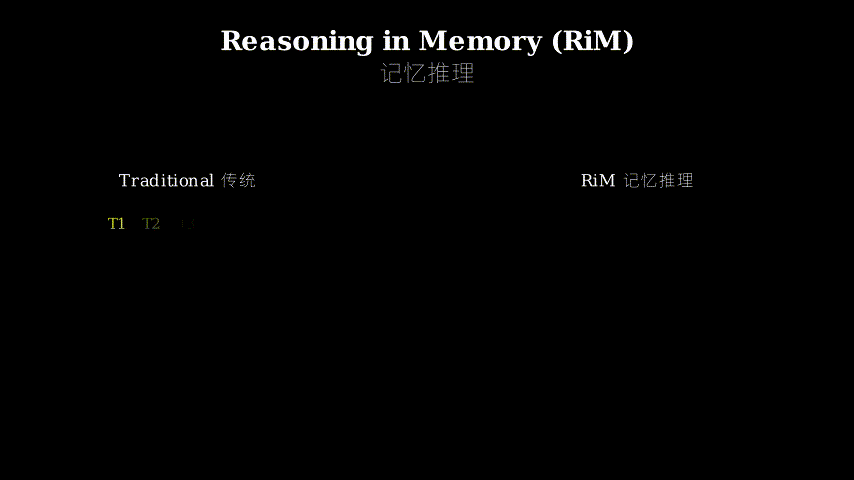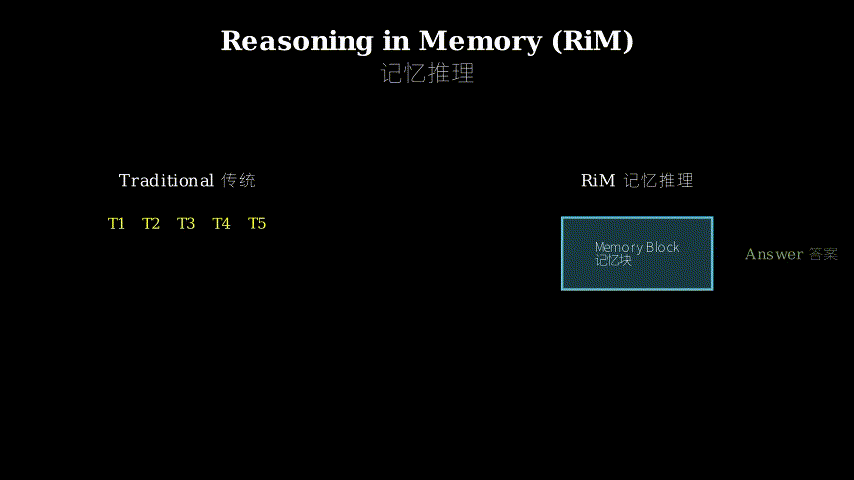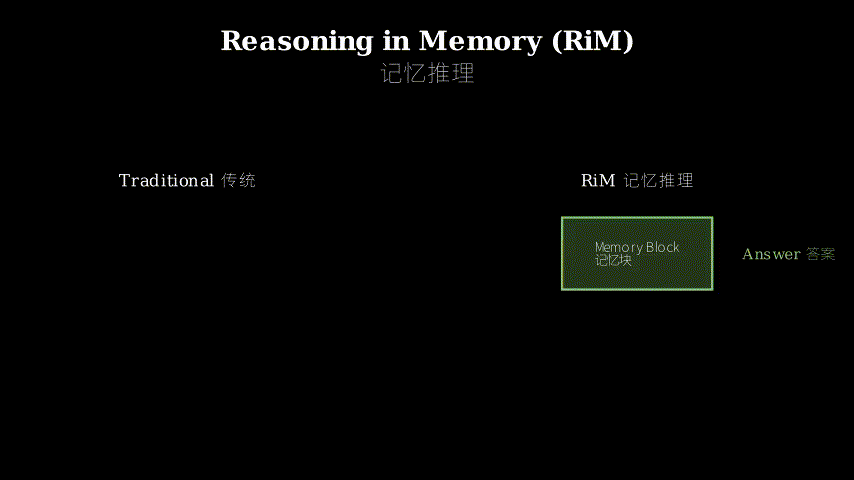
One sentence: Before—reasoning required generating O(N) intermediate tokens autoregressively; after—reasoning happens in fixed memory blocks processed in O(1) forward pass.
Core Mechanism
RiM introduces memory blocks: fixed sequences of special tokens (e.g., <mem1>, <mem2>, …, <mem32>) inserted between the question and answer. These aren’t generated—they’re prepended to the input. The model processes them in a single forward pass, using them as scratch space for internal computation.
Training happens in two stages. Stage 1 (grounding): After each memory block, the model predicts an explicit reasoning step (like chain-of-thought). This teaches the model to use memory blocks for structured thinking. Stage 2 (refinement): Drop the intermediate supervision. After each memory block, the model predicts the final answer. Early blocks produce rough answers; later blocks refine them. The model learns to iteratively improve its answer using memory as working space.
Input:  [Question] <mem1> <mem2> ... <mem32> [Answer]
         |          |      |           |        |
         v          v      v           v        v
Stage 1: Q ------> Step1  Step2  ...  StepN -> A
         (ground memory blocks to explicit reasoning)

Stage 2: Q ------> Ans1   Ans2   ...  AnsN  -> A
         (refine answer iteratively, no intermediate steps)
Think of it like a student solving a math problem on scratch paper. Traditional chain-of-thought is like narrating every calculation out loud—“first I multiply 7 by 3, which gives 21, then I add 5…”—expensive and slow. RiM is like working silently on scratch paper, showing only the final answer. The memory blocks are the scratch paper: fixed space where the model can scribble intermediate thoughts without the cost of generating them token-by-token. Stage 1 teaches the student how to use scratch paper (by checking their work at each step). Stage 2 lets them work freely, only checking the final answer.
Key Concepts
-
Working Memory vs Communication: Human cognition separates internal manipulation (working memory) from external expression (speech). You can solve “17 × 23” in your head without verbalizing every step. LLMs traditionally lack this separation—every computation must be externalized as tokens. RiM introduces the separation by giving models a fixed internal workspace (memory blocks) distinct from the output stream. The model learns to “think” in memory blocks and “speak” only the final answer.
-
Curriculum Grounding: You can’t just tell a model “use these special tokens for reasoning”—it has no prior about what they mean. Stage 1 grounds them by forcing the model to predict explicit reasoning steps after each memory block. This creates a bridge: memory blocks → reasoning steps → answer. Once grounded, Stage 2 removes the bridge (no more intermediate steps) but the model retains the learned association between memory blocks and structured reasoning. It’s like training wheels: necessary at first, removed once the skill is internalized.
-
Iterative Refinement: Instead of generating a single reasoning chain, RiM predicts the final answer multiple times—once after each memory block. Early predictions are rough; later ones incorporate more computation. This mirrors how humans refine answers: first approximation, then correction, then polish. The loss function penalizes all intermediate answers, so the model learns to use each memory block to improve on the previous attempt.
Framework Shift
Before (Chain-of-Thought):          After (RiM):

Q --> [Generate] --> Step1          Q + <mem1><mem2>...<memN>
      [Generate] --> Step2            |
      [Generate] --> Step3            v
      [Generate] --> StepN          [Single Forward Pass]
      [Generate] --> Answer           |
                                      v
(N autoregressive steps)            Answer

Cost: O(N) generation               Cost: O(1) forward pass
Reasoning: externalized             Reasoning: internalized
From sequential generation to parallel processing, the core shift is decoupling computation from communication.
Expert Assessment
Problem choice: Real gap. Test-time compute scaling is a hot topic (o1, self-consistency, tree search), but all current methods pay the autoregressive tax. Decoupling reasoning from generation is a natural next step, though prior attempts (learned embeddings, hidden state manipulation) failed to gain traction. This paper’s timing is good—it addresses a bottleneck in a high-value area.
Method maturity: The two-stage curriculum is clever and well-motivated. Stage 1 solves the grounding problem that plagued earlier latent reasoning work. Stage 2’s iterative refinement is elegant—it reuses the same mechanism (predict answer after each block) rather than introducing new components. However, the method is somewhat brute-force: fixed memory blocks of arbitrary length (32 tokens) with no learned allocation. A more sophisticated approach might dynamically allocate memory or learn when to stop refining. The paper doesn’t explore these directions.
Experimental integrity: Baselines are fair—CoT, self-consistency, and prior latent methods. Results show RiM matches or slightly exceeds CoT on GSM8K, MATH, and ARC while using one forward pass instead of N. The ablations are thorough (varying memory block count, comparing stage 1 vs stage 2). One concern: the experiments use relatively small models (up to 7B parameters). It’s unclear whether the method scales to frontier models (70B+) where autoregressive cost matters most. The paper also doesn’t report wall-clock time comparisons—“one forward pass” sounds fast, but 32 extra tokens still add compute.
Writing quality: The paper is clear and well-structured. The motivation (working memory analogy) is compelling. However, Section 3.2 (training procedure) is dense—it conflates curriculum design, loss functions, and implementation details. Splitting this into “Curriculum Design” and “Training Mechanics” would improve readability. The related work section undersells the novelty—it lists prior latent reasoning methods but doesn’t clearly explain why they failed and how RiM differs.
Verdict: weak accept — Solid contribution with a clever training curriculum, but limited exploration of design space and unclear scaling to large models.
Takeaways
Curriculum grounding for latent representations: If you want a model to use special tokens or embeddings for internal computation, don’t just add them and hope. Ground them first with explicit supervision (Stage 1), then remove the scaffolding (Stage 2). This two-stage pattern transfers to other domains—teaching models to use tool APIs, intermediate data structures, or planning tokens.
Iterative refinement as a training objective: Instead of predicting the answer once, predict it multiple times at different “depths” of computation. Penalize all predictions, not just the final one. This encourages the model to progressively improve its answer, which is useful for any task where reasoning depth varies (math, coding, planning).
Fixed vs generated tokens for compute scaling: When scaling test-time compute, consider whether intermediate tokens need to be generated or can be fixed. If the structure is predictable (e.g., “think for N steps”), fixed tokens avoid autoregressive cost. This applies beyond reasoning—fixed tokens could represent planning steps, retrieval queries, or tool calls.
论文: 2605.30343 作者: Lukas Aichberger, Sepp Hochreiter 分类: cs.CL, cs.AI
缺口
当前方法通过生成中间 token 来扩展测试时推理能力——思维链提示、自洽性、推理路径树搜索。
这些方法有效,但混淆了两种不同的活动:内部计算(想出答案)和外部交流(展示过程)。
每个推理步骤都要付出自回归生成的代价。
模型必须”大声思考”,即使中间步骤对最终答案毫无价值。
此前的潜在推理尝试(隐藏状态、学习嵌入)失败了,因为缺乏训练课程来奠定潜在表示的基础。
缺口在于:没有方法成功地将推理与 token 生成解耦,同时保持竞争力。
问题:推理 = 自回归生成
   |
   v
假设:大模型有潜在的工作记忆容量
   |
   v
方法:固定记忆块 + 两阶段课程
   |
   v
证据:匹配 CoT 性能,1 次前向传播 vs N 次
   |
   v
结论:推理可以内化而无需生成
增量
一句话: 之前——推理需要自回归生成 O(N) 个中间 token; 之后——推理在固定记忆块中进行,O(1) 次前向传播处理完成。
核心机制
RiM 引入记忆块:固定的特殊 token 序列(如 <mem1>、<mem2>、…、<mem32>),插入在问题和答案之间。
这些不是生成的——而是预置到输入中。
模型在单次前向传播中处理它们,将其用作内部计算的草稿空间。
训练分两个阶段。
阶段 1(奠基):在每个记忆块之后,模型预测一个显式推理步骤(类似思维链)。
这教会模型使用记忆块进行结构化思考。
阶段 2(精炼):去掉中间监督。
在每个记忆块之后,模型预测最终答案。
早期块产生粗糙答案; 后期块精炼答案。
模型学会使用记忆作为工作空间迭代改进答案。
输入:[问题] <mem1> <mem2> ... <mem32> [答案]
       |      |      |           |        |
       v      v      v           v        v
阶段1:Q --> 步骤1  步骤2  ...  步骤N -> A
       (将记忆块奠基到显式推理)

阶段2:Q --> 答案1  答案2  ...  答案N -> A
       (迭代精炼答案,无中间步骤)
想象一个学生在草稿纸上解数学题。
传统思维链就像大声叙述每个计算——“首先我把 7 乘以 3,得到 21,然后加 5…”——昂贵且缓慢。
RiM 就像在草稿纸上默默计算,只展示最终答案。
记忆块就是草稿纸:固定空间,模型可以在上面涂写中间思路,而无需逐 token 生成的代价。
阶段 1 教学生如何使用草稿纸(通过检查每一步的工作)。
阶段 2 让他们自由工作,只检查最终答案。
关键概念
- 工作记忆 vs 交流:人类认知将内部操作(工作记忆)与外部表达(言语)分离。
你可以在脑中计算”17 × 23”而不用说出每一步。
大模型传统上缺乏这种分离——每次计算都必须外化为 token。
RiM 通过给模型一个固定的内部工作空间(记忆块)引入了这种分离,与输出流不同。
模型学会在记忆块中”思考”,只”说出”最终答案。
- 课程奠基:你不能只是告诉模型”用这些特殊 token 推理”——它对它们的含义没有先验。
阶段 1 通过强制模型在每个记忆块后预测显式推理步骤来奠定基础。
这创建了一座桥梁:记忆块 → 推理步骤 → 答案。
一旦奠定基础,阶段 2 移除桥梁(不再有中间步骤),但模型保留了记忆块与结构化推理之间的学习关联。
就像训练轮:一开始必需,技能内化后移除。
- 迭代精炼:RiM 不是生成单一推理链,而是多次预测最终答案——每个记忆块后一次。
早期预测粗糙; 后期预测融入更多计算。
这反映了人类如何精炼答案:首次近似,然后修正,然后打磨。
损失函数惩罚所有中间答案,因此模型学会使用每个记忆块改进前一次尝试。
框架转变
之前(思维链):                  之后(RiM):

Q --> [生成] --> 步骤1            Q + <mem1><mem2>...<memN>
      [生成] --> 步骤2              |
      [生成] --> 步骤3              v
      [生成] --> 步骤N            [单次前向传播]
      [生成] --> 答案               |
                                    v
(N 次自回归步骤)                  答案

代价:O(N) 生成                  代价:O(1) 前向传播
推理:外化                       推理:内化
从顺序生成到并行处理,核心转变是将计算与交流解耦。
专家评审
选题眼光:真实缺口。
测试时计算扩展是热门话题(o1、自洽性、树搜索),但所有当前方法都要付自回归税。
将推理与生成解耦是自然的下一步,尽管此前的尝试(学习嵌入、隐藏状态操作)未能获得关注。
本文时机不错——它解决了高价值领域的瓶颈。
方法成熟度:两阶段课程巧妙且动机充分。
阶段 1 解决了困扰早期潜在推理工作的奠基问题。
阶段 2 的迭代精炼优雅——它重用相同机制(每个块后预测答案)而非引入新组件。
然而,方法有些蛮力:任意长度(32 token)的固定记忆块,没有学习分配。
更复杂的方法可能动态分配记忆或学习何时停止精炼。
论文没有探索这些方向。
实验诚意:基线公平——CoT、自洽性和先前的潜在方法。
结果显示 RiM 在 GSM8K、MATH 和 ARC 上匹配或略超 CoT,同时使用一次前向传播而非 N 次。
消融实验彻底(变化记忆块数量,比较阶段 1 vs 阶段 2)。
一个担忧:实验使用相对较小的模型(最多 7B 参数)。
方法是否扩展到前沿模型(70B+)尚不清楚,而自回归代价在那里最重要。
论文也没有报告实际时间比较——“一次前向传播”听起来快,但 32 个额外 token 仍增加计算量。
写作功力:论文清晰且结构良好。
动机(工作记忆类比)令人信服。
然而,第 3.2 节(训练过程)密集——它混合了课程设计、损失函数和实现细节。
将其拆分为”课程设计”和”训练机制”会提高可读性。
相关工作部分低估了新颖性——它列出了先前的潜在推理方法,但没有清楚解释它们为何失败以及 RiM 如何不同。
判决:弱接收 — 扎实的贡献,训练课程巧妙,但设计空间探索有限,扩展到大模型的情况不明。
要点总结
潜在表示的课程奠基:如果你想让模型使用特殊 token 或嵌入进行内部计算,不要只是添加它们然后期待。
先用显式监督奠定基础(阶段 1),然后移除脚手架(阶段 2)。
这种两阶段模式可迁移到其他领域——教模型使用工具 API、中间数据结构或规划 token。
迭代精炼作为训练目标:不是预测答案一次,而是在不同”深度”的计算中多次预测。
惩罚所有预测,而非仅最终预测。
这鼓励模型逐步改进答案,对推理深度变化的任何任务有用(数学、编码、规划)。
固定 vs 生成 token 用于计算扩展:扩展测试时计算时,考虑中间 token 是否需要生成或可以固定。
如果结构可预测(如”思考 N 步”),固定 token 避免自回归代价。
这适用于推理之外——固定 token 可以表示规划步骤、检索查询或工具调用。