Paper: 2604.11557 Authors: Yijuan Liang, Xinghao Chen, Yifan Ge, Ziyi Wu, Hao Wu, Changyu Zeng, Wei Xing, Xiaoyu Shen Categories: cs.AI
The Gap
Existing tool-use research for LLM agents is fragmented. Different papers use incompatible function-calling formats (JSON-RPC vs REST vs custom schemas). Training datasets ignore the structural patterns of how tools compose — whether calls happen in sequence or parallel, single-turn or multi-turn. Benchmarks measure different things with different metrics, making cross-paper comparisons meaningless.
The core issue: no one has treated tool-use as a structured interaction problem with explicit topology. Prior work focuses on individual function calls, not the graph of dependencies between them.
Problem: Fragmented tool-use ecosystem
   |
   v
Assumption: Tool interactions have learnable structural patterns
   |
   +---> Method: Unified representation (QAOA) + controlled synthetic data
   |
   +---> Evidence: 93% precision on Hybrid-20 (vs 85% for GPT-4)
   |
   v
Conclusion: Standardization + structural modeling > ad-hoc approaches
The Increment
One sentence: Before — every lab invents its own tool format and evaluation; after — a common substrate for comparing and training tool-use agents.
Core Mechanism
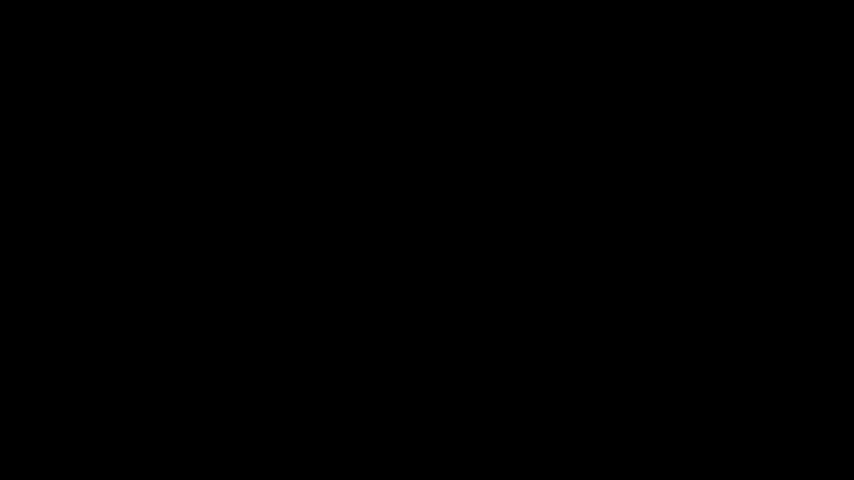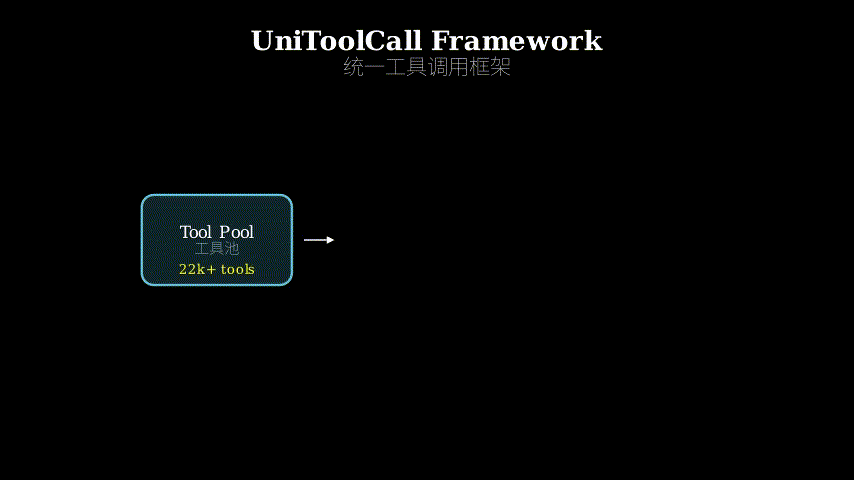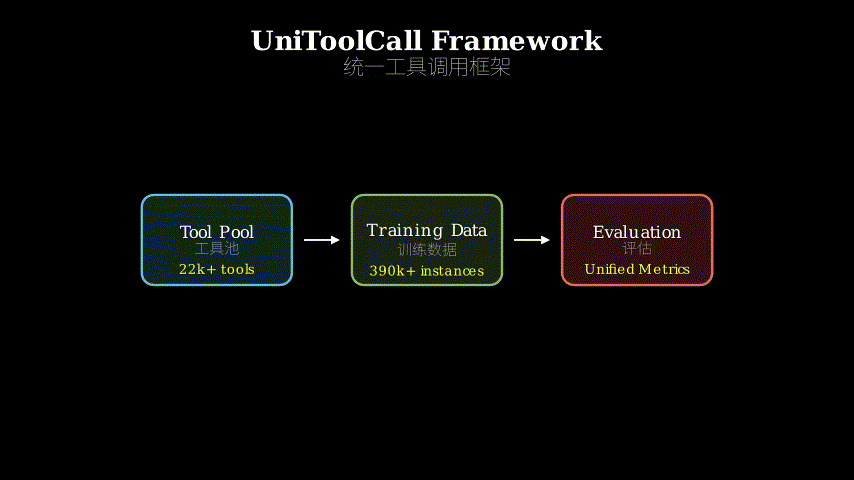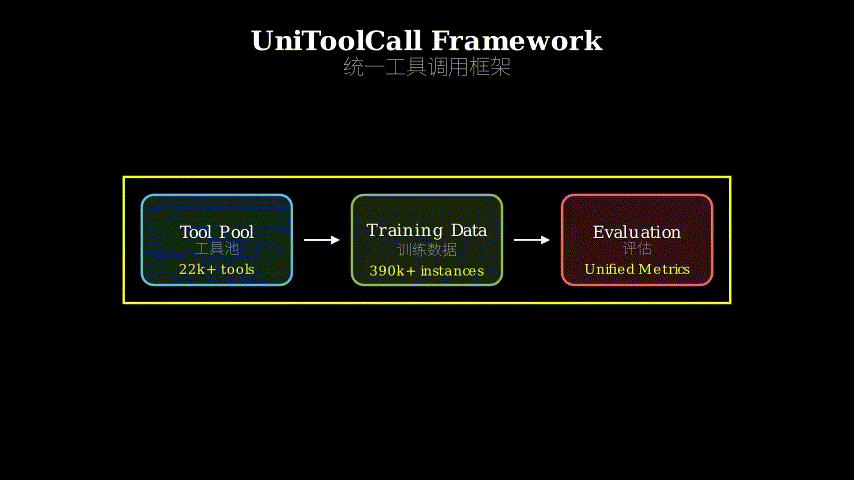
UniToolCall has three layers. First, a tool pool of 22k+ functions with standardized schemas. Second, a hybrid training corpus (390k instances) mixing 10 public datasets with synthetic trajectories that explicitly control interaction structure — single vs multi-hop, serial vs parallel execution, single vs multi-turn conversations. Third, a unified evaluation protocol (QAOA: Query-Action-Observation-Answer) that converts 7 benchmarks into a common format with metrics at function-call, turn, and conversation granularity.
The key innovation is Anchor Linkage for multi-turn reasoning. When generating a multi-turn trajectory, the system identifies “anchor” variables in early turns (e.g., a user_id returned by login()) and forces later turns to reference them. This creates explicit cross-turn dependencies, preventing the model from treating each turn as independent.
Data generation uses a two-stage process: sample a structural template (e.g., “3-hop serial chain with 2 parallel branches”), then instantiate it with tools from the pool. This ensures the training set covers diverse topologies, not just the patterns that happen to appear in public datasets.
Tool Pool (22k functions)
   |
   v
Template Sampler --> [serial/parallel/hybrid structure]
   |
   v
Instantiation --> Synthetic trajectory with Anchor Linkage
   |
   +---> Public datasets (10 sources, standardized)
   |
   v
Hybrid Corpus (390k instances)
   |
   v
Fine-tuning --> Qwen3-8B
   |
   v
Evaluation (QAOA format, 3-level metrics)
Think of it like building a highway system. Before, every city (research lab) had its own road standards — different lane widths, signage, traffic rules. You couldn’t drive a car trained in one city to another. UniToolCall is the interstate highway standard: unified lane markings (QAOA representation), controlled on-ramps and exits (structural templates), and explicit route dependencies (Anchor Linkage). The tool pool is the map of all possible destinations. Training data is generated by sampling routes with specific topologies (serial highways, parallel lanes, multi-level interchanges), ensuring the model learns to navigate any configuration. Evaluation measures whether the model reaches the destination (conversation-level), takes correct exits (turn-level), and stays in its lane (function-call-level).
Key Concepts
-
QAOA Representation: Query-Action-Observation-Answer is a four-part structure for each interaction turn. Query = user input. Action = function call(s) the agent makes. Observation = results returned by tools. Answer = agent’s response to user. This separates “what the agent does” (Action) from “what the agent says” (Answer), making it possible to evaluate tool-use accuracy independently of conversational fluency. Example: User asks “Book a flight to Paris.” Action =
search_flights(destination="Paris"). Observation =[{flight_id: 123, price: 450}]. Answer = “I found a flight for $450.” -
Anchor Linkage: A mechanism to enforce cross-turn dependencies in multi-turn conversations. When generating synthetic data, the system marks certain variables as “anchors” (e.g., session tokens, entity IDs). Later turns must reference these anchors, creating a dependency chain. Without this, models learn to treat each turn independently, failing on tasks like “use the user_id from turn 1 to fetch preferences in turn 3.” It’s like threading a needle through multiple beads — each bead (turn) must pass through the same thread (anchor variable).
-
Structural Templates: Pre-defined patterns for tool interaction topology. Examples: single-hop (one function call), multi-hop serial (A → B → C), multi-hop parallel (A + B → C), hybrid (A → [B + C] → D). Training data is generated by sampling templates, then filling them with tools from the pool. This ensures coverage of diverse interaction patterns, not just the most common ones in public datasets. It’s the difference between learning chess by playing random games vs systematically studying openings, middlegames, and endgames.
Framework Shift
Before (mainstream approach):        After (this paper):

Dataset 1 (format A)                 Tool Pool (22k, unified schema)
Dataset 2 (format B)                        |
Dataset 3 (format C)                        v
    |                                Template Sampler
    v                                   /    |    \
Train on mixed formats          Serial  Parallel  Hybrid
    |                                   \    |    /
    v                                        v
Evaluate on benchmark X          Controlled synthesis + public data
(incomparable to Y, Z)                      |
                                            v
                                    QAOA unified format
                                            |
                                            v
                                  3-level evaluation (call/turn/conv)
From ad-hoc format mixing to controlled structural generation, the core shift is treating tool-use as a graph problem with explicit topology.
Expert Assessment
Problem choice: Real gap. The fragmentation is obvious to anyone who’s tried to compare tool-use papers — you can’t reproduce results because everyone uses different formats and metrics. This is infrastructure work the field needs.
Method maturity: Mostly engineering, not algorithmic novelty. Anchor Linkage is clever but simple. The value is in curation (22k tools, 10 datasets standardized) and systematic coverage of interaction patterns. The structural template approach is borrowed from program synthesis — not new, but well-applied here.
Experimental integrity: Baselines are fair. The Hybrid-20 setting (20 tools, 10 distractors) is genuinely hard. Numbers look solid. One concern: the paper doesn’t report how much of the performance gain comes from data volume (390k instances) vs structural diversity. Ablation on template types would strengthen the claims.
Writing quality: Section 3 (data generation) is dense and could use a figure showing the pipeline. The QAOA format is introduced too late — should be in the introduction. The related work section is thorough but reads like a literature dump. Rewriting it to highlight the specific gaps (format inconsistency, structural blindness, evaluation fragmentation) would make the motivation crisper.
Verdict: weak accept — Solid infrastructure contribution with strong empirical results, but limited algorithmic novelty. The field needs this standardization, even if the methods aren’t groundbreaking.
Takeaways
Structural templates for synthetic data: If you’re generating training data for any sequential decision-making task (not just tool-use), explicitly controlling the topology of trajectories beats sampling from a uniform distribution. Define templates (linear chains, trees, DAGs), then instantiate them. This ensures coverage of edge cases.
Anchor variables for multi-step reasoning: When fine-tuning models on multi-turn tasks, inject explicit dependencies between turns. Mark key variables in early steps and force later steps to reference them. This prevents the model from learning turn-independent shortcuts.
Three-level evaluation: For any agent task, measure at multiple granularities — atomic actions (function calls), episodes (turns), and full trajectories (conversations). Aggregate metrics hide where models fail. Fine-grained metrics reveal whether the issue is action selection, sequencing, or long-term planning.
论文: 2604.11557 作者: Yijuan Liang, Xinghao Chen, Yifan Ge, Ziyi Wu, Hao Wu, Changyu Zeng, Wei Xing, Xiaoyu Shen 分类: cs.AI
缺口
现有的大语言模型智能体工具使用研究是碎片化的。
不同论文使用不兼容的函数调用格式(JSON-RPC、REST、自定义模式)。
训练数据集忽略了工具组合的结构模式——调用是串行还是并行,单轮还是多轮。
基准测试用不同指标衡量不同的东西,跨论文比较毫无意义。
核心问题:没人把工具使用当作一个结构化交互问题,带有明确的拓扑关系。
以往工作关注单个函数调用,而非调用之间的依赖图。
问题:碎片化的工具使用生态
   |
   v
假设:工具交互有可学习的结构模式
   |
   +---> 方法:统一表示(QAOA)+ 受控合成数据
   |
   +---> 证据:Hybrid-20 上 93% 精度(GPT-4 为 85%)
   |
   v
结论:标准化 + 结构建模 > 临时方法
增量
一句话: 之前——每个实验室发明自己的工具格式和评估方法;之后——一个比较和训练工具使用智能体的通用基底。
核心机制
UniToolCall 有三层。
第一层,一个包含 22k+ 函数的工具池,带有标准化模式。
第二层,一个混合训练语料库(390k 实例),混合了 10 个公开数据集和合成轨迹,后者显式控制交互结构——单跳 vs 多跳、串行 vs 并行执行、单轮 vs 多轮对话。
第三层,一个统一评估协议(QAOA:查询-动作-观察-回答),将 7 个基准转换为通用格式,在函数调用、轮次和对话三个粒度上提供指标。
关键创新是用于多轮推理的 Anchor Linkage(锚点链接)。
生成多轮轨迹时,系统识别早期轮次中的”锚点”变量(例如 login() 返回的 user_id),并强制后续轮次引用它们。
这创建了显式的跨轮依赖,防止模型将每轮视为独立的。
数据生成使用两阶段过程:采样一个结构模板(例如”带 2 个并行分支的 3 跳串行链”),然后用工具池中的工具实例化它。
这确保训练集覆盖多样的拓扑结构,而不仅仅是公开数据集中恰好出现的模式。
工具池(22k 函数)
   |
   v
模板采样器 --> [串行/并行/混合结构]
   |
   v
实例化 --> 带锚点链接的合成轨迹
   |
   +---> 公开数据集(10 个来源,标准化)
   |
   v
混合语料库(390k 实例)
   |
   v
微调 --> Qwen3-8B
   |
   v
评估(QAOA 格式,3 级指标)
把它想象成建设高速公路系统。
以前,每个城市(研究实验室)都有自己的道路标准——不同的车道宽度、标识、交通规则。
你不能把在一个城市训练的汽车开到另一个城市。
UniToolCall 是州际高速公路标准:统一的车道标记(QAOA 表示)、受控的上下匝道(结构模板)、显式的路线依赖(锚点链接)。
工具池是所有可能目的地的地图。
训练数据通过采样具有特定拓扑的路线生成(串行高速公路、并行车道、多层立交桥),确保模型学会导航任何配置。
评估衡量模型是否到达目的地(对话级)、是否正确驶出(轮次级)、是否保持在车道内(函数调用级)。
关键概念
- QAOA 表示:查询-动作-观察-回答是每个交互轮次的四部分结构。
查询 = 用户输入。
动作 = 智能体进行的函数调用。
观察 = 工具返回的结果。
回答 = 智能体对用户的响应。
这将”智能体做什么”(动作)与”智能体说什么”(回答)分开,使得可以独立于对话流畅性评估工具使用准确性。
例子:用户问”订一张去巴黎的机票。
“动作 = search_flights(destination="Paris")。
观察 = [{flight_id: 123, price: 450}]。
回答 = “我找到了一张 450 美元的机票。
”
- 锚点链接:一种在多轮对话中强制跨轮依赖的机制。
生成合成数据时,系统将某些变量标记为”锚点”(例如会话令牌、实体 ID)。
后续轮次必须引用这些锚点,创建依赖链。
没有这个,模型会学习将每轮独立处理,在”使用第 1 轮的 user_id 在第 3 轮获取偏好”这样的任务上失败。
这就像用线穿过多个珠子——每个珠子(轮次)必须穿过同一根线(锚点变量)。
- 结构模板:工具交互拓扑的预定义模式。
例子:单跳(一次函数调用)、多跳串行(A → B → C)、多跳并行(A + B → C)、混合(A → [B + C] → D)。
训练数据通过采样模板生成,然后用工具池中的工具填充。
这确保覆盖多样的交互模式,而不仅仅是公开数据集中最常见的模式。
这是通过玩随机游戏学习国际象棋与系统学习开局、中局和残局之间的区别。
框架转变
之前(主流方法):                之后(本文方法):

数据集 1(格式 A)                工具池(22k,统一模式)
数据集 2(格式 B)                       |
数据集 3(格式 C)                       v
    |                                模板采样器
    v                                /    |    \
在混合格式上训练              串行  并行  混合
    |                                \    |    /
    v                                     v
在基准 X 上评估              受控合成 + 公开数据
(与 Y、Z 不可比)                       |
                                         v
                                 QAOA 统一格式
                                         |
                                         v
                              3 级评估(调用/轮次/对话)
从临时格式混合到受控结构生成,核心转变是将工具使用视为具有显式拓扑的图问题。
专家评审
选题眼光:真实缺口。
任何试图比较工具使用论文的人都能看到碎片化——你无法复现结果,因为每个人都使用不同的格式和指标。
这是该领域需要的基础设施工作。
方法成熟度:主要是工程,而非算法创新。
锚点链接很巧妙但简单。
价值在于整理(22k 工具,10 个数据集标准化)和系统覆盖交互模式。
结构模板方法借鉴自程序合成——不是新的,但在这里应用得很好。
实验诚意:基线公平。
Hybrid-20 设置(20 个工具,10 个干扰项)确实很难。
数字看起来扎实。
一个担忧:论文没有报告性能提升有多少来自数据量(390k 实例)vs 结构多样性。
对模板类型的消融实验会加强论证。
写作功力:第 3 节(数据生成)很密集,需要一个展示流程的图。
QAOA 格式引入得太晚——应该在引言中。
相关工作部分很全面,但读起来像文献堆砌。
重写它以突出具体缺口(格式不一致、结构盲目、评估碎片化)会使动机更清晰。
判决:弱接收——扎实的基础设施贡献,实证结果强劲,但算法创新有限。
该领域需要这种标准化,即使方法不是开创性的。
要点总结
合成数据的结构模板:如果你为任何顺序决策任务(不仅仅是工具使用)生成训练数据,显式控制轨迹拓扑优于从均匀分布采样。
定义模板(线性链、树、DAG),然后实例化它们。
这确保覆盖边缘情况。
多步推理的锚点变量:在多轮任务上微调模型时,在轮次之间注入显式依赖。
在早期步骤中标记关键变量,并强制后续步骤引用它们。
这防止模型学习轮次独立的捷径。
三级评估:对于任何智能体任务,在多个粒度上衡量——原子动作(函数调用)、片段(轮次)和完整轨迹(对话)。
聚合指标隐藏了模型失败的地方。
细粒度指标揭示问题是动作选择、排序还是长期规划。