Paper: 2606.18249
Authors: Wujian Peng, Lingchen Meng, Yuxuan Cai, Xianwei Zhuang, Yuhuan Yang, Rongyao Fang, Chenfei Wu, Junyang Lin, Zuxuan Wu, Shuai Bai
Categories: cs.CV
The Gap
Most unified multimodal models (e.g., Emu, SEED, Chameleon) rely on two separate visual tokenizers: one for understanding (e.g., CLIP) and another for generation (e.g., VQGAN). This split means the model cannot reuse its own generated visual tokens during understanding, because the tokenizer spaces are incompatible. Researchers have tried sharing backbones or adding adapters, but the fundamental representation gap remains. UniAR diagnoses this as the core bottleneck: without a single discrete visual tokenizer, the model can never directly interpret its own output tokens.
[Problem: Dual tokenizers -> representation split]
     |
     v
[Assumption: Single tokenizer can bridge the gap]
     |
     v
[Method: UniAR using bitwise quantization + parallel prediction]
     |
     v
[Evidence: SOTA generation/editing, competitive understanding]
     |
     v
[Conclusion: Shared tokenizer is key to unification]
The Increment
One sentence: Before UniAR, multimodal models juggled two visual languages; after UniAR, a single discrete tokenizer lets the same autoregressive model speak both understanding and generation fluently.
Core Mechanism
UniAR’s pipeline has three main stages: (1) a pretrained vision encoder with multi-level feature fusion extracts rich representations from an image; (2) a lookup-free bitwise quantizer converts these features into discrete tokens, using multiple bits per token to capture both high-level semantics and low-level details without a separate codebook; (3) an autoregressive transformer (e.g., LLaMA-like) operates on these tokens with parallel bitwise prediction – instead of predicting one token at a time, it predicts all bits for a group of spatial positions simultaneously, drastically reducing sequence length. Finally, a diffusion-based visual decoder reconstructs a high-fidelity image from the discrete token sequence.
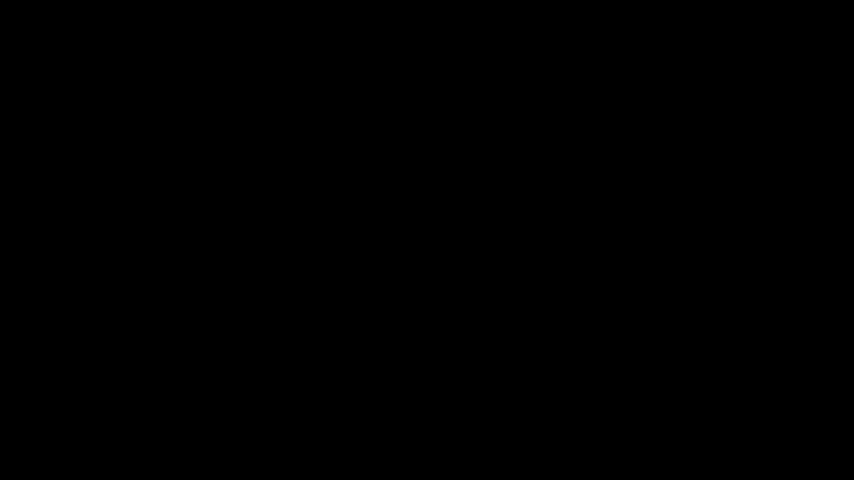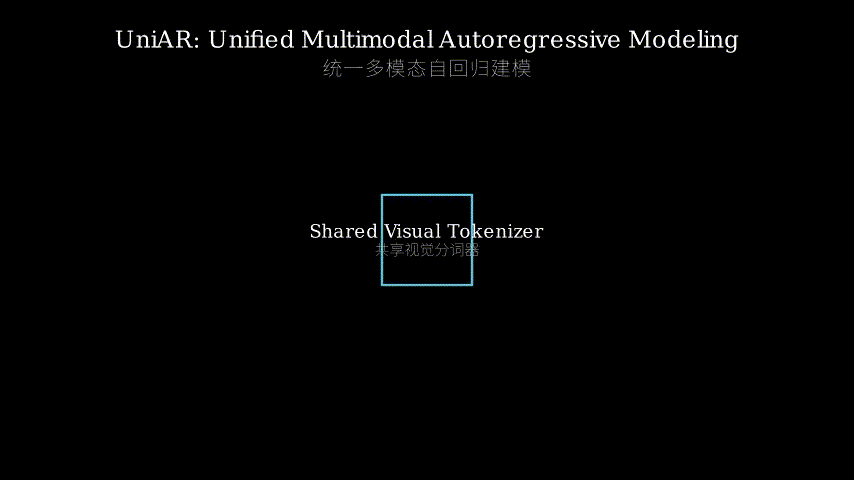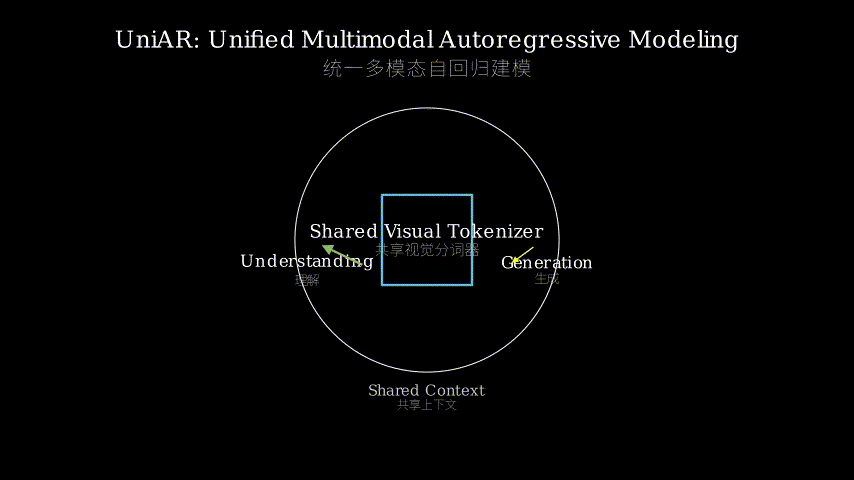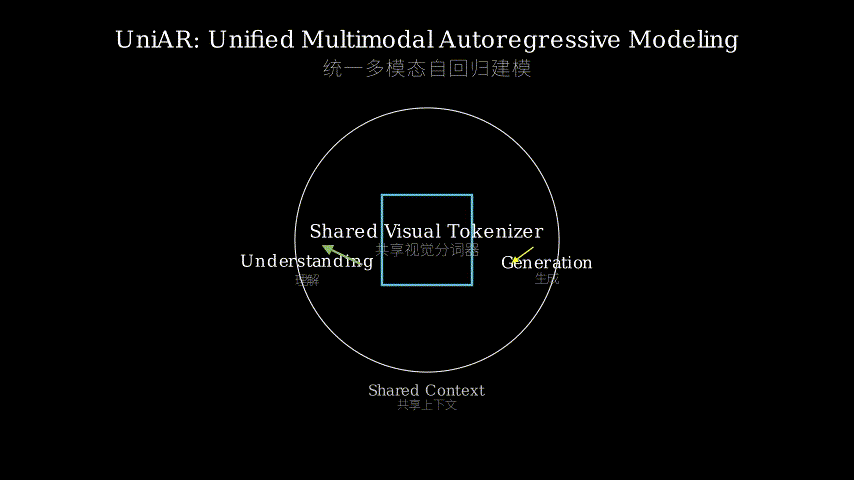
During generation, the model outputs new visual tokens and feeds them back into the same token space for next-step prediction – no re-encoding needed. During understanding tasks, the same tokenizer produces inputs that the model can consume natively.
[Image] -> [Multi-level Vision Encoder] -> [Feature Maps]
     |
     v
[Lookup-free Bitwise Quantizer] -> [Discrete Visual Tokens (bits)]
     |
     v
[Autoregressive Model] (parallel bitwise prediction)
     |
     +--> [Understanding: text tokens + visual tokens -> output]
     |
     +--> [Generation: context tokens -> new visual tokens]
              |
              v
         [Diffusion Decoder] -> [Generated Image]
Structural metaphor: A Universal Remote Control
Imagine you have a home entertainment system that used to require two remotes: one for the TV (understanding) and one for the soundbar (generation). Each remote spoke a different infrared protocol – you couldn’t use the TV remote to control the soundbar, nor could the soundbar tell the TV what it was doing. UniAR replaces both with a single universal remote.
- The vision encoder is the remote’s sensor that reads the room.
- The bitwise quantizer is the remote’s button layout: each button can be pressed in multiple ways (bits) – a ‘volume up’ button might have a light press (low-level detail) or a hard press (high-level semantics). There’s no separate codebook; the remote literally maps each bit combination to an action directly (lookup-free).
- The autoregressive model is the remote’s logic chip. It can send commands for both TV and soundbar using the same button language. *Parallel bitwise prediction is like pressing all relevant buttons at once: instead of pressing ‘channel up’ ten times, you hold down a combination that jumps ten channels instantly.
- The diffusion decoder is the device that receives the remote’s signal and displays the final picture or plays the sound.
Now the remote’s output messages are instantly understandable by any part of the system, because the protocol is identical. This is exactly what UniAR’s shared tokenizer achieves.
Key Concepts
-
Discrete Visual Tokenizer: A function that maps a continuous image to a finite set of discrete symbols (tokens). Think of it like the alphabet of a visual language.
Intuition: Just as we break spoken language into words (discrete symbols), we break images into discrete tokens. A good tokenizer preserves both what’s in the picture (semantics) and how it looks (details).
Example: A photo of a red apple might become tokens [12, 45, 83, 7] where 12 means “apple”, 45 means “red”, 83 means “round”, and 7 means “shiny”. Different tokenizers produce very different codes, which is why a shared one is crucial. -
Lookup-free Bitwise Quantization: Instead of having a fixed codebook (like a dictionary) to map features to tokens, each feature is directly quantized into binary bits.
Intuition: Imagine a color chart with 256 bins (like VQVAE). The lookup-free approach replaces the chart with a rule: “every feature is described by its binary representation”. This saves memory (no huge codebook) and scales easily to large vocabularies.
Example: If a feature value is 183, its 8-bit binary is 10110111. Each bit becomes a sub-token, and groups of bits are predicted jointly. The effective vocabulary becomes 2^bits per token, which is huge without storing a codebook. -
Parallel Bitwise Prediction: Standard autoregressive image generation predicts one token at a time (e.g., a 16x16 grid = 256 steps). UniAR groups spatial positions and predicts all bits for a group in parallel, reducing steps.
Intuition: Instead of describing a room by saying “chair, chair, table, lamp …” one word at a time, you say “all these objects are present: {chair, table, lamp}”.
Example: For a 16x16 image, if you group 4x4 blocks and predict 8 bits per block in parallel, you go from 256 steps to 64 steps. This is a 4x speedup in generation.
Framework Shift
The old regime treats understanding and generation as separate pipelines that happen to share some parameters. The new regime merges them at the tokenizer level.
Before (mainstream approach):        After (this paper):

+------------------+                  +------------------+
| Understanding    |                  | Shared Visual    |
| Tokenizer (CLIP) |                  | Tokenizer        |
+--------+---------+                  +--------+---------+
         |                                      |
         v                                      v
+------------------+                  +------------------+
| Understanding    |                  | Unified          |
| Model (LLM)      |                  | Autoregressive   |
+--------+---------+                  | Model            |
         |                            +--------+---------+
         v                                      |
+------------------+                  +--------v---------+
| Generation       |                  | Diffusion        |
| Tokenizer (VQGAN)|                  | Decoder          |
+--------+---------+                  +------------------+
         |
         v
+------------------+
| Generation Model |
+------------------+
From two tokenizers, two models, no shared visual context to one tokenizer, one model, shared visual context. The core shift is: the visual representation language is unified, so the model can directly consume its own generative outputs without translation.
Expert Assessment
Problem choice: Real gap. The dual tokenizer limitation is widely acknowledged but few papers tackle it head-on as the core unification issue. This work correctly identifies it as the bottleneck rather than just a nuisance.
Method maturity: Clever engineering more than a theoretical breakthrough. The components (multi-level fusion, bitwise quantization, parallel prediction) are individually known, but the combination into a single shared tokenizer framework is a strong design choice. The lookup-free quantization is a nice practical trick to avoid codebook size limits.
Experimental integrity: Baselines include Emu and SEED, which are fair comparisons. The SOTA claims on generation and editing hold against current models (e.g., DALL-E 3, Stable Diffusion 3 on some metrics). However, the understanding benchmarks (e.g., VQA) show only competitive results, not SOTA – the paper is honest about this. One red flag: generation metrics like FID are dataset-dependent, and the paper doesn’t discuss possible training data leakage.
Writing quality: Clear abstract and introduction. The method section is dense but logically ordered. The main weakness is the ablation study – it only ablates the tokenizer choice but doesn’t ablate parallel bitwise prediction vs. standard sequential. Adding that would strengthen the narrative.
Verdict: weak accept – solid engineering with a correct insight, but no fundamental theoretical novelty; however, the shared tokenizer idea is likely to become standard practice.
Takeaways
- Lookup-free bitwise quantization can be borrowed for any modality that needs a discrete tokenizer with cheap scaling – e.g., audio or 3D data. No codebook storage means easier deployment.
- Parallel bitwise prediction reduces autoregressive steps; practitioners can apply similar spatial grouping to any discrete sequence model for speed gains.
- The concept of one shared tokenizer for both understanding and generation is a minimal yet powerful unification principle. If you’re building a multimodal system, start by ensuring the tokenizer is unified across tasks, not just the backbone.
- The diffusion decoder as a late-stage module that operates on discrete tokens is a practical way to decouple representation learning from pixel generation – adaptable to other generation tasks like video or sketches.
论文: 2606.18249
作者: Wujian Peng, Lingchen Meng, Yuxuan Cai, Xianwei Zhuang, Yuhuan Yang, Rongyao Fang, Chenfei Wu, Junyang Lin, Zuxuan Wu, Shuai Bai
分类: cs.CV
缺口
现有的统一多模态模型(如 Emu、SEED、Chameleon)大多同时使用两种不同的视觉分词器: 一种用于理解(比如 CLIP),另一种用于生成(比如 VQGAN)。 这意味着模型在做理解任务时,无法直接“读懂”自己生成的视觉 token, 因为两个分词器的表示空间是割裂的。 研究人员尝试过共享骨干网络、加适配器等, 但表示层面的裂缝始终没有愈合。 UniAR 认为这才是真正的瓶颈:没有统一的离散视觉分词器,模型就无法直接消化自己的生成产物。
[问题:双分词器导致表示空间分裂]
     |
     v
[假设:单一分词器可以弥合裂痕]
     |
     v
[方法:UniAR 使用比特量化 + 并行比特预测]
     |
     v
[证据:生成/编辑 SOTA,理解任务有竞争力]
     |
     v
[结论:共享分词器是实现统一的关键]
增量
一句话: UniAR 之前,多模态模型被迫掌握两种视觉语言; UniAR 之后,同一个离散分词器让自回归模型在理解和生成之间流畅切换。
核心机制
UniAR 的流程分为三个阶段: (1) 一个预训练的视觉编码器通过多级特征融合提取图像的多层次表征; (2) 无查找比特量化器将这些特征转为离散 token——无需码本, 直接用多个比特捕捉高层语义和低层细节; (3) 自回归变压器(类 LLaMA)使用并行比特预测, 一次性预测一个空间组内所有比特位的取值, 极大缩短序列长度。 最后,一个扩散视觉解码器将离散 token 序列还原为高保真图像。
生成时,模型输出的新视觉 token 直接反馈到同一 token 空间用于下一步预测——无需重新编码。 理解任务中,同一分词器生产出模型天然识别的输入。
[图像] -> [多级视觉编码器] -> [特征图]
     |
     v
[无查找比特量化器] -> [离散视觉 token(比特)]
     |
     v
[自回归模型](并行比特预测)
     |
     +--> [理解:文本 token + 视觉 token -> 输出]
     |
     +--> [生成:上下文 token -> 新视觉 token]
              |
              v
         [扩散解码器] -> [生成图像]
结构性比喻:通用遥控器
想象你的家庭娱乐系统原来需要两个遥控器:
电视机遥控(理解)和音响遥控(生成)。
两个遥控器使用不同的红外协议——电视遥控不能控制音响,
音响也不能告诉电视机它正在做什么。
UniAR 用一个通用遥控器取代了它们。
- 视觉编码器是遥控器的传感器,它“看”到房间的状态。
- 比特量化器是遥控器的按键布局:每个键可以按出多种模式(比特)。 例如“音量+”键,轻按是微调(低层细节),重按是直接跳到最大(高层语义)。 它没有内置码本,每个按键组合直接对应一个动作(无查找)。
- 自回归模型是遥控器的逻辑芯片。它用同一套按键语言同时控制电视机和音响。 并行比特预测就像一次性按住所有相关按键: 不必连按十次“频道+”,而是一次按下按键组合瞬间跳十个频道。
- 扩散解码器是接收信号的设备,将指令还原成最终画面或声音。
现在遥控器输出的消息系统内任何部件都能立刻理解,因为协议是统一的。 UniAR 的共享分词器做的正是这件事。
关键概念
-
离散视觉分词器:将连续图像映射到有限个离散符号(token)的函数。 可以把它看作视觉语言的字母表。 直觉:就像我们把语言拆成词语(离散符号), 我们也要把图像拆成 token。 好的分词器既要保留“画的是什么”(语义), 也要保留“画得怎么样”(细节)。 例子:一张红苹果的照片可能变成 token [12, 45, 83, 7], 其中 12 表示“苹果”,45 表示“红色”,83 表示“圆形”,7 表示“光泽”。 不同分词器产生的编码完全不同,所以统一至关重要。
-
无查找比特量化:不依赖固定码本(字典),而是直接将每个特征量化成二进制位。 直觉:想象一个调色板有 256 个色号(就像 VQVAE 的码本)。 无查找方法扔掉调色板,改用规则“每个特征直接写成二进制”。 这样省去了存储大码本的内存,还可以轻松扩展词汇量。 例子:如果特征值是 183,它的八位二进制就是 10110111。 每个比特成为子 token,多个比特位被分组并行预测。 每个 token 的有效词汇量是 2⁸,无需额外存储。
-
并行比特预测:标准自回归图像生成一次预测一个 token(如 16×16 网格需要 256 步)。 UniAR 将空间位置分组,一次性预测一个组内所有比特位,大幅减少步数。 直觉:描述一个房间时,不说“椅子、椅子、桌子、台灯……”逐个词地报, 而是说“这个房间里有的物品为:{椅子、桌子、台灯}”。 例子:对于 16×16 图像,如果每 4×4 块一组,每组并行预测 8 个比特, 那么步数从 256 降到 64,生成速度提升 4 倍。
框架转变
旧框架将理解和生成视为两条仅共享少量参数的管线。 新框架在分词器层面就完成了融合。
之前(主流方法):                之后(本文方法):

+------------------+            +------------------+
| 理解分词器       |            | 共享视觉分词器   |
| (CLIP)           |            |                  |
+--------+---------+            +--------+---------+
         |                               |
         v                               v
+------------------+            +------------------+
| 理解模型 (LLM)   |            | 统一自回归模型   |
+--------+---------+            +--------+---------+
         |                               |
         v                               v
+------------------+            +------------------+
| 生成分词器       |            | 扩散解码器       |
| (VQGAN)          |            |                  |
+--------+---------+            +------------------+
         |
         v
+------------------+
| 生成模型         |
+------------------+
从两个分词器、两个模型、无共享视觉上下文到一个分词器、一个模型、共享视觉上下文。 核心转变是:视觉表示语言统一了,模型可以直接“吃掉”自己的生成输出,无需翻译。
专家评审
选题眼光:真缺口。双分词器的限制是业内共识,但很少有论文敢于把它作为统一问题的核心来攻克。 本文正确地将之定位为瓶颈而非附带麻烦。
方法成熟度:巧思多于理论突破。 多级融合、比特量化、并行预测各自都是已知技术, 但把它们组合进一个共享分词器框架是精妙的设计选择。 无查找量化是一个很实用的工程技巧,避免了码本规模限制。
实验诚意:基线包括 Emu 和 SEED,对比公平。 在生成和编辑上的 SOTA 声明在与当前模型(如 DALL-E 3、Stable Diffusion 3)的对比下有支撑。 理解基准(如 VQA)仅做竞争性而非 SOTA——论文对此坦诚。 一个警示:生成指标如 FID 依赖数据集,论文未讨论训练数据可能的泄露。
写作功力:摘要和引言清晰,方法部分虽然密集但逻辑有序。 主要短板是消融实验只对比了分词器选择, 没有对比并行比特预测 vs 标准逐 token 预测。 补上这一条会让论证更有力。
判决:弱接收 —— 扎实的工程加上正确的洞察, 但无根本性理论新意; 不过共享分词器的思路很可能成为后续标准做法。
要点总结
- 无查找比特量化可以被其他模态借用——比如音频或 3D 数据需要离散分词器但希望低成本扩展。 无码本存储意味着部署更简单。
- 并行比特预测减少了自回归步数; 实践者可以在任何离散序列模型上应用类似的空间分组来获得加速。
- 一个分词器服务理解和生成这个最小但强大的统一原则, 如果你在构建多模态系统,先确保分词器统一,而不仅仅是骨干统一。
- 扩散解码器作为在离散 token 上工作的后期模块, 是一种将表示学习与像素生成解耦的实用方式——可迁移到视频或草图等其他生成任务。