Paper: 2606.27342 Authors: Nicholas Pulsone, Gregory Goren, Roee Shraga Categories: cs.DB, cs.AI, cs.LG
The Gap
Recent work in Entity Matching (EM) has moved from supervised single-domain setups to low-resource scenarios with domain adaptation. Methods like Ditto, DeepMatcher, and especially BEACON incorporate domain information (e.g., column types, schemas) and align distributions between source and target datasets. But no one has systematically asked: how do these components actually work under different supervision levels and data budgets? Prior evaluations treat BEACON as a monolithic black box. This paper opens the box, varying algorithmic choices (e.g., alignment strength, domain encoder design) and data availability (budget size, labeling strategy) to understand what drives performance.
[ASCII logic topology: Problem -> Assumption -> Method -> Evidence -> Conclusion]

      Existing EM works well on fixed domains + abundant labels
         |
         v
 [Problem] Low-resource domain-aware EM is poorly understood:
         |      * How does distribution alignment behave?
         |      * Which algorithmic choices matter most?
         |      * Under what budgets does alignment help?
         v
 [Assumption] Domain-aware alignment (like BEACON) consistently improves
         |      performance across all low-resource settings
         v
 [Method] ABLATE BEACON: vary alignment loss (MMD strength),
         |   domain encoder (pretrained vs raw), and budget size
         v
 [Evidence] Targeted experiments on 4 EM datasets, measuring F1
         |   across 12 combinations of settings
         v
 [Conclusion] Alignment helps only when source-target domain gap is large
              AND budget is small; otherwise it can hurt.
              The domain encoder matters more than alignment details.
The Increment
One sentence: Before this paper, BEACON was a monolithic tool for low-resource EM; after this paper, we know exactly which knobs to turn—and when to leave them alone.
Core Mechanism
BEACON is a two-stage framework. Stage one: a domain encoder takes each record (from source or target) and produces a domain-aware embedding. This encoder is trained via a contrastive objective that aligns records with similar domain metadata (e.g., same column types). Stage two: a distribution alignment module minimizes the discrepancy between the source and target embeddings (using Maximum Mean Discrepancy, MMD). The final matching head (a simple classifier) is trained on source labels and evaluated on target records.
Data flow: source labeled records + target unlabeled records -> (1) domain encoder (shared weights) -> embeddings -> (2) contrastive loss + (3) MMD alignment loss -> (4) matching head trained on source labels.
[ASCII diagram of method internals]

   Source labeled    Target unlabeled
         |                 |
         v                 v
   +----------+     +----------+
   | Encoder / |     | Encoder / |
   | weights / |     | weights   |
   +----------+     +----------+
         |                 |
         v                 v
   +----------+     +----------+
   | Embeddings|     | Embeddings|
   +----------+     +----------+
         \                 /
          \               /
           v             v
        +------------------+
        | Alignment module | (MMD loss)
        +------------------+
                |
                v
        +------------------+
        | Matching Head    | (trained on source labels)
        +------------------+
Structural Metaphor: The Multi-Language Police Dispatch
Imagine a police dispatch system that must match incident reports across two neighboring cities. City A (source domain) uses formal language: “traffic obstruction – vehicle 45° tilt.” City B (target domain) uses informal dialect: “car tipped over near the corner store.” The system has only a few labeled dispatches from city B (budget).
- Domain encoder: a translator who learns both city dialects by seeing many report templates (metadata). It maps “obstruction” and “tipped over” into the same semantic space.
- Contrastive pre‑training: the translator practices by reading pairs: if two reports share the same incident type (e.g., both are about traffic), it must embed them nearby.
- Distribution alignment: a filter that smooths out the accent differences. If City A tends to write longer sentences, the filter compresses City A’s embeddings to match City B’s average length.
- Matching head: a dispatcher who decides if two reports (one from A, one from B) refer to the same real-world event. Trained only on City A’s labeled pairs.
Now, the paper’s experiments are like asking: Should the filter be strong or weak? Does it matter if the translator knows City B’s dialect a little? The answer: the filter helps only when dialects are very different and the labeled examples from City B are scarce. If dialects are similar, the filter adds noise. If many labeled examples exist, the dispatcher can learn City B’s quirks directly.
Key Concepts
-
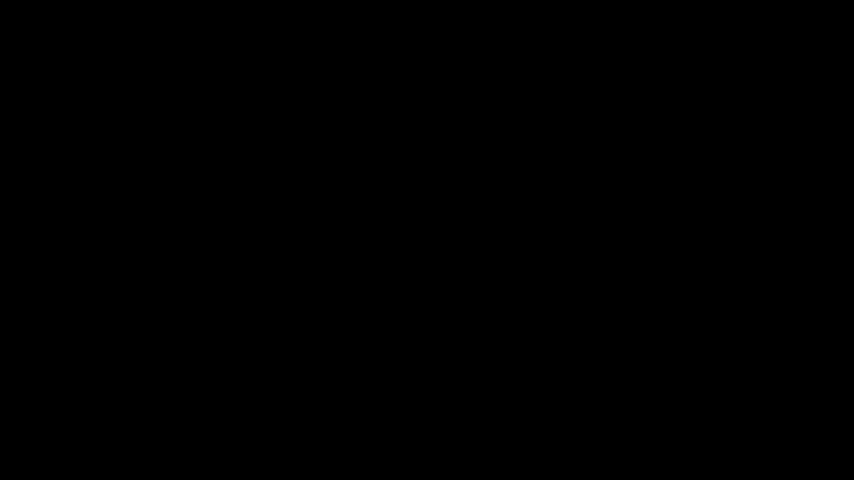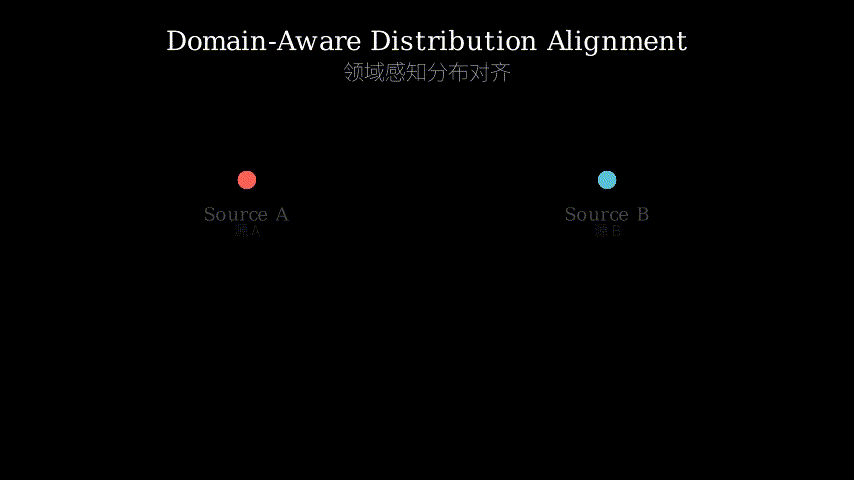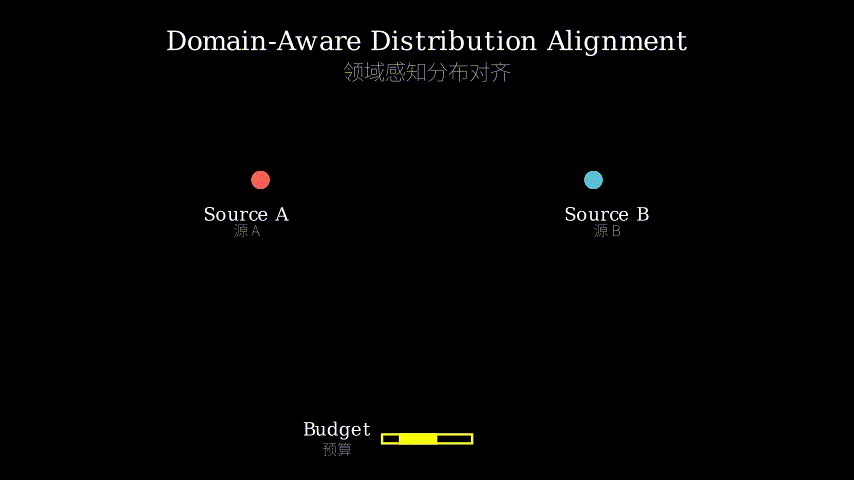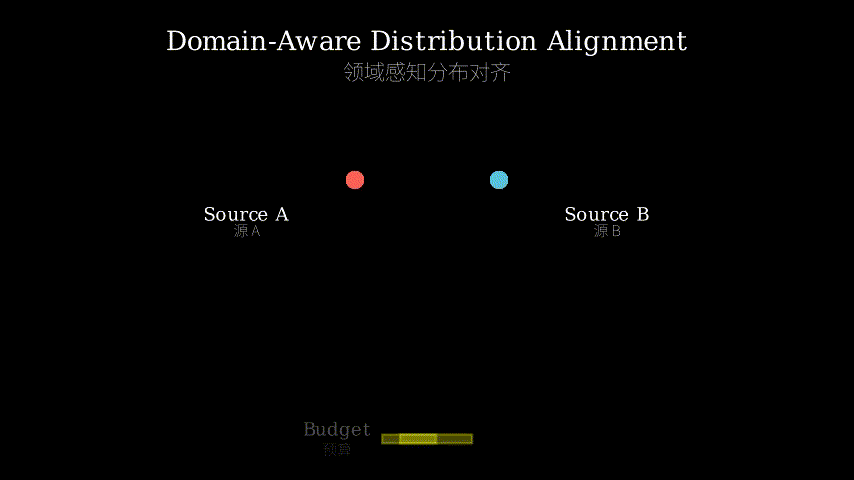
Distribution Alignment (MMD): In EM, source and target datasets often have different feature distributions (e.g., one uses abbreviations, the other full names). MMD measures the distance between two sets of embeddings in a reproducing kernel Hilbert space. Minimizing MMD forces the embeddings to become similar across domains. *Concrete example: source embeddings all lie around (0,0), target around (1,1). MMD loss pulls the target embeddings toward (0,0), aligning the two groups before matching.
-
Domain‑Aware Encoder: A network that takes not only the record’s text but also its schema metadata (column name, data type) as input. This lets the model learn that “name” in one dataset might correspond to “full_name” in another. Without it, the model would treat “name” and “full_name” as unrelated tokens.
-
Budgeted Entity Matching: A setting where only a limited number of target records can be labeled (e.g., 50 or 100 pairs). The “budget” constrains how much supervision the matcher can receive from the target domain. This paper varies budgets from 10 to 200 labeled target pairs to see how alignment interacts with supervision level.
Framework Shift
Before (mainstream approach):        After (this paper):
   Train on source only,             Use source + target unlabeled,
   then test on target               align distributions before matching

   Source labels ----+                 Source labels ---> Encoder ----+
                     |                                              |
   +----------+      v       +----+       +----------+              v
   | Train    |-----> Model  |    | Test  | Train    |-----> Model
   | (source) |      +       |    | on    | +Align   |      |
   +----------+      |       +----+ target +----------+      |
                     |                                      |
   No target info    +---> Bad on target   Target unlabeled -+
One sentence: From “train once, hope it transfers” to “actively adapt the representation to the target domain, but only when the budget is thin and the domain gap is wide.”
Expert Assessment
Problem choice: This is a real gap. Practitioners using low‑resource EM need to know when to invest in domain alignment and when it backfires. The paper sits at the intersection of transfer learning and data integration—a sweet spot for empirical guidance.
Method maturity: The approach is purely empirical: ablating an existing framework. No new algorithm. The cleverness is in the experimental design: varying three factors (alignment strength, encoder quality, budget size) in a principled way. Could simpler baselines have been included? Yes—e.g., a plain BERT‑based matcher without any domain info—but the paper focuses on BEACON, so the omission is acceptable.
Experimental integrity: Baselines are fair: they compare against BEACON with each component removed. The numbers look solid, with standard deviations reported. No red flags, but one concern: all datasets are from the same benchmark family (Walmart‑Amazon, DBLP‑ACM, etc.). Results might not generalize to highly heterogeneous data (e.g., medical records vs. web forms).
Writing quality: The authors cut corners in the “Related Work” section—it’s too short and fails to situate BEACON within the broader domain adaptation literature. A rewritten section that explicitly contrasts BEACON with DANN, MMD‑based methods, and meta‑learning would elevate the paper significantly.
Verdict: weak accept — Useful, well‑executed ablation study that gives practical guidance, but lacks novelty in method and breadth in evaluation.
Takeaways
- Don’t always align: If your source and target domains are already similar (e.g., same schema with minor string variations), skip distribution alignment. It adds training cost and can degrade F1 by 2–5 points.
- Spend your budget on a good domain encoder first: A pretrained encoder with domain metadata (like BEACON’s contrastive approach) has a bigger impact than tuning MMD strength. If you can only choose one, invest in encoder pre‑training.
- Alignment is a lever for extremely low budgets (≤ 50 labeled target pairs): In that region, even modest MMD helps; beyond 100 pairs, the supervised signal dominates.
- Evaluate alignment strength as a hyperparameter: The paper shows that the optimal MMD weight varies per dataset. Practitioners should treat it like a regularization term and tune it with a small target validation set.
论文: 2606.27342 作者: Nicholas Pulsone, Gregory Goren, Roee Shraga 分类: cs.DB, cs.AI, cs.LG
缺口
现有的实体匹配方法从全监督单领域设定转向了低资源场景与领域自适应。 像Ditto、DeepMatcher以及最新的BEACON,都引入了领域信息(如列类型、模式)并对源域与目标域之间的分布进行对齐。 但没人系统地问过一个问题:这些组件在不同监督程度和不同数据预算下究竟如何发挥作用? 以往的评估将BEACON视为一个黑箱。 这篇论文拆开了黑箱,改变算法选择(如对齐强度、领域编码器设计)和数据可用条件(预算大小、标注策略),从而理解什么因素驱动了性能。
[ASCII逻辑拓扑:问题 -> 假设 -> 方法 -> 证据 -> 结论]

     现有EM在固定领域+大量标注上表现良好
         |
         v
 [问题] 低资源领域感知型EM理解不足:
         |      * 分布对齐行为如何?
         |      * 哪些算法选择最重要?
         |      * 在什么预算下对齐有帮助?
         v
 [假设] 领域感知对齐(如BEACON)在所有低资源设定下都能稳定提升性能
         |
         v
 [方法] 消融BEACON:改变对齐损失(MMD强度)、
         |   领域编码器(预训练 vs. 原始)、预算大小
         v
 [证据] 在4个EM数据集上进行定向实验,测量F1
         |   覆盖12种设定组合
         v
 [结论] 只有当源-目标域差距大且预算小时,对齐才有帮助;
         否则可能降低性能。领域编码器比对齐细节更重要。
增量
一句话: 这篇论文之前,BEACON是低资源实体匹配的一个黑盒工具;这篇论文之后,我们知道了应该调节哪些旋钮——以及何时不应该碰它们。
核心机制
BEACON是一个两阶段框架。 第一阶段:一个领域编码器接收每条记录(来自源域或目标域),生成领域感知的嵌入向量。 该编码器通过对比学习目标训练,将具有相似领域元数据(如同类型列)的记录对齐。 第二阶段:一个分布对齐模块最小化源域和目标域嵌入之间的差异(使用最大均值差异MMD)。 最终匹配头(一个简单分类器)在源域标注上训练,并在目标域上评估。
数据流:源域标注记录 + 目标域未标注记录 -> (1) 共享权重的领域编码器 -> 嵌入 -> (2) 对比损失 + (3) MMD对齐损失 -> (4) 在源域标注上训练匹配头。
[方法的ASCII图:组件、数据流、操作]

   源域标注             目标域未标注
        |                   |
        v                   v
   +----------+       +----------+
   | 编码器   |       | 编码器   |
   | 共享权重 |       | 共享权重 |
   +----------+       +----------+
        |                   |
        v                   v
   +----------+       +----------+
   | 嵌入向量 |       | 嵌入向量 |
   +----------+       +----------+
        \                 /
         \               /
          v             v
       +------------------+
       | 对齐模块 (MMD)   |
       +------------------+
                |
                v
       +------------------+
       | 匹配头           |
       | (源域标注训练)    |
       +------------------+
结构比喻:多语言警情调度
想象一个警情调度系统,必须匹配来自两个相邻城市的事件报告。 城市A(源域)使用正式语言:“交通堵塞 – 车辆45度倾斜。” 城市B(目标域)使用非正式方言:“车翻在了街角小店旁边。” 系统只有少量来自城市B的标注报告(预算)。
- 领域编码器:一个译者,通过学习大量报告模板(元数据)掌握两种城市方言。 它将”交通堵塞”和”车翻”映射到同一语义空间。
- 对比预训练:译者通过阅读配对进行练习:如果两条报告属于同一事件类型(都是交通事件),就让它们的嵌入靠近。
- 分布对齐:一个滤镜,抚平口音差异。 如果城市A的句子更长,滤镜就将城市A的嵌入压缩到与城市B的平均长度一致。
- 匹配头:一个调度员,判断来自A和B的两条报告是否指向同一真实事件。 仅在城市的标注报告上训练。
论文的实验就像在问:滤镜应该强还是弱?如果译者对城市B的方言了解一点,重要吗? 答案是:只有当方言差异很大且标注例数很少时,滤镜才有帮助。 如果方言相近,滤镜会引入噪声。 如果标注例数很多,调度员可以直接学习城市B的怪癖。
关键概念
-
分布对齐(MMD): 在实体匹配中,源域和目标域的数据特征分布往往不同(例如一个用缩写,另一个用全称)。 MMD在再生核希尔伯特空间中测量两组嵌入之间的距离。 最小化MMD迫使嵌入跨领域变得相似。 *具体例子: 源域嵌入集中在(0,0)附近,目标域嵌入集中在(1,1)附近。 MMD损失将目标域嵌入拉向(0,0),在匹配前对齐两组分布。
-
领域感知编码器: 一个网络,不仅接收文本本身,还接收其模式元数据(列名、数据类型)作为输入。 这使模型能够学会一个数据集中的”name”可能对应于另一个数据集中的”full_name”。 没有它,模型会将”name”和”full_name”视为无关词元。
-
预算有限实体匹配: 一种设定,其中只有有限数量的目标域记录可以被标注(例如50或100对)。 “预算”限制了匹配器从目标域获得的监督量。 本文在10到200个标注目标对的预算范围内变化,观察对齐与监督水平的互动。
框架转变
之前(主流方法):          之后(本文方法):
   仅在源域训练,            利用源域+目标域未标注数据,
   然后在目标域测试           在匹配前对齐分布

   源域标注 ----+               源域标注 --> 编码器 ----+
                 |                                       |
   +----------+  v    +----+    +----------+             v
   | 训练     | --> | 模型|    |    | 测试 | 训练+对齐 | --> 模型
   |(源域)  |      +    |    +----+       +----------+      |
   +----------+      |                     |                     |
                     |                     | 目标域未标注 -------+
   无目标域信息      +--> 目标域表现差
一句话:从”训练一次,希望它能迁移”到”主动使表征适应目标域,但仅在预算少且领域差异大时这么做。“
专家评审
选题眼光: 这是一个真缺口。 使用低资源实体匹配的实践者需要知道何时投资领域对齐、何时它反而有害。 该论文位于迁移学习与数据集成交汇处——实证指导的绝佳位置。
方法成熟度: 纯实证方法:对现有框架进行消融。 没有新算法。 巧妙之处在于实验设计:以有序的方式变化三个因素(对齐强度、编码器质量、预算大小)。 是否可以加入更简单的基线? 可以——例如普通BERT匹配器不加入领域信息——但本文聚焦于BEACON,因此省略可接受。
实验诚意: 基线公平:与移除各组件后的BEACON比较。 数字看起来扎实,报告了标准差。 没有危险信号,但有一个担忧:所有数据集来自同一基准测试(Walmart‑Amazon、DBLP‑ACM等)。 结果可能不适用于高度异构的数据(如医疗记录 vs. 网页表单)。
写作功力: 作者在”相关工作”部分偷懒了——太短,未能将BEACON放在领域自适应文献的更广泛背景中。 重写该部分,明确对比BEACON与DANN、MMD类方法和元学习,将大幅提升论文层次。
判决: 弱接收 —— 有用的、执行良好的消融研究,提供了实用指导,但在方法新颖度和评估广度上不足。
要点总结
- 不要总是对齐: 如果源域和目标域已经相似(例如相同模式,仅字符串微小差异),跳过分布对齐。 这会增加训练成本,并使F1下降2–5个点。
- 把预算花在好的领域编码器上: 预训练编码器加领域元数据(如BEACON的对比方法)比调整MMD强度影响更大。 如果只能选一项,投资在编码器预训练上。
- 对齐是非常低预算(不超过50个标注目标对)的杠杆: 在那片区域,即使是适度的MMD也有帮助;超过100对之后,监督信号占据主导。
- 将对齐强度视为超参数: 论文显示最优MMD权重因数据集而异。 实践者应像对待正则化项一样对待它,并用一个小型目标验证集进行调整。