Paper: 2605.30342 Authors: Shangjie Xue, Jesse Dill, Dhruv Ahuja, Frank Dellaert, Panagiotis Tsiotras, Danfei Xu Categories: cs.CV, cs.RO
The Gap
3D Gaussian Splatting (3DGS) has become a go-to method for fast, high-quality novel view synthesis. But there’s a blind spot: it doesn’t know what it doesn’t know. When you ask 3DGS to render a view from an angle it’s never seen during training, it confidently produces an image—even if that image is complete hallucination. This matters for robotics: if a robot is exploring an environment and building a 3D map, it needs to know which regions are reliable and which need more observation.
Prior work tried to bolt uncertainty onto 3DGS through various hacks—Monte Carlo dropout, ensemble methods, or depth-based heuristics. These approaches are either too slow for real-time use (ensemble methods), unprincipled (dropout wasn’t designed for this), or ignore the fundamental geometry of the problem (depth alone doesn’t tell you if a surface was actually observed from the training views). The core issue: 3DGS has no built-in notion of “visibility”—which training cameras actually saw which parts of the scene.
Problem: 3DGS hallucinates confidently in unseen regions
   |
   v
Assumption: Uncertainty correlates with visibility from training views
   |
   v
Method: Model anisotropic visibility field per Gaussian particle
   |
   v
Evidence: 200 FPS uncertainty estimation, better active mapping
   |
   v
Conclusion: Visibility-based uncertainty enables efficient exploration
The Increment
One sentence: Before GAVIS, 3DGS couldn’t tell you which parts of its reconstruction were guesses; after GAVIS, every rendered pixel comes with a real-time uncertainty estimate grounded in geometric visibility.
Core Mechanism
GAVIS adds a visibility field to each Gaussian particle in the 3DGS representation. For every particle, it tracks which directions have been observed by training cameras, represented as spherical harmonics (a compact way to encode directional functions on a sphere). During training, when a camera sees a particle, the visibility field for that particle gets updated in the direction of that camera. The result: each particle knows its “observation history”—which angles it’s been seen from and which angles are blind spots.
At inference time, when rendering a novel view, GAVIS computes uncertainty by checking how well the query view direction aligns with the visibility field of each particle. If you’re looking at a particle from a direction similar to training views, uncertainty is low. If you’re looking from a completely novel angle, uncertainty is high. This visibility-based uncertainty is integrated into a Bayesian network that propagates uncertainty through the rendering pipeline, accounting for occlusion and multi-particle contributions.
Training Phase:
Camera_i ---> observes ---> Gaussian_j
                              |
                              v
                    Update visibility field
                    (spherical harmonics)
                              |
                              v
                    Store directional coverage

Inference Phase:
Query view direction ---> compare ---> Visibility field
                                         |
                                         v
                              Compute uncertainty score
                                         |
                                         v
                              Bayesian rasterizer
                                         |
                                         v
                              RGB + Uncertainty map
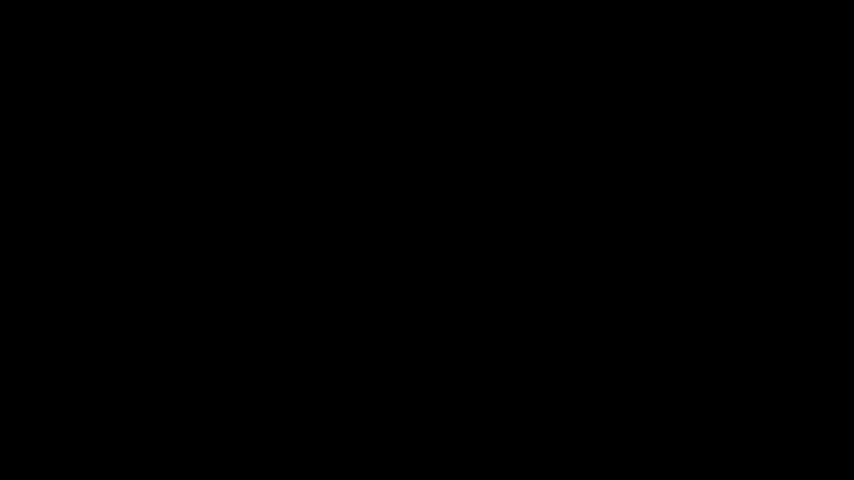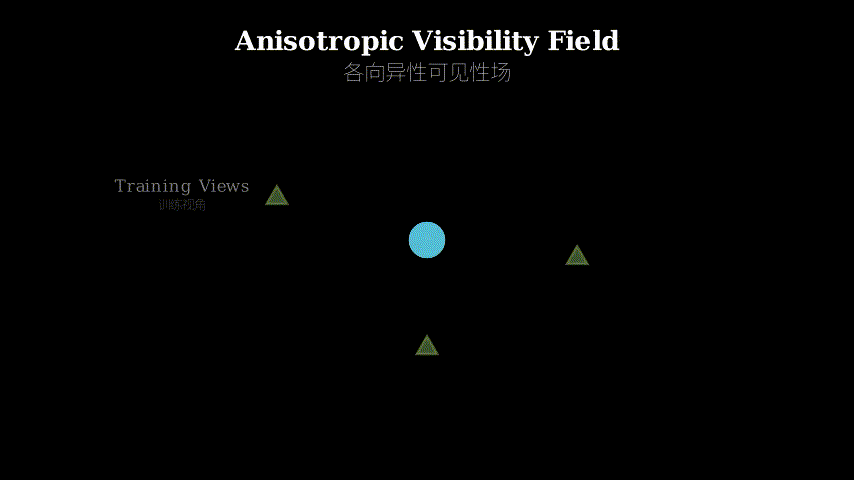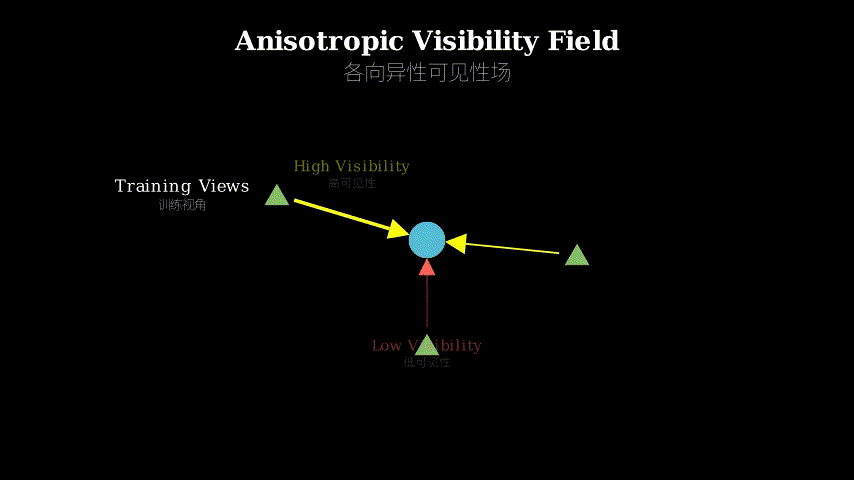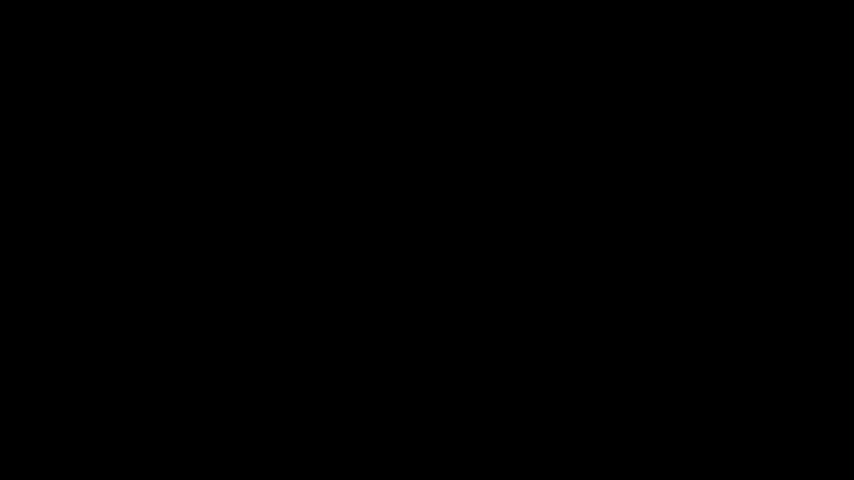
Think of it like a security camera network. Each Gaussian particle is a location in the scene, and the visibility field is a record of which cameras have line-of-sight to that location. When you want to know how confident you should be about what’s happening at a location, you check: “How many cameras can see this spot, and from what angles?” If it’s in a blind spot between cameras, your confidence should be low. GAVIS does exactly this, but for 3D reconstruction: it tracks which training views “covered” each particle, then uses that coverage to estimate uncertainty when rendering new views. The spherical harmonics are just a compact way to store “camera coverage from all directions” without needing a giant lookup table.
Key Concepts
-
Anisotropic Visibility Field: Imagine you’re standing in a room with cameras on the walls. Some parts of you are visible to many cameras (your front if cameras are in front), some parts to few (your back if no cameras are behind you). “Anisotropic” means direction-dependent—the visibility isn’t uniform in all directions. For each Gaussian particle, GAVIS stores a function that says “how well observed am I from direction θ, φ?” This function is represented using spherical harmonics (like Fourier series but on a sphere), which lets you compactly encode complex directional patterns. Concrete example: a particle on a wall might have high visibility from the room side (where cameras were) but zero visibility from inside the wall (where no cameras could be). This directional information is what lets GAVIS distinguish “I’m confident because I’ve seen this” from “I’m guessing because this was occluded.”
-
Bayesian Rasterization: Standard 3DGS rendering is deterministic—you get one RGB value per pixel. Bayesian rasterization treats each pixel’s color as a random variable with a distribution. As you accumulate contributions from multiple Gaussian particles (via alpha blending), you also accumulate uncertainty. If particles along a ray have high visibility (low uncertainty), the final pixel uncertainty is low. If particles are in blind spots (high uncertainty), that propagates to the pixel. The math uses a Bayesian network to properly combine uncertainties while respecting occlusion (particles behind other particles contribute less). The result: every pixel gets both a color and a confidence score, computed in real-time (200 FPS) because the visibility fields are precomputed during training.
Framework Shift
Before (standard 3DGS):              After (GAVIS):

Training views                       Training views
    |                                    |
    v                                    v
Optimize Gaussians                   Optimize Gaussians
(position, color, etc.)              + Visibility fields
    |                                    |
    v                                    v
Novel view query                     Novel view query
    |                                    |
    v                                    v
Render RGB                           Render RGB + Uncertainty
(no confidence info)                 (visibility-grounded)
    |                                    |
    v                                    v
Active mapping:                      Active mapping:
Use heuristics                       Use information gain
(depth, coverage)                    (principled uncertainty)
From blind confidence to informed uncertainty, the core shift is making visibility an explicit, queryable property of the 3D representation.
Expert Assessment
Problem choice: This is a real gap. 3DGS has exploded in popularity for robotics applications (SLAM, exploration, manipulation), but the lack of uncertainty quantification is a genuine blocker for deployment. The problem sits at the intersection of two hot areas (neural rendering and active perception), which is strategically smart. Not manufactured—this is something practitioners actually need.
Method maturity: The visibility field idea is elegant and geometrically principled. Using spherical harmonics is a clever choice—compact, differentiable, and well-suited for directional data. However, the Bayesian network formulation feels slightly over-engineered. The core insight (visibility → uncertainty) is simple; wrapping it in Bayesian machinery adds rigor but also complexity. A simpler baseline (e.g., just using visibility field magnitude as uncertainty) would strengthen the ablation. The active mapping component is standard information gain maximization—nothing novel there, but it’s the right framework.
Experimental integrity: Baselines are fair—they compare against recent uncertainty quantification methods (MC-dropout, ensembles) and active mapping approaches. The 200 FPS claim is impressive and well-documented. One red flag: the paper doesn’t deeply analyze failure modes. What happens in highly specular or transparent regions where visibility doesn’t correlate with uncertainty? The experiments are mostly in diffuse indoor scenes. Numbers look solid, but I’d want to see stress tests in challenging lighting or material conditions.
Writing quality: The paper is well-structured, but the method section is dense. The Bayesian network formulation could be explained more intuitively before diving into equations. The related work section is thorough but reads like a checklist—cutting it down and integrating key comparisons into the method section would improve flow. The experiments section is strong. If I were rewriting one part, it’d be the method section: lead with the intuition (visibility → uncertainty), show a toy example, then introduce the machinery.
Verdict: weak accept — Solid contribution with clear practical value, but the method complexity slightly outpaces the conceptual novelty. The visibility field is the real insight; the rest is competent execution.
Takeaways
Visibility as a first-class citizen: The idea of explicitly tracking and querying visibility in a 3D representation transfers beyond 3DGS. Any implicit or explicit 3D model (NeRF, voxel grids, meshes) could benefit from a visibility field. If you’re building a system that needs to reason about “what have I observed vs. what am I inferring,” bake visibility into the representation from the start.
Spherical harmonics for directional data: If you need to store a function over directions (lighting, visibility, sensor coverage), spherical harmonics are a compact, differentiable choice. They’re underused outside graphics—consider them for any problem involving directional distributions (e.g., antenna patterns, sensor placement, attention mechanisms over spatial directions).
Uncertainty for active learning: The active mapping framework here (maximize information gain using uncertainty) is textbook, but the execution is clean. If you’re doing any form of active data collection (robotics, experimental design, dataset curation), the pattern is: (1) build a model with uncertainty, (2) query where uncertainty is highest, (3) update model. GAVIS shows this works at 200 FPS, which opens doors for real-time active perception.
Post-hoc applicability: The paper mentions GAVIS can be applied post-hoc to existing 3DGS models. This is a strong practical feature—you don’t need to retrain from scratch. If you’re designing a method, consider whether it can augment existing systems without full retraining. It lowers adoption barriers significantly.
论文: 2605.30342 作者: Shangjie Xue, Jesse Dill, Dhruv Ahuja, Frank Dellaert, Panagiotis Tsiotras, Danfei Xu 分类: cs.CV, cs.RO
缺口
3D高斯溅射(3DGS)已成为快速、高质量新视角合成的首选方法。
但它有个盲区:它不知道自己不知道什么。
当你让3DGS从训练时从未见过的角度渲染视图时,它会自信地生成图像——即使那图像完全是幻觉。
这对机器人很重要:如果机器人在探索环境并构建3D地图,它需要知道哪些区域可靠,哪些需要更多观测。
先前工作试图通过各种技巧给3DGS加上不确定性——蒙特卡洛dropout、集成方法或基于深度的启发式。
这些方法要么对实时使用太慢(集成方法),要么缺乏原则(dropout不是为此设计的),要么忽略问题的基本几何(仅凭深度无法告诉你表面是否真的被训练视图观测到)。
核心问题:3DGS没有内置的”可见性”概念——哪些训练相机实际看到了场景的哪些部分。
问题:3DGS在未见区域自信地产生幻觉
   |
   v
假设:不确定性与训练视图的可见性相关
   |
   v
方法:为每个高斯粒子建模各向异性可见性场
   |
   v
证据:200 FPS不确定性估计,更好的主动建图
   |
   v
结论:基于可见性的不确定性实现高效探索
增量
一句话:GAVIS之前,3DGS无法告诉你重建的哪些部分是猜测;GAVIS之后,每个渲染像素都带有基于几何可见性的实时不确定性估计。
核心机制
GAVIS为3DGS表示中的每个高斯粒子添加了可见性场。
对于每个粒子,它跟踪哪些方向被训练相机观测过,用球谐函数表示(一种在球面上编码方向函数的紧凑方式)。
训练时,当相机看到一个粒子,该粒子的可见性场在相机方向上得到更新。
结果:每个粒子知道自己的”观测历史”——从哪些角度被看到过,哪些角度是盲区。
推理时,渲染新视图时,GAVIS通过检查查询视图方向与每个粒子可见性场的对齐程度来计算不确定性。
如果你从与训练视图相似的方向看粒子,不确定性低。
如果从完全新颖的角度看,不确定性高。
这种基于可见性的不确定性被集成到贝叶斯网络中,该网络通过渲染管线传播不确定性,考虑遮挡和多粒子贡献。
训练阶段:
相机_i ---> 观测 ---> 高斯_j
                        |
                        v
                  更新可见性场
                  (球谐函数)
                        |
                        v
                  存储方向覆盖

推理阶段:
查询视图方向 ---> 比较 ---> 可见性场
                              |
                              v
                    计算不确定性分数
                              |
                              v
                    贝叶斯光栅化器
                              |
                              v
                    RGB + 不确定性图
把它想象成一个监控摄像头网络。
每个高斯粒子是场景中的一个位置,可见性场是哪些摄像头对该位置有视线的记录。
当你想知道对某个位置发生的事情应该有多自信时,你检查:“有多少摄像头能看到这个点,从什么角度?“如果它在摄像头之间的盲区,你的信心应该低。
GAVIS正是这样做的,但用于3D重建:它跟踪哪些训练视图”覆盖”了每个粒子,然后在渲染新视图时使用该覆盖来估计不确定性。
球谐函数只是一种紧凑的方式来存储”来自所有方向的摄像头覆盖”,而不需要巨大的查找表。
关键概念
- 各向异性可见性场:想象你站在一个墙上有摄像头的房间里。
你的某些部分对许多摄像头可见(如果摄像头在前面,你的正面),某些部分对少数可见(如果后面没有摄像头,你的背面)。
“各向异性”意味着方向依赖——可见性在所有方向上不均匀。
对于每个高斯粒子,GAVIS存储一个函数,表示”从方向θ、φ我被观测得有多好?“这个函数用球谐函数表示(类似球面上的傅里叶级数),让你能紧凑地编码复杂的方向模式。
具体例子:墙上的粒子可能从房间侧(摄像头所在处)有高可见性,但从墙内(没有摄像头能到达的地方)可见性为零。
这种方向信息让GAVIS能区分”我有信心因为我见过这个”和”我在猜测因为这被遮挡了”。
- 贝叶斯光栅化:标准3DGS渲染是确定性的——每个像素得到一个RGB值。
贝叶斯光栅化将每个像素的颜色视为具有分布的随机变量。
当你累积来自多个高斯粒子的贡献(通过alpha混合)时,你也累积不确定性。
如果沿射线的粒子有高可见性(低不确定性),最终像素不确定性低。
如果粒子在盲区(高不确定性),这会传播到像素。
数学使用贝叶斯网络来正确组合不确定性,同时尊重遮挡(其他粒子后面的粒子贡献较少)。
结果:每个像素都得到颜色和置信度分数,实时计算(200 FPS),因为可见性场在训练期间预先计算。
框架转变
之前(标准3DGS):                之后(GAVIS):

训练视图                          训练视图
    |                                |
    v                                v
优化高斯                          优化高斯
(位置、颜色等)                  + 可见性场
    |                                |
    v                                v
新视图查询                        新视图查询
    |                                |
    v                                v
渲染RGB                           渲染RGB + 不确定性
(无置信度信息)                  (基于可见性)
    |                                |
    v                                v
主动建图:                        主动建图:
使用启发式                        使用信息增益
(深度、覆盖)                    (有原则的不确定性)
从盲目自信到知情不确定性,核心转变是使可见性成为3D表示的显式、可查询属性。
专家评审
选题眼光:这是真缺口。
3DGS在机器人应用(SLAM、探索、操作)中爆炸式增长,但缺乏不确定性量化是部署的真正障碍。
问题位于两个热门领域(神经渲染和主动感知)的交叉点,战略上很聪明。
不是人造的——这是实践者真正需要的。
方法成熟度:可见性场想法优雅且几何上有原则。
使用球谐函数是聪明的选择——紧凑、可微分,适合方向数据。
然而,贝叶斯网络公式感觉略微过度工程化。
核心洞察(可见性→不确定性)很简单;用贝叶斯机制包装它增加了严谨性但也增加了复杂性。
一个更简单的基线(例如,仅使用可见性场幅度作为不确定性)会加强消融。
主动建图组件是标准的信息增益最大化——那里没有新颖之处,但这是正确的框架。
实验诚意:基线公平——他们与最近的不确定性量化方法(MC-dropout、集成)和主动建图方法进行比较。
200 FPS的声明令人印象深刻且有充分记录。
一个警示:论文没有深入分析失败模式。
在高度镜面或透明区域会发生什么,那里可见性与不确定性不相关?实验主要在漫反射室内场景中。
数字看起来扎实,但我想看到在具有挑战性的照明或材料条件下的压力测试。
写作功力:论文结构良好,但方法部分密集。
贝叶斯网络公式在深入方程之前可以更直观地解释。
相关工作部分很全面但读起来像清单——削减它并将关键比较整合到方法部分会改善流程。
实验部分很强。
如果我重写一部分,那会是方法部分:先引导直觉(可见性→不确定性),展示一个玩具例子,然后引入机制。
判决:弱接收 — 具有明确实用价值的扎实贡献,但方法复杂性略微超过概念新颖性。
可见性场是真正的洞察;其余是称职的执行。
要点总结
可见性作为一等公民:在3D表示中显式跟踪和查询可见性的想法超越了3DGS。
任何隐式或显式3D模型(NeRF、体素网格、网格)都可以从可见性场中受益。
如果你正在构建一个需要推理”我观测到了什么vs我在推断什么”的系统,从一开始就将可见性烘焙到表示中。
球谐函数用于方向数据:如果你需要存储方向上的函数(照明、可见性、传感器覆盖),球谐函数是紧凑、可微分的选择。
它们在图形学之外使用不足——考虑将它们用于涉及方向分布的任何问题(例如,天线模式、传感器放置、空间方向上的注意力机制)。
不确定性用于主动学习:这里的主动建图框架(使用不确定性最大化信息增益)是教科书式的,但执行干净。
如果你在做任何形式的主动数据收集(机器人、实验设计、数据集策划),模式是:(1)构建具有不确定性的模型,(2)查询不确定性最高的地方,(3)更新模型。
GAVIS显示这在200 FPS下工作,这为实时主动感知打开了大门。
事后适用性:论文提到GAVIS可以事后应用于现有3DGS模型。
这是一个强大的实用功能——你不需要从头重新训练。
如果你在设计一个方法,考虑它是否可以在不完全重新训练的情况下增强现有系统。
它显著降低了采用障碍。