Paper: 2604.09442 Authors: Dasen Dai, Shuoqi Li, Ronghao Chen, Huacan Wang, Biao Wu, Qizhen Lan Categories: cs.CL
The Gap
UI-to-Code generation is a token-hungry task: a single screenshot becomes thousands of HTML/CSS tokens. Vision-language models (VLMs) must process massive visual token sequences, creating a latency bottleneck. Prior work tried two approaches, both incomplete. First, inference-time token selection uses task-agnostic heuristics (like attention-based pruning) that don’t adapt to UI structure—they’re generic, not smart. Second, zero-out methods reduce feature magnitude without actually shortening sequences, so prefill latency stays high. Neither truly compresses. Meanwhile, optical compression (learned compression in the encoder) has proven effective for document OCR, but nobody had adapted this paradigm to UI-to-Code. The gap: a learned, task-aware compression method that actually shortens the visual token sequence while preserving UI-critical information.
Problem: VLM processes ~6,700 visual tokens
         |
         v
Assumption: Learned compression can adapt to UI structure
         |
         v
Method: Depthwise-separable convolutions + spatial reweighting
         |
         v
Evidence: 256 tokens match uncompressed quality + 9.1x speedup
         |
         v
Conclusion: Encoder-side compression beats inference-time methods
The Increment
One sentence: Before this paper, UI-to-Code relied on inference-time token selection or zeroing; after, learned encoder-side compression becomes the standard, cutting latency by 9× while improving accuracy.
Core Mechanism
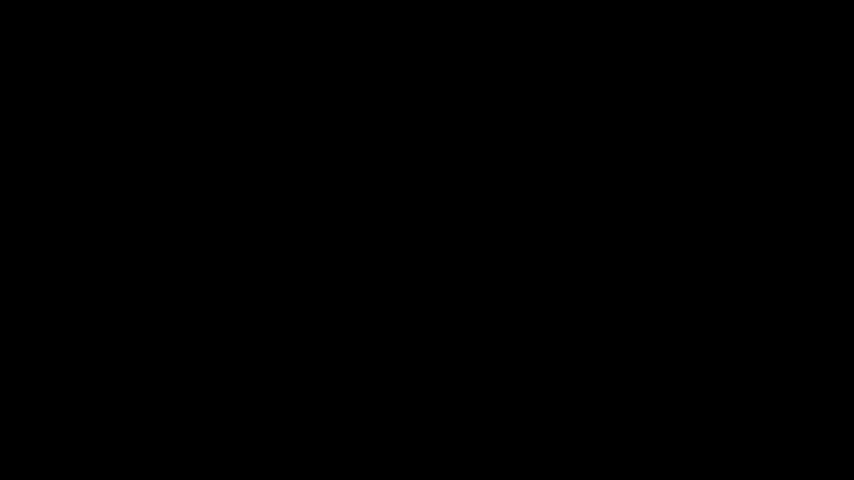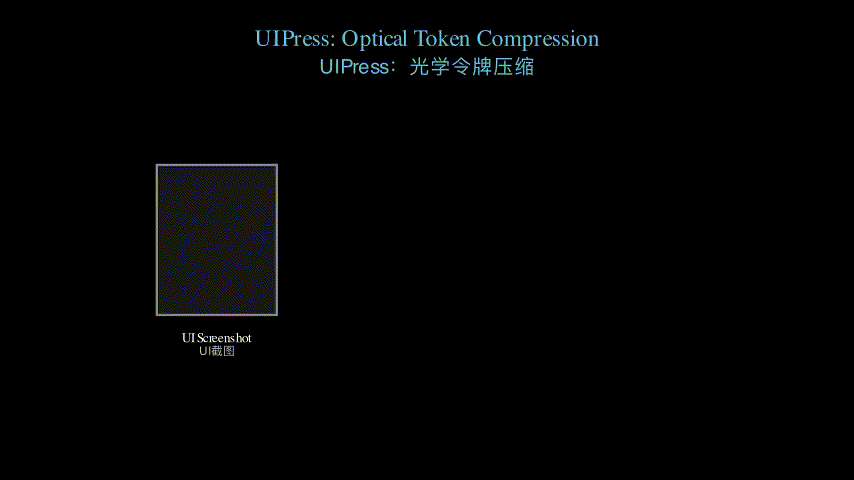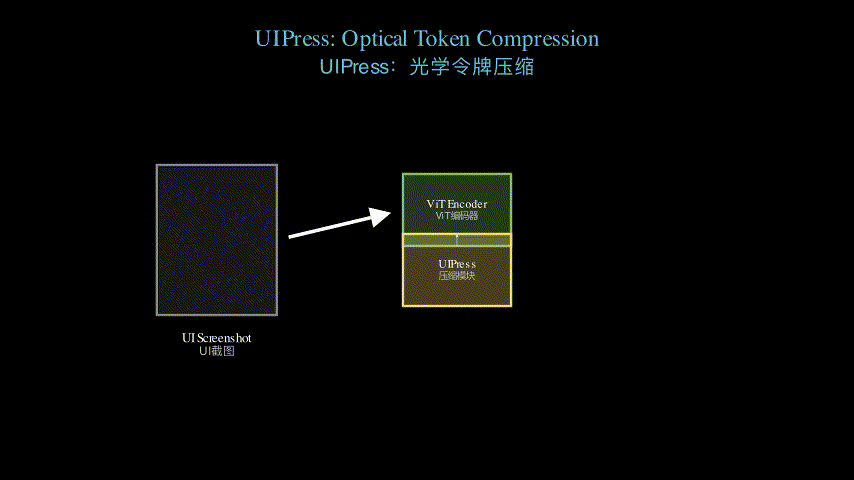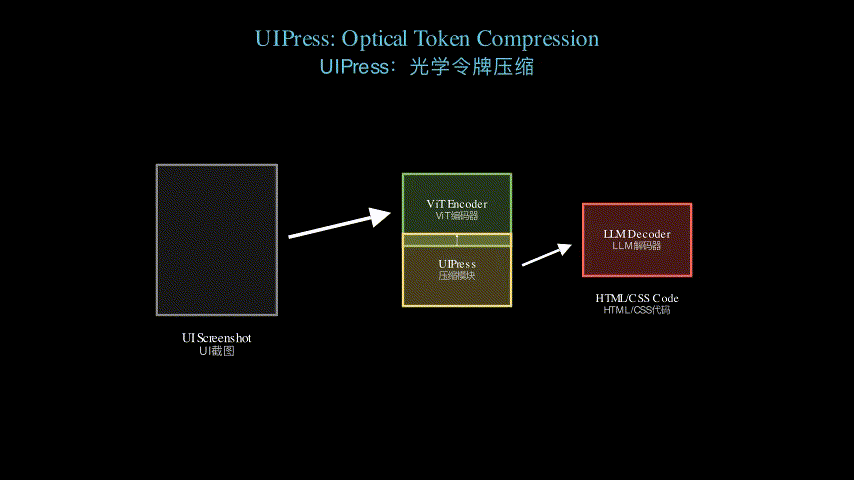
UIPress sits between the frozen ViT encoder and the LLM decoder. It receives ~6,700 visual tokens from the encoder and compresses them to a fixed 256-token budget. The compression pipeline has three stages working in sequence.
First, depthwise-separable convolutions reduce spatial redundancy. These are lightweight convolutions that process each channel independently, then combine results—they’re efficient because they avoid the full cross-channel computation of standard convolutions. Second, element-guided spatial reweighting learns which regions of the UI matter most. The module computes attention-like weights that upweight UI elements (buttons, text, forms) and downweight background noise. Third, a Transformer refinement layer takes the compressed tokens and refines them, allowing cross-token communication to recover lost context. The entire module adds only 21.7M trainable parameters (0.26% of the 8B base model), so it’s a surgical insertion, not a model overhaul.
On the decoder side, Low-Rank Adaptation (LoRA) bridges the representation gap. The compressed tokens have a different distribution than the original 6,700 tokens, so LoRA fine-tunes the LLM’s attention and feed-forward layers to adapt to this new input space without retraining the full model.
ViT Encoder (~6,700 tokens)
         |
         v
Depthwise-Separable Conv (spatial redundancy reduction)
         |
         v
Element-Guided Spatial Reweighting (UI-aware importance)
         |
         v
Transformer Refinement (cross-token context recovery)
         |
         v
256 compressed tokens
         |
         v
LLM Decoder + LoRA (representation adaptation)
         |
         v
HTML/CSS output
Think of UIPress as a museum curator selecting artifacts for a traveling exhibition. The ViT encoder gives you 6,700 artifacts (visual tokens). The curator’s job is to pick 256 that tell the story best. Depthwise-separable convolutions are the curator’s first pass—they group similar artifacts together, removing duplicates. Element-guided spatial reweighting is the curator’s eye for what matters: they know a rare painting (UI button) is more important than a common frame (background). The Transformer refinement is the curator’s final curation—they arrange the 256 selected pieces so they still make narrative sense together. Finally, the museum visitor (LLM decoder) needs to learn how to interpret this curated collection, which is what LoRA does. The visitor’s brain adapts to the new layout, understanding that fewer pieces still convey the full story.
Key Concepts
-
Optical Compression: Compression learned during training (encoder-side), not applied at inference time. The model learns which visual information is task-critical and which is noise. Unlike inference-time methods that use fixed heuristics, optical compression adapts to the specific task (UI-to-Code) and dataset. Think of it as training your eye to see what matters, versus squinting at everything equally.
-
Depthwise-Separable Convolutions: A factorization trick that splits a standard convolution into two lightweight operations: one per-channel (depthwise) and one cross-channel (pointwise). Standard convolutions are expensive because they compute all channel interactions at once. Depthwise-separable does it in two cheaper steps. For a 256×256 image with 768 channels, standard convolution costs ~150M operations; depthwise-separable costs ~20M. Same output, 7× cheaper.
-
Element-Guided Spatial Reweighting: A learned attention mechanism that assigns importance weights to different spatial regions of the UI. A button region gets high weight; empty space gets low weight. This is UI-aware, not generic—it learns that UI elements are information-dense and backgrounds are noise. The module learns these weights during training, so it adapts to the specific UI design patterns in the training data.
Framework Shift
Before (mainstream approach):        After (this paper):
Screenshot                           Screenshot
    |                                    |
    v                                    v
ViT Encoder                          ViT Encoder
    |                                    |
    v                                    v
6,700 visual tokens                  Learned Compression
    |                                    |
    v                                    v
LLM Decoder                          256 visual tokens
    |                                    |
    v                                    v
HTML/CSS                             LLM Decoder + LoRA
                                         |
                                         v
                                     HTML/CSS

Inference-time selection or          Encoder-side learned
zeroing (task-agnostic)              compression (task-aware)
High latency, generic heuristics     Low latency, adaptive
From inference-time token selection to encoder-side learned compression, the core shift is: stop filtering tokens at the last moment; learn to compress them intelligently from the start.
Expert Assessment
Problem choice: This is a real gap. UI-to-Code is a production bottleneck—companies care about latency. Inference-time methods are the current standard, but they’re crude. Optical compression for OCR proved the concept works; adapting it to UI-to-Code is a natural next step. The problem sits at the intersection of practical need and methodological opportunity. Strong framing.
Method maturity: The approach is pragmatic, not flashy. Depthwise-separable convolutions are standard (not novel), spatial reweighting is straightforward attention, Transformer refinement is boilerplate. The novelty is in the combination and the task adaptation, not in individual components. This is actually a strength—the method is reproducible and implementable. No exotic tricks. The LoRA bridge is sensible but feels slightly ad-hoc; a deeper analysis of why the representation gap exists would strengthen this.
Experimental integrity: The comparison is fair—all methods use the same base model (Qwen3-VL-8B). The 9.1× speedup is measured on the same hardware, so it’s not a cherry-picked metric. The CLIP score improvement (+7.5% over uncompressed, +4.6% over the strongest baseline) is solid. One concern: the paper doesn’t report inference-time latency in absolute terms (milliseconds), only relative speedup. Absolute numbers would let readers judge if 9.1× speedup is enough for their use case. Also, the paper doesn’t compare against other learned compression methods (e.g., knowledge distillation, pruning-aware training), only against inference-time baselines. A comparison with other encoder-side methods would strengthen the claim of novelty.
Writing quality: The abstract is dense but clear. The method section is well-structured. One weakness: the paper doesn’t deeply explain *why element-guided spatial reweighting works better than uniform compression. An ablation showing the contribution of each component (convolutions, reweighting, refinement) would help readers understand what’s doing the heavy lifting. The related work section could better position this against optical compression in other domains.
Verdict: Strong accept — This paper solves a real problem with a pragmatic, reproducible method. The 9.1× speedup with quality improvement is compelling. It’s not groundbreaking (components are standard), but it’s the first to combine them for UI-to-Code, and it works. The experimental setup is fair, and the results are convincing. This is the kind of paper that gets deployed.
Takeaways
-
Learned compression beats heuristic selection: If you’re building a latency-critical system with large token sequences, consider encoder-side learned compression over inference-time filtering. The task-awareness pays off.
-
Spatial reweighting is underrated: For vision tasks with non-uniform information density (UIs, documents, medical images), learning to weight regions differently is cheap and effective. Don’t treat all spatial regions equally.
-
Depthwise-separable convolutions are your friend: When you need to compress high-dimensional data (like visual tokens) without blowing up parameter count, depthwise-separable convolutions give you 7-10× efficiency gains. Use them.
-
LoRA for representation adaptation: When you compress inputs to a model, the downstream layers see a different distribution. LoRA is a lightweight way to adapt without retraining. This pattern transfers to other compression scenarios.
-
Fixed-budget compression is practical: Instead of variable-length compression, fixing the output to 256 tokens makes deployment simpler (no dynamic shapes, easier batching). If you’re compressing for production, consider fixed budgets.
论文: 2604.09442 作者: Dasen Dai, Shuoqi Li, Ronghao Chen, Huacan Wang, Biao Wu, Qizhen Lan 分类: cs.CL
缺口
UI转代码生成是个令牌饥渴的任务:一张截图变成数千个HTML/CSS令牌。 视觉语言模型(VLM)必须处理海量视觉令牌序列,造成延迟瓶颈。 此前的工作尝试了两种方法,都不完整。 第一种,推理时令牌选择用任务无关的启发式方法(如基于注意力的剪枝),不适应UI结构——太通用,不够聪明。 第二种,零化方法降低特征幅度但不缩短序列,所以预填充延迟依然很高。 两者都没真正压缩。 与此同时,光学压缩(编码器端的学习型压缩)在文档OCR中已证明有效,但没人把这套范式用到UI转代码。 缺口就在这里:一个学习型、任务感知的压缩方法,既能真正缩短视觉令牌序列,又能保留UI关键信息。
问题:VLM处理约6700个视觉令牌
      |
      v
假设:学习型压缩能适应UI结构
      |
      v
方法:深度可分离卷积+空间重加权
      |
      v
证据:256个令牌匹配未压缩质量+9.1倍加速
      |
      v
结论:编码器端压缩胜过推理时方法
增量
一句话: 这篇论文之前,UI转代码依赖推理时令牌选择或零化;之后,学习型编码器端压缩成为标准,延迟降低9倍同时精度提升。
核心机制
UIPress夹在冻结的ViT编码器和LLM解码器之间。 它接收编码器的约6700个视觉令牌,压缩到固定的256令牌预算。 压缩管道分三个阶段依次工作。
首先,深度可分离卷积降低空间冗余。 这些是轻量级卷积,独立处理每个通道,再合并结果——效率高因为避免了标准卷积的全通道计算。 其次,元素引导的空间重加权学习UI的哪些区域最重要。 模块计算类似注意力的权重,提升UI元素(按钮、文本、表单)的权重,压低背景噪声。 第三,Transformer精化层接收压缩后的令牌并精化它们,允许跨令牌通信来恢复丢失的上下文。 整个模块只增加21.7M可训练参数(基础8B模型的0.26%),是外科手术式的插入,不是模型大改造。
在解码器端,低秩适配(LoRA)桥接表示差异。 压缩后的令牌分布与原始6700个令牌不同,所以LoRA微调LLM的注意力和前馈层来适应这个新输入空间,无需重训整个模型。
ViT编码器(约6700个令牌)
         |
         v
深度可分离卷积(空间冗余降低)
         |
         v
元素引导空间重加权(UI感知重要性)
         |
         v
Transformer精化(跨令牌上下文恢复)
         |
         v
256个压缩令牌
         |
         v
LLM解码器+LoRA(表示适配)
         |
         v
HTML/CSS输出
把UIPress想象成博物馆策展人为巡展选择展品。 ViT编码器给你6700件展品(视觉令牌)。 策展人的工作是选出256件最能讲好故事的。 深度可分离卷积是策展人的第一遍筛选——把相似展品分组,去掉重复。 元素引导空间重加权是策展人的眼光:他们知道稀有画作(UI按钮)比普通相框(背景)重要。 Transformer精化是策展人的最终策展——他们排列这256件选中的作品,让它们仍然讲得通故事。 最后,博物馆访客(LLM解码器)需要学会如何理解这个策展的集合,这就是LoRA做的事。 访客的大脑适应新布局,理解更少的作品仍能传达完整故事。
关键概念
-
光学压缩:训练期间学到的压缩(编码器端),不是推理时应用。 模型学会哪些视觉信息是任务关键的,哪些是噪声。 不像推理时方法用固定启发式,光学压缩适应特定任务(UI转代码)和数据集。 想象成训练你的眼睛看什么重要,而不是对所有东西都眯眼看。
-
深度可分离卷积:一个分解技巧,把标准卷积拆成两个轻量级操作:逐通道(深度)和跨通道(逐点)。 标准卷积贵因为一次计算所有通道交互。 深度可分离分两步便宜地做。 对256×256图像768个通道,标准卷积成本约1.5亿次操作;深度可分离约2000万次。 输出相同,便宜7倍。
-
元素引导空间重加权:一个学习型注意力机制,给UI的不同空间区域分配重要性权重。 按钮区域得高权重;空白区域得低权重。 这是UI感知的,不是通用的——它学会UI元素信息密集,背景是噪声。 模块在训练期间学这些权重,所以适应训练数据中的特定UI设计模式。
框架转变
之前(主流方法):                之后(本文方法):
截图                              截图
  |                                  |
  v                                  v
ViT编码器                          ViT编码器
  |                                  |
  v                                  v
6700个视觉令牌                    学习型压缩
  |                                  |
  v                                  v
LLM解码器                          256个视觉令牌
  |                                  |
  v                                  v
HTML/CSS                           LLM解码器+LoRA
                                       |
                                       v
                                   HTML/CSS

推理时选择或零化                  编码器端学习型
(任务无关)                      压缩(任务感知)
高延迟,通用启发式                低延迟,自适应
从推理时令牌选择到编码器端学习型压缩,核心转变是:别在最后一刻过滤令牌;从一开始就聪明地学会压缩它们。
专家评审
选题眼光: 这是真缺口。 UI转代码是生产瓶颈——公司关心延迟。 推理时方法是现在的标准,但太粗糙。 光学压缩在OCR中证明了概念可行;适配到UI转代码是自然的下一步。 问题处在实际需求和方法论机遇的交点。 选题眼光敏锐。
方法成熟度: 方法务实,不花哨。 深度可分离卷积是标准的(不新颖),空间重加权很直接,Transformer精化是样板。 新颖性在组合和任务适配,不在单个组件。 这其实是优点——方法可复现、可实现。 没有奇技淫巧。 LoRA桥接感觉略显临时;更深入分析为什么表示差异存在会加强这部分。
实验诚意: 对比公平——所有方法用同一基础模型(Qwen3-VL-8B)。 9.1倍加速在同一硬件上测,不是樱桃采摘的指标。 CLIP分数提升(相比未压缩+7.5%,相比最强基线+4.6%)扎实。 一个顾虑:论文没报推理时延迟的绝对值(毫秒),只报相对加速。 绝对数字能让读者判断9.1倍加速对他们的用例够不够。 另外,论文没对比其他学习型压缩方法(如知识蒸馏、剪枝感知训练),只对比推理时基线。 与其他编码器端方法对比会加强新颖性声明。
写作功力: 摘要密集但清晰。 方法章节结构好。 一个弱点:论文没深入解释为什么元素引导空间重加权比均匀压缩更好。 一个消融实验展示每个组件的贡献(卷积、重加权、精化)会帮读者理解什么在做重活。 相关工作章节可以更好地把这个工作与其他领域的光学压缩定位。
判决: 强接收 — 这篇论文解决真问题,用务实、可复现的方法。 9.1倍加速加质量提升很有说服力。 不是突破性的(组件都是标准的),但首次为UI转代码组合它们,而且有效。 这是那种会被部署的论文。 实验设置公平,结果令人信服。
要点总结
-
学习型压缩胜过启发式选择:如果你在构建延迟关键的系统,处理大令牌序列,考虑编码器端学习型压缩而不是推理时过滤。 任务感知会有回报。
-
空间重加权被低估了:对信息密度不均的视觉任务(UI、文档、医学影像),学会对区域差异加权既便宜又有效。 别把所有空间区域一视同仁。
-
深度可分离卷积是你的朋友:需要压缩高维数据(如视觉令牌)又不想爆参数量,深度可分离卷积给你7-10倍效率收益。 用它。
-
LoRA用于表示适配:压缩输入到模型时,下游层看到不同分布。 LoRA是轻量级适配方式,无需重训。 这个模式迁移到其他压缩场景。
-
固定预算压缩很实用:与其变长压缩,固定256令牌输出让部署更简单(无动态形状,批处理更容易)。 生产环境压缩,考虑固定预算。