Paper: 2604.14113 Authors: Fei Tang, Bofan Chen, Zhengxi Lu, Tongbo Chen, Songqin Nong, Tao Jiang, Wenhao Xu, Weiming Lu, Jun Xiao, Yueting Zhuang Categories: cs.CV, cs.AI, cs.CL
The Gap
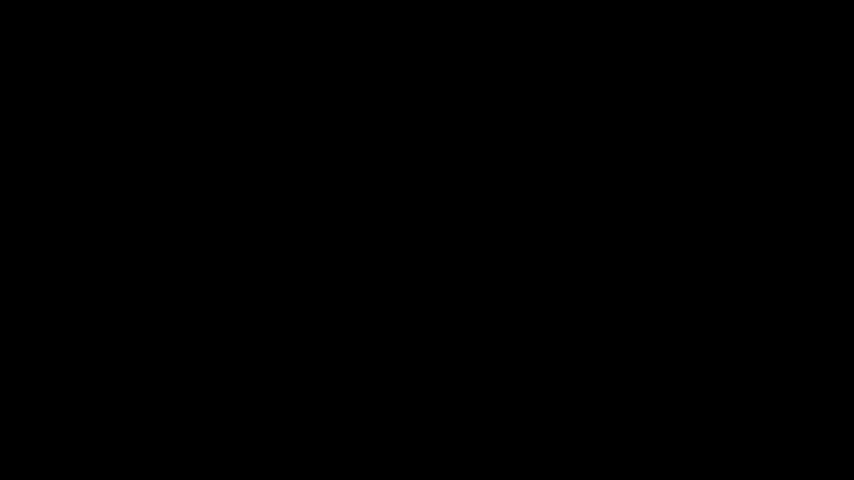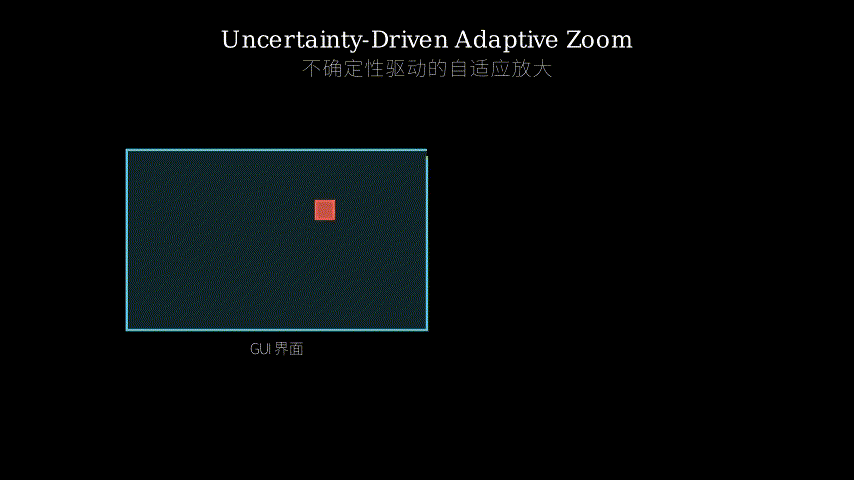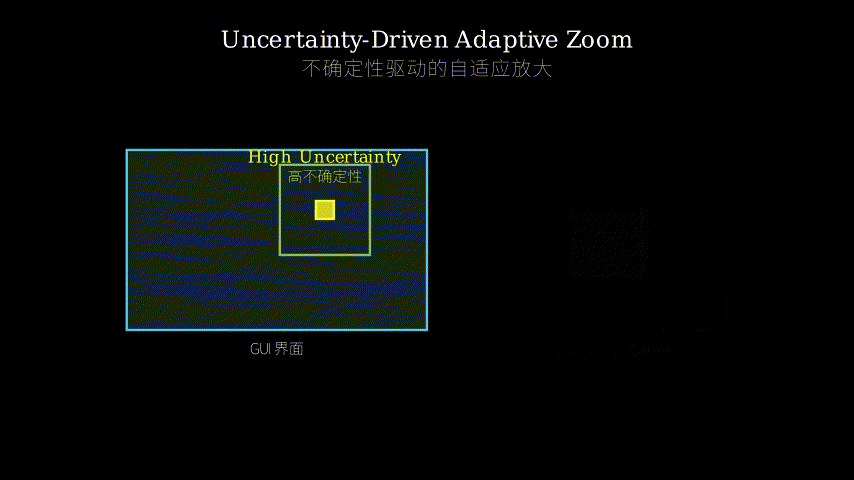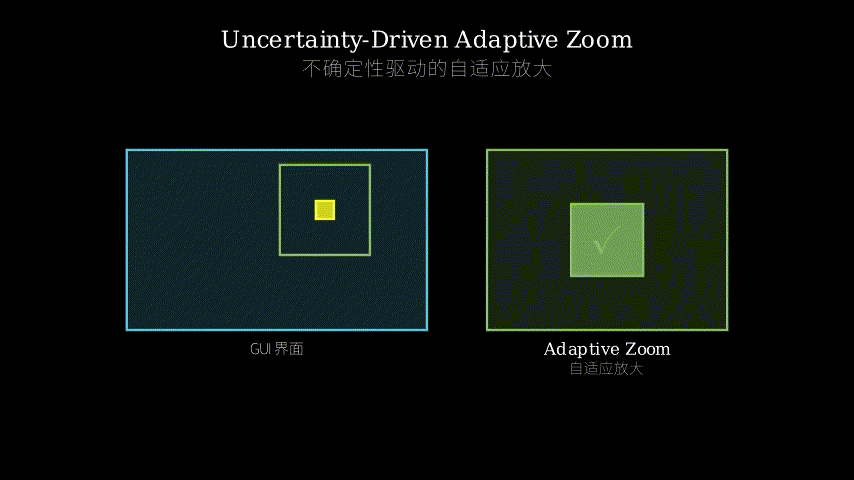
GUI grounding models locate interface elements from natural language queries. They struggle with small icons and dense layouts where pixels matter. Existing zoom-in methods crop and re-run inference at higher resolution, but they zoom uniformly on every instance with fixed crop sizes. This wastes computation on easy cases where the model is already confident, and uses the wrong crop size for hard cases where uncertainty varies. The core problem: treating zoom-in as a fixed recipe rather than an adaptive response to model uncertainty.
Problem: Small icons + dense layouts = poor localization
         |
         v
Prior approach: Uniform zoom-in (fixed trigger + fixed crop size)
         |
         +---> Wastes compute on confident predictions
         +---> Wrong crop size for varying uncertainty
         |
         v
This paper: Adaptive zoom-in (uncertainty-gated + variance-driven sizing)
         |
         +---> Trigger: Spatial consensus + token confidence
         +---> Crop size: Decompose variance into spread + extent
         |
         v
Evidence: +13.4% on ScreenSpot-Pro, +10.3% on UI-Vision, +4.2% on ScreenSpot-v2
         |
         v
Conclusion: Treating zoom-in as uncertainty quantification improves efficiency and accuracy
The Increment
One sentence: Before this paper, zoom-in was a blunt instrument applied everywhere; after, it’s a precision tool deployed only where the model hesitates and scaled to match the uncertainty.
Core Mechanism
UI-Zoomer has two decision modules. First, a confidence-aware gate decides whether to zoom. It runs inference multiple times with dropout to get stochastic predictions, measures spatial consensus (how much the predicted boxes agree), and fuses this with token-level generation confidence. If both signals indicate uncertainty, zoom-in triggers. Second, an uncertainty-driven crop sizing module determines the crop radius. It decomposes prediction variance using the law of total variance: inter-sample spread (how far apart the predicted box centers are) plus intra-sample extent (how large each predicted box is). The crop radius is computed from these two variance components to ensure the zoomed region captures the uncertain area.
Input: Screenshot + Query
         |
         v
    [Base Model]----> Prediction_1, Prediction_2, ..., Prediction_N
         |                    |
         |                    v
         |            Spatial Consensus (box overlap)
         |                    +
         |            Token Confidence (generation score)
         |                    |
         v                    v
    Confident?          [Gate Decision]
         |                    |
         NO                  YES (uncertain)
         |                    |
         v                    v
    Return base          Compute variance:
    prediction           - Inter-sample spread (center positions)
                         - Intra-sample extent (box sizes)
                              |
                              v
                         Crop radius = f(spread, extent)
                              |
                              v
                         Crop + Zoom + Re-inference
                              |
                              v
                         Final prediction
Think of UI-Zoomer as a photographer with a zoom lens. The photographer takes a test shot (base inference). If the subject is blurry and the photographer’s hand shakes (spatial consensus is low and confidence is low), they decide to zoom in. But how much? They look at two things: how much their hand shook between test shots (inter-sample spread) and how big the blurry subject appears (intra-sample extent). A small subject with lots of shake needs a tighter zoom; a large subject with little shake needs less. The photographer computes the zoom level from these two factors, takes the zoomed shot, and gets a sharp image. The key insight: both the decision to zoom and the zoom level come from measuring uncertainty, not from fixed rules.
Key Concepts
-
Spatial Consensus: Imagine you ask five people to point at the same small button on a screen. If their fingers land in roughly the same spot, you have high spatial consensus—the button’s location is clear. If their fingers scatter across the screen, consensus is low—nobody’s sure where it is. UI-Zoomer runs the model multiple times with dropout (like asking multiple people) and measures how much the predicted bounding boxes overlap. Low overlap means the model is uncertain about the location, triggering zoom-in. This is different from just checking if the model’s confidence score is low; a model can be confidently wrong. Spatial consensus checks if the model is consistently pointing at the same place.
-
Law of Total Variance Decomposition: When you measure how spread out predictions are, you can split that spread into two sources. First, inter-sample variance: how much do the predicted box centers differ from each other? Second, intra-sample variance: how large is each predicted box (a large box means the model thinks the element could be anywhere within that box)? The law of total variance says: total uncertainty = between-prediction scatter + within-prediction fuzziness. UI-Zoomer uses this to set crop size. If predictions scatter widely (high inter-sample variance), you need a large crop to capture all candidate locations. If each prediction is a large box (high intra-sample variance), you also need a large crop to cover the fuzzy extent. The math gives you a principled way to compute crop radius from these two components.
-
Training-Free Adaptation: Most methods that improve model performance require retraining on new data or fine-tuning with additional parameters. UI-Zoomer is training-free—it wraps around any existing GUI grounding model without modifying weights. It’s like adding a magnifying glass to a camera; the camera itself doesn’t change, but you get better photos of small objects. This matters because you can apply UI-Zoomer to new models as they come out, or use it when you don’t have training data or compute budget for retraining. The trade-off: you pay in inference time (running the model multiple times and doing a second pass on crops) instead of training time.
Framework Shift
Before (mainstream approach):        After (this paper):

Screenshot + Query                   Screenshot + Query
       |                                    |
       v                                    v
  [Model] --> Prediction              [Model] x N (stochastic)
       |                                    |
       v                                    v
  Zoom everywhere                      Measure uncertainty:
  with fixed crop                      - Spatial consensus
       |                               - Token confidence
       v                                    |
  [Model] --> Final                        v
                                       Uncertain? --> NO --> Return
                                            |
                                           YES
                                            |
                                            v
                                       Compute variance:
                                       - Inter-sample spread
                                       - Intra-sample extent
                                            |
                                            v
                                       Adaptive crop radius
                                            |
                                            v
                                       [Model] --> Final
From uniform intervention to selective precision, the core shift is treating zoom-in as a response to measured uncertainty rather than a blanket preprocessing step.
Expert Assessment
Problem choice: Real gap. Small icons and dense layouts are genuine pain points in GUI automation, and existing zoom-in methods do waste compute. The problem sits at the intersection of efficiency and accuracy—a sweet spot for practical impact. Not a manufactured gap.
Method maturity: Clever insight with solid execution. The key idea—using variance decomposition to set crop size—is elegant and well-motivated. However, the method requires multiple forward passes (N stochastic runs + 1 zoomed run), which is expensive. A simpler approach might be to use model attention maps or gradient-based saliency to identify uncertain regions, avoiding multiple passes. The authors don’t explore this alternative, which feels like a missed opportunity.
Experimental integrity: Baselines are fair (comparing against strong models like GPT-4V and Qwen2-VL). The gains are substantial on ScreenSpot-Pro (+13.4%) but modest on ScreenSpot-v2 (+4.2%), suggesting the method shines on harder datasets with smaller targets. One red flag: no ablation on the number of stochastic passes (N). How sensitive are results to N? Does N=3 work as well as N=10? This matters for practical deployment.
Writing quality: The abstract and method sections are clear, but the related work section is thin—barely half a page. A deeper comparison with uncertainty quantification methods in other vision tasks (e.g., object detection, segmentation) would strengthen the positioning. The experimental section could also benefit from error analysis: when does UI-Zoomer fail? Are there cases where zooming makes things worse?
Verdict: weak accept — Solid contribution with practical value, but the computational cost and lack of simpler baseline comparisons prevent it from being a strong accept.
Takeaways
Practitioners can steal the variance decomposition trick for any task where you need to decide how much context to include around a prediction. For example, in document layout analysis, if your model predicts a table location with high variance, you could use inter-sample spread (how much predicted table corners vary) and intra-sample extent (predicted table size) to determine how much surrounding text to include for context. The general pattern: measure uncertainty in two dimensions (position and extent), then use the law of total variance to compute an adaptive context window. This transfers beyond vision to any structured prediction task where you can run stochastic inference.
论文: 2604.14113 作者: Fei Tang, Bofan Chen, Zhengxi Lu, Tongbo Chen, Songqin Nong, Tao Jiang, Wenhao Xu, Weiming Lu, Jun Xiao, Yueting Zhuang 分类: cs.CV, cs.AI, cs.CL
缺口
GUI定位模型根据自然语言查询在界面截图中找元素。
它们在小图标和密集布局上表现不佳,因为像素级精度很重要。
现有的放大方法会裁剪并在更高分辨率下重新推理,但它们对每个实例都统一放大,使用固定的裁剪尺寸。
这在模型已经有把握的简单案例上浪费计算,在不确定性各异的困难案例上使用错误的裁剪尺寸。
核心问题:把放大当作固定配方,而非对模型不确定性的自适应响应。
问题:小图标 + 密集布局 = 定位差
         |
         v
先前方法:统一放大(固定触发 + 固定裁剪尺寸)
         |
         +---> 在有把握的预测上浪费计算
         +---> 对变化的不确定性用错裁剪尺寸
         |
         v
本文:自适应放大(不确定性门控 + 方差驱动尺寸)
         |
         +---> 触发:空间共识 + token置信度
         +---> 裁剪尺寸:分解方差为散布 + 范围
         |
         v
证据:ScreenSpot-Pro上+13.4%,UI-Vision上+10.3%,ScreenSpot-v2上+4.2%
         |
         v
结论:把放大当作不确定性量化问题能提升效率和准确度
增量
一句话: 这篇论文之前,放大是到处使用的钝器;之后,它是只在模型犹豫时部署、按不确定性缩放的精密工具。
核心机制
UI-Zoomer有两个决策模块。
第一,置信度感知门控决定是否放大。
它用dropout多次运行推理得到随机预测,测量空间共识(预测框的重合程度),并与token级生成置信度融合。
如果两个信号都表明不确定,就触发放大。
第二,不确定性驱动的裁剪尺寸模块决定裁剪半径。
它用全方差定律分解预测方差:样本间散布(预测框中心相距多远)加样本内范围(每个预测框有多大)。
裁剪半径从这两个方差分量计算得出,确保放大区域覆盖不确定区域。
输入:截图 + 查询
         |
         v
    [基础模型]----> 预测_1, 预测_2, ..., 预测_N
         |                    |
         |                    v
         |            空间共识(框重叠)
         |                    +
         |            Token置信度(生成分数)
         |                    |
         v                    v
    有把握?            [门控决策]
         |                    |
        否                   是(不确定)
         |                    |
         v                    v
    返回基础              计算方差:
    预测                 - 样本间散布(中心位置)
                         - 样本内范围(框尺寸)
                              |
                              v
                         裁剪半径 = f(散布, 范围)
                              |
                              v
                         裁剪 + 放大 + 重新推理
                              |
                              v
                         最终预测
把UI-Zoomer想象成一个带变焦镜头的摄影师。
摄影师先拍一张试拍(基础推理)。
如果主体模糊且摄影师的手抖(空间共识低且置信度低),他们决定放大。
但放大多少?他们看两件事:试拍之间手抖了多少(样本间散布)和模糊主体看起来有多大(样本内范围)。
小主体加大抖动需要更紧的变焦;大主体加小抖动需要较少变焦。
摄影师从这两个因素计算变焦级别,拍摄放大照片,得到清晰图像。
关键洞见:放大的决策和变焦级别都来自测量不确定性,而非固定规则。
关键概念
- 空间共识: 想象你让五个人指向屏幕上的同一个小按钮。
如果他们的手指落在大致相同的位置,你有高空间共识——按钮位置清楚。
如果他们的手指散布在屏幕各处,共识低——没人确定它在哪。
UI-Zoomer用dropout多次运行模型(像问多个人)并测量预测边界框的重叠程度。
低重叠意味着模型对位置不确定,触发放大。
这不同于只检查模型的置信度分数是否低;模型可能自信地错。
空间共识检查模型是否一致地指向同一个地方。
- 全方差定律分解: 当你测量预测有多分散时,可以把这种分散拆成两个来源。
第一,样本间方差:预测框中心彼此相差多少?第二,样本内方差:每个预测框有多大(大框意味着模型认为元素可能在框内任何地方)?全方差定律说:总不确定性 = 预测间散布 + 预测内模糊。
UI-Zoomer用这个来设置裁剪尺寸。
如果预测散布很广(高样本间方差),你需要大裁剪来捕获所有候选位置。
如果每个预测是大框(高样本内方差),你也需要大裁剪来覆盖模糊范围。
数学给你一个有原则的方法从这两个分量计算裁剪半径。
- 无需训练的适应: 大多数提升模型性能的方法需要在新数据上重新训练或用额外参数微调。
UI-Zoomer无需训练——它包裹任何现有GUI定位模型而不修改权重。
这就像给相机加放大镜;相机本身不变,但你能拍到小物体的更好照片。
这很重要,因为你可以把UI-Zoomer应用到新模型上,或在没有训练数据或计算预算重新训练时使用它。
权衡:你用推理时间(多次运行模型并在裁剪上做第二遍)而非训练时间付费。
框架转变
之前(主流方法):                之后(本文方法):

截图 + 查询                       截图 + 查询
       |                                |
       v                                v
  [模型] --> 预测                  [模型] x N(随机)
       |                                |
       v                                v
  到处放大                         测量不确定性:
  用固定裁剪                       - 空间共识
       |                           - Token置信度
       v                                |
  [模型] --> 最终                      v
                                   不确定?--> 否 --> 返回
                                        |
                                       是
                                        |
                                        v
                                   计算方差:
                                   - 样本间散布
                                   - 样本内范围
                                        |
                                        v
                                   自适应裁剪半径
                                        |
                                        v
                                   [模型] --> 最终
从统一干预到选择性精准,核心转变是把放大当作对测量不确定性的响应,而非一刀切的预处理步骤。
专家评审
选题眼光: 真缺口。
小图标和密集布局是GUI自动化中的真痛点,现有放大方法确实浪费计算。
问题处于效率和准确度的交叉点——实用影响的甜蜜点。
不是人造缺口。
方法成熟度: 巧妙洞见加扎实执行。
核心想法——用方差分解设置裁剪尺寸——优雅且动机充分。
然而,方法需要多次前向传播(N次随机运行 + 1次放大运行),这很昂贵。
更简单的方法可能是用模型注意力图或基于梯度的显著性来识别不确定区域,避免多次传播。
作者没有探索这个替代方案,感觉是错失的机会。
实验诚意: 基线公平(与GPT-4V和Qwen2-VL等强模型比较)。
在ScreenSpot-Pro上增益显著(+13.4%)但在ScreenSpot-v2上温和(+4.2%),表明方法在有更小目标的更难数据集上表现出色。
一个警示:没有关于随机传播次数(N)的消融。
结果对N有多敏感?N=3和N=10效果一样好吗?这对实际部署很重要。
写作功力: 摘要和方法部分清晰,但相关工作部分单薄——勉强半页。
与其他视觉任务(如目标检测、分割)中不确定性量化方法的更深比较会加强定位。
实验部分也能从错误分析中受益:UI-Zoomer何时失败?有没有放大让事情变糟的案例?
判决: 弱接收 — 有实用价值的扎实贡献,但计算成本和缺乏更简单基线比较阻止它成为强接收。
要点总结
实践者可以为任何需要决定在预测周围包含多少上下文的任务偷走方差分解技巧。
例如,在文档布局分析中,如果你的模型预测表格位置有高方差,你可以用样本间散布(预测表格角点变化多少)和样本内范围(预测表格尺寸)来决定包含多少周围文本作为上下文。
通用模式:在两个维度(位置和范围)测量不确定性,然后用全方差定律计算自适应上下文窗口。
这超越视觉迁移到任何可以运行随机推理的结构化预测任务。