Paper: 2608.06331 Authors: Donna Hooshmand, Shubham Shahi, Cameron Barrie, Abhratanu Dutta, Marko Sterbentz, Harper Pack, Kristian J. Hammond Categories: cs.DB, cs.AI
The Gap
Here’s the thing nobody puts in the demo video. Every text-to-SQL system, every “ask your data a question” product, every automated dashboard generator sits on top of a layer that somebody wrote by hand. Call it the semantic layer, the metrics layer, the analytic schema — dbt has one, Looker has one (LookML), Cube has one, and every serious BI deployment has one. It says: customer is an entity, revenue is a measure not an identifier, order_id in this table joins to that table, and “monthly active users” means this specific aggregation over these specific rows.
That layer is the bottleneck. It’s written by the one person who understands both the business and the schema, it goes stale, and it’s wrong in ways nobody notices until a number on a slide is off by 40%.
What has prior work done? Two clusters, and they’re both partial:
Schema-side work — foreign-key discovery, inclusion-dependency mining, functional-dependency detection, entity matching. Decades of solid results here (think Sherlock, Sato, and the column-type-annotation line of work; the classic FK-discovery literature). It finds *structure but not meaning. It’ll tell you col_7 determines col_9; it won’t tell you col_7 is a customer and col_9 is their lifetime value, or that “customer” is even the right analytic unit.
LLM-side work — feed the DDL to a model, ask it to label columns, generate descriptions, or go straight to SQL. This gets you *meaning but with no guarantee the meaning connects to the data. The model happily asserts that revenue = price * quantity in a table where price is nullable 30% of the time, or generates a join path across a key that doesn’t actually satisfy inclusion. Text-to-SQL benchmarks (Spider, BIRD) mask this because the gold query exists — you never see the systematic failure mode of ungrounded semantic assertions.
The gap Tytan claims: nobody has built the thing that produces a complete, executable, semantically-typed analytic schema — and nobody has defined what it would even mean to evaluate one.
    PROBLEM
    [ analytic semantic layer is hand-written ]
    [ = knowledge acquisition bottleneck     ]
              |
              v
    WHY IT PERSISTED
    +-----------------------+     +------------------------+
    | symbolic methods:     |     | LLM methods:           |
    | find structure,       | AND | find meaning,          |
    | no meaning            |     | no grounding           |
    +-----------------------+     +------------------------+
              |                            |
              \____________  _____________/
                           \/
    ASSUMPTION
    [ the two are complementary, not competing ]
    [ symbolic = evidence,  LLM = hypothesis   ]
    [ residual ambiguity = ask the human       ]
              |
              v
    METHOD
    [ TYTAN: propose (LLM) -> verify (symbolic)      ]
    [        -> if still ambiguous, ask one question ]
              |
              v
    EVIDENCE  (three axes, deliberately separated)
    [ coverage         : 100% vs expert reference    ]
    [ retrieval exec   : 1678 / 1678 claims run     ]
    [ role accuracy    : 92 - 100%                  ]
    [ blind test       : 10-table live DB, no keys, ]
    [                    5 independent annotators   ]
              |
              v
    CONCLUSION
    [ the semantic layer can be machine-built, ]
    [ and "correct" is a measurable property   ]
The Increment
One sentence: Before this paper, “generate the semantic layer” was a prompt you wrote and eyeballed; after it, it’s a pipeline with a verification step and a three-axis definition of correctness that separates *did you find everything from does it execute from is it labeled right.
Core Mechanism
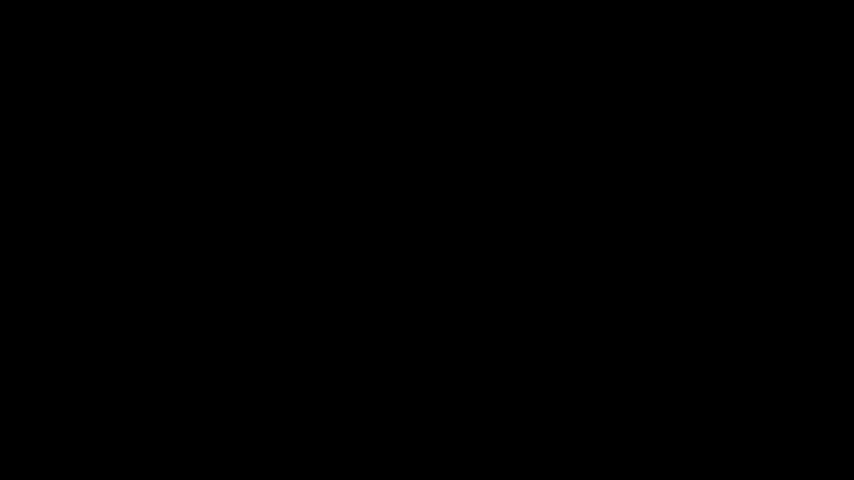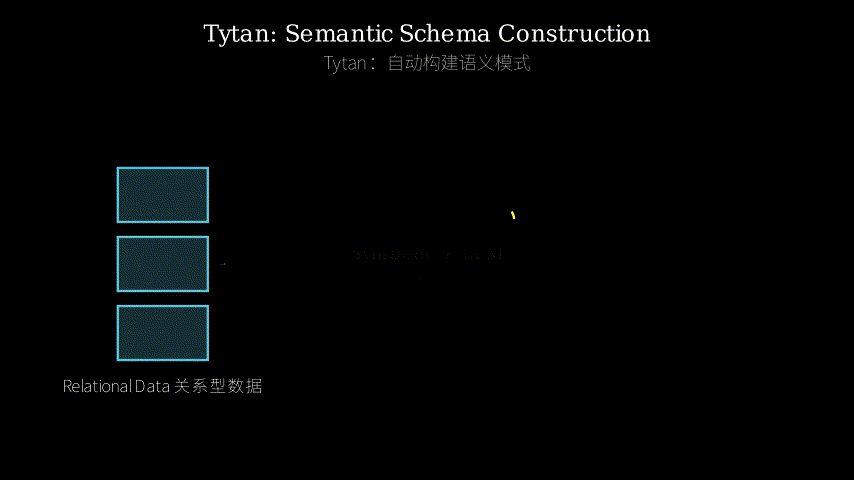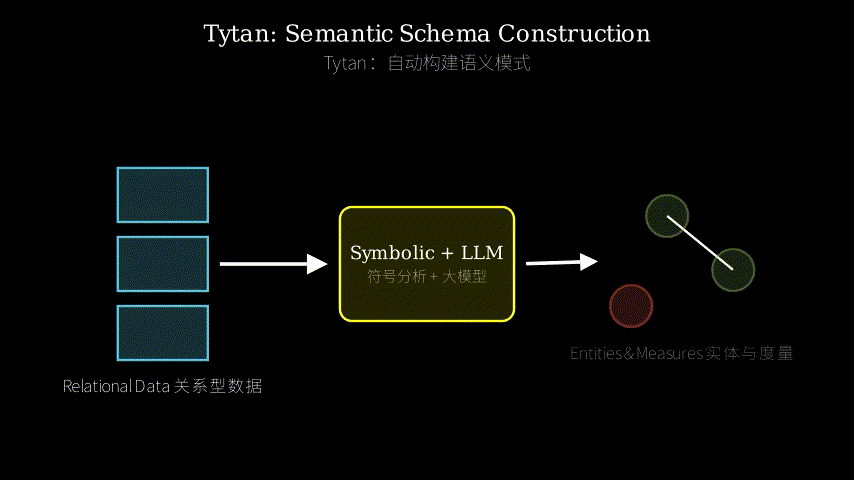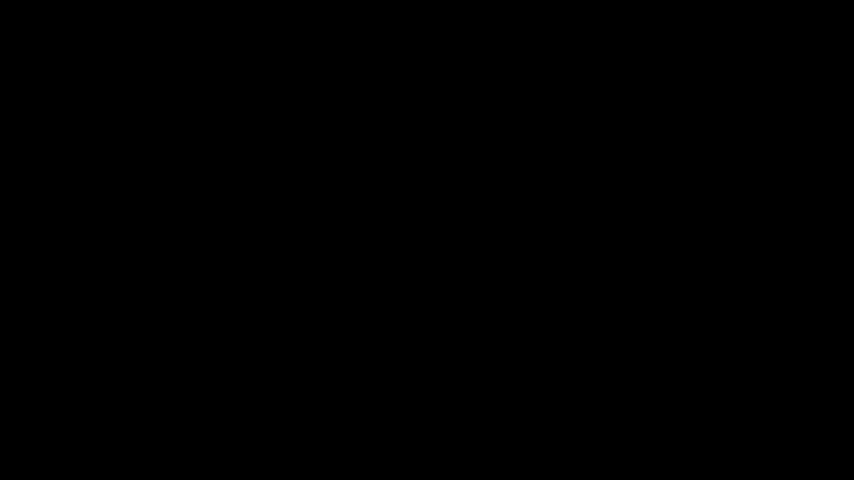
Tytan runs on a database plus, optionally, a short paragraph of user context (“this is our clinical trial enrollment system”). The pipeline has three functional stages, and the important architectural decision is who is allowed to assert what.
Symbolic analysis first. Before any LLM sees anything semantic, Tytan profiles the database: cardinalities, null rates, value distributions, uniqueness, and candidate inclusion dependencies. This matters enormously for the blind test — a live ten-table database with no declared foreign keys. Tytan has to discover that patient_ref in one table is contained in id of another, and it does this by checking the data, not by reading the DDL. The output is a pile of *evidence: facts about the data that are true by construction.
LLM proposal second. Now the model gets the profile plus column names plus sample values and proposes: what real-world entities live here (Patient, Enrollment, Site — not tbl_pt_enr_x), which columns are identifiers vs. measures vs. dimensions vs. temporal, which tables compose into a single unit of analysis, and what to call things in human language. Crucially, every proposal is a *claim, and every claim that touches data must come with a retrieval instruction — a concrete path from the schema element to the bytes.
Verification and the ask. Every retrieval instruction is executed. This is where the 1,678-of-1,678 number comes from: Tytan doesn’t publish a claim it hasn’t run. If a proposed join produces zero rows, or a “measure” turns out to be a categorical code, the claim dies. And when evidence genuinely underdetermines the answer — two plausible join paths, an ambiguous ID column that could be an entity key or a foreign reference — Tytan doesn’t guess and doesn’t silently pick. It asks the user one targeted natural-language question. This is the interactive part of “interactive neurosymbolic,” and it’s doing real work: it converts the system’s uncertainty into the cheapest possible human input rather than dumping a schema and hoping.
   INPUT
   +----------------------------+
   |  relational DB  (+ optional short description) |
   +----------------------------+
                |
                v
   .......... STAGE 1 : SYMBOLIC PROFILING ..........
   +------------------------------------------------+
   |  cardinality / uniqueness / null rate          |
   |  value distributions, sample rows              |
   |  candidate inclusion dependencies              |
   |     (works with NO declared FKs)               |
   +------------------------------------------------+
                |
                |  E V I D E N C E  (true by construction)
                v
   .......... STAGE 2 : LLM PROPOSAL ................
   +------------------------------------------------+
   |  entity proposal    : "this is a Patient"      |
   |  role assignment    : id / measure / dim / time|
   |  unit-of-analysis   : which tables compose     |
   |  naming             : human-readable labels    |
   +------------------------------------------------+
                |
                |  C L A I M S  (each carries a retrieval instruction)
                v
   .......... STAGE 3 : VERIFY ......................
   +------------------------------------------------+
   |   execute every retrieval instruction          |
   +------------------------------------------------+
        |              |                  |
      passes        fails             ambiguous
        |              |                  |
        |              v                  v
        |        [ discard /        [ ONE targeted
        |          re-propose ]       NL question
        |              |              to the user ]
        |              |                  |
        |              +--------+---------+
        |                       |
        |                       v  (answer becomes evidence,
        |                       |   re-enter stage 2)
        v                       |
   +----------------------------+-------------------+
   |   ANALYTIC SEMANTIC SCHEMA                     |
   |   entities + roles + names + verified paths    |
   +------------------------------------------------+
                |
                v
   consumed by: NL query interfaces, auto-reports, BI
The metaphor: an archaeologist, a philologist, and a site supervisor.
You’ve excavated a site. Thousands of potsherds, a few walls, no labels.
The archaeologist is the symbolic stage. She doesn’t interpret; she measures. This sherd is 4cm thick. These two fragments have edges that physically fit. This wall course sits below that one, so it’s older. Everything she writes down is verifiable by anyone who picks up the object. She will never tell you the building was a temple — that’s not her job. In Tytan, this is the profiler: patient_ref values are 100% contained in patients.id, amount has 40,000 distinct values and no nulls.
The philologist is the LLM. He reads the inscriptions, knows a hundred other sites, and says: “given the layout and this word here, this was a granary, that room was an office, and this pit is a votive deposit.” He’s producing *interpretation, and he’s often right because he’s seen the pattern before. But he is capable of confident nonsense — reading a shopping list as a hymn. In Tytan: tbl_pt_enr_x is Enrollment, amount is a measure you can sum, Patient and Enrollment compose into one analytic unit.
The site supervisor is the verification loop, and she’s the reason the report is trustworthy. Every claim the philologist makes, she checks against the archaeologist’s measurements. “You say these two rooms connect — go walk from one to the other.” That’s executing the retrieval instruction. If the doorway is bricked up, the claim is struck. And when the evidence genuinely doesn’t decide — this could be a granary or a stable, the artifacts fit both — she doesn’t flip a coin and she doesn’t write “granary (probably)”. She walks over to the one local farmer who’s been on this land for sixty years and asks him one specific question. That’s the targeted NL question, and note how cheap it is: not “please review this 200-page report,” but “was there ever livestock in this corner?”
The load-bearing part of the analogy: the final site report contains only claims that survived the supervisor. That’s why 1,678 of 1,678 execute — not because the philologist is infallible, but because nothing gets into the report unchecked.
Key Concepts
-
Analytic semantic schema (vs. the schema you already have): Your database schema says
orders.customer_id INTEGER REFERENCES customers(id). That’s a *storage description. An analytic schema says something different: “the thing analysts care about is a Customer, a Customer has a lifetime spend which you compute by summingorders.totalgrouped bycustomer_id, andorders.statusis a category you can filter on but never average.” Same data, different vocabulary. The gap between them is exactly why a text-to-SQL model can produce syntactically valid SQL that answers the wrong question. The storage schema knows the plumbing; the analytic schema knows the *questions. -
Retrieval instruction as the unit of verifiability: This is the paper’s sharpest move, and it transfers well beyond databases. Instead of asking “is this label correct?” (needs a human, subjective), the system requires every semantic claim to carry an *executable consequence. If you claim
total_spendis an aggregable feature of Customer, you must emit the query that computes it. Then correctness has a cheap mechanical proxy: does it run and return sane rows? This turns a large chunk of a fuzzy annotation problem into a compiler problem. The analogy is doctests — a comment claiming a function returns a sorted list is unverifiable prose; a doctest showingsort([3,1]) == [1,3]either passes or doesn’t. -
Ambiguity as a first-class output, not an error: Most pipelines have exactly two modes: succeed, or fail. Tytan has three: verified, rejected, and *underdetermined-so-ask. That third state is the interesting one. It requires the system to know the difference between “I don’t know” and “the data cannot know” — an ID column with no declared reference and two plausible parent tables is genuinely ambiguous no matter how good your model is. No amount of scale fixes it; the information isn’t in the database. Recognizing that and routing it to one sentence of human input is more honest than a confidence score.
Framework Shift
  Before (mainstream approach):          After (this paper):

  == PATH A: symbolic ==                 +---------------------------+
                                         |  DATABASE  (the world)    |
  [ DB ] --> [ FK discovery ]            +---------------------------+
             [ dep. mining  ]                    |
                  |                              v
                  v                        [ MEASURE ]  symbolic
            structure, no meaning          evidence, true by
            ( col_7 -> col_9 )             construction
                                                 |
  == PATH B: LLM ==                              v
                                           [ INTERPRET ] LLM
  [ DDL ] --> [ prompt ] --> [ labels ]     hypotheses, each
                              [ SQL   ]     bundled with an
                  |                         executable claim
                  v                              |
            meaning, no grounding                v
            ( plausible, unchecked )       [ EXECUTE ]
                                            pass / fail / ???
  == and the human ==                            |
                                          +------+------+
  [ expert ] --> writes 500 lines               |      |
                 of LookML by hand           ship   ask ONE
                 (weeks, stale, wrong)               question
                                                     |
  no shared definition of                            v
  "is this schema correct?"                     [ SCHEMA where
                                                  every claim
                                                  has been run ]

  eval: vibes, or downstream            eval: coverage / execution /
        text-to-SQL accuracy                  role accuracy, split
One sentence: From *generate a schema and trust it to generate hypotheses and let the database adjudicate, the core shift is treating LLM output as claims requiring evidence rather than answers requiring formatting — and treating leftover ambiguity as a question to ask rather than a guess to make.
Expert Assessment
Problem choice: Real gap, and well-timed. This is genuinely the unglamorous blocker in the entire natural-language-analytics stack. Everyone benchmarks text-to-SQL on Spider and BIRD, where the schema is small and the semantics are self-evident from column names. Point those same systems at a real enterprise warehouse with 400 tables named dw_fct_txn_agg_v2 and they collapse — not because SQL generation is hard, but because *nobody told the model what the business means. Attacking the semantic layer instead of the query generator is the right call, and it’s where the field is heading. The authors are also from a group (Hammond’s) with a long history in this exact problem space, so the framing has real operational grounding rather than benchmark-chasing.
Method maturity: Clever architecture, not clever algorithms. There’s no new inference procedure here — the components are standard: data profiling, inclusion-dependency checking, prompted LLM proposals, execution as validation. The insight is the *contract: no semantic claim ships without an executable consequence. That’s a genuinely good idea, cheap to implement, and it’s the reason the numbers look the way they do. But be clear-eyed: an experienced engineer with a weekend and a decent prompt could build 70% of this. The remaining 30% — the ambiguity detection, the question generation, the composition of tables into analytic units — is where the real work is, and unfortunately that’s the part the abstract describes least.
Is something simpler being overlooked? Possibly. The paper doesn’t say how much the symbolic stage actually contributes on databases that do have declared foreign keys. On Spider-style schemas, a well-prompted LLM reading the DDL might match Tytan’s entity structure. The blind test (no declared keys) is the case where symbolic profiling clearly earns its keep, and it’s also the only test where that’s demonstrated. An ablation would settle this; I don’t see one advertised.
Experimental integrity: Mixed, and this is where I’d push hardest.
The good: the three-axis decomposition (coverage / retrieval correctness / characterization accuracy) is a real methodological contribution. Separating “did you find it,” “does it run,” and “is it labeled right” prevents the usual mush where one metric hides three failure modes. The blind test with five independent annotators is the strongest single piece of evidence in the paper — held out, live, no declared keys, multiple judges. That’s the design of someone trying to be caught out rather than trying to win.
The concerning: 100% coverage across seven domains is a number that should make you suspicious, not impressed. Perfect scores usually mean the metric is measuring something easier than it sounds. Two questions the abstract doesn’t answer. First, the references are “expert-corrected” — corrected by whom, and with what visibility into Tytan’s output? If the reference was built by an expert reviewing Tytan’s proposals, coverage is close to circular. Second, coverage against a reference measures recall only. What about the entities Tytan proposes that *aren’t in the reference? A system that hallucinates fifteen spurious entities and one real one scores 100% coverage. I want precision, and I want the false-positive rate. Its absence from the abstract is a choice.
Then there’s this line: “Checking the underlying data showed the small disagreement is in the reference, not in TYTAN.” I want to believe it, and it might be entirely true — but “we lost 8% on this metric, then re-examined and concluded the ground truth was wrong” is structurally the most dangerous sentence in empirical work. It should be adjudicated by someone blind to which system produced which answer. If it wasn’t, that 92–100% range is really “92% measured, argued up to 100%.”
And 1,678-of-1,678 retrieval instructions executing is a weaker claim than it reads. These are self-generated claims, verified by the same execution loop that filters them. Of course they all execute — that’s the pipeline’s invariant, not an experimental finding. The interesting numbers would be: how many claims were proposed and discarded before these 1,678 survived? What’s the retry rate? And does “executes correctly” mean “returns rows” or “returns the right rows”? A join that silently produces a Cartesian product executes beautifully.
Finally, no baselines are named in the abstract. Not GPT-4-with-a-good-prompt, not existing commercial semantic-layer generators, not the FK-discovery literature. For a systems paper this is somewhat forgivable — the contribution is partly “here’s a working artifact and a way to evaluate it” — but without a comparison, the reader can’t tell how much of the performance comes from the architecture and how much from a strong underlying model.
Writing quality: The abstract is doing a lot of work and doing it well — the three-axis framing is stated crisply and the blind test is properly foregrounded. But the corner-cutting is visible in exactly the place it matters. The ambiguity-detection mechanism is the intellectual core (it’s in the title, twice over: *interactive and neurosymbolic), and it gets one sentence: “asks the user a targeted natural-language question.” When? On what criterion? How many questions per database — three, or thirty? Because if it’s thirty, this is an expert-assisted tool with good ergonomics, not an automation story, and that changes the entire value proposition. Rewriting that section with a decision rule, a question budget, and a sensitivity analysis on answer quality would elevate the whole paper from “nice system” to “reusable principle.” Second priority: an honest precision/false-positive table alongside the coverage numbers.
Verdict: weak accept — the problem is real, the propose-verify-ask architecture is a sound and reusable design, and the blind test is well constructed; but the near-perfect headline numbers are under-interrogated, precision is missing, and the ambiguity mechanism that makes the title’s claim is the least specified part of the paper.
Takeaways
Things worth stealing, whether or not you touch databases:
Make every semantic claim carry an executable consequence. This is the transferable core. Anywhere an LLM produces structured output — API specs, config, ontologies, data dictionaries, extraction schemas — require it to emit not just the assertion but a runnable check for that assertion, then run it before shipping. You convert “is this label right?” (needs a human) into “does this execute?” (needs a CPU). You won’t catch semantic errors, but you’ll catch the entire class of *ungrounded errors, which in practice is most of them.
Split your metric before you’re forced to. Coverage, executability, and label accuracy fail for different reasons and have different fixes. A single “schema quality” score would have hidden all three. When you’re evaluating a generative system on a fuzzy task, spend an afternoon decomposing what “correct” means — the decomposition is often more durable than the system.
Build the three-state pipeline. Verified / rejected / underdetermined-so-ask. Most LLM systems only have two states and paper over the third with confidence scores, which don’t distinguish “the model is unsure” from “the information isn’t present.” If your input genuinely underdetermines the output, one well-targeted question is worth more than any amount of model capacity. Design for the question, and design it to be answerable in one sentence.
Profile before you prompt. Give the model computed facts about the data (cardinality, null rates, distinct values, actual sample rows) rather than just the DDL. Cheap to compute, and it moves the model from guessing-from-names to reasoning-from-evidence. The blind test here — a live database with no declared foreign keys — is the realistic case, and it’s the case where names alone lie to you.
If you’re building NL-to-data: the lesson is that your bottleneck probably isn’t the SQL generator. Spider and BIRD trained a generation of researchers to optimize query synthesis on schemas where semantics were free. In production, semantics are the expensive part. Fix the semantic layer first.
One caution to carry forward: when your system scores 100%, your first move should be to attack your own metric, not write it in the abstract. Ask what the perfect score is *not measuring. Here, it’s precision — and that omission is the thing a reviewer will find first.
论文: 2608.06331 作者: Donna Hooshmand, Shubham Shahi, Cameron Barrie, Abhratanu Dutta, Marko Sterbentz, Harper Pack, Kristian J. Hammond 分类: cs.DB, cs.AI
缺口
有件事没人放进产品演示视频里。
每一个 text-to-SQL 系统、每一个「向你的数据提问」的产品、每一个自动仪表盘生成器,底下都压着一层人手写出来的东西。
叫它语义层、指标层、分析 schema 都行——dbt 有,Looker 有(LookML),Cube 有,任何认真的 BI 部署都有。
这层东西说的是:customer 是一个实体,revenue 是度量而不是标识符,这张表的 order_id 连到那张表,以及「月活用户」的意思是对这些特定行做这个特定的聚合。
这层就是瓶颈。
它由那个同时懂业务又懂 schema 的唯一一个人写出来,然后慢慢过期,而且它错的方式很隐蔽——直到某张幻灯片上的数字偏了 40%,才有人发现。
此前的工作做到哪一步了?两簇,而且都只做了一半:
schema 侧的工作——外键发现、包含依赖挖掘、函数依赖检测、实体匹配。
这条线几十年积累了很扎实的结果(Sherlock、Sato 那一系列列类型标注工作,以及经典的外键发现文献)。
它找得到结构,找不到含义。
它能告诉你 col_7 决定 col_9;但它不会告诉你 col_7 是客户、col_9 是这个客户的生命周期价值,更不会告诉你「客户」到底是不是正确的分析单元。
LLM 侧的工作——把 DDL 喂给模型,让它标列、生成描述,或者直接出 SQL。
这条路给你含义,但没有任何保证说这个含义真的连得上数据。
模型会很愉快地断言 revenue = price * quantity,而那张表里 price 有 30% 是空值;或者生成一条走不通的 join 路径,因为那个键根本不满足包含关系。
Spider、BIRD 这类 text-to-SQL 基准把这个问题掩盖了——因为标准答案 SQL 存在,你永远看不到无依据的语义断言这个系统性失败模式。
Tytan 声称的缺口是:还没有人做出那个能产出完整、可执行、带语义类型的分析 schema 的东西——而且没有人定义过,评估这样一个东西究竟意味着什么。
    问题
    [ 分析语义层是手写的 ]
    [ = 知识获取瓶颈     ]
              |
              v
    为什么一直没解决
    +-----------------------+     +------------------------+
    | 符号方法:            |     | LLM 方法:             |
    | 找到结构,            | AND | 找到含义,             |
    | 没有含义              |     | 没有接地               |
    +-----------------------+     +------------------------+
              |                            |
              \____________  _____________/
                           \/
    假设
    [ 两者互补,不是竞争          ]
    [ 符号 = 证据,  LLM = 假设    ]
    [ 剩下的模糊 = 去问人         ]
              |
              v
    方法
    [ TYTAN: 提出(LLM) -> 验证(符号)     ]
    [        -> 仍模糊则问一个问题       ]
              |
              v
    证据(三条轴,故意分开)
    [ 覆盖率     : 对比专家参考 100%     ]
    [ 检索可执行 : 1678 / 1678 条都跑通  ]
    [ 角色准确率 : 92 - 100%             ]
    [ 盲测       : 10 表在线库,无声明键 ]
    [              5 位独立标注者        ]
              |
              v
    结论
    [ 语义层可以被机器构建,   ]
    [ 而且「正确」是可测量的   ]
增量
一句话:这篇论文之前,「生成语义层」是你写个 prompt 然后肉眼看看;之后,它是一条带验证环节的流水线,外加一套三轴的正确性定义,把「有没有找全」「跑不跑得通」「标得对不对」这三件事拆开了。
核心机制
Tytan 的输入是一个数据库,外加(可选)一小段用户描述(「这是我们的临床试验入组系统」)。
流水线有三个功能阶段,而其中最重要的架构决策是:谁有权断言什么。
先做符号分析。
在任何 LLM 看到任何语义信息之前,Tytan 先给数据库做画像:基数、空值率、取值分布、唯一性、候选包含依赖。
这一步在盲测里极其关键——那是一个没有声明外键的十表在线数据库。
Tytan 必须自己发现某张表的 patient_ref 被另一张表的 id 包含,而它是通过查数据做到的,不是通过读 DDL。
这一阶段的产出是一堆证据:关于数据的、按构造为真的事实。
再做 LLM 提出。
现在模型拿到画像、列名和样本值,开始提议:这里住着哪些真实世界的实体(Patient、Enrollment、Site——而不是 tbl_pt_enr_x),哪些列是标识符、哪些是度量、哪些是维度、哪些是时间,哪些表组合成一个单一的分析单元,以及用人话该怎么命名。
关键在于:每一条提议都是一个声明,而每一条触及数据的声明都必须附带一条检索指令——一条从 schema 元素通往真实字节的具体路径。
验证与追问。
每一条检索指令都会被真正执行。
1678/1678 这个数字就是这么来的:Tytan 不会发布一条它没跑过的声明。
如果某条提议的 join 返回零行,或者某个被标为「度量」的列其实是分类编码,这条声明就死掉。
而当证据确实无法决定答案时——两条同样说得通的 join 路径、一个既可能是实体主键也可能是外部引用的模糊 ID 列——Tytan 不猜,也不默默选一个。
它向用户提出一个有针对性的自然语言问题。
这就是「interactive neurosymbolic」里 interactive 的部分,而它在干实事:把系统的不确定性转换成成本最低的人类输入,而不是丢一份 schema 出来然后祈祷。
   输入
   +--------------------------------------+
   |  关系数据库 (+ 可选的一小段描述)     |
   +--------------------------------------+
                |
                v
   .......... 阶段 1 : 符号画像 ....................
   +------------------------------------------------+
   |  基数 / 唯一性 / 空值率                        |
   |  取值分布、样本行                              |
   |  候选包含依赖                                  |
   |     (在「无声明外键」时同样工作)             |
   +------------------------------------------------+
                |
                |  证 据 (按构造为真)
                v
   .......... 阶段 2 : LLM 提出 .....................
   +------------------------------------------------+
   |  实体提出     : 「这是一个 Patient」           |
   |  角色分配     : 标识/度量/维度/时间            |
   |  分析单元     : 哪些表组合在一起               |
   |  命名         : 人类可读的标签                 |
   +------------------------------------------------+
                |
                |  声 明 (每条都带一条检索指令)
                v
   .......... 阶段 3 : 验证 .........................
   +------------------------------------------------+
   |   执行每一条检索指令                           |
   +------------------------------------------------+
        |              |                  |
      通过           失败              模糊
        |              |                  |
        |              v                  v
        |        [ 丢弃 /          [ 向用户提出
        |          重新提出 ]        一个针对性
        |              |            的自然语言问题 ]
        |              |                  |
        |              +--------+---------+
        |                       |
        |                       v (回答变成证据,
        |                       |   重新进入阶段 2)
        v                       |
   +----------------------------+-------------------+
   |   分析语义 SCHEMA                              |
   |   实体 + 角色 + 命名 + 已验证的路径            |
   +------------------------------------------------+
                |
                v
   下游消费方:自然语言查询、自动报告、BI
核喻:一个考古学家、一个语文学家、一个工地主管。
你挖开了一处遗址。
几千块陶片、几段墙基,没有任何标签。
考古学家是符号阶段。
她不解释,她只测量。
这块陶片厚 4 厘米。
这两块碎片的断口在物理上能拼合。
这层墙压在那层下面,所以它更早。
她写下的每一句话,任何人拿起那个实物都能自己核验。
她永远不会告诉你这栋建筑是座神庙——那不是她的工作。
在 Tytan 里,她就是画像器:patient_ref 的取值 100% 落在 patients.id 里,amount 有 4 万个不同值且无空值。
语文学家是 LLM。
他读铭文,见过上百处别的遗址,然后说:「从布局和这里这个词来看,这是粮仓,那间是办事房,这个坑是祭祀埋藏。」
他生产的是解释,而且他经常对,因为他见过这个模式。
但他也完全有能力自信地胡说——把一张购物清单读成一首颂歌。
在 Tytan 里:tbl_pt_enr_x 是 Enrollment,amount 是可求和的度量,Patient 和 Enrollment 合成一个分析单元。
工地主管是验证环,她是这份报告可信的唯一原因。
语文学家提出的每一条判断,她都拿去对考古学家的测量做核对。
「你说这两间屋子相通——去,从这间走到那间。」
这就是执行检索指令。
如果那道门被砖封了,这条判断就被划掉。
而当证据确实无法裁决时——这里既可能是粮仓也可能是马厩,出土物两边都说得通——她不掷硬币,也不写「粮仓(大概)」。
她走去找那个在这块地上待了六十年的农户,问他一个具体问题。
这就是那句针对性的自然语言提问,注意它多便宜:不是「请审阅这份 200 页报告」,而是「这个角落以前养过牲口吗?」
这个比喻承重的地方在于:最终的遗址报告里,只包含通过了主管核验的判断。
这才是 1678/1678 全部跑通的原因——不是因为语文学家不会错,而是因为没有任何未经核验的东西能进报告。
关键概念
-
分析语义 schema(对比你已经有的那个 schema):你的数据库 schema 说的是
orders.customer_id INTEGER REFERENCES customers(id)。那是存储*描述。分析 schema 说的是完全不同的事:「分析师关心的东西叫 Customer,Customer 有一个生命周期消费额,算法是把orders.total按customer_id分组求和,而orders.status是一个可以拿来过滤但绝不能求平均的类别。」同一份数据,两套词汇。这两者之间的落差,正是 text-to-SQL 模型能写出语法完全正确、但回答了错误问题的 SQL 的原因。存储 schema 懂管道;分析 schema 懂问题*。 -
把检索指令当作可验证性的最小单位:这是全文最锋利的一手,而且它能迁移到数据库之外很远的地方。与其去问「这个标签对不对」(需要人、主观),系统要求每一条语义声明都必须携带一个**可执行的*后果。你说
total_spend是 Customer 的可聚合特征,那你就得给出计算它的那条查询。于是正确性有了一个廉价的机械代理:它跑不跑得通、返回的行合不合理?这就把一个模糊的标注问题的相当大一块,变成了一个编译问题。类比是 doctest——一句注释声称函数返回排好序的列表,那是无法验证的散文;而一个sort([3,1]) == [1,3]的 doctest,要么过,要么不过。 -
把「模糊」当作一等输出,而不是错误:大多数流水线只有两种模式:成功,或失败。Tytan 有三种:已验证、已拒绝、以及**欠定所以去问*。第三种状态才是有意思的那个。它要求系统能分清「我不知道」和「数据本身无法知道」——一个没有声明引用、且有两个说得通的父表的 ID 列,无论你的模型多强都是真正的模糊。堆算力解决不了,因为信息不在数据库里。承认这一点,然后把它路由成一句人类输入,比给个置信度分数要诚实得多。
框架转变
  之前(主流方法):                     之后(本文方法):

  == 路线 A:符号 ==                     +---------------------------+
                                         |  数据库(世界本身)       |
  [ DB ] --> [ 外键发现   ]              +---------------------------+
             [ 依赖挖掘   ]                     |
                  |                              v
                  v                        [ 测量 ] 符号
            结构,无含义                   按构造为真的证据
            ( col_7 -> col_9 )                   |
                                                 v
  == 路线 B:LLM ==                        [ 解释 ] LLM
                                           假设,每条都捆绑
  [ DDL ] --> [ prompt ] --> [ 标签 ]      一个可执行的声明
                             [ SQL  ]            |
                  |                              v
                  v                        [ 执行 ]
            含义,无接地                    通过 / 失败 / ???
            ( 看着像,没查过 )                    |
                                          +------+------+
  == 还有那个人 ==                              |      |
                                              发布   问一个
  [ 专家 ] --> 手写 500 行                            问题
               LookML                                |
               (几周、过期、错)                       v
                                                [ 每条声明
  对「这个 schema 对不对」                        都被跑过的
  没有共同定义                                    SCHEMA ]

  评估:凭感觉,或者看               评估:覆盖率 / 可执行性 /
        下游 text-to-SQL 准确率            角色准确率,分开算
一句话:从**生成 schema 然后相信它*,到生成假设然后让数据库来裁决,核心转变是把 LLM 的输出当成需要证据的声明、而不是需要排版的答案——并且把剩下的模糊当成一个要去问的问题、而不是一个要去猜的空。
专家评审
选题眼光:真缺口,而且时机对。
这确实是整个自然语言分析技术栈里最不光鲜的那个堵点。
所有人都在 Spider 和 BIRD 上刷 text-to-SQL,那里的 schema 很小,语义从列名就能看出来。
把同样的系统对准一个有 400 张表、表名叫 dw_fct_txn_agg_v2 的真实企业数仓,它们就崩了——不是因为生成 SQL 难,而是因为没人告诉模型这门生意是什么意思。
去攻语义层而不是查询生成器,这个判断是对的,也是这个领域正在去的方向。
作者来自 Hammond 那个组,在这个问题上有很长的历史,所以这个框架有真实的运营基础,不是在追基准。
方法成熟度:架构上巧,算法上不巧。
这里没有新的推理过程——组件都是标准件:数据画像、包含依赖检查、prompt 出来的 LLM 提议、拿执行当验证。
真正的洞见是那个契约:任何语义声明,没有可执行后果就不许发布。
这确实是个好想法,实现成本低,而且它就是那些数字长成那样的原因。
但要看清楚:一个有经验的工程师用一个周末加一个像样的 prompt,能做出这东西的 70%。
剩下 30%——模糊检测、问题生成、把多张表组合成分析单元——才是真正的活儿,而不幸的是,摘要对这部分说得最少。
有没有被忽略的更简单方法?可能有。
论文没说在确实有声明外键的数据库上,符号阶段到底贡献了多少。
在 Spider 那种 schema 上,一个 prompt 写得好的 LLM 光读 DDL 可能就能追平 Tytan 的实体结构。
盲测(无声明键)是符号画像明显挣到工钱的场景,而它也是唯一一个证明了这件事的测试。
一个消融实验就能说清;我没看到有。
实验诚意:好坏参半,这也是我会最用力推的地方。
好的部分:三轴拆解(覆盖率/检索正确性/刻画准确率)是真正的方法论贡献。
把「有没有找到」「跑不跑得通」「标得对不对」分开,防止了那种一个指标掩盖三种失败模式的糊状物。
带五位独立标注者的盲测是全文最强的单一证据——留出、在线、无声明键、多位裁判。
这是一个想被抓错的人的设计,不是一个想赢的人的设计。
担心的部分:七个域上 100% 覆盖率,这个数字应该让你起疑,而不是让你佩服。
满分通常意味着这个指标在测的东西,比它听起来的要容易。
摘要没回答两个问题。
第一,参考 schema 是「专家修正过的」——谁修正的?修正时能不能看到 Tytan 的输出?如果参考是专家审阅 Tytan 的提议之后建起来的,那覆盖率就接近循环论证了。
第二,对着参考算覆盖率只测了召回。
那些 Tytan 提出了、但不在参考里的实体呢?
一个幻觉出十五个假实体、外加一个真实体的系统,覆盖率也是 100%。
我要看精确率,我要看假阳性率。
摘要里没有,这是一个选择。
然后是这句话:「检查底层数据表明,那一小点分歧在参考里,不在 TYTAN 里。」
我愿意相信,而且它可能完全是真的——但「我们在这个指标上掉了 8%,然后重新检查,得出结论是标准答案错了」在实证工作里,结构上是最危险的一句话。
这件事应该由一个不知道哪个答案出自哪个系统的人来裁决。
如果没有,那 92–100% 这个区间的真实含义是「测出来 92%,辩论到 100%」。
而 1678 条检索指令全部执行成功,这个声明比它读起来要弱。
这些是自己生成的声明,由同一个筛掉它们的执行环来验证。
它们当然全都能跑通——那是流水线的不变量,不是实验发现。
有意思的数字应该是:这 1678 条存活下来之前,一共提出并丢弃了多少条?重试率多少?以及「正确执行」是指「返回了行」还是「返回了对的行」?
一个悄悄产生笛卡尔积的 join,执行得漂亮极了。
最后,摘要里没提任何基线。
没有「GPT-4 加好 prompt」,没有现成的商业语义层生成器,没有外键发现那条文献线。
对一篇系统论文来说这尚可原谅——贡献的一部分是「这里有个能跑的东西和一套评估它的方法」——但没有对比,读者就没法判断性能里有多少来自架构、多少来自底下那个强模型。
写作功力:摘要承担了很多任务,而且完成得不错——三轴框架说得干脆,盲测被恰当地放到了前台。
但偷懒的地方,恰好偷在最要命的位置。
模糊检测机制是全文的智力核心(它在标题里出现了两次:interactive 和 neurosymbolic),却只得到一句话:「向用户提出一个有针对性的自然语言问题。」
什么时候问?
依据什么判据?
每个数据库问几个——三个,还是三十个?
因为如果是三十个,那这就是一个人机工程做得不错的专家辅助工具,不是一个自动化的故事,而这会改变整个价值主张。
把那一节重写成一条决策规则、一个提问预算、加上对回答质量的敏感性分析,能把整篇论文从「不错的系统」抬到「可复用的原则」。
第二优先级:在覆盖率数字旁边,老实给一张精确率/假阳性率的表。
判决:弱接收 — 问题是真的,「提出-验证-追问」的架构是个扎实且可复用的设计,盲测也做得讲究;但那些接近满分的头条数字审问得不够,精确率缺席,而支撑标题主张的模糊机制恰恰是全文说明最少的部分。
要点总结
值得偷走的东西,无论你碰不碰数据库:
让每一条语义声明都携带一个可执行的后果。
这是可迁移的内核。
任何地方只要 LLM 在产出结构化输出——API 规格、配置、本体、数据字典、抽取 schema——就要求它不仅给出断言,还要给出针对这个断言的可运行检查,然后在发布前真的跑一遍。
你把「这个标签对吗」(需要人)变成了「这个跑得通吗」(需要 CPU)。
你抓不到语义错误,但你会抓到无依据错误这一整类——而实践中它们占大多数。
在被迫之前,先把你的指标拆开。
覆盖率、可执行性、标签准确率,失败的原因不同,修法也不同。
一个笼统的「schema 质量」分数会把这三样全藏起来。
当你在一个模糊任务上评估生成式系统时,花一个下午拆解「正确」到底意味着什么——这个拆解常常比系统本身更耐用。
造三态流水线。
已验证/已拒绝/欠定所以去问。
大多数 LLM 系统只有两态,然后用置信度分数把第三态糊过去,而置信度分不出「模型不确定」和「信息根本不在那里」。
如果你的输入确实欠定了输出,一个问得准的问题比任何模型容量都值钱。
为这个提问做设计,并且把它设计成一句话就能回答。
先画像,再 prompt。
给模型的不该只有 DDL,而应该是关于数据的计算事实(基数、空值率、不同值个数、真实样本行)。
算起来很便宜,却能把模型从「照着名字猜」推到「照着证据推」。
这里的盲测——一个没有声明外键的在线数据库——才是现实情况,也正是「只有名字会骗你」的那种情况。
如果你在做自然语言到数据:教训是你的瓶颈很可能不在 SQL 生成器。
Spider 和 BIRD 训练了一整代研究者去优化查询合成,而那些 schema 上语义是免费的。
在生产环境里,语义才是贵的那部分。
先修语义层。
一条要带走的警惕:当你的系统拿到 100% 时,你的第一个动作应该是攻击你自己的指标,而不是把它写进摘要。
问一问这个满分没在测什么。
在这里,答案是精确率——而这个缺席,是审稿人第一眼就会找到的东西。