Paper: 2605.31590 Authors: Ruotong Liao, Guowen Huang, Qing Cheng, Guangyao Zhai, Lei Zhang, Xun Xiao, Thomas Seidl, Daniel Cremers, Volker Tresp Categories: cs.CV, cs.AI
The Gap
Text-to-video diffusion models can generate impressive single-event clips (“a dog running”), but struggle with multi-event sequences (“a dog running, then sitting, then barking”). Existing approaches either fine-tune models on multi-event data (expensive, domain-specific) or use naive prompt switching (causes abrupt transitions and event bleeding). The core problem: we don’t know when in the denoising process to switch from one event’s guidance to the next.
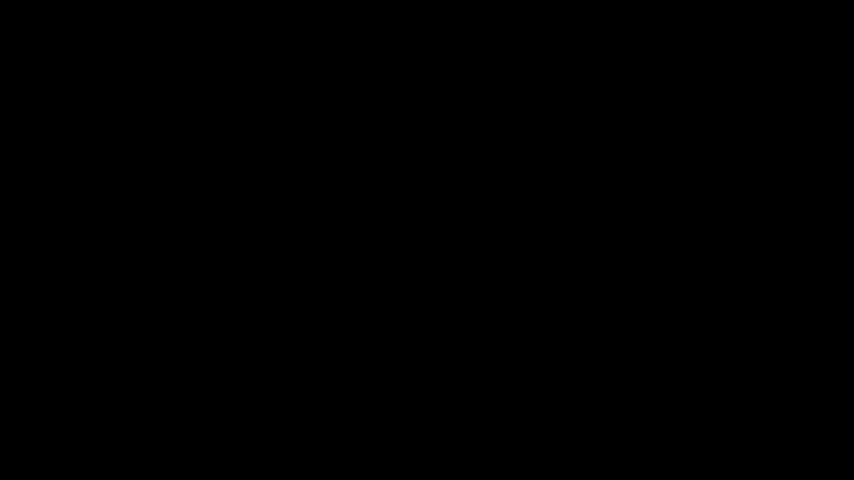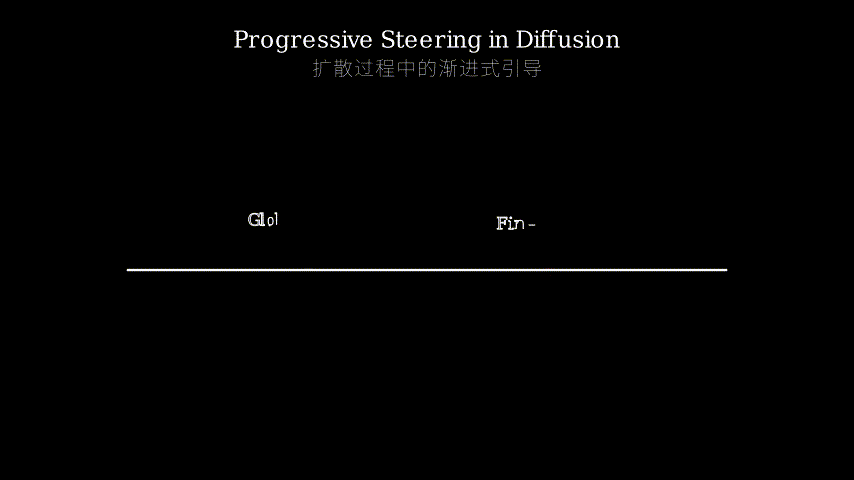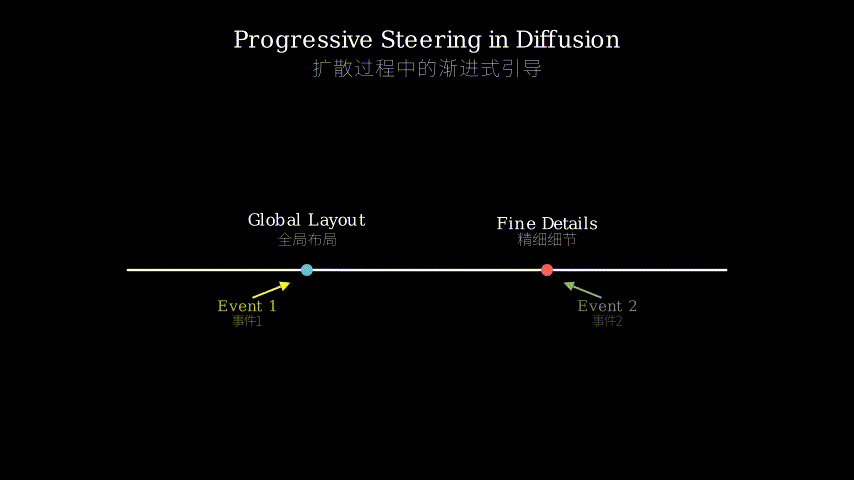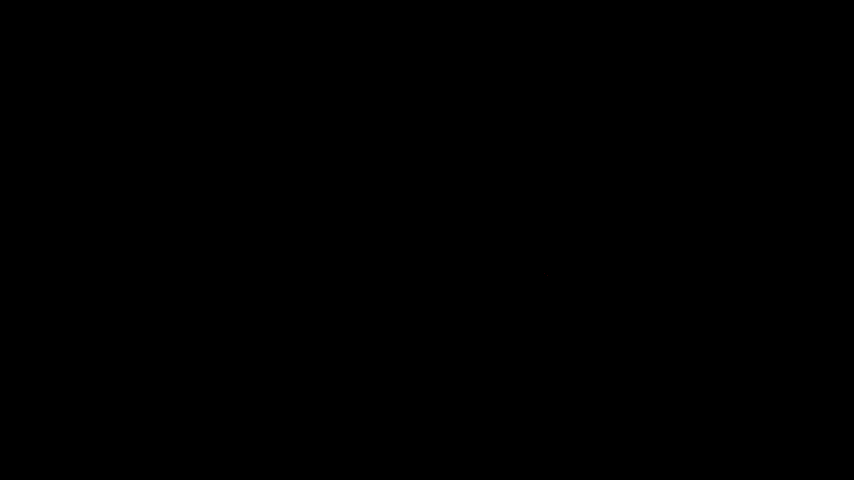
Prior work treats the diffusion trajectory as a black box, switching prompts at arbitrary timesteps or using uniform schedules. This ignores the intrinsic structure of how diffusion models build content—early steps establish global layout, late steps refine details. Without understanding these turning points, you either switch too early (events blur together) or too late (abrupt cuts).
Problem: Multi-event videos need temporal boundaries
    |
    v
Gap: Don't know WHEN to switch event guidance in denoising
    |
    v
Assumption: DiT denoising has intrinsic turning points
    |
    v
Method: Probe DiT to find turning points + design steering handles
    |
    v
Evidence: Outperforms baselines on 8 metrics, scales with event count
    |
    v
Conclusion: Training-free steering via intrinsic structure works
The Increment
One sentence: Before—multi-event generation required training or produced blurry transitions; after—we can steer pretrained models through their intrinsic turning points for clean event boundaries.
Core Mechanism
TunerDiT has two components working in sequence. First, Event-Partitioned Masking divides the video spatially into event regions with transition bands. During denoising, each frame region only receives guidance from its assigned event prompt, but transition bands blend prompts from neighboring events. This creates soft boundaries rather than hard cuts.
Second, Cross-Event Prompt Fusion kicks in during late-stage denoising (after the turning point where layout is fixed). It injects semantic information from neighboring events into the current event’s prompt embedding. This ensures visual coherence across boundaries—if event 1 is “red car” and event 2 is “blue car,” the fusion helps maintain car shape consistency while transitioning color.
The key insight: they probed pretrained DiTs and found that attention patterns shift dramatically at specific denoising timesteps. Early steps show global, diffuse attention (building layout). Late steps show local, focused attention (refining details). The turning point between these regimes is where you should start blending event semantics.
Denoising Timeline:
t=T (noise) -----> turning point -----> t=0 (clean)
    |                    |                    |
    v                    v                    v
[Global layout]    [Transition]      [Local details]
Event masks        Start fusion      Refine boundaries
enforced           between events    with blended prompts
Think of it like painting a mural with multiple scenes. Early on, you sketch the composition—where each scene sits, rough shapes. You don’t want scenes bleeding into each other here, so you mask off regions (Event-Partitioned Masking). But you leave thin overlap zones at boundaries. Midway through, once the layout is locked, you start blending colors at the boundaries so transitions look natural (Cross-Event Prompt Fusion). By the end, you’re just adding fine details within each scene, but the boundary blending from earlier ensures no jarring seams.
Key Concepts
-
Turning Points in Diffusion: Diffusion models don’t denoise uniformly—they have phases. Early timesteps establish global structure (what goes where), late timesteps refine local details (textures, edges). The turning point is the timestep where attention shifts from global to local. Before this point, changing the prompt affects layout; after, it only affects details. TunerDiT finds this point empirically by measuring attention entropy across layers. High entropy = global attention, low entropy = local attention. The turning point is where entropy drops sharply. This matters because you want to enforce event boundaries early (layout phase) but blend semantics late (detail phase).
-
Event-Partitioned Masking: Instead of switching prompts over time (frame 1-10 use prompt A, frame 11-20 use prompt B), TunerDiT switches prompts over space within each frame. Imagine a video with two events: left half is “sunrise,” right half is “sunset.” During denoising, the left region only sees “sunrise” guidance, right only sees “sunset.” But there’s a transition band in the middle that sees a weighted blend of both prompts. The weights shift gradually across the band (80% sunrise / 20% sunset → 50/50 → 20/80). This creates smooth spatial transitions instead of temporal cuts. The band width is tunable—wider bands = smoother transitions but more event mixing.
-
Cross-Event Prompt Fusion: After the turning point, layout is fixed but details are still forming. Here, TunerDiT injects neighboring event semantics into each event’s prompt. Concretely: take event A’s text embedding, add a small weighted component from event B’s embedding, use this fused embedding for late-stage guidance. Why? Without fusion, events can look visually disconnected even with spatial blending—different lighting, different object styles. Fusion ensures semantic consistency (if both events have “car,” the car shape stays consistent) while allowing attribute changes (color, position). The fusion weight is another tunable parameter.
Framework Shift
Before (temporal prompt switching):        After (TunerDiT):

Denoising steps:                           Denoising steps:
t=T  [Prompt A] -----> frames 1-10         t=T  [Spatial masks] -----> all frames
     [Prompt B] -----> frames 11-20             [Event A | Band | Event B]
                                                      |
Problem: Abrupt cuts, event bleeding       t=mid [Turning point detected]
                                                      |
                                           t=0  [Fused prompts] -----> all frames
                                                [A+B_blend in transition zones]

                                           Result: Smooth boundaries, clean events
One sentence: From temporal prompt switching (when to change guidance) to spatial-semantic steering (where and how to blend guidance), the core shift is exploiting diffusion’s intrinsic structure rather than imposing external schedules.
Expert Assessment
Problem choice: Real gap. Multi-event generation is a natural user need (storytelling, tutorials, ads), and existing methods genuinely struggle. The problem sits at the intersection of controllability and long-horizon generation—both active research areas. Not manufactured.
Method maturity: Clever insight (probing for turning points) combined with straightforward engineering (masking + fusion). The turning point discovery is the novel bit; the steering handles are incremental but well-motivated. Could simpler approaches work? Maybe—hierarchical prompting or attention masking without fusion might get 80% of the benefit. But the authors show ablations proving both components matter.
Experimental integrity: Strong. They curated a new benchmark (Meve) because existing ones don’t test multi-event scenarios—fair move. Baselines include recent training-free methods (FreeNoise, MotionCtrl) and a fine-tuned model (Gen-L-Video). Metrics span text alignment, temporal consistency, and event separation. Numbers look solid, and the scaling trend (improvement increases with event count) is a good sanity check. One concern: no user study, so “better” is purely metric-driven.
Writing quality: Clear structure, good motivation. The probing analysis (Section 3.1) could be tighter—lots of attention heatmaps without quantitative thresholds for “turning point.” The method section is dense; a pseudocode block would help. Ablations are thorough. Overall, above-average clarity for a CV paper.
Verdict: weak accept — Solid contribution with practical value, but the novelty is more in application (finding turning points in DiTs) than fundamental method innovation. The training-free angle is appealing, and results are convincing. Would be stronger with user studies and analysis of failure modes.
Takeaways
Probe your models: Don’t treat diffusion as a black box. Measure attention patterns, activation statistics, or gradient flows across timesteps. You’ll find structure (phases, turning points) that you can exploit for control. This applies beyond video—image editing, 3D generation, any diffusion-based task.
Spatial control beats temporal control for multi-event content: Instead of switching prompts over time (frame-by-frame), partition space and blend at boundaries. This generalizes: for multi-object image generation, mask regions per object; for multi-speaker audio, partition frequency bands.
Transition bands are underrated: Hard boundaries (mask A vs mask B) cause artifacts. Soft boundaries (blend A and B over a band) are smoother but risk mixing. The tunable band width gives users a consistency-separation tradeoff. Steal this pattern for any segmentation or partitioning task.
Late-stage semantic fusion: Once structure is set, inject cross-region semantics to maintain coherence. In practice: if you’re generating a composite image with multiple prompts, fuse embeddings in the final 20-30% of denoising steps. Prevents style drift between regions.
论文: 2605.31590 作者: Ruotong Liao, Guowen Huang, Qing Cheng, Guangyao Zhai, Lei Zhang, Xun Xao, Thomas Seidl, Daniel Cremers, Volker Tresp 分类: cs.CV, cs.AI
缺口
文本生成视频的扩散模型能生成令人印象深刻的单事件片段(“一只狗在跑”),但在多事件序列上表现挣扎(“一只狗先跑,然后坐下,然后叫”)。
现有方法要么在多事件数据上微调模型(昂贵,领域特定),要么使用朴素的提示词切换(导致突兀的过渡和事件渗透)。
核心问题:我们不知道在去噪过程的哪个时刻从一个事件的引导切换到下一个。
先前工作把扩散轨迹当黑盒,在任意时间步切换提示词或使用均匀调度。
这忽略了扩散模型构建内容的内在结构——早期步骤建立全局布局,晚期步骤细化细节。
不理解这些转折点,你要么切换太早(事件模糊在一起),要么切换太晚(突兀的切割)。
问题:多事件视频需要时间边界
    |
    v
缺口:不知道何时在去噪中切换事件引导
    |
    v
假设:DiT 去噪有内在转折点
    |
    v
方法:探测 DiT 找转折点 + 设计引导手柄
    |
    v
证据:在 8 个指标上超越基线,随事件数量扩展
    |
    v
结论:通过内在结构的无训练引导有效
增量
一句话:之前——多事件生成需要训练或产生模糊过渡; 之后——我们能通过预训练模型的内在转折点引导它们,获得清晰的事件边界。
核心机制
TunerDiT 有两个按顺序工作的组件。
首先,事件分区掩码将视频在空间上划分为带过渡带的事件区域。
在去噪过程中,每个帧区域只接收其分配事件提示词的引导,但过渡带混合来自相邻事件的提示词。
这创建了软边界而非硬切割。
其次,跨事件提示词融合在晚期去噪阶段启动(在布局固定的转折点之后)。
它将相邻事件的语义信息注入当前事件的提示词嵌入。
这确保了边界处的视觉连贯性——如果事件 1 是”红色汽车”,事件 2 是”蓝色汽车”,融合帮助在过渡颜色时保持汽车形状一致性。
关键洞察:他们探测了预训练的 DiT,发现注意力模式在特定去噪时间步发生剧烈转变。
早期步骤显示全局、分散的注意力(构建布局)。
晚期步骤显示局部、集中的注意力(细化细节)。
这些阶段之间的转折点是你应该开始混合事件语义的地方。
去噪时间线:
t=T(噪声)-----> 转折点 -----> t=0(清晰)
    |                |              |
    v                v              v
[全局布局]      [过渡]        [局部细节]
强制事件掩码    开始事件间    用混合提示词
               融合          细化边界
把它想象成画一幅有多个场景的壁画。
早期,你勾勒构图——每个场景在哪里,粗略形状。
你不希望场景在这里互相渗透,所以你遮住区域(事件分区掩码)。
但你在边界留下薄的重叠区。
中途,一旦布局锁定,你开始在边界混合颜色,让过渡看起来自然(跨事件提示词融合)。
到最后,你只是在每个场景内添加精细细节,但早期的边界混合确保没有刺眼的接缝。
关键概念
- 扩散中的转折点:扩散模型不是均匀去噪的——它们有阶段。
早期时间步建立全局结构(什么在哪里),晚期时间步细化局部细节(纹理、边缘)。
转折点是注意力从全局转向局部的时间步。
在这个点之前,改变提示词影响布局; 之后,它只影响细节。
TunerDiT 通过测量跨层的注意力熵来经验性地找到这个点。
高熵 = 全局注意力,低熵 = 局部注意力。
转折点是熵急剧下降的地方。
这很重要,因为你想在早期强制事件边界(布局阶段),但在晚期混合语义(细节阶段)。
- 事件分区掩码:不是随时间切换提示词(帧 1-10 用提示词 A,帧 11-20 用提示词 B),TunerDiT 在每帧内的空间上切换提示词。
想象一个有两个事件的视频:左半部分是”日出”,右半部分是”日落”。
在去噪期间,左区域只看到”日出”引导,右区域只看到”日落”。
但中间有一个过渡带,看到两个提示词的加权混合。
权重在带上逐渐变化(80% 日出 / 20% 日落 → 50/50 → 20/80)。
这创建了平滑的空间过渡而非时间切割。
带宽度可调——更宽的带 = 更平滑的过渡但更多事件混合。
- 跨事件提示词融合:转折点之后,布局固定但细节仍在形成。
这里,TunerDiT 将相邻事件语义注入每个事件的提示词。
具体来说:取事件 A 的文本嵌入,添加来自事件 B 嵌入的小加权分量,使用这个融合嵌入进行晚期引导。
为什么? 没有融合,即使有空间混合,事件也可能看起来视觉上不连贯——不同的光照,不同的物体风格。
融合确保语义一致性(如果两个事件都有”汽车”,汽车形状保持一致),同时允许属性变化(颜色、位置)。
融合权重是另一个可调参数。
框架转变
之前(时间提示词切换):              之后(TunerDiT):

去噪步骤:                            去噪步骤:
t=T  [提示词 A] -----> 帧 1-10        t=T  [空间掩码] -----> 所有帧
     [提示词 B] -----> 帧 11-20            [事件A | 带 | 事件B]
                                                |
问题:突兀切割,事件渗透               t=mid [检测到转折点]
                                                |
                                      t=0  [融合提示词] -----> 所有帧
                                           [过渡区中 A+B 混合]

                                      结果:平滑边界,清晰事件
一句话:从时间提示词切换(何时改变引导)到空间-语义引导(在哪里以及如何混合引导),核心转变是利用扩散的内在结构而非强加外部调度。
专家评审
选题眼光:真实缺口。
多事件生成是自然的用户需求(讲故事、教程、广告),现有方法确实挣扎。
问题位于可控性和长时程生成的交叉点——两者都是活跃研究领域。
不是人造的。
方法成熟度:巧妙洞察(探测转折点)结合直接的工程(掩码 + 融合)。
转折点发现是新颖部分; 引导手柄是渐进的但动机充分。
更简单的方法能行吗? 也许——分层提示或没有融合的注意力掩码可能获得 80% 的好处。
但作者展示了消融实验,证明两个组件都重要。
实验诚意:强。
他们策划了一个新基准(Meve),因为现有基准不测试多事件场景——公平之举。
基线包括最近的无训练方法(FreeNoise、MotionCtrl)和一个微调模型(Gen-L-Video)。
指标涵盖文本对齐、时间一致性和事件分离。
数字看起来扎实,扩展趋势(改进随事件数量增加)是一个好的合理性检查。
一个担忧:没有用户研究,所以”更好”纯粹是指标驱动的。
写作功力:结构清晰,动机充分。
探测分析(第 3.1 节)可以更紧凑——很多注意力热图但没有”转折点”的定量阈值。
方法部分密集; 伪代码块会有帮助。
消融实验彻底。
总体而言,对于 CV 论文来说清晰度高于平均水平。
判决:弱接收 — 具有实用价值的扎实贡献,但新颖性更多在应用(在 DiT 中找转折点)而非基础方法创新。
无训练角度有吸引力,结果令人信服。
有用户研究和失败模式分析会更强。
要点总结
探测你的模型:不要把扩散当黑盒。
测量跨时间步的注意力模式、激活统计或梯度流。
你会发现可以利用的结构(阶段、转折点)来控制。
这适用于视频之外——图像编辑、3D 生成,任何基于扩散的任务。
空间控制胜过时间控制用于多事件内容:不是随时间切换提示词(逐帧),而是分区空间并在边界混合。
这可以推广:对于多对象图像生成,每个对象掩码区域; 对于多说话人音频,分区频带。
过渡带被低估:硬边界(掩码 A vs 掩码 B)导致伪影。
软边界(在带上混合 A 和 B)更平滑但有混合风险。
可调带宽给用户一个一致性-分离权衡。
为任何分割或分区任务窃取这个模式。
晚期语义融合:一旦结构设定,注入跨区域语义以保持连贯性。
实践中:如果你用多个提示词生成复合图像,在去噪的最后 20-30% 步骤融合嵌入。
防止区域间的风格漂移。