Paper: 2603.30033 Authors: Timon Klein, Jonas Kusch, Sebastian Sager, Stefan Schnake, Steffen Schotthöfer Categories: cs.LG, cs.AI
The Gap
Attention mechanisms in transformers are memory hogs. Multi-headed attention (MHA) stores separate weight matrices for every head, which scales poorly. Recent fixes like Group-Query Attention (GQA) and Multi-head Latent Attention (MLA) reduce parameters through ad-hoc factorizations — GQA groups heads together, MLA compresses across embedding dimensions. But these methods emerged from engineering intuition, not principled approximation theory. Nobody knows what these factorizations actually approximate, what ranks they achieve, or how they relate to each other.
The gap: we have a zoo of efficient attention variants with no unifying theory. Each method is a point solution. We can’t compare their approximation quality, can’t interpolate between them, and can’t reason about what’s being traded off.
Problem: Memory explosion in MHA
   |
   v
Assumption: Attention weights have low-rank structure
   |
   v
Method: Tucker decomposition of 3D weight tensor
   |
   v
Evidence: 10x fewer parameters, comparable metrics
   |
   v
Conclusion: GQA/MLA are special cases of Tucker factorization
The Increment
One sentence: Before this paper, efficient attention methods were isolated tricks; after, they’re points in a continuous tensor decomposition space with interpretable rank budgets.
Core Mechanism
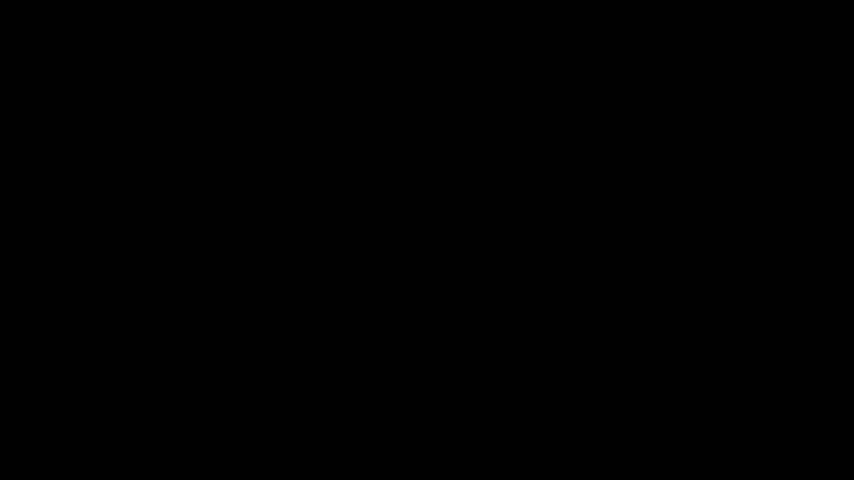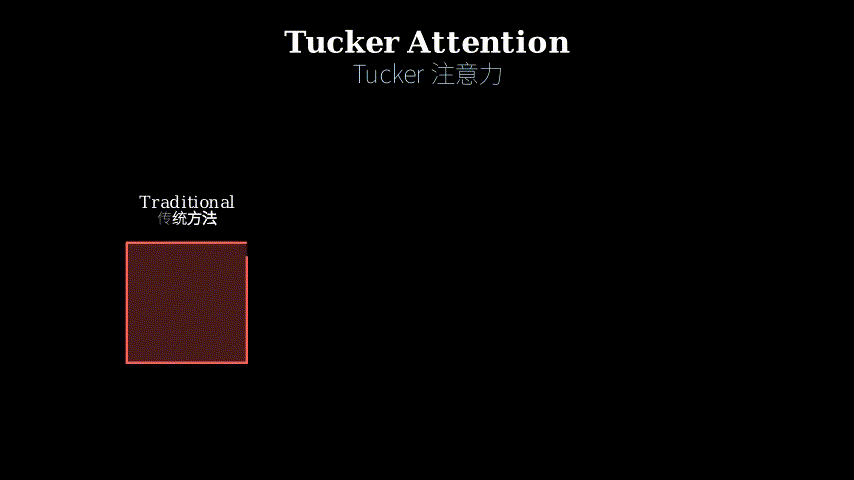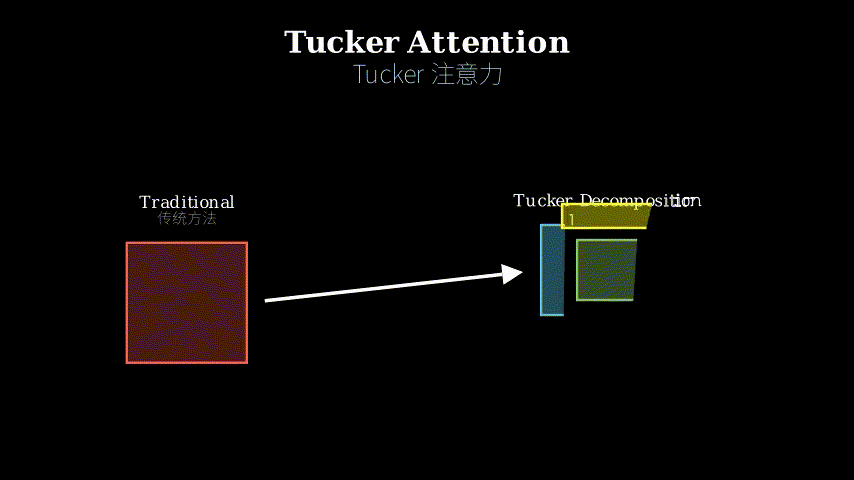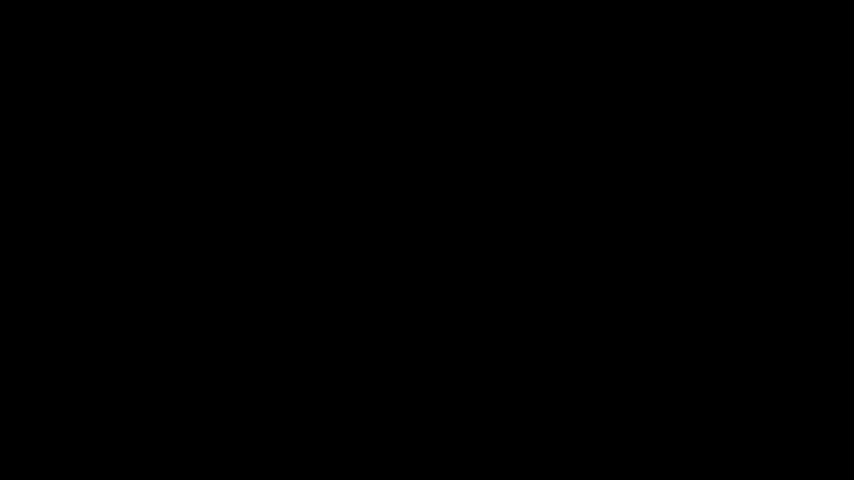
Standard MHA stores a 3D tensor of weights: (num_heads × head_dim × model_dim). Each head gets its own projection matrix. Tucker Attention factorizes this tensor into three smaller matrices plus a tiny core tensor. Think of it as compressing along three axes simultaneously: across heads, across head dimensions, and across model dimensions.
The factorization works like this: instead of storing the full weight tensor W, you store three factor matrices (U, V, S) and a small core tensor G. To reconstruct any slice of W, you multiply through the core: W ≈ G ×₁ U ×₂ V ×₃ S. The ranks of U, V, S control how much information you keep along each axis. Set the head-axis rank low, you get GQA. Set the embedding-axis rank low, you get MLA. Tune all three, you get Tucker Attention.
Standard MHA:
  Input ---[W_q]---> Q (full rank, all heads independent)
         |
         [W_k]---> K
         |
         [W_v]---> V

Tucker Attention:
  Input ---[S]---[Core G]---[U]---> Q (factored)
         |                    |
         [S]---[Core G]---[V]---> K
         |                    |
         [S]---[Core G]---[U]---> V

  Core G: tiny (r_h × r_d × r_m)
  Factor matrices: thin (heads×r_h, dim×r_d, model×r_m)
Here’s the structural metaphor: imagine MHA as a library where every book (head) has its own complete encyclopedia (weight matrix). Tucker Attention is like replacing those encyclopedias with a shared index system. You have three catalogs (the factor matrices U, V, S) and one master reference book (the core tensor G). To look up information for any head, you consult all three catalogs to find the right page in the master reference. The catalogs are thin — they just point to compressed knowledge. The master reference is tiny because it only stores the essential cross-references. GQA is like having multiple heads share the same catalog entry. MLA is like compressing the master reference along one dimension. Tucker does both, plus compresses the catalogs themselves.
Key Concepts
-
Tucker Decomposition: Imagine you have a 3D block of numbers (a tensor). Tucker decomposition is like finding three thin slices (one along each dimension) plus a tiny core block, such that when you multiply them back together in a specific way, you approximately reconstruct the original block. It’s the 3D generalization of matrix SVD. The “ranks” are how thick you make each slice — thicker means more accurate reconstruction but more parameters. In attention, the three dimensions are: which head, which position in the head, which position in the model. Tucker lets you compress all three simultaneously with independent rank budgets.
-
Rank Budget: In low-rank approximation, rank is how many independent patterns you keep. A rank-1 matrix can only represent one direction of variation. Rank-10 can represent ten independent patterns. In Tucker Attention, you have three rank budgets: r_h (how many independent head patterns), r_d (how many independent within-head patterns), r_m (how many independent model-dimension patterns). GQA only budgets r_h (groups heads). MLA only budgets r_m (compresses embeddings). Tucker budgets all three, which is why it needs fewer total parameters for the same approximation quality.
Framework Shift
Before (GQA/MLA):                After (Tucker Attention):
Compress one axis at a time      Compress all axes jointly

MHA: [H x D x M] tensor          Tucker: [H x D x M] tensor
  |                                |
  +--GQA--> group H                +---> [r_h x r_d x r_m] core
  |                                      + 3 factor matrices
  +--MLA--> compress M
                                   GQA = Tucker(r_h=small, r_d=D, r_m=M)
Isolated tricks                   MLA = Tucker(r_h=H, r_d=D, r_m=small)
No shared framework               MHA = Tucker(r_h=H, r_d=D, r_m=M)
From axis-specific compression to joint tensor factorization, the core shift is treating attention weights as a 3D object with exploitable structure along all dimensions simultaneously.
Expert Assessment
Problem choice: Real gap. Memory is the bottleneck for long-context transformers, and the proliferation of ad-hoc attention variants (GQA, MLA, GLA, etc.) genuinely lacks theoretical grounding. This paper asks the right question: what are these methods actually doing in approximation-theoretic terms?
Method maturity: Elegant insight, not brute force. Tucker decomposition is classical (1960s), but applying it to attention weight tensors is non-obvious because attention has never been framed as a 3D approximation problem. The realization that GQA and MLA are special cases is genuinely clarifying. However, the paper doesn’t explore why Tucker specifically — other tensor decompositions (CP, tensor train) might work too.
Experimental integrity: Baselines are fair. They compare against GQA and MLA on equal footing (same model size, same training setup). The LLM experiments (1.3B parameters) and ViT experiments are reasonable scale. One concern: they only report validation perplexity and accuracy, not downstream task performance or inference speed. The “order of magnitude fewer parameters” claim holds for the attention layer, but attention is ~30% of total model parameters, so the end-to-end savings are more modest than the headline suggests.
Writing quality: The paper front-loads tensor notation without building intuition first. Section 2 would benefit from a concrete numerical example (e.g., “here’s a 2×2×2 tensor, here’s its Tucker decomposition with ranks (1,1,1)”). The related work section is thorough but reads like a literature dump. The key insight — that GQA/MLA are rank-constrained Tucker — should be stated in the abstract, not buried in Section 4.
Verdict: weak accept — Solid theoretical contribution that unifies existing methods, but experimental validation is narrow and the practical impact is incremental rather than transformative.
Takeaways
For practitioners: if you’re designing a new efficient attention variant, start with Tucker decomposition and set rank budgets based on where your model has redundancy. Don’t invent a new factorization from scratch — you’re probably rediscovering a special case of Tucker.
For researchers: the “view attention as a 3D tensor” framing is transferable. Other transformer components (feedforward layers, embeddings) might also benefit from joint multi-axis compression instead of axis-by-axis tricks.
Concrete technique: when debugging why your efficient attention variant underperforms, compute the actual achieved ranks along each axis (via SVD of unfolded tensors). If one axis has much lower rank than your budget allows, you’re wasting parameters — reallocate the rank budget.
论文: 2603.30033 作者: Timon Klein, Jonas Kusch, Sebastian Sager, Stefan Schnake, Steffen Schotthöfer 分类: cs.LG, cs.AI
缺口
Transformer 的注意力机制很吃内存。
多头注意力(MHA)给每个头存一套独立的权重矩阵,扩展性很差。
最近的改进方法,比如分组查询注意力(GQA)和多头潜在注意力(MLA),通过特设的因式分解来减少参数——GQA 把多个头分组共享,MLA 在嵌入维度上压缩。
但这些方法都是工程直觉的产物,不是基于严格的近似理论。
没人知道这些因式分解到底在近似什么,达到了什么秩,彼此之间有什么关系。
缺口在于:我们有一堆高效注意力的变体,但没有统一的理论。
每个方法都是孤立的点解决方案。
我们无法比较它们的近似质量,无法在它们之间插值,也无法推理到底牺牲了什么。
问题: MHA 的内存爆炸
   |
   v
假设: 注意力权重有低秩结构
   |
   v
方法: 对 3D 权重张量做 Tucker 分解
   |
   v
证据: 参数减少 10 倍,指标相当
   |
   v
结论: GQA/MLA 是 Tucker 分解的特例
增量
一句话: 这篇论文之前,高效注意力方法是孤立的技巧;之后,它们成了连续张量分解空间中的点,有可解释的秩预算。
核心机制
标准 MHA 存储一个 3D 权重张量:(头数 × 头维度 × 模型维度)。
每个头有自己的投影矩阵。
Tucker 注意力把这个张量分解成三个更小的矩阵加一个微型核心张量。
可以理解为沿三个轴同时压缩:跨头、跨头内维度、跨模型维度。
分解的工作方式是这样的:不存储完整的权重张量 W,而是存储三个因子矩阵(U, V, S)和一个小核心张量 G。
要重建 W 的任何切片,通过核心相乘:W ≈ G ×₁ U ×₂ V ×₃ S。
U, V, S 的秩控制沿每个轴保留多少信息。
把头轴的秩设低,就得到 GQA。
把嵌入轴的秩设低,就得到 MLA。
三个都调,就得到 Tucker 注意力。
标准 MHA:
  输入 ---[W_q]---> Q (满秩,所有头独立)
        |
        [W_k]---> K
        |
        [W_v]---> V

Tucker 注意力:
  输入 ---[S]---[核心 G]---[U]---> Q (分解后)
        |                     |
        [S]---[核心 G]---[V]---> K
        |                     |
        [S]---[核心 G]---[U]---> V

  核心 G: 很小 (r_h × r_d × r_m)
  因子矩阵: 瘦长 (头数×r_h, 维度×r_d, 模型×r_m)
结构性比喻是这样的:把 MHA 想象成一个图书馆,每本书(头)都有自己的完整百科全书(权重矩阵)。
Tucker 注意力就像用共享索引系统替换那些百科全书。
你有三个目录(因子矩阵 U, V, S)和一本主参考书(核心张量 G)。
要查找任何头的信息,你查阅三个目录,在主参考书中找到正确的页面。
目录很薄——它们只是指向压缩后的知识。
主参考书很小,因为它只存储必要的交叉引用。
GQA 就像让多个头共享同一个目录条目。
MLA 就像沿一个维度压缩主参考书。
Tucker 两者都做,还压缩目录本身。
关键概念
- Tucker 分解: 想象你有一个 3D 数字块(张量)。
Tucker 分解就像找到三个薄片(沿每个维度一个)加一个微型核心块,当你以特定方式把它们乘回去时,能近似重建原始块。
它是矩阵 SVD 的 3D 推广。
“秩”就是每个切片的厚度——越厚重建越准确,但参数越多。
在注意力中,三个维度是:哪个头、头内哪个位置、模型中哪个位置。
Tucker 让你用独立的秩预算同时压缩这三个维度。
- 秩预算: 在低秩近似中,秩是你保留多少独立模式。
秩为 1 的矩阵只能表示一个变化方向。
秩为 10 可以表示十个独立模式。
在 Tucker 注意力中,你有三个秩预算:r_h(多少独立头模式)、r_d(多少独立头内模式)、r_m(多少独立模型维度模式)。
GQA 只预算 r_h(分组头)。
MLA 只预算 r_m(压缩嵌入)。
Tucker 三个都预算,这就是为什么它用更少的总参数达到相同的近似质量。
框架转变
之前(GQA/MLA):                   之后(Tucker 注意力):
一次压缩一个轴                    联合压缩所有轴

MHA: [H x D x M] 张量            Tucker: [H x D x M] 张量
  |                                |
  +--GQA--> 分组 H                 +---> [r_h x r_d x r_m] 核心
  |                                      + 3 个因子矩阵
  +--MLA--> 压缩 M
                                   GQA = Tucker(r_h=小, r_d=D, r_m=M)
孤立的技巧                         MLA = Tucker(r_h=H, r_d=D, r_m=小)
没有共享框架                       MHA = Tucker(r_h=H, r_d=D, r_m=M)
从特定轴压缩到联合张量分解,核心转变是把注意力权重当作一个 3D 对象,沿所有维度同时利用可挖掘的结构。
专家评审
选题眼光: 真实缺口。
内存是长上下文 Transformer 的瓶颈,各种特设注意力变体(GQA、MLA、GLA 等)的激增确实缺乏理论基础。
这篇论文问对了问题:这些方法在近似理论意义上到底在做什么?
方法成熟度: 优雅的洞见,不是蛮力。
Tucker 分解是经典方法(1960 年代),但把它应用到注意力权重张量上并不显然,因为注意力从未被框定为 3D 近似问题。
意识到 GQA 和 MLA 是特例,这个发现确实有启发性。
但论文没有探索为什么特别是 Tucker——其他张量分解(CP、张量链)可能也行。
实验诚意: 基线公平。
他们在同等条件下(相同模型大小、相同训练设置)与 GQA 和 MLA 比较。
LLM 实验(13 亿参数)和 ViT 实验的规模合理。
一个担忧:他们只报告验证困惑度和准确率,没有下游任务性能或推理速度。
“参数减少一个数量级”的说法对注意力层成立,但注意力只占模型总参数的约 30%,所以端到端的节省比标题暗示的要温和。
写作功力: 论文一上来就堆张量符号,没有先建立直觉。
第 2 节如果有具体数值例子会更好(比如”这是一个 2×2×2 张量,这是它秩为(1,1,1)的 Tucker 分解”)。
相关工作部分很全面,但读起来像文献堆砌。
关键洞见——GQA/MLA 是秩约束的 Tucker——应该写在摘要里,而不是埋在第 4 节。
判决: 弱接收 — 扎实的理论贡献,统一了现有方法,但实验验证范围窄,实际影响是渐进式而非变革性的。
要点总结
对实践者:如果你在设计新的高效注意力变体,从 Tucker 分解开始,根据模型哪里有冗余来设置秩预算。
不要从头发明新的因式分解——你很可能在重新发现 Tucker 的特例。
对研究者:“把注意力看作 3D 张量”这个框架可以迁移。
Transformer 的其他组件(前馈层、嵌入)可能也能从联合多轴压缩中受益,而不是逐轴技巧。
具体技术:当调试为什么你的高效注意力变体表现不佳时,计算沿每个轴实际达到的秩(通过展开张量的 SVD)。
如果某个轴的秩远低于你的预算,说明在浪费参数——重新分配秩预算。