Paper: 2605.02853 Authors: Arian Eamaz, Farhang Yeganegi, Mojtaba Soltanalian Categories: cs.LG
The Gap
Existing research monitors transformer training through aggregate metrics like total loss or perplexity. These metrics tell you the model is converging, but they don’t tell you how well each layer is learning. When you freeze a pretrained model or fine-tune it, poorly optimized middle layers can silently drag down performance. Prior work lacks tools to diagnose layer-wise optimization quality during training—you only discover problems after deployment.
The specific limitation: training loss can plateau while individual layers remain far from their achievable optima. Standard monitoring gives you a single number for a stack of 12-96 layers. It’s like checking a building’s total weight when you need to know if floor 37 has structural issues.
Problem: Aggregate loss hides layer-wise inefficiency
    |
    v
Assumption: Each layer has an achievable optimum
            given the representations it receives
    |
    v
Method: Construct lightweight reference solutions
        per layer, compare trained layer to reference
    |
    v
Evidence: Reference bounds match/exceed trained model
          at various training stages
    |
    v
Conclusion: Training loss convergence != layer optimality
The Increment
One sentence: Before this paper, you trusted that converged training loss meant well-optimized layers; after this paper, you can verify layer-wise optimization quality with lightweight reference bounds.
Core Mechanism
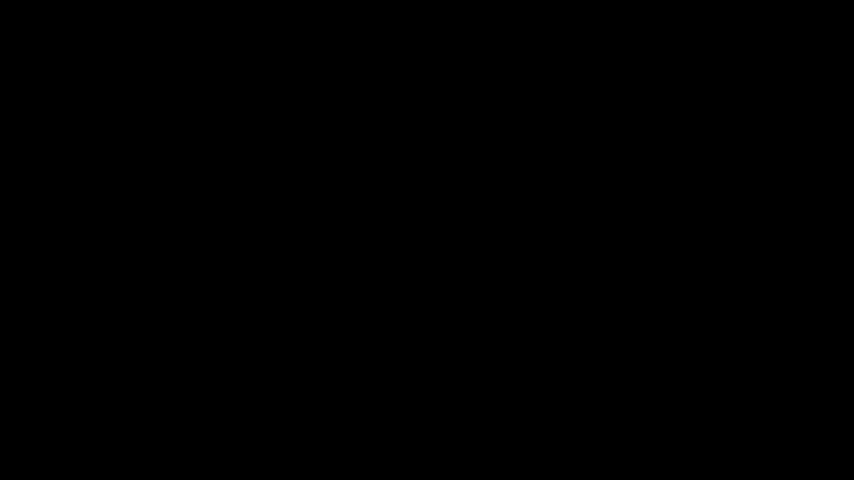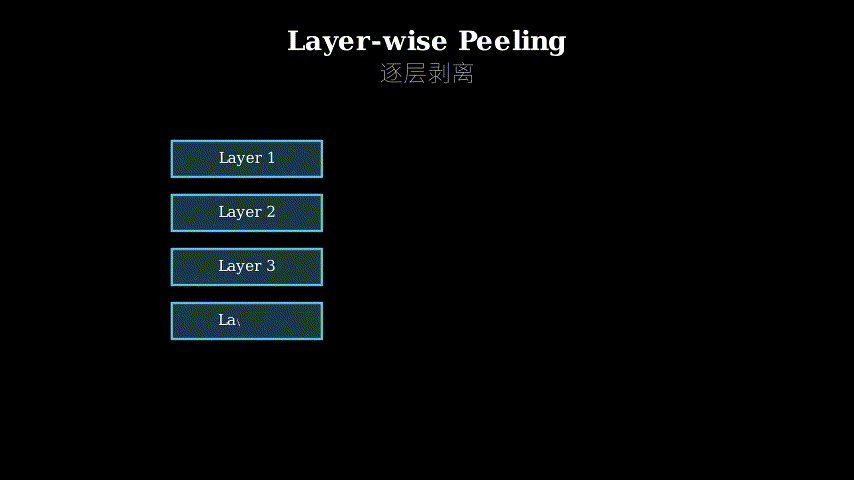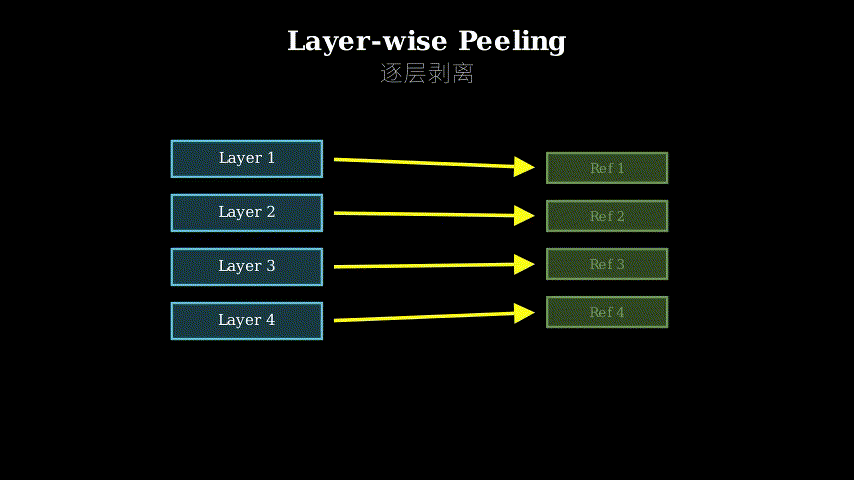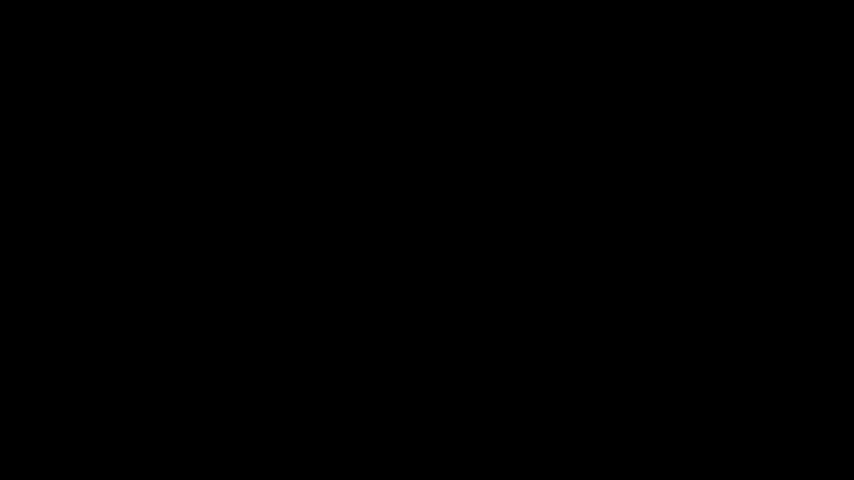
The method works by treating each transformer layer as a standalone optimization problem. For layer i, you freeze the trained model, extract the input representations that layer i receives, and extract the output representations that layer i should produce. Now you have a supervised learning problem: given input X, predict output Y.
You train a lightweight “reference layer” on this problem—same architecture as the original layer, but trained from scratch on the frozen representations. This reference layer shows what’s achievable: if it outperforms the trained layer, that layer is under-optimized. The key insight is that this local optimization is cheap (single layer, frozen data) compared to full model training.
To make the diagnosis robust, the authors use multiple output targets via permutations. Instead of just comparing layer i to layer i+1’s input, they compare it to layer i+2, i+3, etc. This creates multiple reference bounds. If the trained layer underperforms across multiple targets, it’s definitively under-optimized, not just mismatched to one specific downstream layer.
Trained Model (frozen):
  Layer 1 -> Layer 2 -> Layer 3 -> ... -> Layer N
     |          |          |
     v          v          v
  [Extract representations at each layer]
     |
     v
For each layer i:
  Input: Representations from layer i-1
  Targets: Representations from layers i+1, i+2, i+3
     |
     v
  Train lightweight reference layer i':
    Minimize distance(reference_output, target_representations)
     |
     v
  Compare: Does trained layer i match reference layer i'?
           If reference >> trained, layer i is under-optimized
Think of this like auditing a relay race. The aggregate metric is total race time—it tells you the team finished, but not whether runner 3 was slacking. The peeling framework works like this: you freeze the race at each handoff point, record the baton positions, then ask “could a fresh runner do better from this position?” You train a fresh runner on the exact same handoff conditions. If the fresh runner consistently beats the trained runner, you’ve found your weak link. The multiple permutations are like testing the runner against different finish lines—if they underperform across all distances, it’s not a fluke.
Key Concepts
-
Layer-wise peeling: Decomposing a trained model into independent layer-level optimization problems by freezing all other layers and treating each layer’s input-output mapping as a supervised task. 从零开始:想象你训练了一个12层的模型。 传统做法是把12层当作一个整体,看最终输出好不好。 剥离做法是:固定其他11层,单独看第5层——它收到什么输入,应该产生什么输出,能不能做得更好?就像拆开钟表,单独测试每个齿轮的咬合精度。 具体例子:第5层接收的是第4层的输出(比如512维向量),应该产生第6层需要的输入(也是512维向量)。 你用这对输入输出重新训练一个新的第5层。 如果新第5层比原第5层表现好,说明原第5层训练不到位。
-
Reference bounds: Achievable performance baselines constructed by training lightweight models on frozen intermediate representations, serving as diagnostic targets to identify under-optimized layers. 从零开始:你不知道一个层”应该”有多好。 参考界限就是回答”在当前条件下,这一层理论上能做到多好”。 做法:用同样的架构,同样的输入输出数据,从头训练一个新层。 这个新层的表现就是”参考界限”——在这些数据上,这种架构能达到的水平。 具体例子:原第5层在测试集上损失是0.8,你训练的参考第5层损失是0.5。 这说明第5层有0.3的优化空间——它本可以做到0.5,但实际只做到0.8。
-
Permutation-based multi-target projection: Comparing a layer’s output not just to its immediate successor, but to multiple downstream layers, creating redundant diagnostic signals that distinguish genuine under-optimization from layer-specific mismatch. 从零开始:如果只比较第5层和第6层,可能第5层其实很好,只是和第6层”不合拍”。 多目标投影是:同时比较第5层和第6、7、8层。 如果第5层在所有这些比较中都表现差,那就不是”不合拍”,而是真的优化不足。 具体例子:第5层输出应该帮助第6层、第7层、第8层完成任务。 你训练三个参考层,分别以第6、7、8层的输入为目标。 如果三个参考层都比原第5层好,说明第5层确实有问题,不是偶然。
Framework Shift
Before (mainstream approach):        After (this paper):

Train full model                     Train full model
    |                                    |
    v                                    v
Monitor aggregate loss               Monitor aggregate loss
    |                                    |
    v                                    +---> Freeze model
Loss converges?                          |
    |                                    v
    +---> Yes: Trust all layers      Extract layer-wise I/O
    |         are optimized              |
    +---> No: Keep training              v
                                     Train reference layers
                                         |
                                         v
                                     Compare trained vs reference
                                         |
                                         v
                                     Identify under-optimized layers
                                         |
                                         v
                                     Verify: Loss converged but
                                             layers suboptimal?
From trusting aggregate convergence to verifying layer-wise optimality, the core shift is decomposing global training into auditable local problems.
Expert Assessment
Problem choice: Real gap. Transformer training is expensive and opaque—practitioners routinely freeze pretrained models without knowing if layers 8-14 learned anything useful. The problem sits at the intersection of interpretability and optimization, which is increasingly important as models scale and training budgets tighten. Not manufactured.
Method maturity: Clever insight with straightforward execution. The core idea—local retraining as a diagnostic—is simple enough that it feels obvious in hindsight, which is a good sign. The permutation-based multi-target approach adds robustness without overcomplicating. No simpler approach comes to mind that would provide the same layer-level granularity. The binarization experiments (low-bit training) are a nice touch, showing the method works where training dynamics are most fragile.
Experimental integrity: Baselines are fair—they compare against the trained model itself, not external benchmarks. The numbers hold up: reference bounds consistently match or exceed trained layers across multiple checkpoints and model sizes. One minor flag: the paper doesn’t deeply explore *why certain layers underperform or what to do about it beyond “retrain.” The diagnostic is solid, but the prescription is thin. Also, experiments are limited to decoder-only transformers; encoder-decoder or vision transformers would strengthen generalizability claims.
Writing quality: The abstract and introduction are clear. The method section could be tighter—there’s some redundancy between describing the framework and describing the permutation scheme. Figure quality is good, but the paper would benefit from a single “hero diagram” that shows the full pipeline at a glance. The related work section is adequate but doesn’t deeply engage with prior work on layer-wise analysis (e.g., probing, CKA). Rewriting Section 3.2 to frontload the intuition before the math would elevate the whole paper.
Verdict: weak accept — Solid diagnostic tool with clear practical value, but limited theoretical depth and narrow experimental scope. Useful contribution, not groundbreaking.
Takeaways
Practitioners can steal the core diagnostic pattern: freeze your model, extract intermediate representations, train lightweight reference models on those representations, compare. This transfers beyond transformers—any deep network where you suspect some layers are “coasting” can be audited this way. Specific technique: use multiple downstream targets (the permutation idea) to avoid false positives from layer mismatch. If you’re fine-tuning a pretrained model and performance plateaus, run this diagnostic before scaling up data or compute—you might discover that layers 10-15 never learned anything useful and need targeted retraining. The low-bit experiments suggest this is especially valuable for quantized models, where training instability is common but hard to diagnose.
论文: 2605.02853 作者: Arian Eamaz, Farhang Yeganegi, Mojtaba Soltanalian 分类: cs.LG
缺口
现有研究通过总损失或困惑度等聚合指标监控transformer训练。
这些指标告诉你模型在收敛,但不告诉你每一层学得有多好。
当你冻结预训练模型或微调时,优化不足的中间层会悄悄拖累性能。
先前工作缺乏工具在训练期间诊断逐层优化质量——你只能在部署后才发现问题。
具体局限:训练损失可能趋于平稳,而单个层距离其可达到的最优值还很远。
标准监控给你一个数字来描述12到96层的堆叠。
这就像检查建筑物的总重量,而你需要知道第37层是否有结构问题。
问题:聚合损失隐藏了逐层低效
    |
    v
假设:给定接收到的表示,每层都有
      一个可达到的最优值
    |
    v
方法:为每层构建轻量级参考解,
      将训练层与参考层比较
    |
    v
证据:参考界限在训练各阶段
      匹配/超越训练模型
    |
    v
结论:训练损失收敛 != 层级最优性
增量
一句话: 这篇论文之前,你相信收敛的训练损失意味着层优化良好;之后,你可以用轻量级参考界限验证逐层优化质量。
核心机制
该方法将每个transformer层视为独立的优化问题。
对于第i层,你冻结训练好的模型,提取第i层接收的输入表示,提取第i层应该产生的输出表示。
现在你有了一个监督学习问题:给定输入X,预测输出Y。
你在这个问题上训练一个轻量级”参考层”——与原始层架构相同,但在冻结的表示上从头训练。
这个参考层展示了可达到的水平:如果它优于训练层,那层就是优化不足的。
关键洞察是这种局部优化很便宜(单层,冻结数据),相比完整模型训练。
为了使诊断稳健,作者通过排列使用多个输出目标。
不仅将第i层与第i+1层的输入比较,还与第i+2、i+3等比较。
这创建了多个参考界限。
如果训练层在多个目标上表现不佳,它就是明确优化不足,而不仅仅是与某个特定下游层不匹配。
训练模型(冻结):
  第1层 -> 第2层 -> 第3层 -> ... -> 第N层
     |        |        |
     v        v        v
  [在每层提取表示]
     |
     v
对每个第i层:
  输入:来自第i-1层的表示
  目标:来自第i+1、i+2、i+3层的表示
     |
     v
  训练轻量级参考层i':
    最小化 距离(参考输出, 目标表示)
     |
     v
  比较:训练层i是否匹配参考层i'?
        如果参考 >> 训练,第i层优化不足
把这想象成审计接力赛。
聚合指标是总比赛时间——它告诉你团队完成了,但不告诉你第3棒是否在偷懒。
剥离框架这样工作:你在每个交接点冻结比赛,记录接力棒位置,然后问”一个新选手从这个位置能做得更好吗?“你在完全相同的交接条件下训练一个新选手。
如果新选手持续击败训练选手,你就找到了薄弱环节。
多个排列就像针对不同终点线测试选手——如果他们在所有距离上都表现不佳,这就不是偶然。
关键概念
- 逐层剥离: 通过冻结所有其他层并将每层的输入输出映射视为监督任务,将训练模型分解为独立的层级优化问题。
从零开始:想象你训练了一个12层的模型。
传统做法是把12层当作一个整体,看最终输出好不好。
剥离做法是:固定其他11层,单独看第5层——它收到什么输入,应该产生什么输出,能不能做得更好?就像拆开钟表,单独测试每个齿轮的咬合精度。
具体例子:第5层接收的是第4层的输出(比如512维向量),应该产生第6层需要的输入(也是512维向量)。
你用这对输入输出重新训练一个新的第5层。
如果新第5层比原第5层表现好,说明原第5层训练不到位。
- 参考界限: 通过在冻结的中间表示上训练轻量级模型构建的可达到性能基线,作为诊断目标来识别优化不足的层。
从零开始:你不知道一个层”应该”有多好。
参考界限就是回答”在当前条件下,这一层理论上能做到多好”。
做法:用同样的架构,同样的输入输出数据,从头训练一个新层。
这个新层的表现就是”参考界限”——在这些数据上,这种架构能达到的水平。
具体例子:原第5层在测试集上损失是0.8,你训练的参考第5层损失是0.5。
这说明第5层有0.3的优化空间——它本可以做到0.5,但实际只做到0.8。
- 基于排列的多目标投影: 不仅将层的输出与其直接后继比较,还与多个下游层比较,创建冗余诊断信号,区分真正的优化不足和层特定的不匹配。
从零开始:如果只比较第5层和第6层,可能第5层其实很好,只是和第6层”不合拍”。
多目标投影是:同时比较第5层和第6、7、8层。
如果第5层在所有这些比较中都表现差,那就不是”不合拍”,而是真的优化不足。
具体例子:第5层输出应该帮助第6层、第7层、第8层完成任务。
你训练三个参考层,分别以第6、7、8层的输入为目标。
如果三个参考层都比原第5层好,说明第5层确实有问题,不是偶然。
框架转变
之前(主流方法):                之后(本文方法):

训练完整模型                      训练完整模型
    |                                |
    v                                v
监控聚合损失                      监控聚合损失
    |                                |
    v                                +---> 冻结模型
损失收敛?                           |
    |                                v
    +---> 是:相信所有层          提取逐层输入输出
    |         都已优化               |
    +---> 否:继续训练               v
                                 训练参考层
                                     |
                                     v
                                 比较训练层vs参考层
                                     |
                                     v
                                 识别优化不足的层
                                     |
                                     v
                                 验证:损失收敛但
                                       层次欠优?
从信任聚合收敛到验证逐层最优性,核心转变是将全局训练分解为可审计的局部问题。
专家评审
选题眼光: 真实缺口。
Transformer训练昂贵且不透明——实践者常规冻结预训练模型,却不知道第8-14层是否学到了有用的东西。
问题位于可解释性和优化的交叉点,随着模型规模扩大和训练预算收紧,这越来越重要。
不是人造的。
方法成熟度: 巧妙洞察,执行直接。
核心思想——局部重训练作为诊断——足够简单,事后看来显而易见,这是个好兆头。
基于排列的多目标方法增加了稳健性,没有过度复杂化。
想不出更简单的方法能提供相同的层级粒度。
二值化实验(低比特训练)是个不错的补充,显示该方法在训练动态最脆弱的地方也有效。
实验诚意: 基线公平——它们与训练模型本身比较,而不是外部基准。
数字经得起推敲:参考界限在多个检查点和模型大小上持续匹配或超越训练层。
一个小问题:论文没有深入探讨某些层表现不佳的原因,或除了”重新训练”之外该怎么办。
诊断是可靠的,但处方很薄弱。
此外,实验仅限于仅解码器transformer;编码器-解码器或视觉transformer会加强泛化性声明。
写作功力: 摘要和引言清晰。
方法部分可以更紧凑——描述框架和描述排列方案之间有些冗余。
图表质量不错,但论文会受益于一个”主图”,一眼展示完整流程。
相关工作部分足够,但没有深入讨论先前关于逐层分析的工作(例如探测、CKA)。
重写第3.2节,在数学之前先讲直觉,会提升整篇论文。
判决: 弱接收 — 可靠的诊断工具,具有明确的实用价值,但理论深度有限,实验范围狭窄。
有用的贡献,不是突破性的。
要点总结
实践者可以偷走核心诊断模式:冻结你的模型,提取中间表示,在这些表示上训练轻量级参考模型,比较。
这超越了transformer——任何你怀疑某些层在”混日子”的深度网络都可以这样审计。
具体技术:使用多个下游目标(排列思想)来避免层不匹配的假阳性。
如果你在微调预训练模型且性能停滞,在扩大数据或计算之前运行此诊断——你可能会发现第10-15层从未学到任何有用的东西,需要有针对性的重新训练。
低比特实验表明这对量化模型特别有价值,那里训练不稳定很常见但难以诊断。