Paper: 2604.04921 Authors: Weian Mao, Xi Lin, Wei Huang, Yuxin Xie, Tianfu Fu, Bohan Zhuang, Song Han, Yukang Chen Categories: cs.CL, cs.CV
The Gap
Existing KV cache compression methods (H2O, StreamingLLM, SnapKV) estimate key importance using attention scores from recent post-RoPE queries. The problem: RoPE rotates queries with position, making any single query unrepresentative of future queries at different positions. This leads to unstable key selection and degraded reasoning accuracy, especially in long-context scenarios requiring extended chain-of-thought.
The boundary: Post-RoPE space is position-dependent, so importance estimates are myopic. Prior work hasn’t exploited the pre-RoPE space where queries and keys exhibit position-invariant structure.
Problem: Long context reasoning exhausts KV cache memory
                    |
                    v
Prior approach: Compress KV cache using post-RoPE attention scores
                    |
                    v
Limitation: Queries rotate -> few representative samples -> poor key selection
                    |
                    v
Observation: Pre-RoPE Q/K vectors concentrate around fixed centers
                    |
                    v
Assumption: Centers encode distance preference via trigonometric series
                    |
                    v
Method: Score keys by position using centers + trigonometric formula
                    |
                    v
Evidence: AIME25 32K tokens - full accuracy, 2.5x throughput (vs 50% accuracy for baselines)
                    |
                    v
Conclusion: Pre-RoPE structure enables stable, position-aware KV compression
The Increment
One sentence: Before this paper, KV compression relied on unstable post-RoPE attention patterns; after, we can predict key importance from stable pre-RoPE geometric structure.
Core Mechanism
TriAttention operates in three stages. First, it analyzes the pre-RoPE space to extract Q/K concentration centers—fixed vectors around which queries and keys cluster across all positions. Second, it derives a trigonometric scoring function from these centers: the dot product between Q and K centers produces a cosine series that predicts attention preference as a function of relative distance. Third, it combines this distance-based score with Q/K norms (magnitude signals) to rank keys, keeping only the top-scoring subset.
Data flows like this: input tokens → pre-RoPE Q/K vectors → extract centers (one-time calibration) → for each new token, compute trigonometric score for all cached keys based on distance → multiply by norm ratio → select top keys → apply RoPE and standard attention on compressed cache.
The key operation is the trigonometric series evaluation: score(distance) = sum_i cos(i * distance * theta_i), where theta values come from the Q/K center geometry. This replaces expensive attention computation with cheap trigonometric lookups indexed by relative position.
Input tokens
     |
     v
[Pre-RoPE Q/K extraction]
     |
     +---> [Center calibration] (one-time)
     |           |
     |           v
     |     Q_center, K_center
     |           |
     v           v
[New token] -> [Trigonometric scoring]
                score(d) = cos(d*theta_1) + cos(d*theta_2) + ...
                     |
                     v
               [Norm weighting]
                score *= ||Q|| * ||K||
                     |
                     v
               [Top-K selection]
                     |
                     v
               [Compressed KV cache] -> Standard attention
Think of TriAttention as a lighthouse system. Traditional methods (post-RoPE scoring) are like a lighthouse that rotates—its beam sweeps different directions at different times, so you can’t predict where it’ll shine next. TriAttention instead looks at the lighthouse’s fixed foundation (pre-RoPE centers). The foundation’s orientation determines a predictable pattern: “this lighthouse always illuminates points at 30°, 90°, 150° relative to its base.” The trigonometric series is the formula that maps foundation geometry to beam pattern. When a new ship (query) arrives, instead of waiting to see where the rotating beam points, you calculate “given this foundation and the ship’s position, will it be illuminated?” The norm weighting is like accounting for beam intensity and ship reflectivity. You keep only the ships (keys) that will be brightly lit, discarding the rest. The foundation never moves, so the pattern stays stable even as ships arrive at different positions.
Key Concepts
-
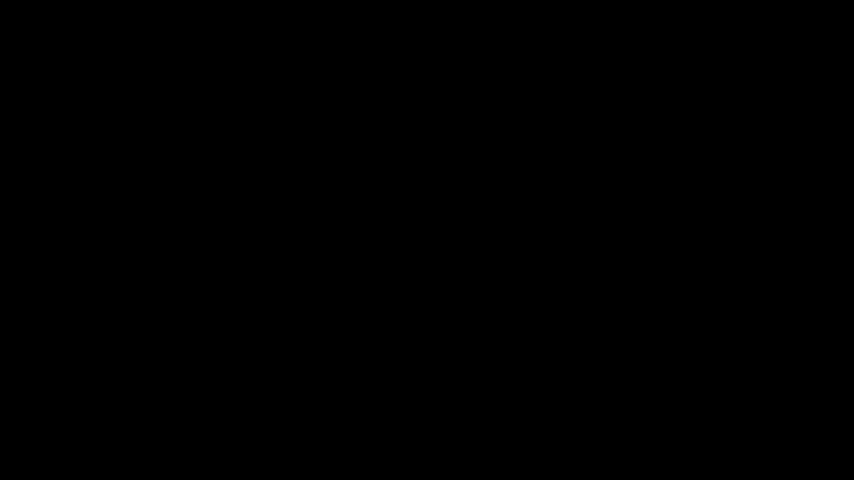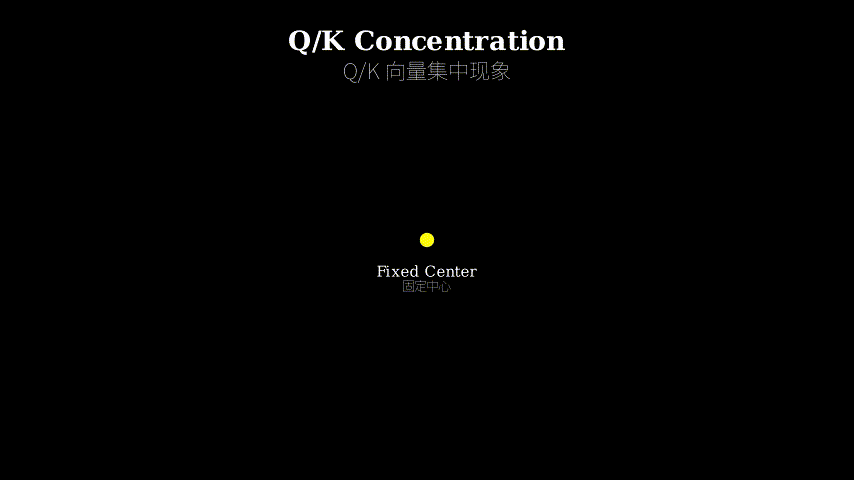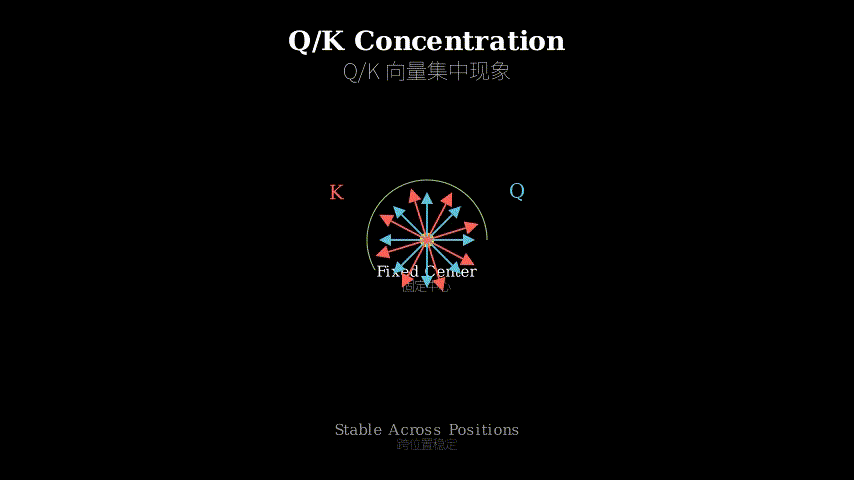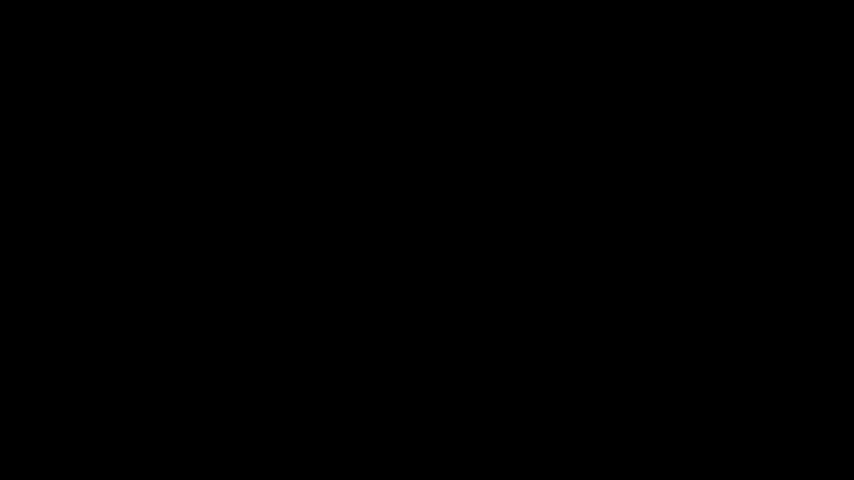
Q/K Concentration: In the pre-RoPE space (before rotary position encoding is applied), query and key vectors don’t scatter randomly across the embedding dimension. Instead, they cluster tightly around fixed, non-zero center vectors that remain stable regardless of token position. Imagine throwing darts at a board: instead of hitting everywhere, all darts land in a small circle around a fixed point. This concentration means we can characterize the entire distribution of Q/K vectors with just their centers, drastically reducing the information needed to predict attention patterns. Concretely, if you compute the mean of all query vectors before RoPE across a calibration set, that mean vector (Q_center) captures the dominant direction queries point toward.
-
Trigonometric Distance Preference: Because Q and K centers are fixed, their dot product after RoPE becomes a trigonometric series in the relative distance between tokens. RoPE rotates vectors by an angle proportional to position, so
Q(pos_i) · K(pos_j)after rotation equalsQ_center · K_centerrotated by(pos_i - pos_j) ** theta. This expands intocos(distance * theta_1) + cos(distance * theta_2) + ...for different frequency components. The result: attention preference becomes a periodic function of distance—queries naturally prefer keys at specific relative positions (e.g., nearest neighbors, or tokens exactly 512 positions away). This is why the method is called “TriAttention”—the trigonometric series encodes which distances matter. -
Norm as Importance Signal: Beyond position, the magnitude (L2 norm) of Q and K vectors signals importance. A query with large norm is “shouting loudly” and will attend strongly to any key; a key with large norm is “highly visible” and will attract attention from any query. TriAttention multiplies the trigonometric distance score by
||Q|| ** ||K||to capture this: a key at a preferred distance with high norm scores higher than a key at the same distance with low norm. This is analogous to both distance and brightness mattering when deciding which stars to observe—a bright star far away might beat a dim star nearby.
Framework Shift
Before (post-RoPE scoring):          After (TriAttention):

Query at pos=100                     Pre-RoPE centers (fixed)
     |                                    Q_center, K_center
     v                                         |
Compute attention to all keys                 v
     |                               Trigonometric formula
     v                                score(d) = f(centers, d)
Score keys by attention                       |
     |                                         v
     v                               For each key: score(pos_key - pos_query)
Keep top keys                                 |
                                              v
Problem: Query rotates next step    Keep top keys by score + norm
-> scores invalid
                                    Benefit: Formula stable across positions
One sentence: From chasing rotating attention patterns to predicting attention from fixed geometric structure, the core shift is position-dependence to position-invariance.
Expert Assessment
Problem choice: Real gap. KV cache memory is the bottleneck for long-context LLMs in production (e.g., OpenClaw deployment). Prior compression methods do degrade reasoning accuracy significantly on hard benchmarks like AIME, so this isn’t manufactured. The problem sits at the intersection of efficiency and capability—timely given the push toward 100K+ context windows.
Method maturity: Clever insight, not brute force. The Q/K concentration observation is genuinely novel and the trigonometric derivation is mathematically grounded. However, the method requires calibration (computing centers on a dataset), which adds deployment friction. A simpler baseline—just using distance and norms without the trigonometric series—isn’t thoroughly ablated. The paper could be clearer on when concentration holds (does it break for certain architectures or tasks?).
Experimental integrity: Baselines are fair (H2O, StreamingLLM, SnapKV are leading methods). The AIME25 results are striking (full accuracy vs ~50% for baselines), but AIME is a single reasoning-heavy benchmark. Broader evaluation on diverse long-context tasks (retrieval, summarization, multi-hop QA) would strengthen claims. The throughput measurements are credible (2.5x is modest, not outlandish). One red flag: the paper doesn’t discuss failure modes—when does TriAttention degrade?
Writing quality: The core idea is buried. Section 3.1 (Q/K concentration) should lead the paper, but it’s preceded by dense motivation. The trigonometric derivation in 3.2 is rigorous but could use a visual diagram showing how centers → cosine series → distance preference. The related work section is perfunctory—doesn’t position the work within the broader KV compression landscape (e.g., how does this relate to sparse attention patterns like local+strided?). Rewriting the introduction to lead with “we discovered Q/K concentration” would elevate the whole paper.
Verdict: Weak accept — solid contribution with a novel geometric insight, but needs broader empirical validation and clearer exposition of when the method applies.
Takeaways
Steal the concentration hypothesis: Before compressing or pruning in any learned representation space, check if your vectors concentrate around fixed centers. If they do, you can replace expensive pairwise computations (attention, similarity search) with cheap lookups indexed by a low-dimensional summary (the centers). This applies beyond transformers—think graph neural networks (node embeddings), recommendation systems (user/item vectors), or retrieval (query/document embeddings).
Trigonometric series as a design pattern: When your data has rotational symmetry (RoPE, circular convolutions, phase-based encodings), express relationships as trigonometric series rather than learned weights. The series is interpretable (each frequency component has meaning), parameter-efficient (a few Fourier coefficients vs a full matrix), and stable (doesn’t drift with position). Use this for any architecture where position is encoded as rotation.
Norm as a universal importance signal: In attention mechanisms, vector magnitude is often ignored (cosine similarity normalizes it away). TriAttention shows that norm carries orthogonal information to direction—it’s a proxy for “how much does this token matter?” Practitioners can add norm-based gating to any attention variant (cross-attention, self-attention, memory-augmented models) as a cheap importance filter before expensive operations.
论文: 2604.04921 作者: Weian Mao, Xi Lin, Wei Huang, Yuxin Xie, Tianfu Fu, Bohan Zhuang, Song Han, Yukang Chen 分类: cs.CL, cs.CV
缺口
现有的 KV 缓存压缩方法(H2O、StreamingLLM、SnapKV)使用 RoPE 后的最近查询的注意力分数来估计键的重要性。
问题在于:RoPE 会随位置旋转查询向量,导致任何单个查询都无法代表未来不同位置的查询。
这导致键选择不稳定,推理精度下降,尤其是在需要长链式思考的长上下文场景中。
边界:RoPE 后的空间依赖位置,因此重要性估计是短视的。
先前工作没有利用 RoPE 前的空间,而那里的查询和键展现出位置不变的结构。
问题:长上下文推理耗尽 KV 缓存内存
                |
                v
先前方法:用 RoPE 后的注意力分数压缩 KV 缓存
                |
                v
局限:查询旋转 -> 代表性样本少 -> 键选择差
                |
                v
观察:RoPE 前的 Q/K 向量围绕固定中心集中
                |
                v
假设:中心通过三角级数编码距离偏好
                |
                v
方法:用中心 + 三角公式根据位置给键打分
                |
                v
证据:AIME25 32K tokens - 完整精度,2.5 倍吞吐(基线仅 50% 精度)
                |
                v
结论:RoPE 前结构支持稳定的位置感知 KV 压缩
增量
一句话:这篇论文之前,KV 压缩依赖不稳定的 RoPE 后注意力模式;之后,我们可以从稳定的 RoPE 前几何结构预测键的重要性。
核心机制
TriAttention 分三个阶段运作。
首先,它分析 RoPE 前的空间以提取 Q/K 集中中心——查询和键在所有位置上聚集的固定向量。
其次,它从这些中心推导出三角评分函数:Q 和 K 中心的点积产生一个余弦级数,该级数将注意力偏好预测为相对距离的函数。
第三,它将这个基于距离的分数与 Q/K 范数(幅度信号)结合来对键排序,只保留得分最高的子集。
数据流动如下:输入 tokens → RoPE 前的 Q/K 向量 → 提取中心(一次性校准)→ 对于每个新 token,根据距离计算所有缓存键的三角分数 → 乘以范数比 → 选择 top 键 → 在压缩缓存上应用 RoPE 和标准注意力。
关键操作是三角级数求值:score(distance) = sum_i cos(i * distance * theta_i),其中 theta 值来自 Q/K 中心几何。
这用廉价的按相对位置索引的三角查找替代了昂贵的注意力计算。
输入 tokens
     |
     v
[RoPE 前 Q/K 提取]
     |
     +---> [中心校准](一次性)
     |           |
     |           v
     |     Q_center, K_center
     |           |
     v           v
[新 token] -> [三角评分]
                score(d) = cos(d*theta_1) + cos(d*theta_2) + ...
                     |
                     v
               [范数加权]
                score *= ||Q|| * ||K||
                     |
                     v
               [Top-K 选择]
                     |
                     v
               [压缩 KV 缓存] -> 标准注意力
把 TriAttention 想象成一个灯塔系统。
传统方法(RoPE 后评分)就像一个旋转的灯塔——它的光束在不同时刻扫向不同方向,所以你无法预测它下一步会照向哪里。
TriAttention 转而观察灯塔的固定基座(RoPE 前的中心)。
基座的朝向决定了一个可预测的模式:“这个灯塔总是照亮相对于其基座 30°、90°、150° 的点。“三角级数就是将基座几何映射到光束模式的公式。
当一艘新船(查询)到达时,你不用等着看旋转光束指向哪里,而是计算”给定这个基座和船的位置,它会被照亮吗?“范数加权就像考虑光束强度和船的反射率。
你只保留会被明亮照亮的船(键),丢弃其余的。
基座永不移动,所以即使船在不同位置到达,模式也保持稳定。
关键概念
- Q/K 集中现象:在 RoPE 前的空间(应用旋转位置编码之前),查询和键向量不会在嵌入维度上随机散布。
相反,它们紧密聚集在固定的非零中心向量周围,这些中心向量无论 token 位置如何都保持稳定。
想象向靶子投掷飞镖:不是打得到处都是,而是所有飞镖都落在围绕固定点的小圆圈内。
这种集中意味着我们可以仅用中心来刻画 Q/K 向量的整个分布,大幅减少预测注意力模式所需的信息。
具体来说,如果你在校准集上计算 RoPE 前所有查询向量的均值,那个均值向量(Q_center)就捕获了查询指向的主导方向。
- 三角距离偏好:因为 Q 和 K 中心是固定的,它们在 RoPE 后的点积变成了 tokens 间相对距离的三角级数。
RoPE 按与位置成比例的角度旋转向量,所以旋转后的 Q(pos_i) · K(pos_j) 等于 Q_center · K_center 旋转 (pos_i - pos_j) * theta。
这展开为不同频率分量的 cos(distance * theta_1) + cos(distance * theta_2) + ...。
结果:注意力偏好变成距离的周期函数——查询自然偏好特定相对位置的键(例如,最近邻,或恰好相距 512 个位置的 tokens)。
这就是该方法被称为”TriAttention”的原因——三角级数编码了哪些距离重要。
- 范数作为重要性信号:除了位置,Q 和 K 向量的幅度(L2 范数)也标志着重要性。
范数大的查询是在”大声喊叫”,会强烈关注任何键;范数大的键”高度可见”,会吸引任何查询的注意力。
TriAttention 将三角距离分数乘以 ||Q|| * ||K|| 来捕获这一点:处于偏好距离且范数高的键比相同距离但范数低的键得分更高。
这类似于决定观察哪些星星时距离和亮度都重要——远处的亮星可能胜过近处的暗星。
框架转变
之前(RoPE 后评分):              之后(TriAttention):

位置 100 的查询                    RoPE 前的中心(固定)
     |                                  Q_center, K_center
     v                                       |
计算对所有键的注意力                          v
     |                               三角公式
     v                                score(d) = f(centers, d)
按注意力给键打分                              |
     |                                         v
     v                               对每个键:score(pos_key - pos_query)
保留 top 键                                   |
                                              v
问题:下一步查询旋转              按分数 + 范数保留 top 键
-> 分数失效
                                    优势:公式跨位置稳定
一句话:从追逐旋转的注意力模式到从固定几何结构预测注意力,核心转变是从位置依赖到位置不变。
专家评审
选题眼光:真实缺口。
KV 缓存内存是生产环境中长上下文 LLMs 的瓶颈(例如 OpenClaw 部署)。
先前的压缩方法在 AIME 等困难基准上确实显著降低推理精度,所以这不是人造问题。
该问题处于效率与能力的交叉点——鉴于向 100K+ 上下文窗口的推进,时机恰当。
方法成熟度:巧劲,非蛮力。
Q/K 集中观察确实新颖,三角推导有数学基础。
然而,该方法需要校准(在数据集上计算中心),这增加了部署摩擦。
一个更简单的基线——仅使用距离和范数而不用三角级数——没有被彻底消融。
论文可以更清楚地说明集中何时成立(对某些架构或任务会失效吗?)。
实验诚意:基线公平(H2O、StreamingLLM、SnapKV 是领先方法)。
AIME25 结果引人注目(完整精度 vs 基线约 50%),但 AIME 是单一的推理密集型基准。
在多样化的长上下文任务(检索、摘要、多跳 QA)上的更广泛评估会加强主张。
吞吐量测量可信(2.5 倍是适度的,不离谱)。
一个警示:论文没有讨论失效模式——TriAttention 何时会退化?
写作功力:核心思想被埋没了。
3.1 节(Q/K 集中)应该引领论文,但它前面是密集的动机部分。
3.2 中的三角推导严谨但可以用视觉图表展示中心 → 余弦级数 → 距离偏好。
相关工作部分敷衍——没有将工作定位在更广泛的 KV 压缩景观中(例如,这与局部+跨步等稀疏注意力模式有何关系?)。
重写引言以”我们发现了 Q/K 集中”开头会提升整篇论文。
判决:弱接收 — 具有新颖几何洞察的扎实贡献,但需要更广泛的实证验证和更清晰的方法适用性阐述。
要点总结
偷走集中假设:在任何学习表示空间中压缩或剪枝之前,检查你的向量是否围绕固定中心集中。
如果是,你可以用按低维摘要(中心)索引的廉价查找替代昂贵的成对计算(注意力、相似性搜索)。
这超越了 transformers——想想图神经网络(节点嵌入)、推荐系统(用户/物品向量)或检索(查询/文档嵌入)。
三角级数作为设计模式:当你的数据具有旋转对称性(RoPE、循环卷积、基于相位的编码)时,将关系表达为三角级数而非学习权重。
级数可解释(每个频率分量有意义)、参数高效(几个傅里叶系数 vs 完整矩阵)且稳定(不随位置漂移)。
将此用于任何位置被编码为旋转的架构。
范数作为通用重要性信号:在注意力机制中,向量幅度常被忽略(余弦相似度将其归一化掉)。
TriAttention 表明范数携带与方向正交的信息——它是”这个 token 有多重要?“的代理。
实践者可以在任何注意力变体(交叉注意力、自注意力、记忆增强模型)中添加基于范数的门控,作为昂贵操作前的廉价重要性过滤器。