Paper: 2603.25737 Authors: Yuxing Lu, Xukai Zhao, Wei Wu, Jinzhuo Wang Categories: cs.AI, cs.CL, cs.IR
The Gap
RAG systems retrieve documents from a static knowledge base, but the facts needed to answer a query are often scattered across multiple documents and buried in noise. Existing approaches treat the corpus as fixed infrastructure—you build it once, index it, and hope retrieval finds the right needles in the haystack. When retrieval fails, researchers tune the retriever or reranker, but the haystack itself stays messy. The core assumption is that the knowledge base is given, not learned.
Problem: Facts fragmented + buried in noise
   |
   v
Assumption: Corpus is fixed infrastructure
   |
   v
Method: Distill successful retrievals -> compact knowledge units
   |
   v
Evidence: +2.14% avg gain across 4 RAG methods, 6 benchmarks
   |
   v
Conclusion: Corpus itself can be trained offline
The Increment
One sentence: Before this paper, RAG systems retrieved from static corpora and tuned retrieval components; after, the corpus itself becomes a trainable artifact that learns from labeled examples.
Core Mechanism
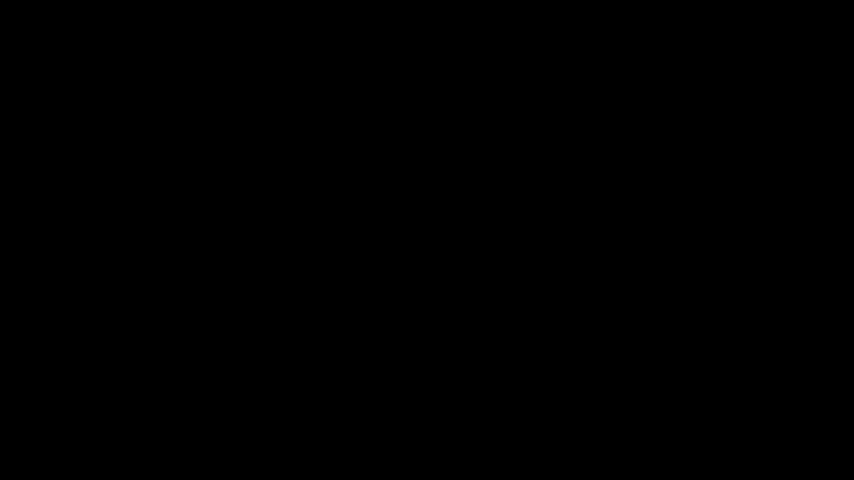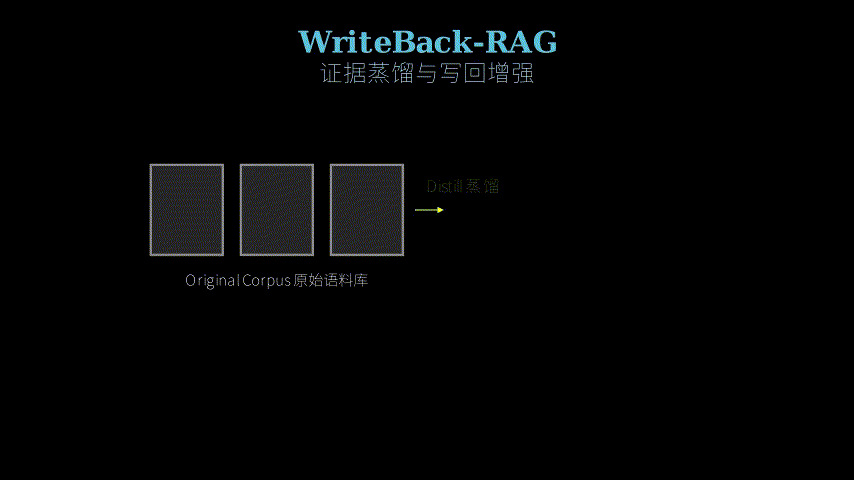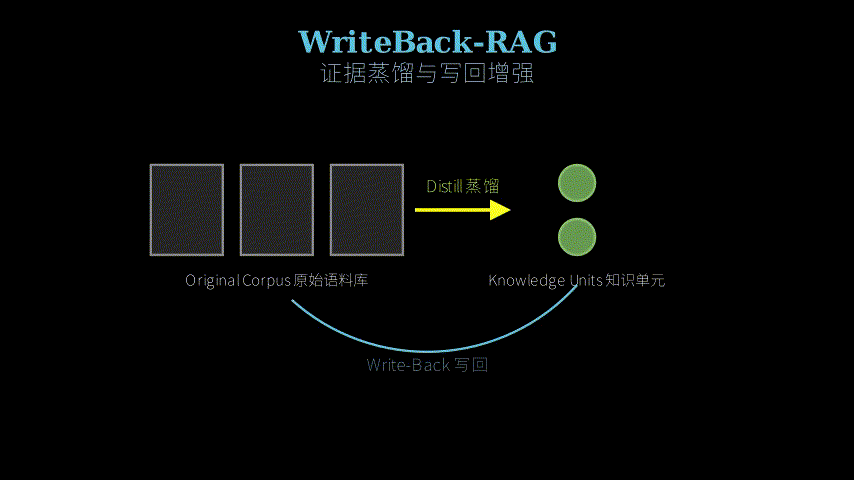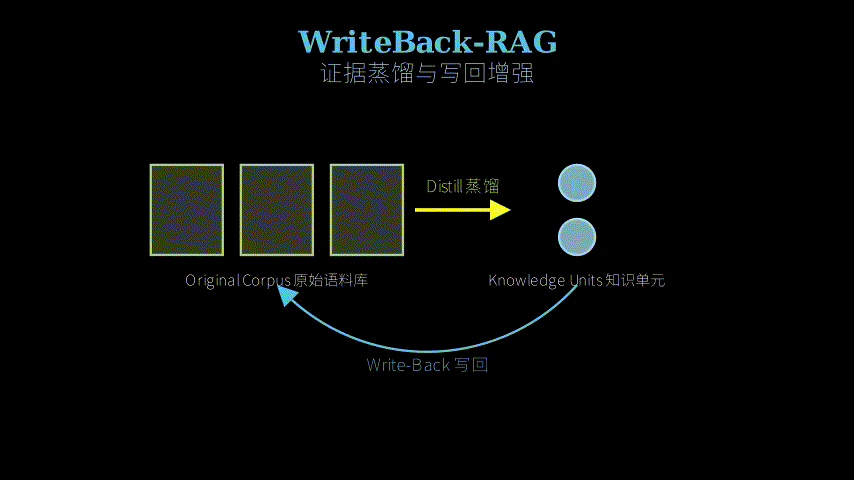
WriteBack-RAG operates in three stages. First, it runs a RAG pipeline on labeled examples and identifies which queries succeeded. Second, it traces back to the retrieved documents that contributed to correct answers and isolates the relevant passages. Third, it distills these passages into compact “knowledge units”—short, self-contained text snippets that preserve the essential facts—and indexes them alongside the original corpus.
The distillation step uses an LLM to compress multi-document evidence into minimal text. For example, if a query about “Einstein’s Nobel Prize year” required retrieving three documents (one about Einstein’s biography, one listing Nobel laureates, one about 1921 physics), the system extracts the relevant sentences from each and fuses them into a single unit: “Einstein won the Nobel Prize in Physics in 1921 for the photoelectric effect.” This unit gets indexed with a new document ID.
Input Corpus          Labeled Examples
     |                      |
     v                      v
  Retrieve  ---------->  Identify
     |                   Successes
     |                      |
     v                      v
Original Docs  ------>  Trace Back
     |                      |
     v                      v
  Extract Relevant  --->  Distill
  Passages               Compact
     |                    Units
     v                      |
Augmented Corpus  <---------+
(Original + Units)
Think of it like a librarian who watches readers struggle to find answers, then creates custom index cards. When a reader successfully pieces together an answer from three different books, the librarian writes a new card summarizing exactly what they needed, files it in the catalog, and future readers find it directly. The original books stay on the shelves, but now there’s also a layer of “cheat sheets” derived from past successful searches. The librarian doesn’t change how readers search—they just make the collection smarter.
Key Concepts
-
Evidence Distillation: The process of compressing multi-document retrieval results into minimal text that preserves factual content. Unlike summarization (which reduces a single document) or fusion (which merges retrieved chunks at query time), distillation happens offline and creates new indexable units. Imagine you’re making flashcards from textbook chapters—you don’t copy paragraphs, you extract the atomic fact (“mitochondria = powerhouse of cell”) and write it on a card. That card becomes a first-class citizen in your study deck.
-
Write-Back: The operation of inserting distilled knowledge units back into the corpus as new documents. This is the key architectural move—instead of caching query-specific results or fine-tuning the retriever, you modify the knowledge base itself. It’s like a database that learns from queries: when a complex join operation succeeds, the database materializes a new view and indexes it. Future queries can hit the view directly instead of repeating the join.
Framework Shift
Before (mainstream approach):        After (this paper):

Query --> Retrieve --> Rerank        Query --> Retrieve --> Rerank
            |             |                      |             |
            v             v                      v             v
      [Static Corpus]   Answer             [Trained Corpus]  Answer
                                                  ^
                                                  |
                                           Distilled Units
                                           (from past success)
From treating the corpus as immutable infrastructure to treating it as a learnable parameter, the core shift is making the knowledge base itself the target of optimization.
Expert Assessment
Problem choice: Real gap. The observation that RAG corpora are assembled once and frozen is accurate, and the fragmentation problem is well-motivated. This sits at the intersection of retrieval and knowledge distillation, which is timely given RAG’s prominence. Not groundbreaking conceptually—the idea of enriching a corpus from usage is old (see query logs in search engines)—but applying it systematically to RAG is fresh.
Method maturity: Straightforward engineering with one clever insight (write-back as offline preprocessing). The distillation step leans on LLM prompting rather than a learned model, which is pragmatic but leaves performance on the table. The cross-method transfer experiments are the strongest evidence that this isn’t just overfitting to one pipeline. However, the paper doesn’t explore failure modes: what happens when distillation introduces errors or when the labeled set is biased?
Experimental integrity: Baselines are fair (four different RAG methods, six benchmarks, two LLM backbones). The +2.14% average gain is modest but consistent. The ablation showing that distilled units help other RAG pipelines is convincing. One red flag: no analysis of corpus size growth or retrieval latency impact. If you’re adding thousands of new documents, does retrieval slow down? Do redundant units pollute results?
Writing quality: The abstract and intro are crisp. The method section is clear but could use a failure case analysis. The related work undersells connections to query-based corpus expansion and knowledge base construction. The conclusion is generic (“future work will explore…”). Rewriting Section 4.3 to include error analysis and computational cost would elevate the paper significantly.
Verdict: weak accept — Solid execution of a practical idea with consistent empirical gains, but lacks depth in understanding when and why the method fails.
Takeaways
Steal the write-back pattern: if you have a system that retrieves from a corpus and you have labeled examples, trace successful retrievals back to their sources, distill the relevant content, and index it. This applies beyond RAG—think code search (distill successful code snippets into reusable templates), legal research (distill case law into precedent summaries), or customer support (distill ticket resolutions into KB articles). The key is that distillation happens offline, so it doesn’t add latency, and the enriched corpus benefits all future queries, not just the ones you trained on.
The cross-method transfer result is the most interesting finding: knowledge distilled using one RAG pipeline improves other pipelines. This suggests the distilled units capture something fundamental about the query-answer relationship, not pipeline-specific quirks. If you’re building a RAG system, consider distillation as a preprocessing step even if you don’t control the downstream retrieval method.
论文: 2603.25737 作者: Yuxing Lu, Xukai Zhao, Wei Wu, Jinzhuo Wang 分类: cs.AI, cs.CL, cs.IR
缺口
RAG系统从静态知识库中检索文档,但回答查询所需的事实往往分散在多个文档中,并被无关内容掩埋。
现有方法将语料库视为固定基础设施——构建一次、索引、然后寄希望于检索能在草堆里找到正确的针。
当检索失败时,研究者调整检索器或重排序器,但草堆本身依然混乱。
核心假设是知识库是给定的,而非学习得到的。
问题:事实碎片化 + 埋藏在噪声中
   |
   v
假设:语料库是固定基础设施
   |
   v
方法:蒸馏成功检索 -> 紧凑知识单元
   |
   v
证据:4种RAG方法、6个基准上平均+2.14%提升
   |
   v
结论:语料库本身可以离线训练
增量
一句话: 这篇论文之前,RAG系统从静态语料库检索并调整检索组件;之后,语料库本身成为可训练的产物,能从标注样本中学习。
核心机制
WriteBack-RAG分三个阶段运行。
首先,它在标注样本上运行RAG流程,识别哪些查询成功了。
其次,它回溯到对正确答案有贡献的检索文档,隔离出相关段落。
第三,它将这些段落蒸馏成紧凑的”知识单元”——保留核心事实的简短自包含文本片段——并将它们与原始语料库一起索引。
蒸馏步骤使用LLM将多文档证据压缩为最小文本。
例如,如果关于”爱因斯坦诺贝尔奖年份”的查询需要检索三个文档(一个关于爱因斯坦传记,一个列出诺贝尔奖得主,一个关于1921年物理学),系统从每个文档中提取相关句子,融合成单个单元:“爱因斯坦因光电效应于1921年获得诺贝尔物理学奖。
“这个单元获得新的文档ID并被索引。
输入语料库          标注样本
     |                |
     v                v
  检索  ---------->  识别
     |              成功案例
     |                |
     v                v
原始文档  ------>  回溯
     |                |
     v                v
  提取相关  --->  蒸馏
  段落            紧凑单元
     |                |
     v                v
增强语料库  <---------+
(原始+单元)
把它想象成一个图书管理员观察读者费力寻找答案,然后创建定制索引卡。
当读者成功从三本不同的书中拼凑出答案时,管理员写一张新卡片,总结他们需要的确切内容,归档到目录中,未来的读者就能直接找到它。
原始书籍仍在书架上,但现在还有一层从过去成功搜索中衍生的”速查表”。
管理员不改变读者的搜索方式——他们只是让馆藏变得更聪明。
关键概念
- 证据蒸馏: 将多文档检索结果压缩为保留事实内容的最小文本的过程。
不同于摘要(缩减单个文档)或融合(在查询时合并检索块),蒸馏离线发生并创建新的可索引单元。
想象你从教科书章节制作闪卡——你不复制段落,而是提取原子事实(“线粒体=细胞的动力工厂”)写在卡片上。
那张卡片成为你学习卡组中的一等公民。
- 写回: 将蒸馏的知识单元作为新文档插入语料库的操作。
这是关键的架构举措——不是缓存特定查询的结果或微调检索器,而是修改知识库本身。
就像一个从查询中学习的数据库:当复杂的连接操作成功时,数据库物化一个新视图并索引它。
未来的查询可以直接命中视图,而不是重复连接。
框架转变
之前(主流方法):                之后(本文方法):

查询 --> 检索 --> 重排          查询 --> 检索 --> 重排
          |         |                    |         |
          v         v                    v         v
    [静态语料库]   答案              [训练语料库]  答案
                                          ^
                                          |
                                    蒸馏单元
                                    (来自过去成功)
从将语料库视为不可变基础设施到将其视为可学习参数,核心转变是让知识库本身成为优化目标。
专家评审
选题眼光: 真实缺口。
RAG语料库一次组装后冻结的观察是准确的,碎片化问题动机充分。
这处于检索和知识蒸馏的交叉点,鉴于RAG的突出地位,时机恰当。
概念上不算突破——从使用中丰富语料库的想法很古老(参见搜索引擎中的查询日志)——但系统地应用于RAG是新鲜的。
方法成熟度: 直接的工程加一个巧妙洞察(写回作为离线预处理)。
蒸馏步骤依赖LLM提示而非学习模型,这很实用但留下了性能空间。
跨方法迁移实验是最有力的证据,表明这不只是对一个流程的过拟合。
然而,论文没有探索失败模式:当蒸馏引入错误或标注集有偏时会发生什么?
实验诚意: 基线公平(四种不同RAG方法、六个基准、两个LLM骨干)。
+2.14%的平均增益虽温和但一致。
消融实验显示蒸馏单元帮助其他RAG流程,这很有说服力。
一个警示:没有分析语料库大小增长或检索延迟影响。
如果添加数千个新文档,检索会变慢吗?冗余单元会污染结果吗?
写作功力: 摘要和引言简洁。
方法部分清晰但可以加入失败案例分析。
相关工作低估了与基于查询的语料库扩展和知识库构建的联系。
结论很泛泛(“未来工作将探索…”)。
重写4.3节加入错误分析和计算成本会显著提升论文。
判决: 弱接收 — 实用想法的扎实执行,有一致的实证增益,但缺乏对方法何时及为何失败的深入理解。
要点总结
偷走写回模式:如果你有一个从语料库检索的系统且有标注样本,将成功检索回溯到源头,蒸馏相关内容并索引它。
这适用于RAG之外——想想代码搜索(将成功的代码片段蒸馏为可复用模板)、法律研究(将判例法蒸馏为先例摘要)或客户支持(将工单解决方案蒸馏为知识库文章)。
关键是蒸馏离线发生,不增加延迟,且增强的语料库惠及所有未来查询,而非仅训练过的查询。
跨方法迁移结果是最有趣的发现:使用一个RAG流程蒸馏的知识改进了其他流程。
这表明蒸馏单元捕获了查询-答案关系的某些基本东西,而非流程特定的怪癖。
如果你在构建RAG系统,即使不控制下游检索方法,也可以考虑将蒸馏作为预处理步骤。