Paper: 2605.22821 Authors: Jan Tempus, Philip Whittington, Craig W. Schmidt, Dennis Komm, Tiago Pimentel Categories: cs.CL, cs.LG
The Gap
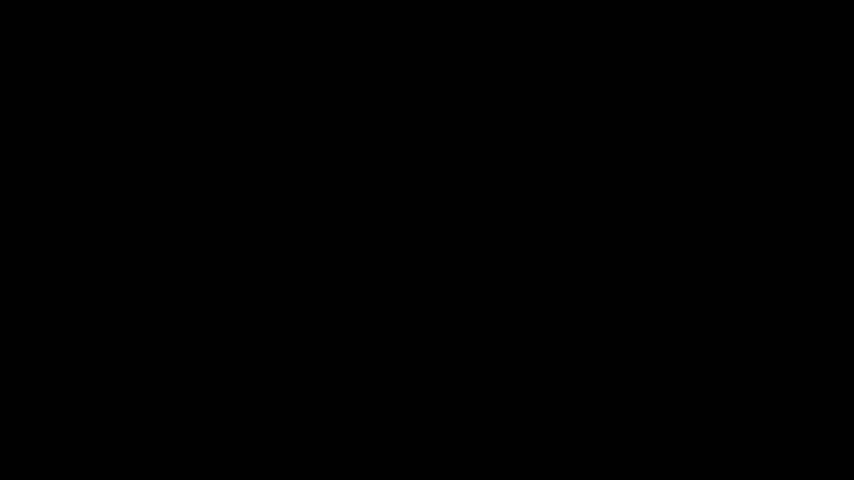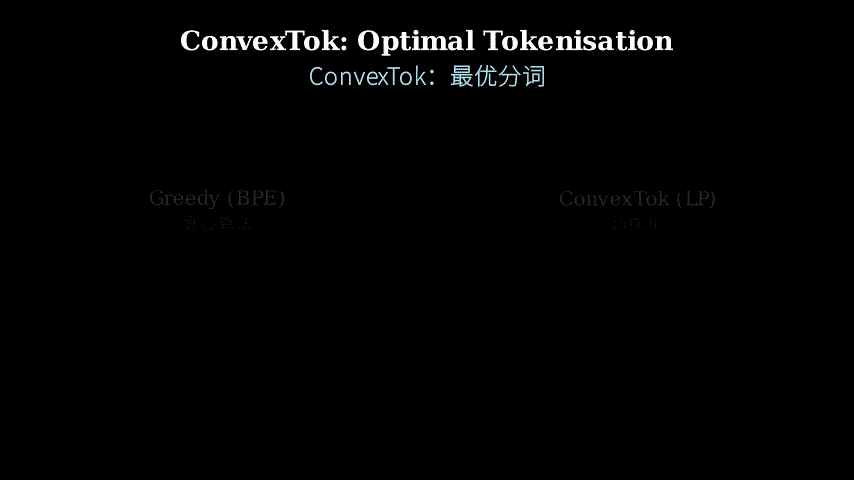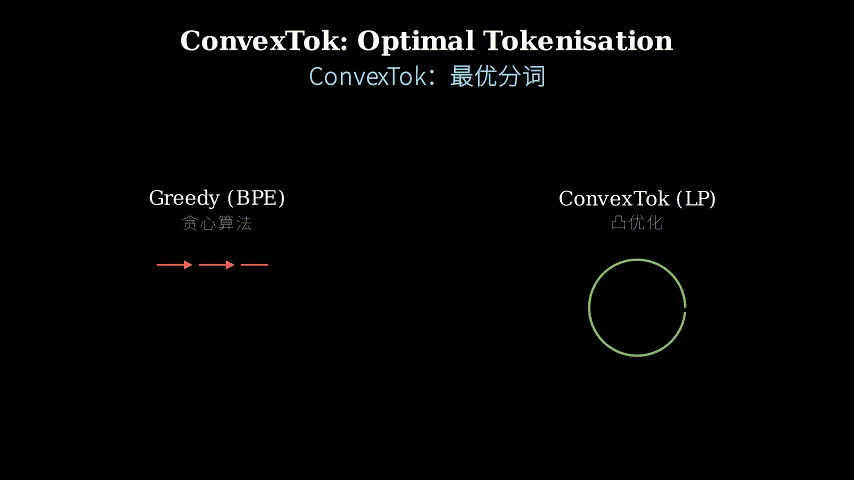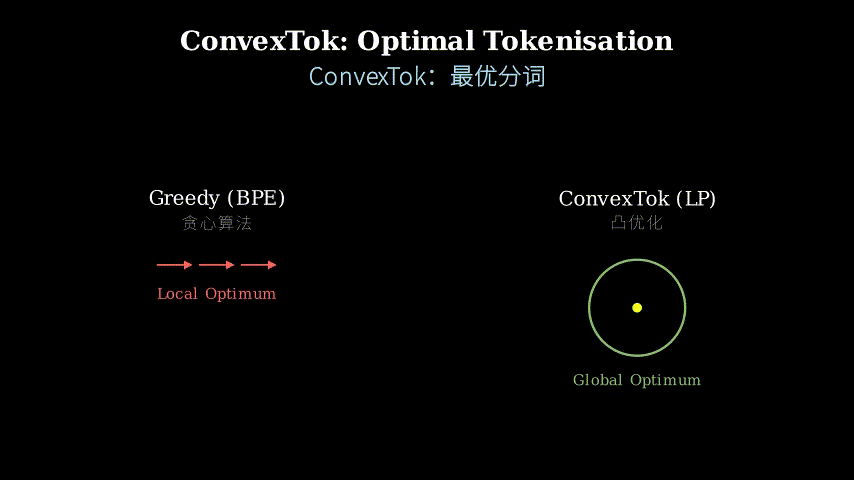
Current tokenization algorithms like BPE (Byte Pair Encoding) and Unigram make greedy, locally optimal decisions. They build vocabularies by iteratively selecting the next best token without considering the global quality of the final vocabulary. This means they can get stuck in local optima—the vocabulary they produce might be good, but there’s no way to know how far it is from the best possible vocabulary for a given objective.
The gap: No existing tokenization method can certify optimality or provide bounds on how suboptimal the result is.
Problem: Greedy tokenizers make local decisions
    |
    v
Assumption: Tokenization can be formulated as global optimization
    |
    v
Method: Linear program with convex relaxation
    |
    v
Evidence: 1% from optimal, better BpB, improved metrics
    |
    v
Conclusion: Global optimization beats greedy heuristics
The Increment
One sentence: Before this paper, tokenizers were greedy algorithms with unknown optimality gaps; after, we have a method that provably gets within 1% of optimal and can certify that distance.
Core Mechanism
ConvexTok formulates tokenizer construction as a linear program. The key insight is treating token selection as a binary decision problem: for each possible token (substring from the training corpus), decide whether to include it in the vocabulary (1) or not (0). The objective function measures vocabulary quality—typically minimizing the total encoding length of the training corpus.
The challenge is that this is a combinatorial optimization problem (NP-hard). ConvexTok solves it by relaxing the binary constraints: instead of forcing each decision to be exactly 0 or 1, it allows fractional values between 0 and 1. This turns the problem into a linear program that can be solved efficiently using convex optimization. After solving the relaxed problem, ConvexTok rounds the fractional solutions back to binary decisions, selecting the top-k tokens by their fractional values to fill the vocabulary.
The relaxation also provides a lower bound on the optimal objective value. By comparing the achieved objective (after rounding) to this lower bound, ConvexTok can certify how close the solution is to optimal—something no greedy algorithm can do.
Training Corpus
    |
    v
[Extract all possible substrings]
    |
    v
[Formulate LP: minimize encoding cost]
    |  Variables: x_i in [0,1] for each token i
    |  Objective: sum of costs weighted by x_i
    |  Constraints: coverage, vocabulary size
    v
[Solve relaxed LP] --> Lower bound (optimal cost)
    |
    v
[Round: select top-k by x_i values]
    |
    v
Final Vocabulary + Optimality Certificate
Think of it like portfolio optimization. A greedy tokenizer is like picking stocks one at a time—you choose the best-looking stock right now, then the next best given what you already have, and so on. You never look at the portfolio as a whole. ConvexTok is like modern portfolio theory: you define what “good” means for the entire portfolio (minimize risk for a given return), formulate it as an optimization problem, and solve for the globally optimal allocation. The relaxation is like allowing fractional shares—you can hold 0.7 shares of a stock in the mathematical solution, then round to whole shares at the end. The gap between the fractional solution and the rounded solution tells you how much you lost by rounding, giving you a certificate of near-optimality.
Key Concepts
-
Convex Relaxation: Imagine you’re trying to pack a suitcase with items that either fit completely or don’t fit at all (binary: in or out). This is hard because you have to try many combinations. Convex relaxation says: “What if items could be partially packed?” You solve this easier problem where an item can be 40% in the suitcase, get an answer, then round back to whole items. The “partial packing” solution gives you a lower bound on the best possible packing—you know the real answer can’t be better than this, because you gave yourself extra flexibility. In tokenization, tokens are either in the vocabulary (1) or out (0). Relaxing to [0,1] makes the problem solvable, and the relaxed solution bounds the optimal binary solution.
-
Optimality Certificate: Most algorithms give you an answer but no guarantee about quality. An optimality certificate is a mathematical proof of how good your solution is. ConvexTok provides two numbers: the cost of its vocabulary (upper bound) and the cost of the relaxed solution (lower bound). If they’re close—say, within 1%—you have a certificate that your vocabulary is within 1% of the best possible. It’s like a GPS telling you not just “you’ll arrive in 30 minutes” but “the absolute fastest possible route is 29.7 minutes, so you’re within 1% of optimal.”
-
Greedy vs. Global Optimization: Greedy algorithms make the best local choice at each step. Climbing a hill, a greedy algorithm always steps upward—it reaches the nearest peak but might miss a higher mountain across the valley. Global optimization looks at the entire landscape and finds the true highest peak. BPE and Unigram are greedy: they merge the most frequent pair or select the token that most reduces cost right now. ConvexTok is global: it considers all tokens simultaneously and selects the set that minimizes total cost, even if some individual tokens wouldn’t be chosen greedily.
Framework Shift
Before (BPE/Unigram):                After (ConvexTok):

Start with characters                Define objective for entire vocab
    |                                     |
    v                                     v
Repeat:                              Formulate as LP over all tokens
  - Find best local merge/add            |
  - Update vocabulary                    v
  - Never reconsider                 Solve relaxed problem
    |                                     |
    v                                     v
Final vocab                          Round to binary + certificate
(unknown quality)                    (provably near-optimal)

Sequential decisions -->             Simultaneous optimization
No optimality guarantee -->          Certified 1% gap
[One sentence: From sequential local decisions to simultaneous global optimization, the core shift is treating tokenization as a solvable mathematical program rather than a greedy heuristic.]
Expert Assessment
Problem choice: Real gap. Tokenization is foundational to NLP, and the lack of optimality guarantees in BPE/Unigram has been a known limitation. This isn’t manufactured—it’s a natural question once you realize greedy algorithms dominate a critical pipeline component. The timing is right: convex optimization tools are mature, and the field is scrutinizing tokenization more carefully as models scale.
Method maturity: Elegant insight, not brute force. The convex relaxation is a standard technique from combinatorial optimization, applied cleverly to a new domain. The rounding strategy is simple (top-k by fractional value), which is both a strength (easy to implement) and a potential weakness (more sophisticated rounding might improve results). The lower bound from the relaxed LP is the key contribution—it’s what enables the optimality certificate.
Experimental integrity: Baselines are fair (BPE, Unigram, standard benchmarks). The improvements are modest but consistent: better intrinsic metrics (compression, fertility) and BpB, less consistent on downstream tasks. The 1% optimality gap is impressive and well-documented. One concern: the LP formulation requires defining an objective upfront, and the paper focuses on encoding length. If the true goal is downstream task performance, the mismatch might explain why downstream gains are inconsistent. The paper is honest about this.
Writing quality: Clear and well-structured. The LP formulation is explained carefully. The experimental section could be stronger—more ablations on different objectives, vocabulary sizes, and languages would solidify the claims. The discussion of why downstream improvements are inconsistent feels underdeveloped; this deserves a deeper investigation or at least more speculation.
Verdict: weak accept — Solid contribution with practical value and theoretical rigor, but the downstream task results are mixed and the method’s sensitivity to objective choice needs more exploration.
Takeaways
Steal the certificate idea: Even if you don’t use ConvexTok, the concept of providing optimality certificates for heuristic algorithms is broadly applicable. Any time you’re using a greedy or approximate algorithm, ask: can I formulate a relaxed version that gives a lower bound? This applies to neural architecture search, hyperparameter tuning, data subset selection, etc.
Rethink greedy pipelines: Tokenization isn’t the only NLP component built on greedy heuristics. Beam search, pruning strategies, and incremental training all make local decisions. This paper shows that reformulating as global optimization can be tractable and worthwhile. Look for similar opportunities in your pipeline.
Objective mismatch matters: ConvexTok optimizes for encoding length but is evaluated on downstream tasks. The inconsistent downstream gains suggest the objective doesn’t fully capture what makes a tokenizer good for language modeling. This is a reminder: when you optimize a proxy metric, measure the gap between proxy and true goal. If they diverge, either improve the proxy or accept the limitation.
论文: 2605.22821 作者: Jan Tempus, Philip Whittington, Craig W. Schmidt, Dennis Komm, Tiago Pimentel 分类: cs.CL, cs.LG
缺口
当前的分词算法如 BPE(字节对编码)和 Unigram 采用贪心策略,做出局部最优决策。
它们通过迭代选择下一个最佳 token 来构建词表,而不考虑最终词表的全局质量。
这意味着它们可能陷入局部最优——生成的词表可能不错,但无法知道它距离给定目标下的最佳词表有多远。
缺口在于:现有分词方法无法证明最优性,也无法提供次优程度的界限。
问题:贪心分词器做局部决策
    |
    v
假设:分词可以建模为全局优化
    |
    v
方法:带凸松弛的线性规划
    |
    v
证据:距最优1%,更好的BpB,改进的指标
    |
    v
结论:全局优化胜过贪心启发式
增量
一句话:这篇论文之前,分词器是最优性未知的贪心算法;
之后,我们有了一种可证明达到最优解1%以内并能证明该距离的方法。
核心机制
ConvexTok 将分词器构建建模为线性规划。
核心洞察是将 token 选择视为二元决策问题:对训练语料中的每个可能 token(子串),决定是否将其纳入词表(1或0)。
目标函数衡量词表质量——通常是最小化训练语料的总编码长度。
挑战在于这是一个组合优化问题(NP-hard)。
ConvexTok 通过松弛二元约束来解决:不强制每个决策恰好为0或1,而是允许0到1之间的分数值。
这将问题转化为可用凸优化高效求解的线性规划。
求解松弛问题后,ConvexTok 将分数解四舍五入回二元决策,按分数值选择前 k 个 token 填充词表。
松弛还提供了最优目标值的下界。
通过比较实现的目标(四舍五入后)与该下界,ConvexTok 可以证明解距最优有多近——这是贪心算法做不到的。
训练语料
    |
    v
[提取所有可能的子串]
    |
    v
[建立LP:最小化编码成本]
    |  变量:每个token i 的 x_i 属于 [0,1]
    |  目标:按 x_i 加权的成本总和
    |  约束:覆盖率、词表大小
    v
[求解松弛LP] --> 下界(最优成本)
    |
    v
[四舍五入:按 x_i 值选前k个]
    |
    v
最终词表 + 最优性证书
可以把它想象成投资组合优化。
贪心分词器就像逐个挑选股票——你现在选看起来最好的股票,然后在已有基础上选下一个最好的,如此往复。
你从不审视整个投资组合。
ConvexTok 就像现代投资组合理论:你定义整个投资组合的”好”是什么(在给定收益下最小化风险),将其建模为优化问题,求解全局最优配置。
松弛就像允许持有零碎股份——在数学解中你可以持有0.7股,然后在最后四舍五入为整数股。
分数解与四舍五入解之间的差距告诉你因四舍五入损失了多少,给你一个接近最优的证书。
关键概念
- 凸松弛:想象你要往行李箱里装东西,物品要么完全装进去,要么装不进(二元:进或出)。
这很难,因为你得尝试很多组合。
凸松弛说:“如果物品可以部分装进去呢?“你求解这个更简单的问题,物品可以40%在行李箱里,得到答案,然后四舍五入回整数物品。
“部分装箱”解给你最佳装箱的下界——你知道真实答案不可能比这更好,因为你给了自己额外的灵活性。
在分词中,token 要么在词表里(1)要么不在(0)。
松弛到 [0,1] 使问题可解,松弛解界定了最优二元解。
- 最优性证书:大多数算法给你一个答案但不保证质量。
最优性证书是关于你的解有多好的数学证明。
ConvexTok 提供两个数字:其词表的成本(上界)和松弛解的成本(下界)。
如果它们接近——比如在1%以内——你就有了一个证书,证明你的词表在最佳可能的1%以内。
这就像GPS不仅告诉你”你将在30分钟后到达”,还告诉你”绝对最快的路线是29.7分钟,所以你在最优的1%以内。”
- 贪心 vs. 全局优化:贪心算法在每一步做出最佳局部选择。
爬山时,贪心算法总是向上走——它到达最近的山峰,但可能错过山谷对面更高的山。
全局优化审视整个地形,找到真正的最高峰。
BPE 和 Unigram 是贪心的:它们合并最频繁的对,或选择当前最能降低成本的 token。
ConvexTok 是全局的:它同时考虑所有 token,选择使总成本最小的集合,即使某些单个 token 不会被贪心选中。
框架转变
之前(BPE/Unigram):              之后(ConvexTok):

从字符开始                        为整个词表定义目标
    |                                 |
    v                                 v
重复:                            对所有token建立LP
  - 找最佳局部合并/添加                |
  - 更新词表                          v
  - 从不重新考虑                  求解松弛问题
    |                                 |
    v                                 v
最终词表                          四舍五入为二元 + 证书
(质量未知)                      (可证明接近最优)

顺序决策 -->                      同时优化
无最优性保证 -->                  证明1%差距
[一句话:从顺序局部决策到同时全局优化,核心转变是将分词视为可解的数学规划而非贪心启发式。]
专家评审
选题眼光:真实缺口。
分词是 NLP 的基础,BPE/Unigram 缺乏最优性保证是已知局限。
这不是人造的——一旦你意识到贪心算法主导着关键管道组件,这是个自然的问题。
时机恰当:凸优化工具已成熟,随着模型规模扩大,该领域正在更仔细地审视分词。
方法成熟度:优雅的洞察,非蛮力。
凸松弛是组合优化的标准技术,巧妙地应用到新领域。
四舍五入策略简单(按分数值取前k个),这既是优势(易实现)也是潜在弱点(更复杂的四舍五入可能改进结果)。
松弛LP的下界是关键贡献——它使最优性证书成为可能。
实验诚意:基线公平(BPE、Unigram、标准基准)。
改进适度但一致:更好的内在指标(压缩率、fertility)和 BpB,下游任务上不太一致。
1%最优性差距令人印象深刻且有充分记录。
一个担忧:LP 建模需要预先定义目标,论文聚焦于编码长度。
如果真正目标是下游任务性能,这种不匹配可能解释了为何下游收益不一致。
论文对此是诚实的。
写作功力:清晰且结构良好。
LP 建模解释得很仔细。
实验部分可以更强——对不同目标、词表大小和语言的更多消融实验会巩固主张。
关于为何下游改进不一致的讨论感觉不够深入;
这值得更深入的调查或至少更多推测。
判决:弱接收 — 具有实用价值和理论严谨性的扎实贡献,但下游任务结果参差不齐,方法对目标选择的敏感性需要更多探索。
要点总结
偷走证书思想:即使你不用 ConvexTok,为启发式算法提供最优性证书的概念也广泛适用。
任何时候你使用贪心或近似算法,问问:我能建立一个给出下界的松弛版本吗?这适用于神经架构搜索、超参数调优、数据子集选择等。
重新思考贪心管道:分词不是唯一建立在贪心启发式上的 NLP 组件。
束搜索、剪枝策略和增量训练都做局部决策。
本文表明,重新建模为全局优化可以是可行且值得的。
在你的管道中寻找类似机会。
目标不匹配很重要:ConvexTok 优化编码长度但在下游任务上评估。
不一致的下游收益表明目标没有完全捕捉到什么使分词器对语言建模有益。
这是个提醒:当你优化代理指标时,衡量代理与真实目标之间的差距。
如果它们分歧,要么改进代理,要么接受局限。