Paper: 2605.30344 Authors: Xiaona Zhou, Muntasir Wahed, Tianjiao Yu, Constantin Brif, Ismini Lourentzou Categories: cs.AI
The Gap
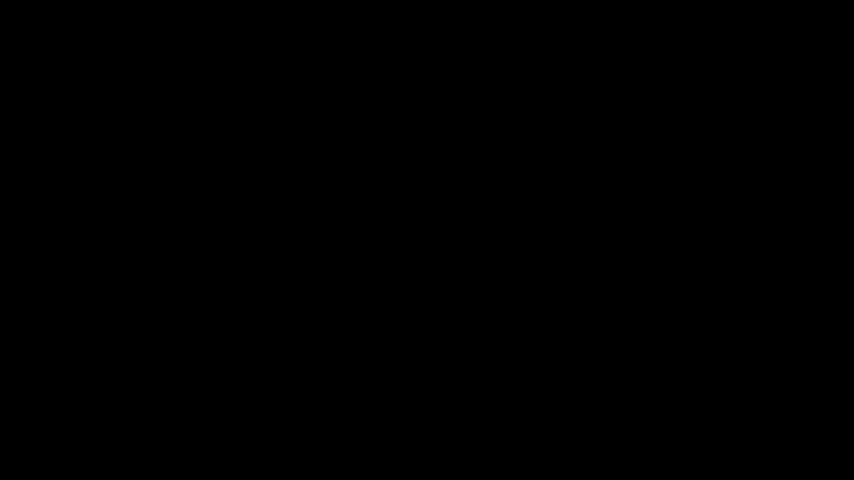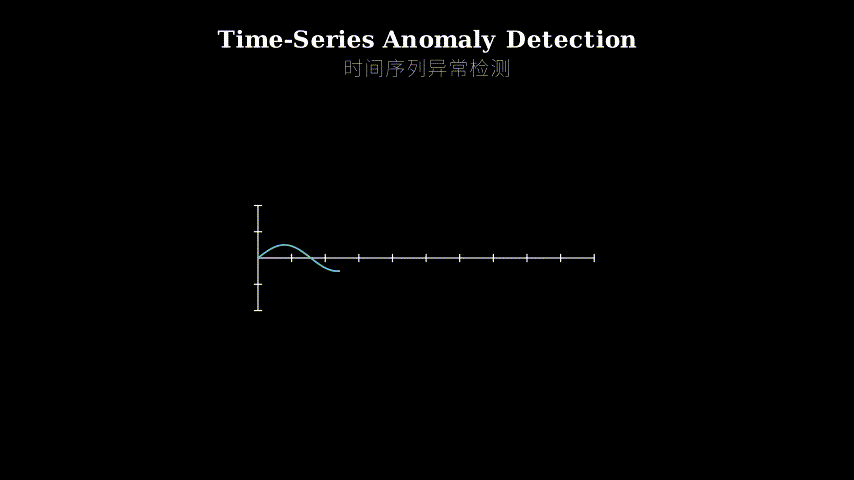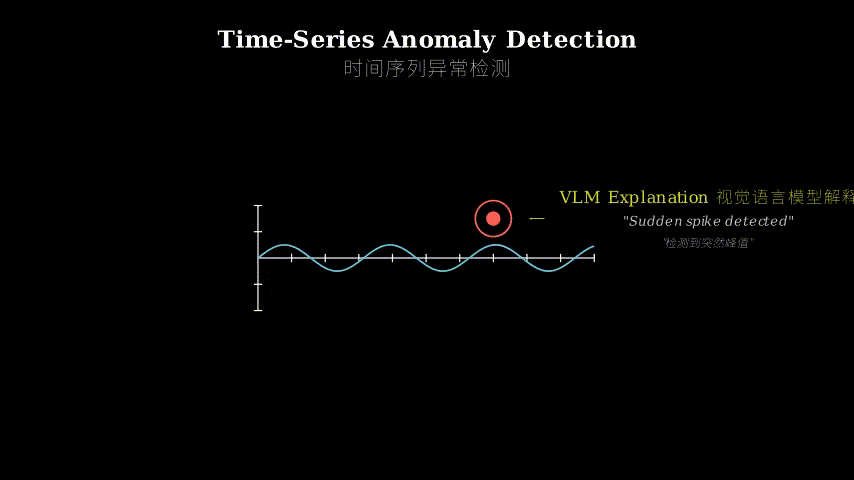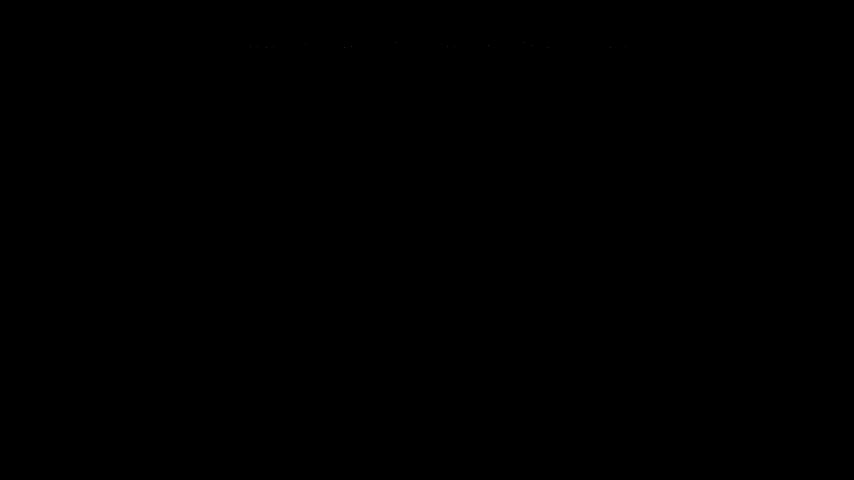
Large vision-language models (VLMs) excel at image captioning and visual question answering, but stumble when asked to find anomalies in time-series plots. Prior work tried applying GPT-4V and other large multimodal models to anomaly detection, but performance was disappointing. The core problem: existing anomaly detection benchmarks only provide interval labels (“anomaly from timestamp 100 to 150”) without explaining why those intervals are anomalous. You can’t fine-tune a VLM to produce grounded explanations when your training data has no explanations.
Meanwhile, smaller VLMs (7B parameters or less) remain unexplored for this task. The field assumed you needed massive models, but no one tested whether a compact, specialized model could outperform general-purpose giants.
Problem: Time-series anomaly detection lacks explainability
   |
   v
Observation: Existing benchmarks have interval labels but no rationales
   |
   v
Assumption: Small VLMs can learn to explain if given quality rationales
   |
   v
Method: Build VisAnomBench (data + rationales), fine-tune small VLM
   |
   v
Evidence: 21+ point precision gain, 23+ point F1 gain vs baselines
   |
   v
Conclusion: Parameter-efficient VLMs + curated rationales > large general models
The Increment
One sentence: Before this paper, applying VLMs to time-series anomaly detection meant throwing GPT-4V at raw plots and getting mediocre results; after, we have a 7B-parameter specialist that detects anomalies more accurately *and explains them in natural language.
Core Mechanism
VisAnomReasoner is a fine-tuned vision-language model built on Qwen2-VL-7B. The input is a time-series plot rendered as an image. The output is both anomaly localization (which time intervals are abnormal) and a natural language explanation (why those intervals are anomalous).
Training happens in two stages. First, the authors construct VisAnomBench by taking public time-series datasets with interval annotations, rendering them as plots, then generating candidate explanations using multiple large VLMs (GPT-4V, Gemini, Claude). They don’t just pick one explanation—they use a reward model with task-specific metrics (does the explanation mention the correct interval? does it describe the visual pattern? is it factually grounded?) to select the highest-quality rationale for each anomaly. This creates a dataset where every anomaly has both a precise interval label and a human-readable explanation.
Second, they fine-tune Qwen2-VL-7B on VisAnomBench using parameter-efficient methods (LoRA adapters). The model learns to map visual patterns in time-series plots to both structured outputs (anomaly intervals) and unstructured outputs (explanations). At inference, given a new time-series plot, the model predicts anomaly intervals and generates a rationale.
Input: Time-series plot (image)
   |
   v
[Qwen2-VL-7B backbone]
   |
   +---> [LoRA adapters] (fine-tuned on VisAnomBench)
   |
   v
Output: Anomaly intervals + Natural language explanation

Training data flow:
Public datasets --> Render as plots --> Generate candidate explanations (GPT-4V, Gemini, Claude)
                                              |
                                              v
                                    Reward model selects best explanation
                                              |
                                              v
                                    VisAnomBench (plots + intervals + rationales)
Think of this like training a medical resident. A hospital has X-rays with diagnoses (“fracture at L3 vertebra”) but no teaching notes explaining why that shadow indicates a fracture. You can’t train residents effectively with labels alone. So you bring in senior radiologists (the large VLMs) to write teaching notes for each case, then use a grading rubric (the reward model) to keep only the clearest explanations. Now you have a teaching file. You give this to a junior resident (the 7B model) who studies it intensively. The resident becomes specialized—not as broadly knowledgeable as the senior radiologists, but faster and more reliable at this specific task because they’ve internalized the reasoning patterns.
The key insight: you don’t need a 100B-parameter generalist if you can distill expert reasoning into a curated dataset and train a specialist. The specialist learns the task-specific visual patterns (sudden spikes, gradual drifts, periodic disruptions) and the language patterns for describing them.
Key Concepts
-
Vision-Language Model (VLM): A neural network that processes both images and text. Unlike a pure vision model (which outputs class labels or bounding boxes) or a pure language model (which outputs text), a VLM can take an image as input and generate natural language descriptions, or take text questions about an image and answer them. The “vision” part encodes the image into numerical representations; the “language” part decodes those representations into words. For time-series anomaly detection, the VLM sees a plot (vision) and outputs both structured predictions (which intervals are anomalous) and explanations (language). The advantage: humans can audit the model’s reasoning, not just its predictions.
-
Reward model for rationale selection: When you ask multiple large VLMs to explain an anomaly, you get multiple candidate explanations—some accurate, some vague, some hallucinated. A reward model is a scoring function that evaluates each candidate on task-specific criteria. For this paper, the reward model checks: (1) Does the explanation mention the correct time interval? (2) Does it describe the visual pattern (spike, drop, oscillation)? (3) Is it factually grounded in the data? The highest-scoring explanation becomes the training label. This is like having multiple tutors explain a concept, then using a rubric to pick the clearest explanation for the textbook. Without this filtering step, the training data would be noisy and the fine-tuned model would learn to mimic both good and bad reasoning.
-
Parameter-efficient fine-tuning (LoRA): Fine-tuning a 7B-parameter model normally means updating all 7 billion weights, which requires massive compute and memory. LoRA (Low-Rank Adaptation) freezes the original model weights and adds small “adapter” matrices that learn the task-specific adjustments. Instead of updating 7B parameters, you update maybe 50M. It’s like teaching someone a new skill by giving them a cheat sheet rather than rewriting their entire brain. The base model retains its general knowledge (language understanding, visual reasoning), and the adapters specialize it for anomaly detection. This makes training feasible on academic-scale compute.
Framework Shift
Before (mainstream approach):        After (this paper):

Time-series data                     Time-series data
   |                                    |
   v                                    v
Statistical methods                  Render as plot (image)
(ARIMA, isolation forest)               |
   |                                    v
   v                                 Small VLM (7B params)
Anomaly intervals                    + LoRA adapters
(no explanation)                     + Curated rationales
                                        |
                                        v
                                     Anomaly intervals
                                     + Natural language explanation
                                     ("Sudden spike at t=120
                                      exceeds 3x normal range")

Key difference:                      Key difference:
- Treats time-series as numbers     - Treats time-series as visual pattern
- Black-box predictions             - Interpretable reasoning
- Large models underperform         - Small specialist outperforms
One sentence: From statistical black boxes operating on raw numbers to a visual reasoning specialist that sees patterns in plots and explains them in plain language.
Expert Assessment
Problem choice: Real gap. Anomaly detection is a mature field, but explainability remains a pain point—especially in high-stakes domains (healthcare, finance) where “the model said so” isn’t enough. The observation that large VLMs underperform here is surprising and worth investigating. The problem sits at the intersection of time-series analysis and interpretable AI, both active areas.
Method maturity: Clever insight, not brute force. The core contribution isn’t a novel architecture—it’s recognizing that (1) rendering time-series as images lets you leverage VLM capabilities, and (2) curating high-quality rationales via reward-based selection is more effective than naively prompting large models. The LoRA fine-tuning is standard practice. The reward model design is task-specific but straightforward. The real innovation is the data construction pipeline. One concern: the method assumes anomalies are visually salient in plots, which may not hold for subtle statistical anomalies.
Experimental integrity: Baselines are fair—they compare against both traditional methods (isolation forest, LSTM autoencoders) and large VLMs (GPT-4V, Gemini). The improvements are substantial (21+ points in precision, 23+ in F1), which suggests the method isn’t just tuning hyperparameters. Cross-benchmark evaluation on TSB-AD-U shows generalization. However, the paper doesn’t report compute costs or inference latency, which matters for practical deployment. Also, the reward model for rationale selection is itself a design choice—different reward functions might yield different results, but no ablation is provided.
Writing quality: The abstract and introduction are clear. The method section could be tighter—the reward model design is buried in supplementary material, but it’s central to understanding why the approach works. The related work section lists prior VLM applications but doesn’t deeply engage with why they failed (was it model size? training data? task formulation?). The results section is thorough but could benefit from error analysis: what types of anomalies does the model still miss?
Verdict: Weak accept — Solid execution on a real problem with meaningful improvements, but the contribution is more engineering (data curation + fine-tuning) than conceptual breakthrough. The lack of compute cost analysis and reward model ablation weakens the experimental story.
Takeaways
For practitioners: If you’re building anomaly detection systems and need explainability, consider rendering your time-series as plots and fine-tuning a small VLM rather than engineering features for traditional models. The key isn’t the model size—it’s the quality of the training rationales. If you can’t afford manual annotation, use the reward-based selection trick: generate multiple explanations from large models, score them on task-specific criteria, keep the best.
For researchers: The reward model for rationale selection is underexplored. Most work on learning from AI feedback focuses on general helpfulness or harmlessness. This paper shows that task-specific reward functions (checking interval accuracy, visual grounding) can filter noisy synthetic data into high-quality training signals. This pattern likely transfers to other domains where you need structured outputs + explanations (medical diagnosis, financial forecasting, scientific data analysis).
Transferable technique: The two-stage pipeline (generate diverse candidates with large models → filter with task-specific rewards → train specialist) is a general recipe for building interpretable systems when you have labels but no rationales. It’s cheaper than human annotation and more reliable than naively prompting large models at inference time.
论文: 2605.30344 作者: Xiaona Zhou, Muntasir Wahed, Tianjiao Yu, Constantin Brif, Ismini Lourentzou 分类: cs.AI
缺口
大型视觉语言模型(VLM)在图像描述和视觉问答上表现出色,但在时序图表中寻找异常时却表现不佳。
此前的工作尝试将 GPT-4V 等大型多模态模型应用于异常检测,但效果令人失望。
核心问题在于:现有的异常检测基准只提供区间标签(“时间戳 100 到 150 之间有异常”),却不解释为什么这些区间是异常的。
当训练数据没有解释时,你无法微调 VLM 来生成有根据的解释。
与此同时,更小的 VLM(70 亿参数或更少)在这个任务上仍未被探索。
该领域假设需要大规模模型,但没人测试过紧凑的专用模型是否能超越通用巨型模型。
问题:时序异常检测缺乏可解释性
   |
   v
观察:现有基准有区间标签但无理由说明
   |
   v
假设:小型 VLM 如果获得高质量理由可以学会解释
   |
   v
方法:构建 VisAnomBench(数据+理由),微调小型 VLM
   |
   v
证据:精确率提升 21+ 个百分点,F1 提升 23+ 个百分点
   |
   v
结论:参数高效的 VLM + 精选理由 > 大型通用模型
增量
一句话:这篇论文之前,将 VLM 应用于时序异常检测意味着把 GPT-4V 扔给原始图表然后得到平庸结果;
之后,我们有了一个 70 亿参数的专家模型,能更准确地检测异常并且用自然语言解释它们。
核心机制
VisAnomReasoner 是基于 Qwen2-VL-7B 微调的视觉语言模型。
输入是渲染为图像的时序图表。
输出既包括异常定位(哪些时间区间是异常的),也包括自然语言解释(为什么这些区间是异常的)。
训练分两个阶段。
首先,作者构建 VisAnomBench:从公开时序数据集获取区间标注,将其渲染为图表,然后使用多个大型 VLM(GPT-4V、Gemini、Claude)生成候选解释。
他们不是简单选一个解释——而是使用带有任务特定指标的奖励模型(解释是否提到了正确区间?
是否描述了视觉模式?
是否基于事实?
)来为每个异常选择最高质量的理由。
这创建了一个数据集,其中每个异常都有精确的区间标签和人类可读的解释。
其次,他们使用参数高效方法(LoRA 适配器)在 VisAnomBench 上微调 Qwen2-VL-7B。
模型学习将时序图表中的视觉模式映射到结构化输出(异常区间)和非结构化输出(解释)。
在推理时,给定新的时序图表,模型预测异常区间并生成理由。
输入:时序图表(图像)
   |
   v
[Qwen2-VL-7B 主干]
   |
   +---> [LoRA 适配器](在 VisAnomBench 上微调)
   |
   v
输出:异常区间 + 自然语言解释

训练数据流:
公开数据集 --> 渲染为图表 --> 生成候选解释(GPT-4V、Gemini、Claude)
                                    |
                                    v
                          奖励模型选择最佳解释
                                    |
                                    v
                          VisAnomBench(图表+区间+理由)
把这想象成培训住院医生。
医院有 X 光片和诊断(“L3 椎骨骨折”),但没有教学笔记解释为什么那个阴影表示骨折。
仅凭标签无法有效培训住院医生。
所以你请来资深放射科医生(大型 VLM)为每个病例写教学笔记,然后用评分标准(奖励模型)只保留最清晰的解释。
现在你有了教学档案。
你把这个给初级住院医生(70 亿参数模型),让他们深入学习。
住院医生变得专业化——虽然不像资深放射科医生那样知识广博,但在这个特定任务上更快更可靠,因为他们内化了推理模式。
关键洞察:如果你能将专家推理提炼到精选数据集中并训练专家模型,就不需要 1000 亿参数的通才。
专家模型学习任务特定的视觉模式(突然尖峰、渐进漂移、周期性中断)以及描述它们的语言模式。
关键概念
- 视觉语言模型(VLM):一种同时处理图像和文本的神经网络。
与纯视觉模型(输出类别标签或边界框)或纯语言模型(输出文本)不同,VLM 可以接收图像作为输入并生成自然语言描述,或接收关于图像的文本问题并回答它们。
“视觉”部分将图像编码为数值表示;
“语言”部分将这些表示解码为文字。
对于时序异常检测,VLM 看到图表(视觉)并输出结构化预测(哪些区间是异常的)和解释(语言)。
优势:人类可以审计模型的推理,而不仅仅是预测。
- 理由选择的奖励模型:当你让多个大型 VLM 解释一个异常时,你会得到多个候选解释——有些准确,有些模糊,有些是幻觉。
奖励模型是一个评分函数,根据任务特定标准评估每个候选。
对于本文,奖励模型检查:(1)解释是否提到了正确的时间区间?
(2)是否描述了视觉模式(尖峰、下降、振荡)?
(3)是否基于数据事实?
得分最高的解释成为训练标签。
这就像让多个导师解释一个概念,然后用评分标准为教科书挑选最清晰的解释。
没有这个过滤步骤,训练数据会很嘈杂,微调后的模型会学习模仿好的和坏的推理。
- 参数高效微调(LoRA):微调一个 70 亿参数的模型通常意味着更新所有 70 亿个权重,这需要大量计算和内存。
LoRA(低秩适应)冻结原始模型权重,并添加小型”适配器”矩阵来学习任务特定的调整。
你不是更新 70 亿参数,而是更新大约 5000 万。
这就像通过给某人一张备忘单来教他们新技能,而不是重写他们的整个大脑。
基础模型保留其通用知识(语言理解、视觉推理),适配器将其专业化用于异常检测。
这使得在学术规模的计算资源上训练变得可行。
框架转变
之前(主流方法):                之后(本文方法):

时序数据                          时序数据
   |                                 |
   v                                 v
统计方法                          渲染为图表(图像)
(ARIMA, 孤立森林)                    |
   |                                 v
   v                              小型 VLM(70 亿参数)
异常区间                          + LoRA 适配器
(无解释)                        + 精选理由
                                     |
                                     v
                                  异常区间
                                  + 自然语言解释
                                  ("t=120 处突然尖峰
                                   超过正常范围 3 倍")

关键差异:                        关键差异:
- 将时序视为数字                  - 将时序视为视觉模式
- 黑盒预测                        - 可解释推理
- 大型模型表现不佳                - 小型专家模型表现更好
一句话:从对原始数字操作的统计黑盒,到能在图表中看到模式并用通俗语言解释的视觉推理专家。
专家评审
选题眼光:真实缺口。
异常检测是一个成熟领域,但可解释性仍然是痛点——尤其在高风险领域(医疗、金融),“模型这么说”是不够的。
观察到大型 VLM 在这里表现不佳令人惊讶,值得研究。
问题位于时序分析和可解释 AI 的交叉点,两者都是活跃领域。
方法成熟度:巧劲,非蛮力。
核心贡献不是新颖架构——而是认识到(1)将时序渲染为图像可以利用 VLM 能力,(2)通过基于奖励的选择精选高质量理由比天真地提示大型模型更有效。
LoRA 微调是标准做法。
奖励模型设计是任务特定的但很直接。
真正的创新是数据构建流程。
一个担忧:该方法假设异常在图表中视觉上显著,这对于微妙的统计异常可能不成立。
实验诚意:基线公平——他们与传统方法(孤立森林、LSTM 自编码器)和大型 VLM(GPT-4V、Gemini)进行了比较。
改进幅度很大(精确率 21+ 个百分点,F1 23+ 个百分点),这表明该方法不仅仅是调整超参数。
在 TSB-AD-U 上的跨基准评估显示了泛化能力。
然而,论文没有报告计算成本或推理延迟,这对实际部署很重要。
此外,用于理由选择的奖励模型本身是一个设计选择——不同的奖励函数可能产生不同结果,但没有提供消融实验。
写作功力:摘要和引言清晰。
方法部分可以更紧凑——奖励模型设计埋在补充材料中,但它对理解方法为何有效至关重要。
相关工作部分列出了先前的 VLM 应用,但没有深入探讨它们为何失败(是模型大小?
训练数据?
任务表述?
)。
结果部分很全面,但可以从错误分析中受益:模型仍然遗漏了哪些类型的异常?
判决:弱接收 — 在真实问题上扎实执行并有显著改进,但贡献更多是工程(数据精选+微调)而非概念突破。
缺乏计算成本分析和奖励模型消融削弱了实验故事。
要点总结
对实践者:如果你正在构建需要可解释性的异常检测系统,考虑将时序渲染为图表并微调小型 VLM,而不是为传统模型设计特征。
关键不是模型大小——而是训练理由的质量。
如果负担不起人工标注,使用基于奖励的选择技巧:从大型模型生成多个解释,根据任务特定标准评分,保留最好的。
对研究者:用于理由选择的奖励模型尚未充分探索。
大多数关于从 AI 反馈中学习的工作关注一般有用性或无害性。
本文表明,任务特定的奖励函数(检查区间准确性、视觉基础)可以将嘈杂的合成数据过滤为高质量的训练信号。
这种模式可能迁移到其他需要结构化输出+解释的领域(医学诊断、金融预测、科学数据分析)。
可迁移技术:两阶段流程(用大型模型生成多样候选 → 用任务特定奖励过滤 → 训练专家模型)是在有标签但无理由时构建可解释系统的通用配方。
它比人工标注更便宜,比在推理时天真地提示大型模型更可靠。