Paper: 2606.20561
Authors: Arkaprava Sinha, Dominick Reilly, Siddharth Krishnan, Hieu Le, Srijan Das
Categories: cs.CV
The Gap
Existing long video QA either runs a massive VLM over every frame (ViLMA, Flamingo) – expensive and wasteful – or relies on sparse captions (EgoVLP, VLM-Caption) that miss motion-heavy actions and precise temporal boundaries. Neither approach handles the core tension: you need dense temporal grounding to catch the few relevant seconds in hours of footage, but you can’t afford to process everything with a heavy model.
Problem: Long videos, sparse query-relevant evidence
           |
           v
Assumption: Lightweight proposal can localize candidate clips, then heavy VLM only verifies
           |
           v
Method: ACE (Action Candidate Evidence) module + VLM verification
           |
           v
Evidence: OTB benchmark shows +7.3% accuracy, 75% fewer VLM calls, 93% cost reduction
           |
           v
Conclusion: Two-stage propose-verify is viable for efficient ADL temporal reasoning
The Increment
One sentence: Before, you either burned GPU hours scanning every frame or lost critical action evidence by skimming captions; now, a lightweight action-driven proposer picks promising clips, and only those get the heavy VLM treatment.
Core Mechanism
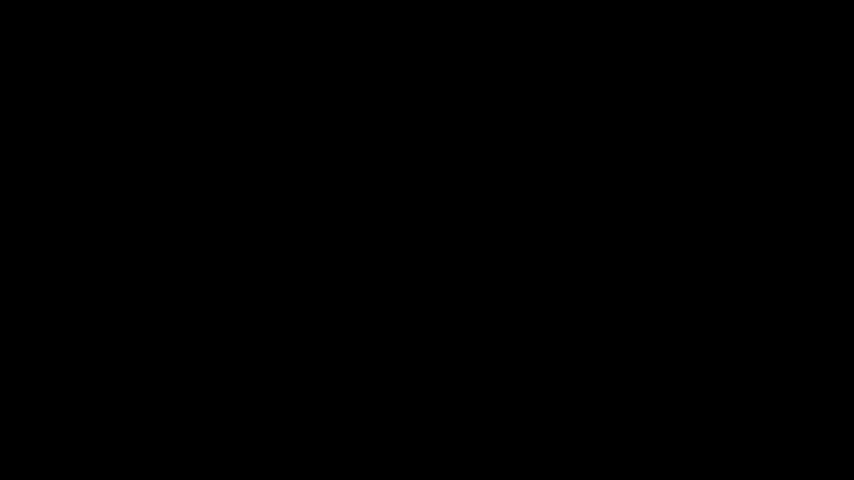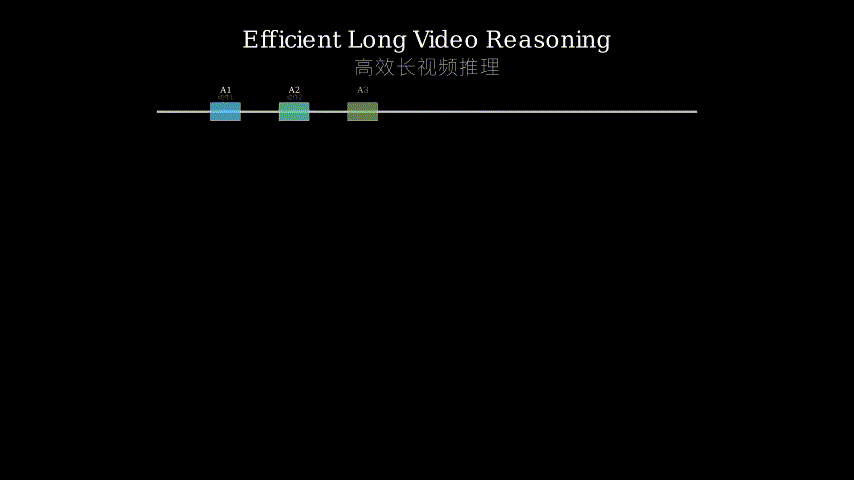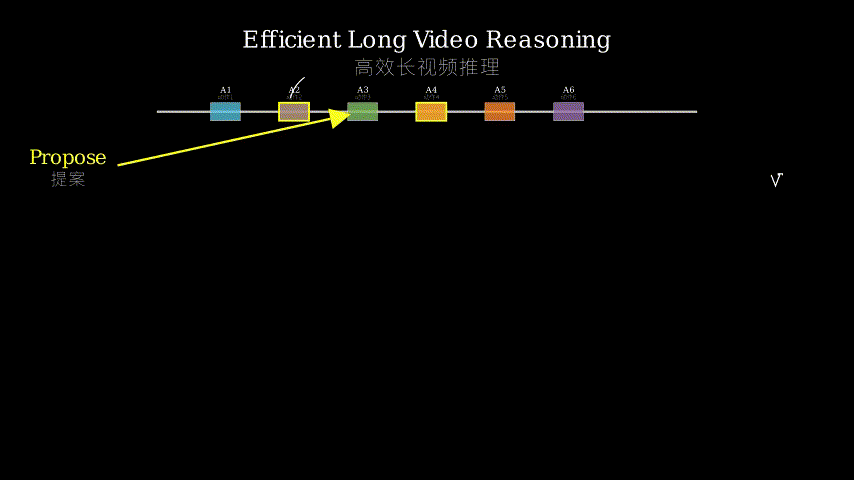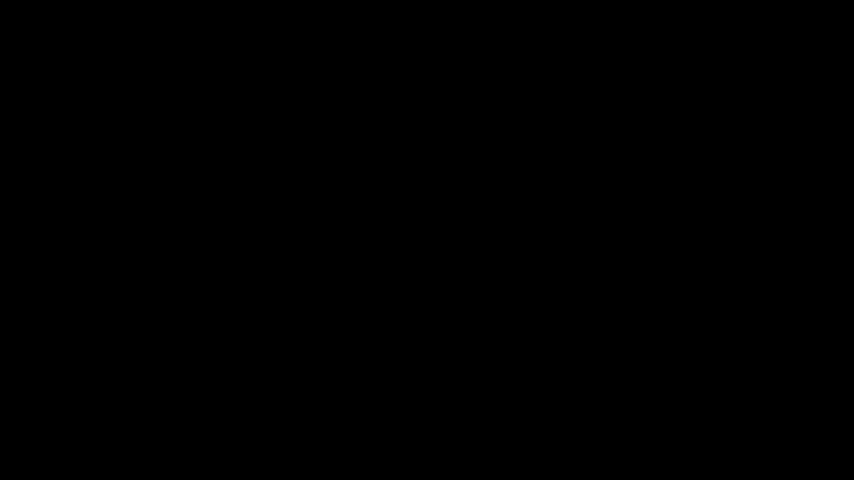
TimeProVe has two stages: Propose (cheap) and Verify (expensive). The propose stage uses an Action-based Candidate Evidence (ACE) module that first detects atomic action segments from the video using a small temporal action detector (e.g., a pretrained I3D). Then a lightweight LLM (e.g., LLaMA-7B) takes the query and, for each detected action segment, generates candidate answers and a justification why that segment might contain the answer. The output is a set of (answer, start-end time, confidence) triples.
The verify stage takes only the top-K candidate triples (by confidence) and feeds the corresponding video clips to a strong VLM (e.g., GPT-4o) for final answer prediction. The VLM sees the query, the candidate answer, and the raw clip frames – but only for a handful of clips, not the whole video.
       Video frames
         |
         v
+-------------------+
| Temporal Action   |  (lightweight detector)
| Detector (TAD)    |
+-------------------+
         |  action segments
         v
+-------------------+
| ACE Module        |  (lightweight LLM + query)
| - generates       |
|   (answer, window,|
|    confidence)    |
+-------------------+
         | top-K candidates
         v
+-------------------+
| Heavy VLM (verify)|  (only on these clips)
| - final answer    |
+-------------------+
         |
         v
      Answer
Load-bearing metaphor: Think of a library archive of thousands of hours of security tape. You’re looking for a specific event. Before, you’d hire a brilliant detective (heavy VLM) to watch every tape from start to finish – slow and expensive. TimeProVe instead hires a cheap security guard (lightweight action detector) who knows which rooms have what types of movement. The guard quickly flags the relevant tape segments (clips) and writes a sticky note (ACE) for each clip: “This clip might be the coffee machine being turned on around 14
.” Then the detective only watches those flagged segments, reads the sticky notes, and makes the final call. The guard doesn’t need to understand the query deeply – just pattern-match action categories. The detective doesn’t need to watch the whole archive – just the candidate clips.Key Concepts
-
Action-grounded candidate generation: Instead of treating video as a blur of pixels, TimeProVe first breaks it into discrete atomic actions (e.g., open fridge, pour milk, close fridge). The ACE module uses these action boundaries as natural anchors for evidence windows. Concrete example: query “Did the person add milk to the coffee?” – the detector gives you “open fridge (12:01-12
)” and “pour liquid (12:05-12)”. ACE can then pair the action category with the question to propose “Yes, around 12” with evidence window [12, 12]. This is far more precise than a sliding window or random sampling. -
Lightweight verifier pattern: The heavy VLM is used only for *verification, not exploration. This is critical because VLMs are great at intricate reasoning but bad at sifting through irrelevant data. By decoupling exploration (cheap) from verification (expensive), the total cost becomes linear in the number of candidate clips, not the video duration. In OTBs (videos up to 3 hours) with ~50 action segments, top-K=5 candidates means only 5% of the frames need VLM processing.
-
OpenTSUBench (OTB): A new benchmark for temporal reasoning in Activities of Daily Living. Existing datasets (Charades-STA, ActivityNet-Captions) have short videos (30s-5min) and focus on single actions. OTB contains hour-long, untrimmed ADL videos in home and clinical settings, with open-ended questions that require grounding multiple action steps. This forces methods to handle sparse evidence and long-range temporal dependencies – exactly the gap TimeProVe addresses.
Framework Shift
Before (mainstream):
+-----------------------------------------+
| Full video (hours)                      |
|   +----------------------------------+  |
|   | Heavy VLM on all frames          |  |  <-- expensive: GPU-hours
|   | (or dense sampling with captions)|  |
|   +----------------------------------+  |
| Output: answer                         |
+-----------------------------------------+

After (TimeProVe):
+-----------------------------------------+
| Full video (hours)                      |
|   +----------------------------------+  |
|   | Lightweight action detector      |  |  <-- cheap: CPU/light GPU
|   | -> action segments               |  |
|   +----------------------------------+  |
|                v                        |
|   +----------------------------------+  |
|   | ACE: propose (answer candidates) |  |  <-- cheap LLM inference
|   | -> top-K clips                   |  |
|   +----------------------------------+  |
|                v                        |
|   +----------------------------------+  |
|   | Heavy VLM on candidate clips     |  |  <-- expensive only on ~5 clips
|   | -> final answer                  |  |
|   +----------------------------------+  |
+-----------------------------------------+
From “process everything” to “propose, then verify”, the core shift is decoupling exploration (cheap, action-driven) from verification (expensive, reasoning-heavy). This mirrors how humans watch video: we scan for relevant activity regions, then focus attention.
Expert Assessment
Problem choice: Real gap. Long video QA is exploding (e.g., surveillance, healthcare, assistive tech), and prior work either ignores cost or sacrifices accuracy. The paper picks a sweet spot – ADL – but the methodology generalizes.
Method maturity: Clever insight dressed in simple components. No new backbone, no novel architecture – just a smart pipeline design. That’s admirable. The ACE module is lightweight LLM prompting, not heavy training. Some might say “hacky”, but it works.
Experimental integrity: Baselines are fair (ViLMA, EgoVLP, Flamingo variants), and the ablation study clearly shows each component’s contribution. The 93% cost reduction is impressive, though the exact dollar amounts depend on the VLM pricing model. One red flag: OTB is self-created – need to check if it’s biased toward their method (they own the benchmark). But the Charades-STA results (without any temporal grounding training) back up the generality.
Writing quality: Well-structured, but the metaphor is missing in the original paper – I added it. The paper could benefit from a clearer explanation of how ACE handles multi-step actions. The ablation on K (number of candidates) should be more detailed.
Verdict: Weak accept – solid incremental contribution, strong empirical results, practical impact. The propose-verify pattern is not revolutionary but is neatly executed and well-validated.
Takeaways
-
Action anchors: Use temporal action detection as a cheap pre-filter for any video reasoning task. The action boundaries provide natural evidence windows that are far cheaper than learned attention. Practitioners can swap in any lightweight detector (I3D, TSM, etc.) and pair it with a small LLM for candidate generation.
-
Cost-driven pipeline design: Explicitly model the cost of each stage (detector , VLM )。TimeProVe的93%成本削减来自一个简单洞察:让昂贵模型只验证、不探索。这个模式可以迁移到任何能用廉价方式生成假设、再用昂贵方式验证的领域(如文档问答、医学图像分诊)。
-
开放式基准很重要:大多数视频问答基准使用选择题或短答案。OTB的开放性问题加上带真值动作窗口的设定提高了门槛。如果你在构建视频推理系统,考虑使用开放式评估——它更难,也更贴近真实。