Paper: 2604.26946 Authors: Wanrong Zheng, Yunhao Ge, Laurent Itti Categories: cs.CV, cs.RO
The Gap
Multimodal large language models (MLLMs) can now navigate unknown environments by looking at images and following natural language instructions. The promise: drop GPT-4V into a robot, give it “go to the kitchen,” and watch it work. The reality: these zero-shot agents drift off course, stop too early, and fail most of the time.
Prior work uses MLLMs as step-by-step planners—at each timestep, the model sees the current view and decides the next action. This myopic approach has three failure modes: (1) no global sense of direction leads to wandering, (2) local decisions accumulate error without correction, (3) stopping criteria are unreliable because the model only sees “now.”
Problem: Zero-shot VLN agents fail frequently
   |
   v
Observation: MLLMs plan myopically (one view at a time)
   |
   v
Hypothesis: Navigation needs three temporal scopes
   |
   +---> Global: landmarks & coarse plan
   +---> Local: current view alignment
   +---> Retrospective: trajectory audit
   |
   v
Method: Three-Step Nav (forward/now/backward protocol)
   |
   v
Evidence: SOTA on R2R-CE (44.56% SR) and RxR-CE (35.68% SR)
   |
   v
Conclusion: Hierarchical temporal reasoning fixes MLLM drift
The Increment
One sentence: Before this paper, zero-shot VLN agents planned frame-by-frame and drifted; after, they plan hierarchically across three time horizons and stay on course.
Core Mechanism
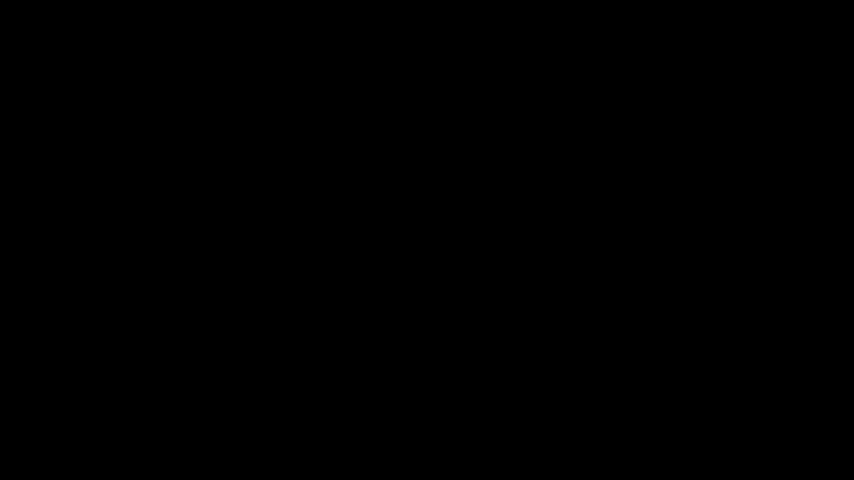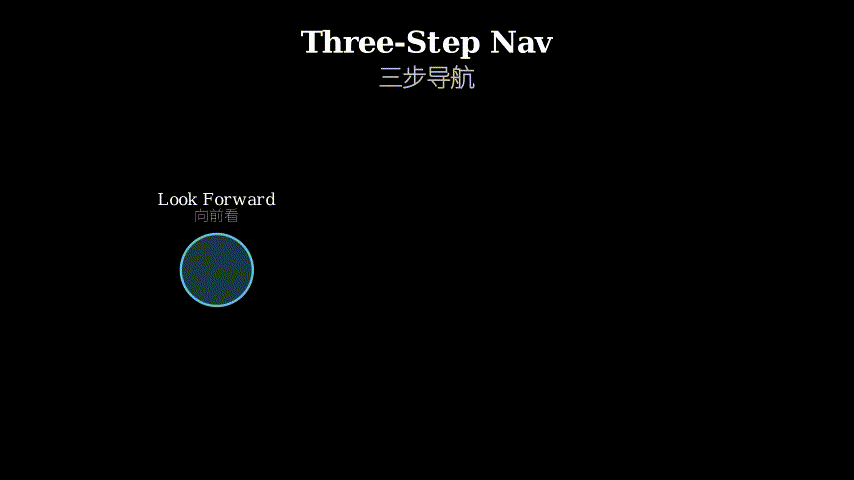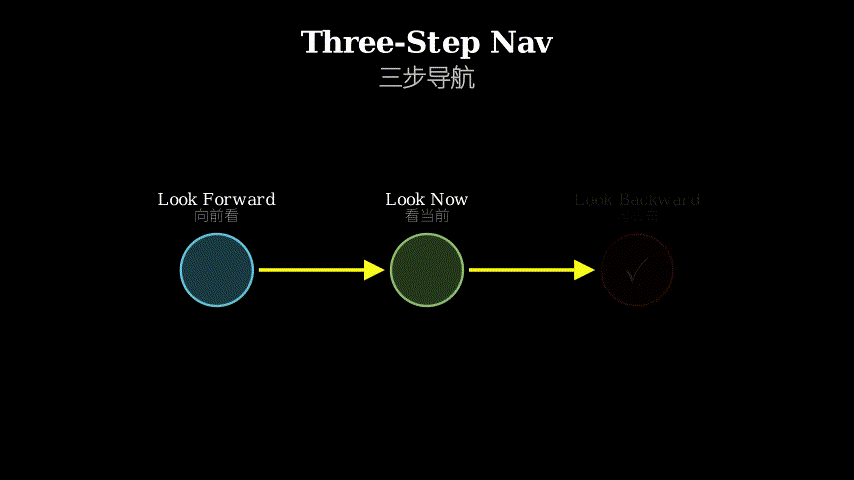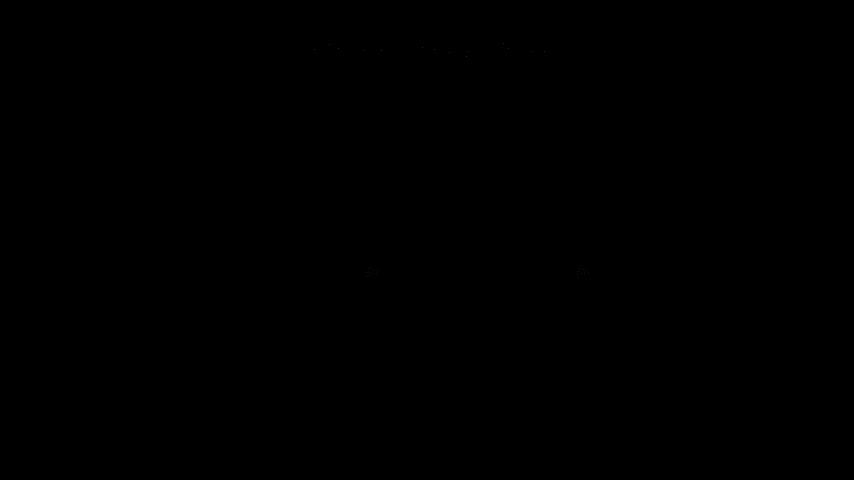
Three-Step Nav wraps around any MLLM-based navigator with a three-view protocol. First, “look forward” extracts global landmarks from the instruction (e.g., “go to the kitchen” → identify “stove,” “sink,” “fridge”). The MLLM generates a coarse plan by breaking the instruction into sub-goals tied to these landmarks.
Second, “look now” aligns the current visual observation with the next sub-goal. Instead of asking “what should I do?” the MLLM gets “you’re heading to the stove—which direction matches that sub-goal?” This grounds local decisions in the global plan.
Third, “look backward” audits the trajectory before stopping. The MLLM reviews the sequence of visited views against the original instruction. If drift is detected (e.g., “I see a bedroom but the goal was kitchen”), it rejects the stop and continues. This retrospective check prevents premature halting.
Instruction: "Go to the kitchen and turn left at the stove"
    |
    v
[Look Forward] -----> Extract landmarks: {stove, kitchen}
    |                 Generate sub-goals: [find kitchen, locate stove, turn left]
    v
[Look Now] --------> At each step:
    |                 Current view + next sub-goal --> action
    |                 (e.g., "heading to stove" + image --> "turn right")
    v
[Look Backward] ---> Before stopping:
    |                 Review trajectory: [view1, view2, ..., viewN]
    |                 Check: does this match "kitchen + stove + left"?
    v
Stop or Continue
Think of it like driving to a friend’s house in an unfamiliar city. You start by identifying major landmarks from the directions (“turn at the gas station, then look for the red barn”). As you drive, you match what you see now to the next landmark. Before parking, you double-check: “Did I pass the gas station? Did I see the red barn? Am I on the right street?” If something’s off, you keep going. Three-Step Nav does exactly this—global landmarks anchor the plan, local matching guides each turn, and retrospective audit catches accumulated errors before committing to “arrived.”
Key Concepts
-
Hierarchical temporal reasoning: Navigation isn’t a sequence of independent decisions—it’s a nested structure. Global context (where am I going?) constrains local choices (which way now?), and retrospective review (did I get there?) validates the whole trajectory. Most MLLM navigators collapse this hierarchy into a flat “what next?” loop, losing the ability to maintain direction or self-correct. Three-Step Nav restores the hierarchy by explicitly separating forward planning, present execution, and backward auditing.
-
Landmark-based sub-goal decomposition: Instead of treating instructions as opaque text, the method extracts visual anchors—objects or scenes that can be recognized in images. “Go to the kitchen” becomes “find a room with stove, sink, counters.” These landmarks serve as waypoints, turning a vague goal into a sequence of verifiable checkpoints. The key insight: MLLMs are better at matching images to concrete objects than inferring abstract spatial relationships.
Framework Shift
Before (myopic planning):              After (hierarchical planning):

Instruction                            Instruction
    |                                      |
    v                                      v
[MLLM at t=0]                          [Look Forward]
    | "what next?"                         | extract landmarks
    v                                      | generate sub-goals
Action_0                                   v
    |                                  [Look Now] <--+
    v                                      | align view    |
[MLLM at t=1]                              | to sub-goal   |
    | "what next?"                         v               |
    v                                  Action_t            |
Action_1                                   |               |
    |                                      v               |
   ...                                 [Look Backward]     |
    |                                      | audit path    |
[MLLM at t=N]                              v               |
    | "stop?"                           Stop? ----No-------+
    v                                      |
Stop (often wrong)                        Yes
                                           v
                                      Stop (verified)
From reactive step-by-step to deliberative plan-execute-audit, the core shift is temporal scope expansion—the agent now reasons across past, present, and future simultaneously.
Expert Assessment
Problem choice: Real gap. Zero-shot VLN is a legitimate frontier—fine-tuned models work but don’t generalize, and current MLLM approaches fail >50% of the time on standard benchmarks. The three failure modes (drift, premature stop, no global plan) are well-documented in prior work. This isn’t manufactured.
Method maturity: Clever insight, not brute force. The three-view protocol is simple—no new architectures, no training, just prompt engineering with temporal structure. The elegance is in recognizing that MLLMs already have the capabilities (landmark extraction, trajectory review) but need the right scaffolding to use them. However, the method is still prompt-dependent; different MLLM backbones may need tuning.
Experimental integrity: Baselines are fair (compares against other zero-shot MLLM methods like NavGPT, LLaVA-Nav). The numbers are strong—44.56% success rate on R2R-CE vs. 37.8% for the next best. Ablations show each component (forward/now/backward) contributes. One concern: experiments only on two datasets (R2R-CE, RxR-CE), both from the same benchmark family. Generalization to other VLN tasks (object-goal navigation, vision-dialog navigation) is unproven.
Writing quality: Clear structure, good motivation. The three-step framing is memorable. Weakness: the “look backward” mechanism is under-explained—how exactly does the MLLM audit a trajectory? What prompts are used? The paper shows examples but doesn’t formalize the auditing logic. Rewriting Section 3.3 with explicit prompt templates and decision rules would strengthen reproducibility.
Verdict: weak accept — Solid contribution with clean results, but limited scope (two related datasets) and under-specified auditing mechanism prevent strong accept.
Takeaways
Hierarchical prompting for sequential tasks: The three-view protocol (forward/now/backward) is a general pattern. Any task where an LLM makes a sequence of decisions can benefit from separating global planning, local execution, and retrospective validation. Example: code generation (sketch architecture → write function → review for bugs), multi-step reasoning (identify sub-questions → answer each → check consistency).
Landmark extraction as grounding: Instead of asking models to reason about abstract goals, extract concrete visual or textual anchors first. This reduces hallucination and gives the model verifiable checkpoints. Transfers to: document QA (extract key entities before answering), video understanding (identify salient frames before summarizing).
Retrospective auditing as a safety layer: Before committing to a final decision (stop navigating, submit answer, deploy code), have the model review the entire process. This catches accumulated drift that local checks miss. Cheap to implement (one extra LLM call) and broadly applicable.
论文: 2604.26946 作者: Wanrong Zheng, Yunhao Ge, Laurent Itti 分类: cs.CV, cs.RO
缺口
多模态大语言模型(MLLM)现在可以通过看图像和遵循自然语言指令来导航未知环境。
承诺是:把 GPT-4V 装进机器人,给它”去厨房”的指令,然后看它工作。
现实是:这些零样本智能体会偏离路线,过早停止,大多数时候都会失败。
先前工作将 MLLM 用作逐步规划器——在每个时间步,模型看到当前视图并决定下一个动作。
这种短视方法有三种失败模式:(1)没有全局方向感导致游荡,(2)局部决策累积误差而无法纠正,(3)停止标准不可靠,因为模型只看到”现在”。
问题:零样本 VLN 智能体频繁失败
   |
   v
观察:MLLM 短视规划(一次一个视图)
   |
   v
假设:导航需要三个时间尺度
   |
   +---> 全局:地标和粗略计划
   +---> 局部:当前视图对齐
   +---> 回溯:轨迹审计
   |
   v
方法:Three-Step Nav(前视/当前/后视协议)
   |
   v
证据:R2R-CE (44.56% SR) 和 RxR-CE (35.68% SR) 达到 SOTA
   |
   v
结论:分层时间推理修复 MLLM 漂移
增量
一句话:这篇论文之前,零样本 VLN 智能体逐帧规划并漂移;
之后,它们跨三个时间视野分层规划并保持航向。
核心机制
Three-Step Nav 用三视图协议包装任何基于 MLLM 的导航器。
首先,“前视”从指令中提取全局地标(例如,“去厨房” → 识别”炉灶”、“水槽”、“冰箱”)。
MLLM 通过将指令分解为与这些地标绑定的子目标来生成粗略计划。
其次,“当前视”将当前视觉观察与下一个子目标对齐。
不是问”我应该做什么?“,而是 MLLM 得到”你正在前往炉灶——哪个方向与该子目标匹配?“这将局部决策锚定在全局计划中。
第三,“后视”在停止前审计轨迹。
MLLM 根据原始指令审查访问过的视图序列。
如果检测到漂移(例如,“我看到卧室但目标是厨房”),它拒绝停止并继续。
这种回溯检查防止过早停止。
指令:"去厨房并在炉灶处左转"
    |
    v
[前视] -----> 提取地标:{炉灶, 厨房}
    |         生成子目标:[找到厨房, 定位炉灶, 左转]
    v
[当前视] --------> 在每一步:
    |              当前视图 + 下一个子目标 --> 动作
    |              (例如,"前往炉灶" + 图像 --> "右转")
    v
[后视] ---> 停止前:
    |       审查轨迹:[视图1, 视图2, ..., 视图N]
    |       检查:这是否匹配"厨房 + 炉灶 + 左转"?
    v
停止或继续
想象一下在陌生城市开车去朋友家。
你首先从方向中识别主要地标(“在加油站转弯,然后寻找红色谷仓”)。
开车时,你将现在看到的与下一个地标匹配。
停车前,你再次检查:“我经过加油站了吗?
我看到红色谷仓了吗?
我在正确的街道上吗?“如果有问题,你继续前进。
Three-Step Nav 正是这样做的——全局地标锚定计划,局部匹配指导每次转弯,回溯审计在承诺”到达”之前捕获累积误差。
关键概念
- 分层时间推理:导航不是一系列独立决策——它是嵌套结构。
全局上下文(我要去哪里?)约束局部选择(现在往哪走?),回溯审查(我到了吗?)验证整个轨迹。
大多数 MLLM 导航器将这种层次结构折叠成扁平的”下一步是什么?“循环,失去了保持方向或自我纠正的能力。
Three-Step Nav 通过明确分离前向规划、当前执行和后向审计来恢复层次结构。
- 基于地标的子目标分解:该方法不是将指令视为不透明文本,而是提取视觉锚点——可以在图像中识别的物体或场景。
“去厨房”变成”找到有炉灶、水槽、台面的房间”。
这些地标充当航点,将模糊目标转化为一系列可验证的检查点。
关键洞察:MLLM 更擅长将图像与具体物体匹配,而不是推断抽象空间关系。
框架转变
之前(短视规划):                  之后(分层规划):

指令                                指令
    |                                   |
    v                                   v
[MLLM 在 t=0]                       [前视]
    | "下一步?"                         | 提取地标
    v                                   | 生成子目标
动作_0                                  v
    |                               [当前视] <--+
    v                                   | 对齐视图    |
[MLLM 在 t=1]                           | 到子目标    |
    | "下一步?"                         v            |
    v                               动作_t           |
动作_1                                  |            |
    |                                   v            |
   ...                              [后视]           |
    |                                   | 审计路径   |
[MLLM 在 t=N]                           v            |
    | "停止?"                        停止? ---否----+
    v                                   |
停止(常错)                            是
                                        v
                                   停止(已验证)
从反应式逐步到深思熟虑的计划-执行-审计,核心转变是时间范围扩展——智能体现在同时跨过去、现在和未来推理。
专家评审
选题眼光:真实缺口。
零样本 VLN 是合法前沿——微调模型有效但不泛化,当前 MLLM 方法在标准基准上失败率 >50%。
三种失败模式(漂移、过早停止、无全局计划)在先前工作中有充分记录。
这不是人造的。
方法成熟度:巧妙洞察,非蛮力。
三视图协议很简单——没有新架构,没有训练,只是带有时间结构的提示工程。
优雅之处在于认识到 MLLM 已经具备能力(地标提取、轨迹审查),但需要正确的脚手架来使用它们。
然而,该方法仍然依赖提示;
不同的 MLLM 主干可能需要调整。
实验诚意:基线公平(与其他零样本 MLLM 方法如 NavGPT、LLaVA-Nav 比较)。
数字强劲——R2R-CE 上 44.56% 成功率 vs. 次佳的 37.8%。
消融实验显示每个组件(前视/当前视/后视)都有贡献。
一个担忧:实验仅在两个数据集(R2R-CE、RxR-CE)上进行,两者都来自同一基准家族。
对其他 VLN 任务(目标导航、视觉对话导航)的泛化未经证明。
写作功力:结构清晰,动机良好。
三步框架令人难忘。
弱点:“后视”机制解释不足——MLLM 究竟如何审计轨迹?
使用什么提示?
论文展示了示例但没有形式化审计逻辑。
用显式提示模板和决策规则重写第 3.3 节将增强可重现性。
判决:弱接收 — 扎实贡献和清晰结果,但有限范围(两个相关数据集)和未充分指定的审计机制阻止强接收。
要点总结
顺序任务的分层提示:三视图协议(前视/当前视/后视)是通用模式。
任何 LLM 做出一系列决策的任务都可以从分离全局规划、局部执行和回溯验证中受益。
示例:代码生成(草拟架构 → 编写函数 → 审查错误),多步推理(识别子问题 → 回答每个 → 检查一致性)。
地标提取作为锚定:不是让模型推理抽象目标,而是首先提取具体的视觉或文本锚点。
这减少了幻觉并为模型提供可验证的检查点。
迁移到:文档问答(回答前提取关键实体),视频理解(总结前识别显著帧)。
回溯审计作为安全层:在承诺最终决策(停止导航、提交答案、部署代码)之前,让模型审查整个过程。
这捕获了局部检查遗漏的累积漂移。
实现成本低(一次额外的 LLM 调用)且广泛适用。