Paper: 2604.25895 Authors: Steve Coyne Categories: cs.CY, cs.AI, cs.CL
The Gap
RLHF has become the dominant method for aligning language models, but the field treats human annotators as a black box labeled “human feedback.” Existing work focuses on technical pipeline optimization—better reward models, more efficient training, cleaner data collection—while leaving a foundational question unexamined: what normative role do annotators actually play? Are they executing the designers’ vision, reporting objective facts, or exercising independent judgment?
This ambiguity isn’t just philosophical. It creates concrete problems: pipelines designed for one role fail when annotators behave according to another, disagreement is handled inconsistently (sometimes averaged away, sometimes treated as signal), and validation criteria remain ad hoc. The gap is conceptual infrastructure—we’re building increasingly sophisticated systems on an undefined foundation.
Problem: RLHF treats annotators as undifferentiated "feedback"
   |
   v
Assumption: Different annotation tasks require different normative models
   |
   v
Method: Distinguish three models (extension/evidence/authority)
        + Map each to appropriate pipeline design choices
   |
   v
Evidence: Survey of landmark papers shows implicit model mixing
   |
   v
Conclusion: Decompose annotation dimensions, tailor pipelines per model
The Increment
One sentence: Before this paper, RLHF pipelines treated all human judgments uniformly; after, we have a conceptual framework that distinguishes three normative roles and prescribes different handling for each.
Core Mechanism
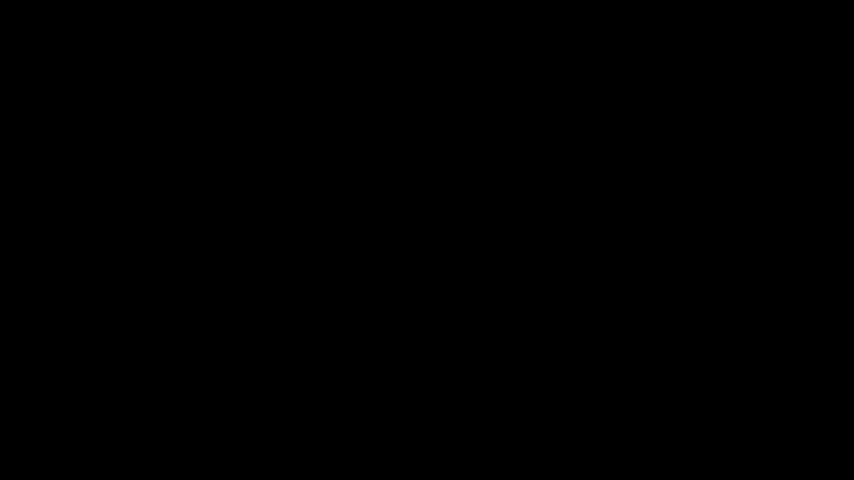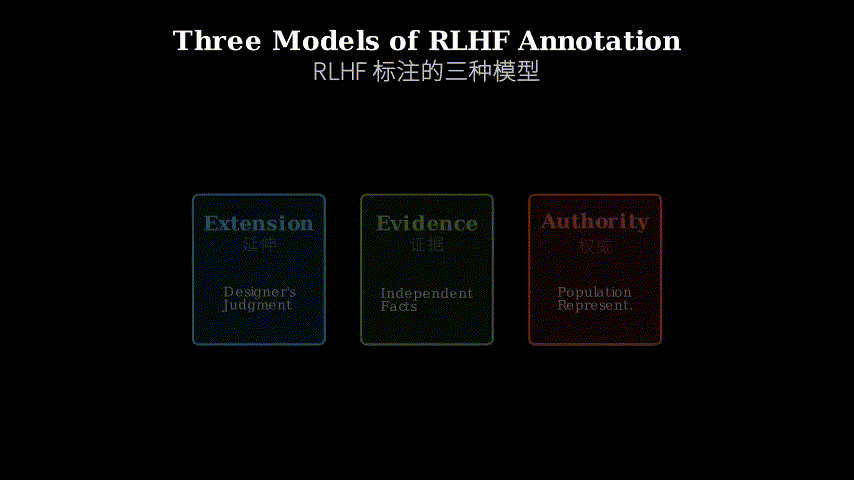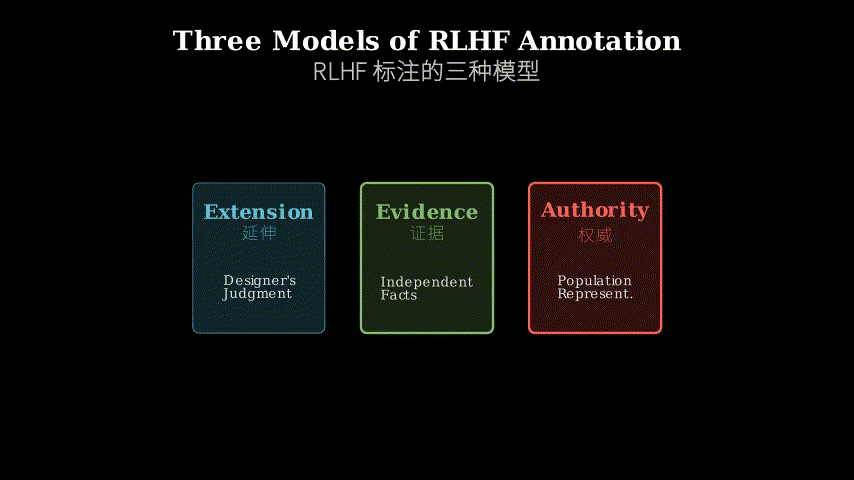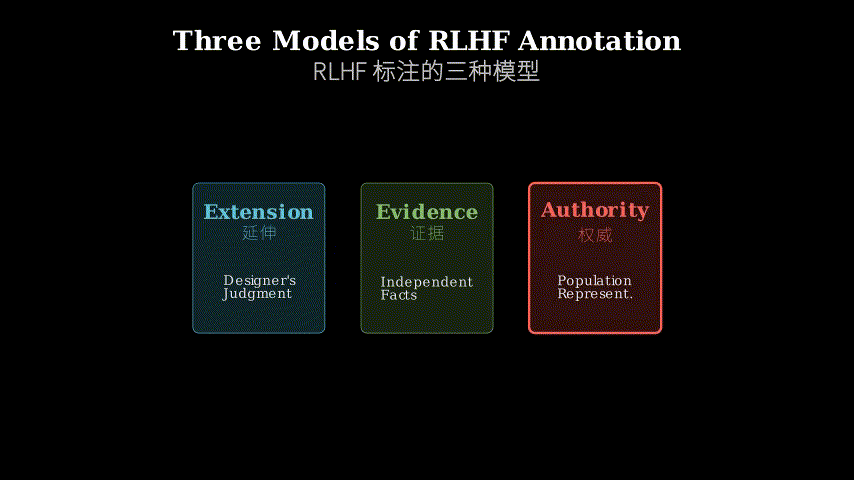
The paper doesn’t propose a new algorithm—it provides a taxonomy. The core mechanism is conceptual decomposition: take the monolithic notion of “human feedback” and split it into three models based on the annotator’s normative relationship to the output.
Extension model: Annotators are proxies for system designers. They’re trained to internalize and apply the designers’ preferences. Think of them as additional hands executing a centralized vision. Disagreement here is noise—it means training was incomplete or instructions were unclear. The pipeline should maximize inter-annotator agreement through detailed guidelines, calibration sessions, and quality control. Aggregation is straightforward: majority vote or consensus, with outliers flagged for retraining.
Evidence model: Annotators are measurement instruments reporting on external facts. These facts might be linguistic (is this grammatical?), social (would this be considered offensive?), or even moral (does this violate a widely-held norm?). Disagreement here is signal—it reveals uncertainty or genuine variation in the phenomenon being measured. The pipeline should sample diverse annotators to capture this variation, validate against ground truth where available, and aggregate using statistical methods that preserve uncertainty (weighted averaging, confidence intervals).
Authority model: Annotators are representatives of the user population, exercising legitimate judgment about what the system should do. They’re not implementing someone else’s vision or reporting facts—they’re making decisions. Disagreement here is fundamental—different stakeholders have different values. The pipeline should ensure demographic representativeness, make the decision-making process transparent, and aggregate using democratic methods (voting, deliberation) rather than statistical averaging.
Extension Model:          Evidence Model:           Authority Model:

Designer                  Phenomenon                Population
   |                         |                         |
   v                         v                         v
Guidelines                Sampling                 Selection
   |                         |                         |
   v                         v                         v
Annotators                Annotators               Annotators
(proxies)                 (instruments)            (representatives)
   |                         |                         |
   v                         v                         v
Consensus                 Distribution             Democratic
(noise reduction)         (capture variance)       (value aggregation)
Think of it like three different ways to use a focus group. Extension: You’re a product designer testing whether your team correctly implemented your vision—you want the focus group trained on your design principles, and you’re looking for unanimous “yes, this matches the brief.” Evidence: You’re a market researcher measuring consumer preferences—you want a representative sample, and you’re mapping the distribution of opinions. Authority: You’re a community deciding what to build—the focus group has decision-making power, and you’re running a vote or deliberation process.
Key Concepts
-
Normative role: This isn’t about what annotators do (click buttons, write text) but what justifies using their judgments. In the extension model, justification comes from fidelity to designer intent. In the evidence model, it comes from measurement validity. In the authority model, it comes from representativeness and legitimacy. The same annotation task (e.g., “rate this response”) can have different normative roles depending on why we care about the rating. If we care because it reflects the designer’s quality standards, that’s extension. If we care because it measures user satisfaction, that’s evidence. If we care because users have a right to shape the system, that’s authority.
-
Disagreement interpretation: The three models give opposite prescriptions for handling disagreement. Extension treats it as error (fix through training). Evidence treats it as data (preserve through statistical methods). Authority treats it as legitimate pluralism (resolve through democratic process). Most RLHF papers implicitly choose one interpretation without justifying why. This matters because the choice determines whether you average away minority views, weight them by confidence, or give them proportional representation.
-
Validation criteria: How do you know if your annotation pipeline is working? Extension model: high inter-annotator agreement, alignment with designer judgments. Evidence model: correlation with external ground truth, test-retest reliability. Authority model: demographic representativeness, procedural fairness. These criteria can conflict—a highly trained, homogeneous annotator pool (good for extension) is terrible for authority. A demographically representative pool (good for authority) may have low agreement (bad for extension).
Framework Shift
Before (mainstream approach):        After (this paper):

Human Feedback                       Extension    Evidence    Authority
      |                                 |            |            |
      v                                 v            v            v
  Annotation                        Consensus   Distribution  Democratic
      |                                 |            |            |
      v                                 v            v            v
  Aggregation                       Designer    Measurement  Stakeholder
  (one-size)                         Intent       Validity   Legitimacy
      |                                 |            |            |
      v                                 +------------+------------+
 Reward Model                                      |
                                                   v
                                            Reward Model
                                          (dimension-specific)
From monolithic “human feedback” to decomposed annotation dimensions, the core shift is recognizing that different aspects of model behavior require different normative justifications and therefore different pipeline designs.
Expert Assessment
Problem choice: This is a real gap, not manufactured. The RLHF literature has been remarkably unreflective about the normative foundations of human feedback. The problem sits at a critical juncture—as these systems move from research to deployment, the “who decides what the model should do?” question becomes unavoidable. The timing is right.
Method maturity: This is conceptual work, not empirical, so “method” means the taxonomy itself. The three-way distinction is clean and well-motivated, drawing on established frameworks from political philosophy and measurement theory. The weakness is that it’s a first cut—there are likely hybrid cases or additional models (e.g., annotators as adversarial red-teamers). The paper acknowledges this but doesn’t fully explore the boundaries.
Experimental integrity: No experiments—this is a conceptual paper. The “evidence” is a literature survey showing how existing papers implicitly mix models. The survey is illustrative rather than systematic, which is fine for a position paper but limits the empirical claims. The author could have strengthened this by analyzing a larger corpus or conducting interviews with RLHF practitioners.
Writing quality: The paper is clear and well-structured, but the middle section (surveying existing work) drags. The failure modes section is the most valuable—concrete examples of what goes wrong when models are conflated—but it’s buried. Rewriting to lead with failure modes, then introduce the taxonomy as a solution, would make the argument more compelling. The normative criteria section (how to choose among models) feels underdeveloped—it’s where the rubber meets the road, but it’s only two pages.
Verdict: weak accept — Addresses an important conceptual gap with a useful framework, but the analysis could be deeper and the prescriptive guidance more concrete.
Takeaways
For practitioners building RLHF pipelines: Don’t use a single annotation protocol for all dimensions. Decompose your task. Safety judgments (is this harmful?) might be evidence-based—you’re measuring against social norms. Style preferences (is this engaging?) might be authority-based—users have legitimate disagreement. Factual accuracy (is this correct?) is evidence-based but with ground truth. Design separate pipelines for each.
For researchers: The extension/evidence/authority distinction is a useful lens for analyzing existing work. When you read an RLHF paper, ask: which model is implicit in their annotation protocol? Does their aggregation method match? Many papers use evidence-model language (measuring preferences) but extension-model methods (training for agreement).
For policy discussions: The authority model provides vocabulary for the “who should control AI?” debate. If you believe users should have a say in model behavior, you need annotation pipelines designed for representativeness and democratic aggregation, not just accuracy or efficiency. This has implications for how companies should structure their feedback processes.
Transferable technique: The “decompose by normative role” approach applies beyond RLHF. Any system that aggregates human judgments—content moderation, recommendation systems, search ranking—faces the same question: are judges implementing a policy, measuring a phenomenon, or exercising authority? The answer determines how you should recruit, train, and aggregate.
论文: 2604.25895 作者: Steve Coyne 分类: cs.CY, cs.AI, cs.CL
缺口
RLHF 已成为对齐语言模型的主流方法,但该领域把人类标注者当作一个标着”人类反馈”的黑箱。
现有工作聚焦于技术流程优化——更好的奖励模型、更高效的训练、更干净的数据收集——却对一个根本问题视而不见:标注者究竟扮演什么规范角色?
他们是在执行设计者的愿景、报告客观事实,还是行使独立判断?
这种模糊不只是哲学问题。
它制造了具体麻烦:为某种角色设计的流程在标注者按另一种角色行事时失效,分歧处理不一致(有时被平均掉,有时被当作信号),验证标准临时拼凑。
缺口在于概念基础设施——我们在未定义的地基上建造越来越复杂的系统。
问题:RLHF 把标注者当作无差别的"反馈"
   |
   v
假设:不同标注任务需要不同的规范模型
   |
   v
方法:区分三种模型(延伸/证据/权威)
      + 将每种模型映射到相应的流程设计选择
   |
   v
证据:对标志性论文的调研显示隐含的模型混用
   |
   v
结论:分解标注维度,为每种模型定制流程
增量
一句话:这篇论文之前,RLHF 流程统一对待所有人类判断;
之后,我们有了一个概念框架,区分三种规范角色并为每种角色开出不同的处理方案。
核心机制
这篇论文没有提出新算法——它提供了一套分类法。
核心机制是概念分解:把”人类反馈”这个整体概念拆成三种模型,依据标注者与输出之间的规范关系来划分。
延伸模型:标注者是系统设计者的代理。
他们接受训练以内化并应用设计者的偏好。
把他们想象成执行集中愿景的额外人手。
这里的分歧是噪音——意味着训练不完整或指令不清晰。
流程应通过详细指南、校准会议和质量控制来最大化标注者间一致性。
聚合很直接:多数投票或共识,异常值标记后重新训练。
证据模型:标注者是报告外部事实的测量仪器。
这些事实可能是语言学的(这合乎语法吗?
)、社会性的(这会被认为冒犯吗?
)、甚至道德性的(这违反了广泛持有的规范吗?
)。
这里的分歧是信号——它揭示了被测现象的不确定性或真实变异。
流程应抽样多样化的标注者以捕捉这种变异,在有真值的地方验证,并使用保留不确定性的统计方法聚合(加权平均、置信区间)。
权威模型:标注者是用户群体的代表,对系统应该做什么行使合法判断。
他们不是在实现别人的愿景或报告事实——他们在做决策。
这里的分歧是根本性的——不同利益相关者有不同价值观。
流程应确保人口统计学代表性,让决策过程透明,并使用民主方法(投票、协商)而非统计平均来聚合。
延伸模型:              证据模型:              权威模型:

设计者                  现象                    群体
   |                      |                       |
   v                      v                       v
指南                    抽样                    选拔
   |                      |                       |
   v                      v                       v
标注者                  标注者                  标注者
(代理)                  (仪器)                  (代表)
   |                      |                       |
   v                      v                       v
共识                    分布                    民主
(降噪)                  (捕捉变异)              (价值聚合)
把它想象成使用焦点小组的三种不同方式。
延伸:你是产品设计师,测试团队是否正确实现了你的愿景——你希望焦点小组接受过你的设计原则训练,你在寻找一致的”是的,这符合简报”。
证据:你是市场研究员,测量消费者偏好——你想要代表性样本,你在绘制意见分布图。
权威:你是社区,决定要建造什么——焦点小组有决策权,你在运行投票或协商流程。
关键概念
- 规范角色:这不是关于标注者做什么(点按钮、写文本),而是关于什么证明了使用他们判断的正当性。
在延伸模型中,正当性来自对设计者意图的忠实度。
在证据模型中,来自测量有效性。
在权威模型中,来自代表性和合法性。
同一个标注任务(例如”给这个回复打分”)可以有不同的规范角色,取决于我们为什么在意这个评分。
如果我们在意是因为它反映了设计者的质量标准,那是延伸。
如果我们在意是因为它测量了用户满意度,那是证据。
如果我们在意是因为用户有权塑造系统,那是权威。
- 分歧解读:三种模型对处理分歧给出相反的处方。
延伸把它当作错误(通过训练修正)。
证据把它当作数据(通过统计方法保留)。
权威把它当作合法的多元性(通过民主程序解决)。
大多数 RLHF 论文隐含地选择了一种解读而不说明理由。
这很重要,因为这个选择决定了你是平均掉少数派观点、按置信度加权,还是给予比例代表权。
- 验证标准:你怎么知道标注流程是否有效?
延伸模型:高标注者间一致性,与设计者判断对齐。
证据模型:与外部真值相关,重测信度。
权威模型:人口统计学代表性,程序公平性。
这些标准可能冲突——高度训练的同质标注者池(对延伸好)对权威来说很糟糕。
人口统计学代表性的池子(对权威好)可能一致性低(对延伸不好)。
框架转变
之前(主流方法):              之后(本文方法):

人类反馈                        延伸      证据      权威
    |                             |         |         |
    v                             v         v         v
  标注                          共识      分布      民主
    |                             |         |         |
    v                             v         v         v
  聚合                          设计者    测量      利益相关者
(一刀切)                      意图      有效性    合法性
    |                             |         |         |
    v                             +---------+---------+
奖励模型                                   |
                                           v
                                      奖励模型
                                    (维度特定)
从整体的”人类反馈”到分解的标注维度,核心转变是认识到模型行为的不同方面需要不同的规范证明,因此需要不同的流程设计。
专家评审
选题眼光:这是真缺口,不是人造的。
RLHF 文献对人类反馈的规范基础一直缺乏反思。
这个问题处于关键节点——随着这些系统从研究走向部署,“谁决定模型应该做什么?
“这个问题变得无法回避。
时机恰当。
方法成熟度:这是概念性工作,不是实证性的,所以”方法”指的是分类法本身。
三分法清晰且动机充分,借鉴了政治哲学和测量理论的既有框架。
弱点在于这是初步切分——可能存在混合情况或额外模型(例如标注者作为对抗性红队)。
论文承认了这一点但没有充分探索边界。
实验诚意:没有实验——这是概念论文。
“证据”是文献调研,展示现有论文如何隐含地混用模型。
调研是说明性的而非系统性的,这对立场论文来说没问题,但限制了实证主张。
作者本可以通过分析更大语料库或采访 RLHF 从业者来加强这一点。
写作功力:论文清晰且结构良好,但中间部分(调研现有工作)拖沓。
失效模式部分最有价值——模型混淆时出错的具体例子——但被埋没了。
重写成先展示失效模式,再引入分类法作为解决方案,会让论证更有说服力。
规范标准部分(如何在模型间选择)感觉欠发达——这是关键所在,但只有两页。
判决:弱接收 — 用有用的框架解决了重要的概念缺口,但分析可以更深入,规范性指导可以更具体。
要点总结
对于构建 RLHF 流程的实践者:不要对所有维度使用单一标注协议。
分解你的任务。
安全判断(这有害吗?
)可能基于证据——你在测量社会规范。
风格偏好(这吸引人吗?
)可能基于权威——用户有合法分歧。
事实准确性(这正确吗?
)基于证据但有真值。
为每个维度设计单独的流程。
对于研究者:延伸/证据/权威区分是分析现有工作的有用透镜。
当你读 RLHF 论文时,问:他们的标注协议中隐含了哪种模型?
他们的聚合方法匹配吗?
许多论文使用证据模型语言(测量偏好)但用延伸模型方法(训练以达成一致)。
对于政策讨论:权威模型为”谁应该控制 AI?
“辩论提供了词汇。
如果你相信用户应该对模型行为有发言权,你需要为代表性和民主聚合设计的标注流程,而不仅仅是准确性或效率。
这对公司应如何构建反馈流程有影响。
可迁移技术:“按规范角色分解”的方法适用于 RLHF 之外。
任何聚合人类判断的系统——内容审核、推荐系统、搜索排名——都面临同样的问题:评判者是在实施政策、测量现象,还是行使权威?
答案决定了你应该如何招募、训练和聚合。