Paper: 2607.18198 Authors: Peng Sun, Zhenglin Cheng, Deyuan Liu, Jun Xie, Xinyi Shang, Tao Lin Categories: cs.LG, cs.CV
The Gap
Modern generative modeling has three dominant paradigms, each with a real limitation:
GANs use an adversarial critic to push generated samples toward real data. But adversarial training is notoriously unstable—mode collapse, training divergence, and hyperparameter sensitivity are the norm, not the exception.
Diffusion models prescribe a noise-to-data path via iterative denoising. They produce stunning results but require 20-1000 function evaluations (NFEs) at inference time. Distillation helps, but introduces its own complexity and quality trade-offs.
Autoregressive models factorize the joint distribution sequentially. They’re elegant but fundamentally sequential—generation speed scales linearly with dimension.
Drifting Models (a recent line of work) tried to bridge diffusion and GAN ideas by using minibatch-wide all-pairs field computation to define sample dynamics. But this creates O(B²) computational cost per batch and high variance in gradient estimates.
This paper asks: can we get direct, sample-level regression supervision for a one-step generator without adversarial training, without multi-step denoising, and without expensive all-pairs fields?
Problem: One-step generation is hard
        |
        v
Existing paths each hit a wall
        |
        +---> GANs: adversarial instability
        +---> Diffusion: many NFEs required
        +---> Drifting: O(B^2) field cost, noise
        |
        v
Can we get cheap, direct supervision
for one-step generation?
        |
        v
Key assumption: Energy distance
can be decomposed into per-sample
pairwise interactions (3-body)
        |
        v
Method: Each sample attracted to
one real, repelled from one fake,
with online tracking for stability
        |
        v
Evidence: FID 1.63 on ImageNet-256
at NFE=1, competitive with multi-step
        |
        v
Conclusion: Tracked scattering is a
viable route to high-dim one-step gen
The Increment
One sentence: Before this paper, one-step high-quality generation required either distillation from multi-step models or unstable adversarial training; after this paper, energy-based scattering provides direct regression supervision that achieves comparable quality without either.
Core Mechanism
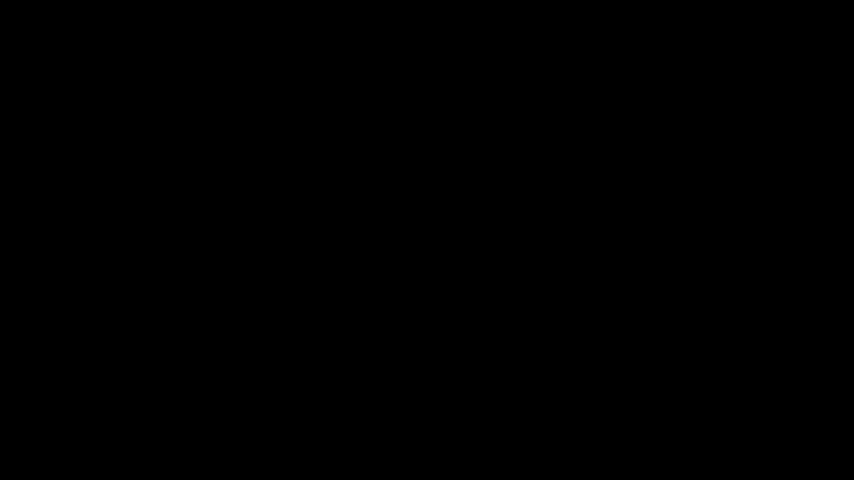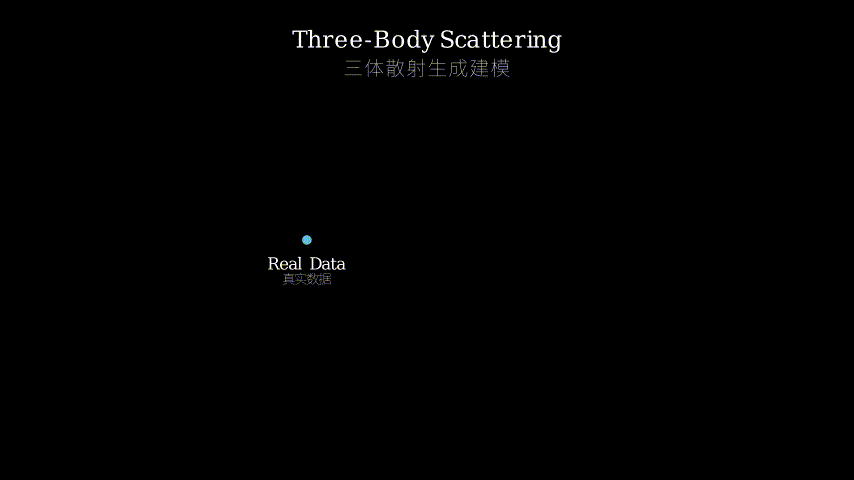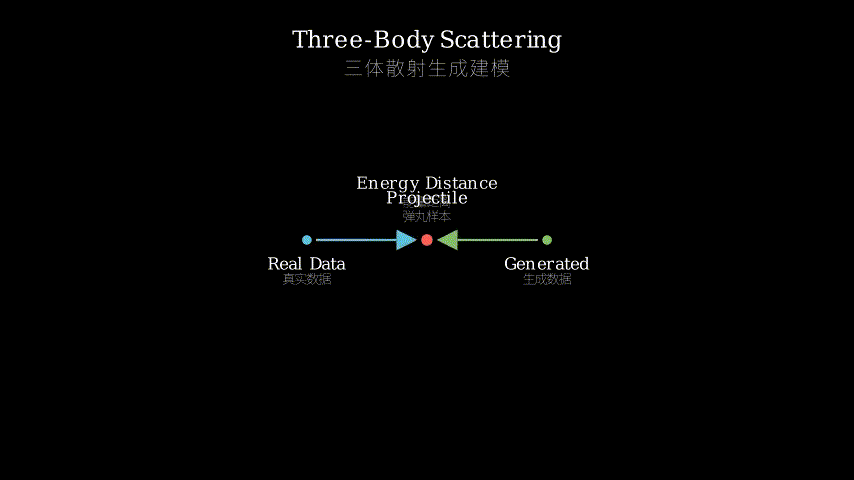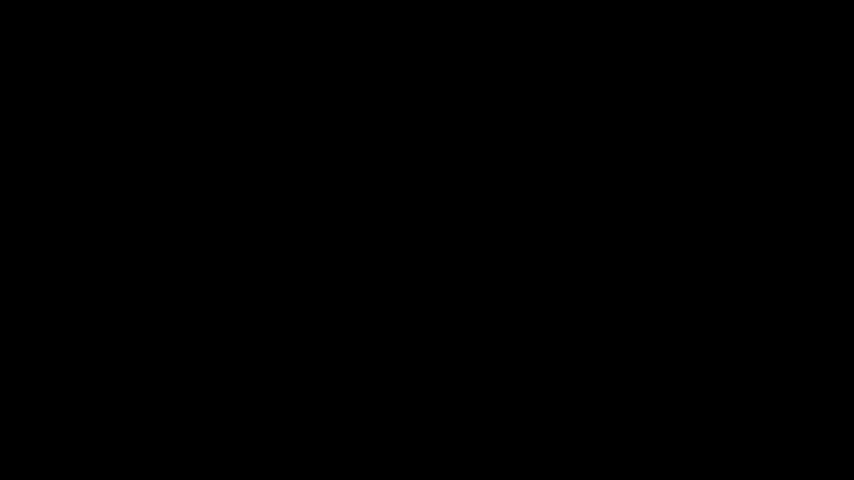
The method rests on a clean mathematical idea: the energy distance between two distributions can be decomposed into per-sample “scattering” interactions. Instead of computing a minibatch-wide vector field (as in Drifting Models), each training sample—the “projectile”—interacts with exactly two partners: one real data point (the “source”) and one independently generated point (the “anti-source”).
The projectile is attracted toward the real source and repelled from the anti-source. This creates a velocity field for each sample. Crucially, the expected velocity equals the Wasserstein-2 gradient flow of the energy distance—meaning this simple interaction is actually doing principled optimization in distribution space.
To reduce noise from this stochastic field, the authors introduce online tracking: instead of using raw velocities, they maintain an exponential moving average of the conditional expectation. This smooths out the per-sample noise without requiring the expensive all-pairs computation.
The architecture is straightforward: a generator (like DiT or PixelDiT) takes noise and produces an image in one step. The scattering loss provides direct regression targets for this generator. No discriminator network, no iterative sampling loop.
[Training Loop - One Step]

Noise z --> Generator G(z) --> Projectile x_p
                                    |
            +--- Attraction ---+    +--- Repulsion ---+
            |                  |    |                  |
            v                  |    v                  |
       Real source x_r        |  Fake source x_f      |
       (sampled from data)    |  (sampled from G)      |
            |                  |    |                  |
            +---> Force on x_p <--->+                  |
                        |                                |
                        v                                |
                  Raw velocity v_p                       |
                        |                                |
                        v                                |
               Online tracking (EMA)                     |
                        |                                |
                        v                                |
               Tracked velocity v_hat                    |
                        |                                |
                        v                                |
            Regression loss on generator <---------------+

[Scattering Dynamics]

    x_r (real)          x_p (projectile)         x_f (fake)
        *                       o                      x
        |                       |                      |
        +----- attraction ----->+<----- repulsion -----+
                                |
                                v
                         net velocity
                         (gradient flow)
Structural metaphor: Imagine you’re a painter learning to create realistic portraits. In the old GAN approach, a harsh art critic tells you “this is fake” or “this is real” but never tells you *why or how to fix it—you just get a thumbs up or thumbs down, and the critic keeps changing their standards. In the diffusion approach, you paint in 50 tiny layers, each one a subtle adjustment, which is precise but painfully slow.
The three-body scattering approach is different. You paint a portrait in one stroke. Then you look at two reference photos: one real portrait that’s beautiful (the source) and one bad portrait a previous version of you painted (the anti-source). The real portrait pulls your technique toward realism; the bad portrait pushes you away from your own mistakes. Each painting session, you get one pull and one push—a clear, directional signal. Over many sessions, you converge on realism. And because you track your average corrections over time (the EMA), you don’t overreact to any single weird portrait pair.
Key Concepts
-
Energy Distance: A way to measure how different two distributions are, based on the average distance between random samples. Think of it like this: if you and a friend each toss darts at a wall randomly, the energy distance between your two “dart distributions” is related to how far apart your darts tend to land on average, minus how far apart darts from the *same person land. If your distributions are identical, these two quantities cancel out and the distance is zero. The key insight is that this distance can be decomposed into pairwise interactions—no need to estimate densities or solve optimization problems.
-
Wasserstein-2 Gradient Flow: Imagine pouring water on a landscape. The water flows downhill following the steepest descent—that’s a gradient flow. Now imagine the “landscape” is a space of probability distributions, and the “height” is the energy distance. The Wasserstein-2 gradient flow is the optimal way for a distribution to morph toward a target, minimizing transport cost. The paper shows that the simple attraction-repulsion dynamics of three-body scattering exactly recover this flow in expectation—meaning the physics-inspired mechanism is doing the mathematically optimal thing.
-
Tracked Scattering: Each individual scattering interaction is noisy—it’s based on just one real sample and one fake sample, so the direction can be misleading. Tracked scattering is like a GPS that smooths out jittery readings. Instead of following each raw velocity signal, you maintain a running average (exponential moving average) of where the signals are pointing. This reduces variance dramatically without requiring you to compute the full all-pairs field across the entire minibatch.
Framework Shift
Before (mainstream):                   After (this paper):

  Noise                                Noise
    |                                    |
    v                                    v
  Generator ----> many steps ---->    Generator ----> 1 step ----> Image
    |                                    |
    v                                    v
  Critic (discriminator               Scattering loss
  or score network)                   (attraction + repulsion)
    |                                    |
    v                                    v
  Adversarial loss                    Regression loss
  or denoising loss                   (direct, stable)
  (unstable / slow)

Key difference: supervision signal comes from energy-based
pairwise interactions, not from a learned critic or
iterative denoising trajectory.
From iterative refinement with learned critics to one-step generation with energy-based scattering, the core shift is replacing supervision complexity (adversarial networks, multi-step schedules) with geometric simplicity (attraction toward real, repulsion from fake).
Expert Assessment
Problem choice: This is a genuine gap. One-step generation quality is the practical bottleneck for diffusion-based models in production. The field has been circling this problem through distillation, consistency models, and flow matching—but all these inherit the multi-step paradigm. Asking whether energy-based dynamics can provide direct one-step supervision is a legitimate and timely question.
Method maturity: The core insight—decomposing energy distance into per-sample three-body interactions—is elegant and mathematically clean. It’s not brute force; it’s finding the right decomposition. That said, the “three-body” framing is somewhat forced—it’s really pairwise attraction and repulsion, with the projectile being the point being optimized. The physics analogy adds flavor but shouldn’t be mistaken for actual three-body dynamics. The online tracking (EMA) is a practical engineering choice, not a theoretical contribution.
Experimental integrity: FID 1.63 at NFE=1 on ImageNet-256 is genuinely impressive and competitive with multi-step methods. The comparison against distillation-based one-step methods (like SDXL-Turbo, LCM) is fair—they compare against published numbers from established methods. However, the computational cost comparison deserves scrutiny: each training step may be cheaper than Drifting Models (O(B) vs O(B²)), but the total training cost and convergence speed aren’t thoroughly compared against alternatives like consistency models. The frozen image features for scattering is a pragmatic choice that may limit transferability.
Writing quality: The paper is dense but well-structured. The “design map” relating diffusion supervision, Drift dynamics, and GAN objectives is valuable—this kind of taxonomic clarity helps the field. The weakest section is the related work, which doesn’t adequately position against consistency models and flow matching—two very active and directly competing approaches. A deeper comparison there would elevate the whole paper.
Verdict: weak accept — The core decomposition is mathematically clean and the one-step results are strong, but the paper undersells the competition from consistency models and doesn’t fully justify why energy-based scattering should be preferred over simpler flow-matching objectives.
Takeaways
The decomposition trick: If you have a loss that requires O(B²) computation across a minibatch, look for whether it can be decomposed into O(B) per-sample terms. The energy distance is a case study—its all-pairs form has a sampling-based decomposition that preserves the gradient flow guarantee.
Direct regression beats adversarial training when you can get it: The paper demonstrates that for one-step generation, you don’t necessarily need a learned critic. If you can define a physics-inspired energy that provides regression targets, training becomes more stable. This principle may transfer to other domains where adversarial training is the bottleneck.
Tracking as variance reduction: The EMA-based tracking of conditional expectations is a simple but effective technique. If your loss involves stochastic pairwise interactions, maintaining a tracked estimate of the “true” direction can dramatically reduce noise. This is applicable beyond generation—to contrastive learning, metric learning, or any pairwise loss.
论文: 2607.18198 作者: Peng Sun, Zhenglin Cheng, Deyuan Liu, Jun Xie, Xinyi Shang, Tao Lin 分类: cs.LG, cs.CV
缺口
现代生成建模有三大主流范式,各有各的硬伤:
GAN 用对抗判别器把生成样本推向真实数据。 但对抗训练出了名地不稳定——模式崩塌、训练发散、超参敏感是常态。
扩散模型 通过迭代去噪来走完从噪声到数据的路径。 效果惊艳,但推理时需要 20-1000 次函数评估。 蒸馏能帮忙,但引入了额外的复杂度和质量损失。
自回归模型 按顺序分解联合分布。 数学上优雅,但本质上是串行的——生成速度和维度成正比。
Drifting Models 试图用小批量内的全场计算来桥接扩散和 GAN 思路, 但每个 batch 的计算开销是 O(B²),梯度估计的方差也很高。
这篇论文的问题是:能不能不靠对抗训练、不靠多步去噪、 不靠昂贵的全场计算,就给一步生成器提供直接的回归监督信号?
问题:一步高质量生成很难
        |
        v
现有路径各有瓶颈
        |
        +---> GAN:对抗训练不稳定
        +---> 扩散:推理步数太多
        +---> Drifting:O(B^2) 代价,方差大
        |
        v
能否用低成本的直接监督
实现一步生成?
        |
        v
关键假设:能量距离可以分解为
逐样本的成对交互(三体)
        |
        v
方法:每个样本被一个真实样本吸引、
被一个生成样本排斥,
在线追踪来降噪
        |
        v
证据:ImageNet-256 上 NFE=1,
FID 达到 1.63
        |
        v
结论:追踪散射是通往高维
一步生成的可行路径
增量
一句话: 在这篇论文之前,一步高质量生成要么依赖多步模型的蒸馏,要么依赖不稳定的对抗训练;之后,基于能量的散射机制提供了直接的回归监督,在不依赖两者的情况下达到了可比的质量。
核心机制
这个方法建立在一个简洁的数学洞察之上: 能量距离可以分解为逐样本的”散射”交互。 不同于 Drifting Models 在小批量内计算全场向量, 每个训练样本——“弹丸”——只和两个伙伴交互: 一个真实数据点(“源”)和一个独立生成的点(“反源”)。
弹丸被真实源吸引,被反源排斥,产生一个速度场。 关键的是,这个速度场的期望值正好等于能量距离的 Wasserstein-2 梯度流—— 意味着这个简单的交互实际上在做分布空间上的原则性优化。
为了降低这种随机场的噪声,作者引入了在线追踪: 不使用原始速度,而是维护条件期望的指数移动平均。 这平滑了逐样本的噪声,而不需要昂贵的全场计算。
架构很直接:一个生成器(如 DiT 或 PixelDiT)接收噪声, 一步输出图像。散射损失为生成器提供直接的回归目标。 没有判别器网络,没有迭代采样循环。
[训练循环 - 单步]

噪声 z --> 生成器 G(z) --> 弹丸 x_p
                                    |
            +--- 吸引 ---+          +--- 排斥 ---+
            |             |          |            |
            v             |          v            |
       真实源 x_r         |      伪源 x_f         |
       (从数据采样)      |   (从 G 采样)        |
            |             |          |            |
            +---> 对 x_p 的合力 <--->+             |
                        |                          |
                        v                          |
                  原始速度 v_p                      |
                        |                          |
                        v                          |
               在线追踪(EMA)                      |
                        |                          |
                        v                          |
               追踪速度 v_hat                      |
                        |                          |
                        v                          |
            对生成器的回归损失 <--------------------+

[散射动力学]

    x_r (真实)        x_p (弹丸)           x_f (伪)
        *                  o                   x
        |                  |                   |
        +---- 吸引 ------->+<------ 排斥 ------+
                           |
                           v
                      合速度方向
                      (梯度流)
核喻(结构性比喻):想象你在学画画,目标是画出逼真的肖像。
老办法 GAN 是这样的:一个刻薄的评论家看你画完后只说”假的”或”真的”, 从不告诉你为什么、怎么改——你只得到一个赞或踩, 而且评论家的标准还在不断变。
扩散模型是另一条路:你分 50 层慢慢叠加,每层做一点点微调。 精确但慢得要命。
三体散射不一样。你一笔画完一幅肖像。 然后你对照两张参考照片:一张是画得很好的真人肖像(源), 一张是你自己之前画的烂画(反源)。 好照片拉着你的手法向真实靠拢, 烂画推着你远离自己的毛病。 每次画画,你得到一次拉和一次推——清晰的方向性信号。 经过很多次练习,你收敛到逼真。
而且因为你追踪了自己修正是均值(EMA), 你不会因为某一张奇怪的参考照片对就过度反应。
关键概念
-
能量距离:衡量两个分布有多不同的方法,基于随机样本之间的平均距离。 想象你和朋友各往墙上随机扔飞镖。 能量距离和你们的飞镖平均落点有多远相关, 减去同一个人的飞镖之间的平均距离。 如果两个分布完全相同,这两项相消,距离为零。 关键洞见是这个距离可以分解为成对交互——不需要估计密度或解优化问题。
-
Wasserstein-2 梯度流:想象往地形上倒水,水沿着最陡的方向流下—— 那就是梯度流。现在想象”地形”是概率分布的空间, “高度”是能量距离。 Wasserstein-2 梯度流是分布向目标变形的最优路径, 最小化传输成本。 本文证明三体散射的吸引-排斥动态在期望上恰好恢复了这个流—— 意味着这个物理启发的机制在做数学上最优的事情。
-
追踪散射:单次散射交互是嘈杂的——只基于一个真实样本和一个伪样本, 方向可能有误导。 追踪散射就像一个能平滑抖动信号的 GPS。 你不跟随每个原始速度信号, 而是维护信号指向的移动平均(指数移动平均)。 这大幅降低了方差,而不需要在整个小批量上计算全场。
框架转变
之前(主流方法):                    之后(本文方法):

  噪声                                噪声
    |                                    |
    v                                    v
  生成器 ----> 多步迭代 ---->          生成器 ----> 一步 ----> 图像
    |                                    |
    v                                    v
  判别器(或得分网络)                  散射损失
    |                                  (吸引 + 排斥)
    v                                    |
  对抗损失或去噪损失                    v
  (不稳定 / 慢)                      回归损失
                                      (直接、稳定)

关键区别:监督信号来自基于能量的成对交互,
而非来自可学习的判别器或迭代去噪轨迹。
从用可学习判别器做迭代精修,到用基于能量的散射做一步生成, 核心转变是用几何简洁性(向真实吸引、向伪样本排斥) 替代了监督复杂性(对抗网络、多步调度)。
专家评审
选题眼光:这是一个真实的缺口。 一步生成质量是扩散模型落地的实际瓶颈。 领域一直在通过蒸馏、一致性模型、流匹配来绕这个问题—— 但它们都继承了多步范式的基因。 问能量动态能否提供直接的一步监督,是一个合法且及时的问题。
方法成熟度:核心洞察——将能量距离分解为逐样本的三体交互—— 是优雅且数学上干净的。这不是蛮力,而是找到了正确的分解。 不过”三体”的框架有些牵强——本质上是吸引和排斥的成对交互, 弹丸只是被优化的点。物理类比增加了味道, 但不应被当作真正的三体动力学。 在线追踪(EMA)是务实的工程选择,不是理论贡献。
实验诚意:NFE=1 时 ImageNet-256 上 FID 1.63 确实令人印象深刻, 与多步方法具有竞争力。 与基于蒸馏的一步方法(如 SDXL-Turbo、LCM)的比较是公平的—— 他们与已发表的成熟方法的数字做了对比。 然而计算代价的对比值得推敲: 每个训练步可能比 Drifting Models 便宜(O(B) vs O(B²)), 但总训练代价和收敛速度与一致性模型等替代方案没有做充分比较。 在冻结图像特征上做散射是务实的选择,但可能限制了迁移性。
写作功力:论文密度大但结构清晰。 将扩散监督、Drift 动态和 GAN 目标联系起来的”设计地图”很有价值—— 这种分类清晰度对领域有帮助。 最弱的部分是相关工作, 没有充分与一致性模型和流匹配定位—— 这两个非常活跃且直接竞争的方法。 在那里做更深入的比较能让整篇论文升一个档次。
判决:弱接收 —— 核心分解数学上干净,一步结果很强, 但论文对一致性模型的竞争估计不足, 也没有充分论证为什么基于能量的散射应该优于更简单的流匹配目标。
要点总结
分解技巧:如果你的损失需要在小批量上做 O(B²) 的计算, 看看能否分解为 O(B) 的逐样本项。 能量距离是一个案例研究——它的全场形式有一个采样分解, 保留了梯度流保证。
回归优于对抗训练(在可行时):论文证明, 对于一步生成,不一定需要可学习的判别器。 如果你能定义一个物理启发的能量来提供回归目标, 训练会更稳定。 这个原则可能迁移到对抗训练是瓶颈的其他领域。
追踪作为方差降低:基于 EMA 的条件期望追踪是一个简单但有效的技术。 如果你的损失涉及随机成对交互, 维护一个”真实”方向的追踪估计可以大幅降低噪声。 这适用于生成之外的场景——对比学习、度量学习或任何成对损失。