Paper: 2606.06476 Authors: Chenming Zhu, Jingli Lin, Yilin Long, Peizhou Cao, Tai Wang, Jiangmiao Pang, Xihui Liu Categories: cs.CV
The Gap
Current VLMs (GPT-4V, Gemini, Qwen-VL) handle visual reasoning well within frame boundaries but fail at spatial reasoning that requires imagining what’s outside their view. They can describe “a mug on a table” but struggle with “if I walk around this table, which side would I see the mug handle?” The core problem: their reasoning operates only on observed pixels and text-based chain-of-thought, with no mechanism to visualize unobserved space or alternative viewpoints.
Prior attempts (StructLM, PIVOT) add 3D-aware pretraining or geometric modules, but they encode spatial knowledge in weights rather than through active visual exploration. They’re guessing at layouts rather than looking.
Problem: Spatial reasoning requires      Hypothesis: Models need to "see"
cross-view inference from limited  -->   imagined views, not just reason
egocentric observations                  over text descriptions

            |
            v
Method: RL policy + world simulator      Evidence: +9.0 pts on MMSI-Bench
generates action-conditioned       -->   vs base Qwen-VL; +4.4 pts improved
novel views during reasoning             simulator vs Gemini baseline

            |
            v
Conclusion: Imagination helps, but learning when/where to imagine matters more
The Increment
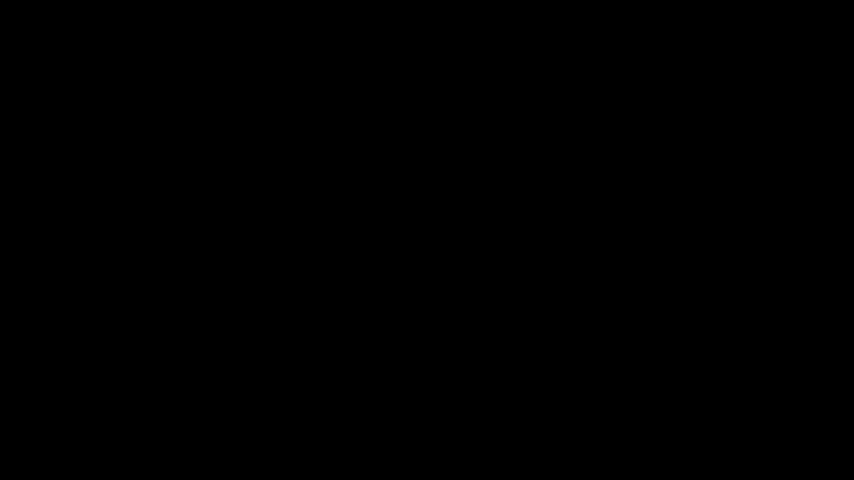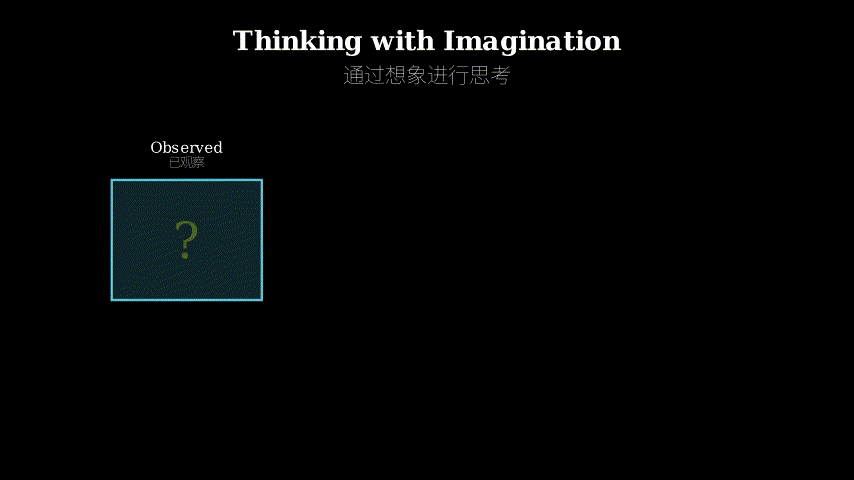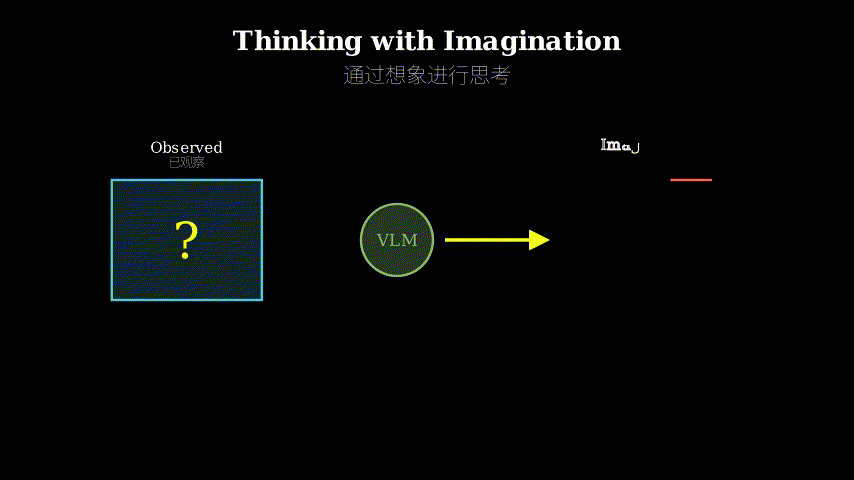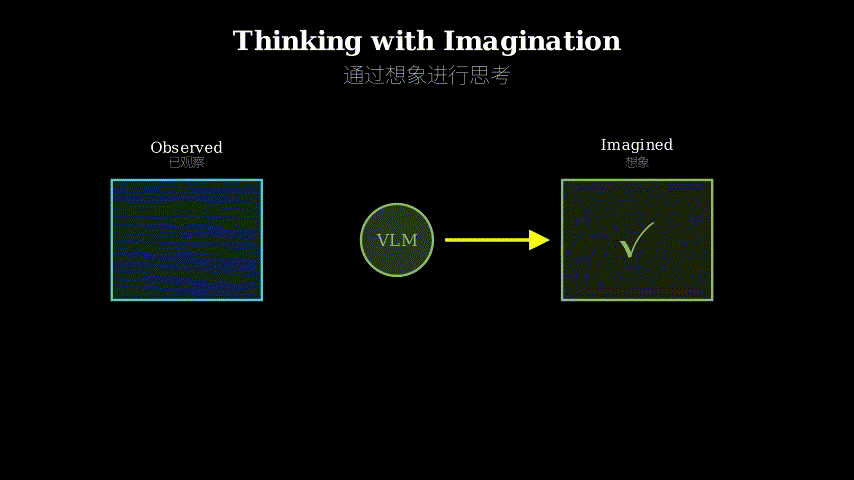
One sentence: Before — VLMs reason only from given views; after — VLMs actively request imagined viewpoints from a simulator during inference, like mentally rotating an object before answering.
Core Mechanism
Astra has two components trained separately then coupled at inference. Astra-WM is a world simulator built on Bagel (a video diffusion model). You feed it context images and a natural-language camera motion like “move forward 2 meters,” and it generates a photorealistic novel-view image. To ensure generated views are geometrically coherent, they train with view consistency tuning: the model must predict the same 3D structure from different synthesized angles, enforced via depth map alignment and optical flow matching losses.
Astra-VL is the policy—a VLM fine-tuned with RL to decide when to invoke the simulator. It gets a spatial reasoning question and initial observations. At each step, it can either answer directly or request an imagined view by specifying camera motion. The simulator returns the novel view, which gets appended to context. The policy repeats until it commits to an answer. The reward function is sparse (correct/incorrect final answer) plus penalties for unnecessary simulator calls.
Training happens in two curriculum phases. Phase 1: supervised warmup where the model learns to issue camera commands and incorporate simulated views into reasoning, with ground-truth actions from an oracle. Phase 2: RL exploration where the model discovers which questions benefit from imagination and which don’t. A key insight: they penalize simulator invocations that don’t improve answer quality, teaching the model to imagine only when direct reasoning fails.
User Question + Initial Views
        |
        v
   Astra-VL Policy
   /            \
  v              v
Answer        Request Camera Motion
Directly      (e.g., "rotate left 90 deg")
  |                   |
  |                   v
  |            Astra-WM Simulator
  |            (Bagel + Consistency Tuning)
  |                   |
  |                   v
  |            Novel View Image
  |                   |
  |                   v
  +----------> Append to Context
                      |
                      v
                 Loop Until
                Final Answer
Think of Astra as a detective with a mental holodeck. The detective (Astra-VL) gets a crime scene photo and a question about what’s behind a wall. Instead of guessing, the detective steps into the holodeck (Astra-WM) and says “show me the view if I walk around this corner.” The holodeck generates that view based on spatial consistency rules learned from thousands of real scenes. The detective examines the imagined view, decides if they need another angle, and eventually commits to a conclusion. Critically, the detective learned through trial and error when it’s worth entering the holodeck versus just reasoning from the original photo—because the holodeck isn’t free (costs inference time and sometimes hallucinates).
Key Concepts
-
Action-Conditioned Imagination: Instead of passively viewing fixed images, the model actively requests specific viewpoints by specifying camera transformations in natural language (“move 1 meter forward and tilt up 30 degrees”). The world model then generates that exact view. This is different from random view synthesis or fixed multi-view setups—the model explores the scene based on what information it needs to answer the question. Imagine trying to estimate room dimensions from a single photo: you’d want to peek around corners, not just see random angles. That peek is action-conditioned.
-
View Consistency Tuning: Generated novel views must be geometrically coherent with context images, meaning if you synthesize view A→B and B→C, the predicted 3D geometry should align transitively. Without this, the simulator might generate a door in one imagined view that contradicts where the wall was in the original image. The training uses two losses: depth consistency (projected depth maps from different views should agree on overlapping regions) and optical flow matching (pixel motion between views should follow epipolar geometry). Think of it as training the simulator to maintain a single coherent 3D mental model rather than generating independent hallucinated views.
-
World-Simulator-in-the-Loop RL: The policy doesn’t just learn spatial reasoning—it learns tool use. Standard RL would reward correct answers, but the model could exploit the simulator by calling it on every question, ballooning inference cost. The curriculum teaches restraint: Phase 1 uses imitation learning on oracle trajectories (questions where imagination provably helps), Phase 2 adds a cost term that penalizes simulator calls that don’t flip wrong answers to right. The model learns a meta-policy: “Is this question answerable from given views, or do I need to imagine?” Similar to a student learning not to check notes for every quiz question, only when stuck.
Framework Shift
Before (standard VLM reasoning):          After (Astra):

   Image → VLM → Text CoT → Answer          Image → Policy
                                                     |
                                              Need more views?
                                              /            \
                                            No             Yes
                                            |               |
                                        Answer      Camera Action
                                                           |
                                                    Simulator
                                                           |
                                                   Novel View → Policy
                                                                |
                                                             Loop

Fixed observation space                  Active visual exploration
Reasoning in text                        Reasoning through imagined percepts
One sentence: From passive inference on fixed views to active visual exploration where the model decides what to imagine.
Expert Assessment
Problem choice: Real gap, not manufactured. Spatial reasoning from limited egocentric views is a genuine frontier—humans do this constantly (imagining what’s behind us, mentally rotating objects), and it’s critical for embodied AI. The problem sits at the intersection of 3D vision and reasoning, an under-explored area compared to flat image understanding.
Method maturity: Clever but not over-engineered. Coupling a generative world model with RL policy is conceptually clean. The view consistency tuning is a smart engineering choice—without it, the simulator would be unreliable. However, one concern: the method assumes the simulator’s errors are benign. If the world model hallucinates confidently wrong geometry, the policy might make decisions based on false evidence. The paper doesn’t deeply explore failure modes of compounding imagination errors.
Experimental integrity: Baselines are fair—they compare against using no simulator (base VLM), using a weaker simulator (Gemini’s native view synthesis), and ablations of their own components. Numbers are modest but consistent: +9 points on MMSI-Bench, +6 on MindCube. The gains aren’t dramatic, suggesting the approach works but isn’t a silver bullet. One red flag: they don’t report how often the simulator is invoked per question or compute cost multiplier. If the model calls the simulator 10 times per query, deployment becomes impractical.
Writing quality: The core idea is well-motivated, but Section 3.2 (training details) compresses too much into dense paragraphs. The RL curriculum deserves clearer exposition—readers shouldn’t have to reverse-engineer why Phase 1 uses oracle actions. The ablation study (Table 3) is rushed; each component deserves a sentence explaining *why removing it hurts. Rewriting the method section with more breathing room and intuitive build-up would elevate the paper significantly.
Verdict: Weak accept — Novel idea with solid execution, but modest empirical gains and incomplete analysis of failure modes. This is a strong workshop paper or borderline conference acceptance, primarily for introducing the paradigm of world-simulator-augmented reasoning rather than definitive performance wins.
Takeaways
For practitioners: The two-phase RL curriculum is the stealable insight. If you’re training models to use tools (search engines, code interpreters, calculators), don’t just reward task success—penalize unnecessary tool calls. Phase 1 (imitation on oracle tool-use traces) + Phase 2 (RL with cost penalties) is a clean recipe for teaching when to use tools, not just how. This transfers beyond vision: a coding assistant that learns to call linters only when unsure, not reflexively.
For researchers: The view consistency tuning technique (depth + optical flow losses) is a practical way to improve any generative 3D model’s coherence without needing explicit 3D supervision. If you’re working on video generation, novel-view synthesis, or any task where outputs must respect geometric relationships, this dual-loss approach is worth trying.
Philosophical shift: This paper hints at a broader principle—reasoning systems benefit from closing the loop between inference and perception. Current LLMs “think” in language; Astra shows that for spatial problems, thinking in imagined percepts is more natural. The next version of this idea might apply to temporal reasoning (simulating future states), social reasoning (imagining others’ perspectives), or scientific reasoning (mentally running experiments). The pattern is: don’t just chain-of-thought your way through—simulate your way through.
论文: 2606.06476 作者: Chenming Zhu, Jingli Lin, Yilin Long, Peizhou Cao, Tai Wang, Jiangmiao Pang, Xihui Liu 分类: cs.CV
缺口
现有视觉语言模型(GPT-4V、Gemini、Qwen-VL)在画面边界内的视觉推理表现良好,但在需要想象视野外内容的空间推理上失败。
它们能描述”桌上有个杯子”,却难以回答”如果我绕桌子走一圈,从哪边能看到杯把?“核心问题:它们的推理仅基于观察到的像素和文本式思维链,没有机制可视化未观测空间或替代视角。
此前尝试(StructLM、PIVOT)添加 3D 感知预训练或几何模块,但它们把空间知识编码在权重里,而非通过主动视觉探索。
它们在猜布局,而非在看。
问题:空间推理需要从有限     假设:模型需要"看见"想象
的自我中心观测推断    -->    的视角,而非仅对文本
跨视角信息                   描述进行推理

            |
            v
方法:强化学习策略+世界      证据:相比基础 Qwen-VL
模拟器在推理过程中生成  -->  在 MMSI-Bench 上 +9.0 分;
动作条件的新视角             改进模拟器相比 Gemini 基线 +4.4 分

            |
            v
结论:想象有帮助,但学会何时何地想象更重要
增量
一句话:之前——视觉语言模型只从给定视角推理;之后——模型在推理过程中主动向模拟器请求想象的视角,就像在回答前心里旋转物体。
核心机制
Astra 有两个分别训练后在推理时耦合的组件。
Astra-WM 是基于 Bagel(视频扩散模型)构建的世界模拟器。
喂给它上下文图像和自然语言相机运动指令如”向前移动 2 米”,它生成逼真的新视角图像。
为确保生成视角几何连贯,采用视角一致性调优训练:模型必须从不同合成角度预测相同的 3D 结构,通过深度图对齐和光流匹配损失强制执行。
Astra-VL 是策略——用强化学习微调的视觉语言模型,决定何时调用模拟器。
它获得空间推理问题和初始观测。
每一步可以直接回答或通过指定相机运动请求想象视角。
模拟器返回新视角,追加到上下文。
策略重复直到提交答案。
奖励函数稀疏(最终答案正确/错误)加上不必要模拟器调用的惩罚。
训练分两个课程阶段。
阶段 1:监督预热,模型学习发出相机指令并将模拟视角纳入推理,使用来自预言机的真实动作。
阶段 2:强化学习探索,模型发现哪些问题受益于想象、哪些不需要。
关键洞察:惩罚不改善答案质量的模拟器调用,教模型仅在直接推理失败时想象。
用户问题 + 初始视角
        |
        v
   Astra-VL 策略
   /            \
  v              v
直接          请求相机运动
回答        (如"向左旋转 90 度")
  |                   |
  |                   v
  |            Astra-WM 模拟器
  |          (Bagel + 一致性调优)
  |                   |
  |                   v
  |              新视角图像
  |                   |
  |                   v
  +----------> 追加到上下文
                      |
                      v
                循环直到
                最终答案
把 Astra 想象成带着心理全息甲板的侦探。
侦探(Astra-VL)拿到犯罪现场照片和关于墙后有什么的问题。
侦探不猜,而是走进全息甲板(Astra-WM)说”给我看如果绕过这个角落的视角”。
全息甲板基于从数千真实场景学到的空间一致性规则生成该视角。
侦探检查想象的视角,决定是否需要另一个角度,最终提交结论。
关键是,侦探通过试错学会了何时值得进入全息甲板而非从原照片推理——因为全息甲板不免费(消耗推理时间且有时会产生幻觉)。
关键概念
- 动作条件想象:模型不是被动查看固定图像,而是通过用自然语言指定相机变换(“向前移动 1 米并向上倾斜 30 度”)主动请求特定视角。
世界模型随后生成那个确切视角。
这不同于随机视角合成或固定多视角设置——模型根据回答问题所需信息探索场景。
想象从单张照片估算房间尺寸:你会想偷看角落,而非只看随机角度。
那个偷看就是动作条件的。
- 视角一致性调优:生成的新视角必须与上下文图像几何连贯,意味着如果合成视角 A→B 和 B→C,预测的 3D 几何应传递对齐。
没有这个,模拟器可能在一个想象视角中生成门,与原图像中墙的位置矛盾。
训练使用两个损失:深度一致性(不同视角的投影深度图在重叠区域应一致)和光流匹配(视角间像素运动应遵循对极几何)。
可以理解为训练模拟器维护单一连贯的 3D 心理模型,而非生成独立的幻觉视角。
- 世界模拟器在环强化学习:策略不仅学习空间推理——它学习工具使用。
标准强化学习会奖励正确答案,但模型可能通过对每个问题调用模拟器来作弊,导致推理成本暴涨。
课程教约束:阶段 1 在预言机轨迹(想象可证明有帮助的问题)上使用模仿学习,阶段 2 添加成本项,惩罚不将错误答案翻转为正确的模拟器调用。
模型学习元策略:“这个问题从给定视角可回答,还是需要想象?“类似学生学会不是每道测验题都查笔记,只在卡住时查。
框架转变
之前(标准视觉语言模型推理):    之后(Astra):

   图像 → VLM → 文本 CoT → 答案      图像 → 策略
                                           |
                                      需要更多视角?
                                      /            \
                                    否              是
                                    |               |
                                  答案         相机动作
                                                   |
                                              模拟器
                                                   |
                                           新视角 → 策略
                                                    |
                                                  循环

固定观测空间                        主动视觉探索
文本推理                            通过想象感知推理
一句话:从对固定视角的被动推理到模型决定想象什么的主动视觉探索。
专家评审
选题眼光:真缺口,非人造。
从有限自我中心视角进行空间推理是真正的前沿——人类持续这样做(想象身后有什么、心里旋转物体),这对具身 AI 至关重要。
该问题位于 3D 视觉和推理的交叉点,相比平面图像理解探索不足。
方法成熟度:巧妙但不过度工程化。
将生成世界模型与强化学习策略耦合概念上清晰。
视角一致性调优是聪明的工程选择——没有它,模拟器会不可靠。
然而,一个担忧:该方法假设模拟器的错误是良性的。
如果世界模型自信地幻觉出错误几何,策略可能基于假证据做决策。
论文未深入探索复合想象错误的失败模式。
实验诚意:基线公平——与不用模拟器(基础视觉语言模型)、用较弱模拟器(Gemini 原生视角合成)及自身组件消融对比。
数字适度但一致:MMSI-Bench 上 +9 分,MindCube 上 +6 分。
增益不戏剧化,表明方法有效但非银弹。
一个警示:未报告每问题模拟器调用频率或计算成本倍数。
如果模型每次查询调用模拟器 10 次,部署变得不切实际。
写作功力:核心想法动机充分,但 3.2 节(训练细节)将太多内容压缩进密集段落。
强化学习课程值得更清晰阐述——读者不应需要逆向工程为何阶段 1 用预言机动作。
消融研究(表 3)仓促;每个组件值得一句话解释为何移除它会受伤。
用更多呼吸空间和直观构建重写方法部分会显著提升论文。
判决:弱接收——新颖想法配扎实执行,但实验增益适度且失败模式分析不完整。
这是强研讨会论文或临界会议接收,主要因引入世界模拟器增强推理范式而非决定性性能胜利。
要点总结
对实践者:两阶段强化学习课程是可偷的洞察。
如果训练模型使用工具(搜索引擎、代码解释器、计算器),不仅奖励任务成功——惩罚不必要的工具调用。
阶段 1(在预言机工具使用轨迹上模仿)+ 阶段 2(带成本惩罚的强化学习)是教何时使用工具而非仅如何使用的清晰配方。
这超越视觉迁移:学会仅在不确定时调用 linter 而非反射性调用的编码助手。
对研究者:视角一致性调优技术(深度 + 光流损失)是改进任何生成 3D 模型连贯性的实用方法,无需显式 3D 监督。
如果研究视频生成、新视角合成或任何输出必须尊重几何关系的任务,这个双损失方法值得尝试。
哲学转变:本文暗示更广泛原理——推理系统受益于闭合推理与感知间的循环。
当前大语言模型用语言”思考”;Astra 表明对空间问题,用想象感知思考更自然。
这个想法的下一版本可能应用于时间推理(模拟未来状态)、社会推理(想象他人视角)或科学推理(心里运行实验)。
模式是:不仅用思维链推理——用模拟推理。