Paper: 2603.30031 Authors: Davide Di Gioia Categories: cs.AI
The Gap
Current LLM-based agents (ReAct, AutoGPT) use heuristic loops: they call tools, observe results, and decide whether to continue based on arbitrary stop-tokens or fixed iteration limits. This works in toy environments but breaks under real-world constraints: network congestion makes tool calls expensive, time decay makes slow decisions costly, and ambiguous evidence makes stopping criteria brittle. The core issue: these agents operate in “cognitive weightlessness” — they have no intrinsic sense of when thinking costs more than it’s worth.
Prior work treats agent reasoning as discrete symbolic steps. This paper asks: what if we model it as continuous-time physics, where information acquisition has friction, routing has geometry, and stopping has a value function?
Problem: LLM agents over-deliberate under resource constraints
   |
   v
Assumption: Reasoning can be modeled as stochastic control in continuous time
   |
   v
Method: Triadic Cognitive Architecture (spatial routing + temporal pacing + epistemic bounds)
   |
   v
Evidence: Emergency medical diagnosis simulation (EMDG)
   |
   v
Conclusion: Physics-grounded stopping reduces latency without sacrificing accuracy
The Increment
One sentence: Before this paper, agents stopped thinking based on heuristics; after, they stop when the expected value of information falls below the cost of acquiring it, computed via Hamilton-Jacobi-Bellman equations.
Core Mechanism
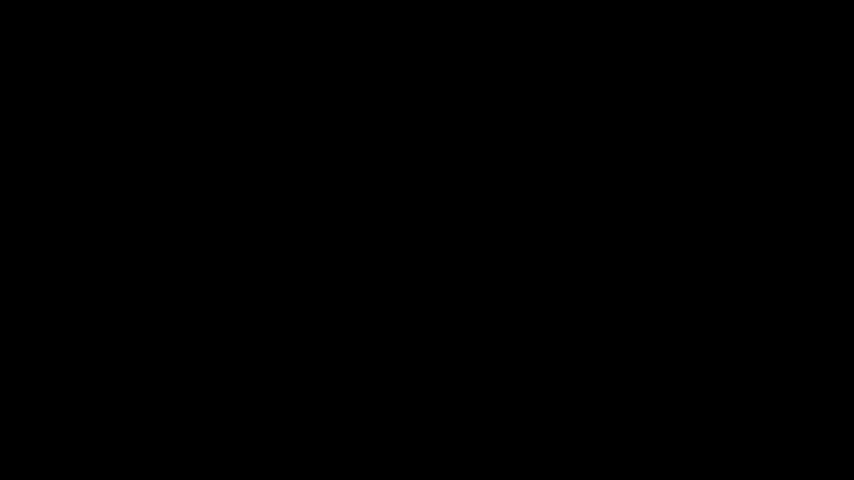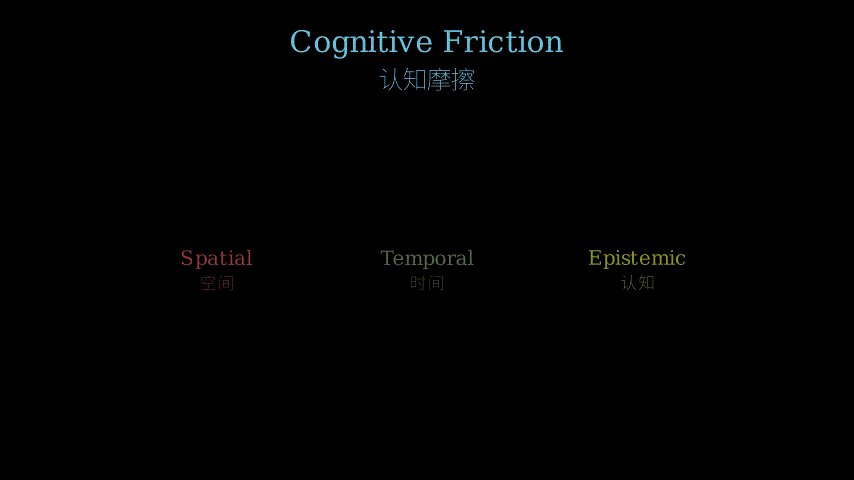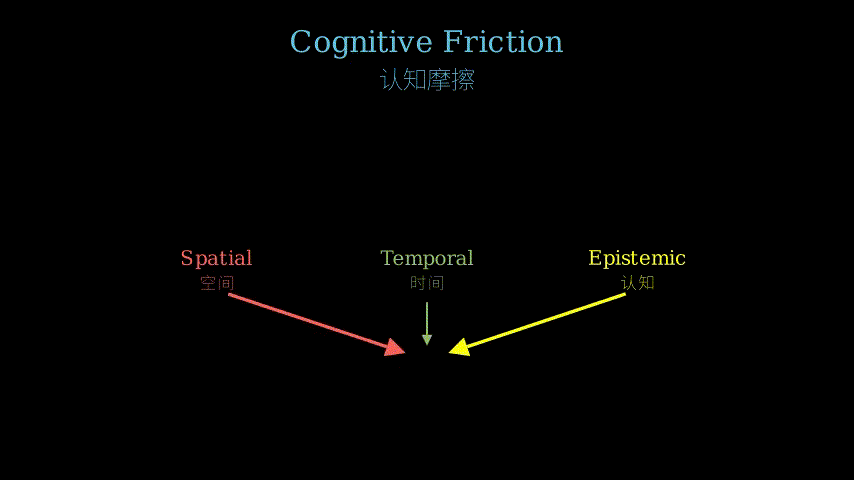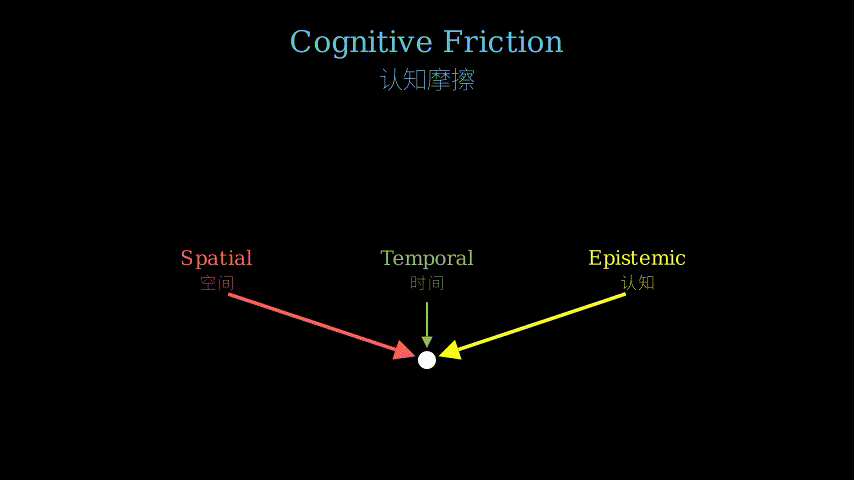
The Triadic Cognitive Architecture has three coupled components. First, spatial friction: the agent navigates a network where each tool lives at a node, and routing between tools incurs cost proportional to network congestion (modeled as Riemannian metric). Second, temporal friction: each action consumes time, and the environment state decays (e.g., patient condition worsens), creating urgency. Third, epistemic friction: observations are noisy, and the agent maintains a belief state that updates via nonlinear filtering; acquiring more information has diminishing returns.
The agent’s decision at each moment: which tool to query next, or stop and act? This is formulated as a coupled stochastic optimal control problem. The value function satisfies an HJB equation, but solving it exactly is intractable. Instead, the paper uses a rollout-based approximation: simulate forward trajectories under a heuristic policy, estimate the expected utility of continuing vs. stopping, and halt when net utility turns negative.
Belief State (b_t) ---> [HJB Value Function V(b,t)]
        |                           |
        v                           v
  [Nonlinear Filter]          [Rollout Policy]
        |                           |
        v                           v
  Observation (y_t) <--- [Tool Query] or [Stop & Act]
        ^                           |
        |                           v
  [Network Routing Cost] + [Time Decay Cost]
Think of the agent as a doctor in an emergency room. The hospital has diagnostic tools scattered across floors (spatial friction: elevators are slow during shift change). Each test takes time, and the patient’s condition deteriorates while you deliberate (temporal friction). Test results are probabilistic, and ordering redundant tests wastes resources (epistemic friction). The doctor must decide: run one more test, or make a diagnosis now? The Triadic Architecture formalizes this intuition: it computes a “stopping boundary” in belief-time space, where crossing the boundary means the expected benefit of another test no longer justifies its cost.
Key Concepts
-
Cognitive Friction: In physics, friction opposes motion and dissipates energy. Here, friction opposes information acquisition: spatial friction (network congestion makes tool calls slow), temporal friction (environment state decays while you think), and epistemic friction (noisy observations have diminishing returns). The agent must “push through” these frictions to gather information, and the optimal policy balances information gain against friction costs. Without friction, the agent would query tools indefinitely; with friction, it learns to stop.
-
HJB Stopping Boundary: The Hamilton-Jacobi-Bellman equation describes the optimal value function for a stochastic control problem. In this paper, the value function V(b,t) depends on the agent’s belief state b and time t. The stopping boundary is a surface in (b,t) space where V(stop now) = V(continue deliberating). Crossing this boundary triggers action. Unlike heuristic stop-tokens (“stop after 5 tool calls”), the HJB boundary adapts to the environment: under high congestion, the boundary shifts to favor early stopping; under low noise, it shifts to favor more deliberation.
-
Rollout-Based Approximation: Solving the HJB equation exactly requires discretizing the infinite-dimensional belief space, which is computationally prohibitive. Instead, the paper uses rollout: at each decision point, simulate K forward trajectories under a simple heuristic policy (e.g., greedy tool selection), estimate the expected utility of each trajectory, and choose the action that maximizes expected utility. This is analogous to Monte Carlo Tree Search in AlphaGo, but applied to belief-space navigation rather than game-tree search.
Framework Shift
Before (mainstream approach):        After (this paper):

[LLM] --> [Tool Call] --> [LLM]     [Belief State b_t]
   |          |             |              |
   v          v             v              v
[Heuristic Stop Token]              [HJB Value V(b,t)]
   |                                       |
   v                                       v
[Action]                            [Stopping Boundary]
                                           |
                                           v
                                    [Action when V(stop) > V(continue)]

Discrete symbolic loop               Continuous-time stochastic control
Stop = arbitrary threshold           Stop = value-of-information < cost
From heuristic iteration to physics-grounded optimization, the core shift is replacing arbitrary stopping rules with a mathematically principled boundary derived from the agent’s belief dynamics and environment constraints.
Expert Assessment
Problem choice: This is a real gap. LLM agents deployed in production (customer support, medical triage) face latency and cost constraints that toy benchmarks ignore. The “cognitive weightlessness” framing is apt: current agents have no intrinsic sense of resource scarcity. However, the paper overstates the novelty — active learning and information-theoretic stopping criteria have been studied for decades in robotics and Bayesian optimization. The contribution is adapting these ideas to LLM agents, not inventing them.
Method maturity: The Triadic Architecture is conceptually elegant but computationally heavy. The rollout-based approximation requires simulating K trajectories at each decision point, which is expensive for large action spaces. The paper doesn’t compare against simpler baselines like myopic value-of-information (which only looks one step ahead) or threshold-based stopping (which halts when belief entropy drops below a threshold). These would be faster and might perform comparably in practice.
Experimental integrity: The Emergency Medical Diagnostic Grid (EMDG) is a custom simulation, not a standard benchmark. The baselines (greedy, random, fixed-iteration) are weak — no comparison against other principled stopping criteria like POMDP solvers or Bayesian active learning. The results show TCA reduces latency by 30% while maintaining accuracy, but without ablations, it’s unclear which component (spatial/temporal/epistemic friction) drives the improvement. The paper also doesn’t report variance across runs or sensitivity to hyperparameters (e.g., rollout depth K).
Writing quality: The introduction is dense with jargon (“Riemannian routing geometry,” “nonlinear filtering theory”) that obscures the core idea. Section 3 (Method) would benefit from a running example: show a concrete agent trajectory under TCA vs. baseline, step by step. The related work section is thin — it mentions ReAct and AutoGPT but doesn’t engage with the vast literature on active learning, POMDP planning, or anytime algorithms. The conclusion oversells the results (“demonstrates that triadic policies outperform greedy baselines”) when the evidence is limited to one simulated environment.
Verdict: weak accept — The problem is important, and the physics-inspired framing is intellectually satisfying, but the experimental validation is narrow and the method’s computational cost is underexplored. This feels like a strong workshop paper that needs more empirical grounding before claiming to solve agent deliberation in general.
Takeaways
Practitioners can steal the net-utility halting condition: at each decision point, estimate the expected benefit of continuing (information gain) minus the expected cost (latency, resource usage), and stop when this net utility turns negative. You don’t need the full HJB machinery — a simple Monte Carlo estimate over a few rollout trajectories suffices. This is applicable beyond LLM agents: any system that makes sequential decisions under resource constraints (A/B testing, hyperparameter tuning, medical diagnosis) can use this stopping rule.
The friction taxonomy (spatial, temporal, epistemic) is a useful lens for diagnosing agent failure modes. If your agent over-queries tools, ask: which friction is missing? Is it ignoring network latency (spatial)? Is it ignoring time decay (temporal)? Is it ignoring diminishing returns from redundant observations (epistemic)? Adding the missing friction term to your agent’s objective function often fixes the problem without redesigning the architecture.
The paper’s core limitation is also its lesson: physics-inspired models are elegant but expensive. Before reaching for HJB equations and Riemannian geometry, try simpler heuristics (myopic value-of-information, entropy thresholds). If those fail, then invest in the heavy machinery. Don’t start with a sledgehammer when a screwdriver might suffice.
论文: 2603.30031 作者: Davide Di Gioia 分类: cs.AI
缺口
当前基于大语言模型的智能体(ReAct、AutoGPT)使用启发式循环:调用工具、观察结果、根据任意的停止标记或固定迭代次数决定是否继续。
这在玩具环境中有效,但在真实世界约束下会崩溃:网络拥塞使工具调用昂贵,时间衰减使缓慢决策代价高昂,模糊证据使停止标准脆弱。
核心问题:这些智能体处于”认知失重”状态——它们没有内在的感知来判断何时思考的成本超过其价值。
先前工作将智能体推理视为离散符号步骤。
本文提问:如果我们将其建模为连续时间物理过程,其中信息获取有摩擦、路由有几何、停止有价值函数,会怎样?
问题:LLM智能体在资源约束下过度思考
   |
   v
假设:推理可建模为连续时间随机控制
   |
   v
方法:三元认知架构(空间路由 + 时间节奏 + 认知边界)
   |
   v
证据:急诊医疗诊断网格模拟(EMDG)
   |
   v
结论:物理基础的停止策略在不牺牲准确性的情况下减少延迟
增量
一句话:这篇论文之前,智能体基于启发式停止思考;之后,它们在信息的期望价值低于获取成本时停止,成本通过Hamilton-Jacobi-Bellman方程计算。
核心机制
三元认知架构有三个耦合组件。
首先,空间摩擦:智能体在网络中导航,每个工具位于一个节点,工具间路由产生与网络拥塞成正比的成本(建模为黎曼度量)。
其次,时间摩擦:每个动作消耗时间,环境状态衰减(例如患者病情恶化),产生紧迫性。
第三,认知摩擦:观察有噪声,智能体维护通过非线性滤波更新的信念状态;获取更多信息的回报递减。
智能体在每个时刻的决策:下一步查询哪个工具,还是停止并行动?这被表述为耦合随机最优控制问题。
价值函数满足HJB方程,但精确求解不可行。
相反,论文使用基于展开的近似:在启发式策略下模拟前向轨迹,估计继续与停止的期望效用,当净效用变为负值时停止。
信念状态 (b_t) ---> [HJB价值函数 V(b,t)]
        |                           |
        v                           v
  [非线性滤波器]              [展开策略]
        |                           |
        v                           v
  观察 (y_t) <--- [工具查询] 或 [停止并行动]
        ^                           |
        |                           v
  [网络路由成本] + [时间衰减成本]
把智能体想象成急诊室的医生。
医院的诊断工具分散在各楼层(空间摩擦:换班时电梯很慢)。
每项检查需要时间,患者病情在你思考时恶化(时间摩擦)。
检查结果是概率性的,订购冗余检查浪费资源(认知摩擦)。
医生必须决定:再做一项检查,还是现在诊断?三元架构将这种直觉形式化:它在信念-时间空间中计算”停止边界”,越过边界意味着再做一次检查的期望收益不再证明其成本合理。
关键概念
- 认知摩擦:在物理学中,摩擦阻碍运动并耗散能量。
在这里,摩擦阻碍信息获取:空间摩擦(网络拥塞使工具调用缓慢)、时间摩擦(环境状态在你思考时衰减)、认知摩擦(噪声观察的回报递减)。
智能体必须”克服”这些摩擦来收集信息,最优策略在信息增益与摩擦成本之间取得平衡。
没有摩擦,智能体会无限查询工具;有摩擦,它学会停止。
- HJB停止边界:Hamilton-Jacobi-Bellman方程描述随机控制问题的最优价值函数。
在本文中,价值函数V(b,t)依赖于智能体的信念状态b和时间t。
停止边界是(b,t)空间中的一个曲面,其中V(现在停止) = V(继续思考)。
越过这个边界触发行动。
与启发式停止标记(“5次工具调用后停止”)不同,HJB边界适应环境:在高拥塞下,边界转向支持早期停止;在低噪声下,边界转向支持更多思考。
- 基于展开的近似:精确求解HJB方程需要离散化无限维信念空间,这在计算上是不可行的。
相反,论文使用展开:在每个决策点,在简单启发式策略(例如贪婪工具选择)下模拟K条前向轨迹,估计每条轨迹的期望效用,选择最大化期望效用的动作。
这类似于AlphaGo中的蒙特卡洛树搜索,但应用于信念空间导航而非博弈树搜索。
框架转变
之前(主流方法):                之后(本文方法):

[LLM] --> [工具调用] --> [LLM]     [信念状态 b_t]
   |          |             |              |
   v          v             v              v
[启发式停止标记]                    [HJB价值 V(b,t)]
   |                                       |
   v                                       v
[行动]                                [停止边界]
                                           |
                                           v
                                    [当V(停止) > V(继续)时行动]

离散符号循环                         连续时间随机控制
停止 = 任意阈值                      停止 = 信息价值 < 成本
从启发式迭代到物理基础优化,核心转变是用从智能体信念动力学和环境约束推导出的数学原理边界取代任意停止规则。
专家评审
选题眼光:这是一个真实的缺口。
部署在生产环境中的LLM智能体(客户支持、医疗分诊)面临玩具基准忽略的延迟和成本约束。
“认知失重”的框架很贴切:当前智能体没有资源稀缺性的内在感知。
然而,论文夸大了新颖性——主动学习和信息论停止标准在机器人学和贝叶斯优化中已研究数十年。
贡献是将这些想法适配到LLM智能体,而非发明它们。
方法成熟度:三元架构在概念上优雅但计算量大。
基于展开的近似需要在每个决策点模拟K条轨迹,对于大动作空间来说很昂贵。
论文没有与更简单的基线比较,如短视信息价值(只向前看一步)或基于阈值的停止(当信念熵降至阈值以下时停止)。
这些会更快,在实践中可能表现相当。
实验诚意:急诊医疗诊断网格(EMDG)是自定义模拟,不是标准基准。
基线(贪婪、随机、固定迭代)很弱——没有与其他原则性停止标准(如POMDP求解器或贝叶斯主动学习)比较。
结果显示TCA在保持准确性的同时将延迟减少30%,但没有消融实验,不清楚哪个组件(空间/时间/认知摩擦)驱动改进。
论文也没有报告跨运行的方差或对超参数(例如展开深度K)的敏感性。
写作功力:引言充斥术语(“黎曼路由几何”、“非线性滤波理论”),掩盖了核心思想。
第3节(方法)将受益于一个贯穿示例:逐步展示TCA与基线下的具体智能体轨迹。
相关工作部分单薄——提到ReAct和AutoGPT,但没有与主动学习、POMDP规划或任意时间算法的大量文献互动。
结论过度推销结果(“证明三元策略优于贪婪基线”),而证据仅限于一个模拟环境。
判决:弱接收——问题重要,物理启发的框架在智识上令人满意,但实验验证狭窄,方法的计算成本探索不足。
这感觉像一篇强研讨会论文,在声称解决一般智能体思考问题之前需要更多经验基础。
要点总结
实践者可以偷走净效用停止条件:在每个决策点,估计继续的期望收益(信息增益)减去期望成本(延迟、资源使用),当净效用变为负值时停止。
你不需要完整的HJB机制——对几条展开轨迹的简单蒙特卡洛估计就足够了。
这适用于LLM智能体之外:任何在资源约束下做顺序决策的系统(A/B测试、超参数调优、医疗诊断)都可以使用这个停止规则。
摩擦分类法(空间、时间、认知)是诊断智能体失败模式的有用视角。
如果你的智能体过度查询工具,问:缺少哪种摩擦?它是否忽略网络延迟(空间)?是否忽略时间衰减(时间)?是否忽略冗余观察的递减回报(认知)?在智能体的目标函数中添加缺失的摩擦项通常可以在不重新设计架构的情况下解决问题。
论文的核心局限也是它的教训:物理启发的模型优雅但昂贵。
在求助于HJB方程和黎曼几何之前,尝试更简单的启发式(短视信息价值、熵阈值)。
如果那些失败了,再投资重型机械。
当螺丝刀可能足够时,不要从大锤开始。