Paper: 2608.06361 Authors: Sarvesh Baskar, Zikui Cai, Shayan Shabihi, Anirudh Satheesh, Muhammad R. Islam, Udari Madhushani Sehwag, Tom Goldstein, Furong Huang Categories: cs.AI
The Gap
Video benchmarks come in two flavors, and both leave the same hole.
Real-world suites (Video-MME, TempCompass, EgoSchema and friends) give you authentic clips and broad coverage, but every clip is a fixed bundle: the number of events, how fast they come, how long the video runs, and how cluttered the scene is all move together. When a model fails, you cannot say whether it failed because there were fourteen events, because they arrived at 3 Hz, because the video was two minutes long, or because the background was busy. The independent variables are welded together.
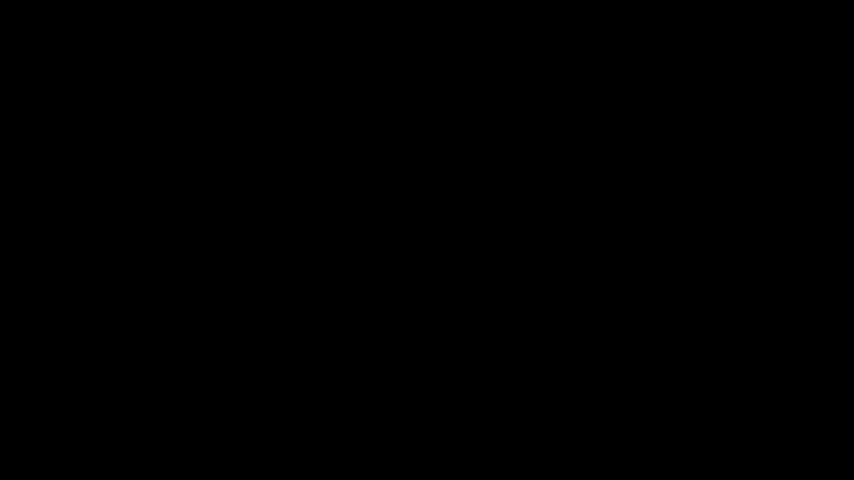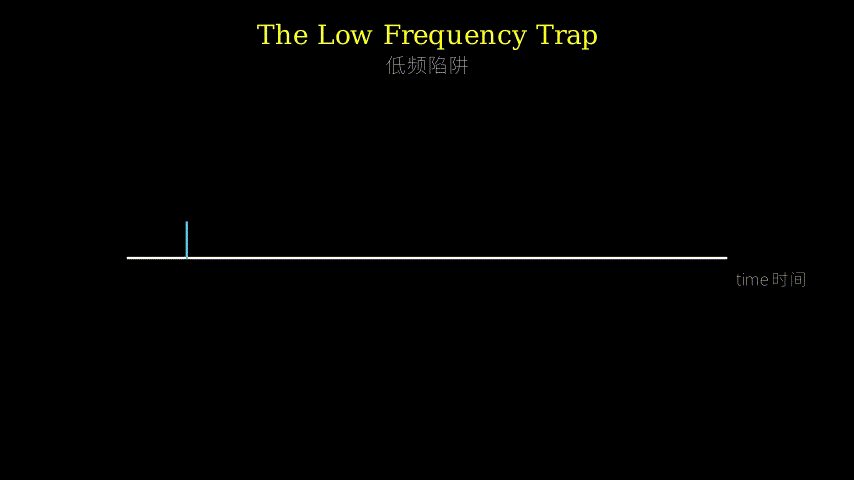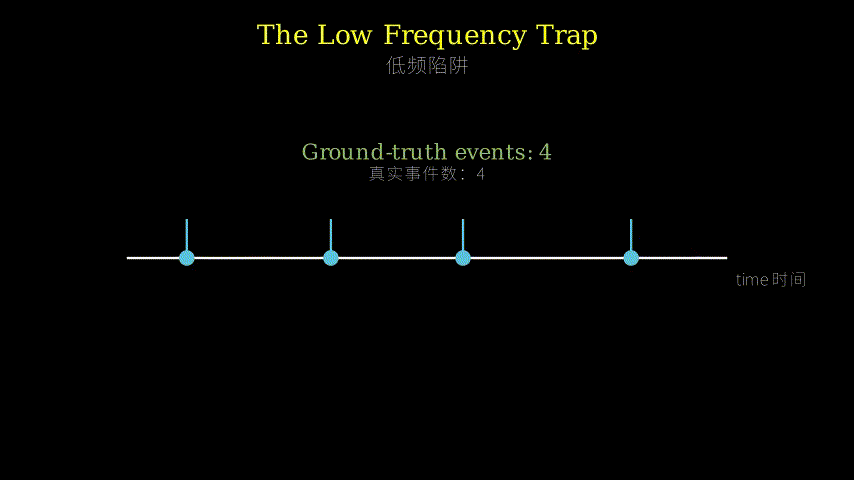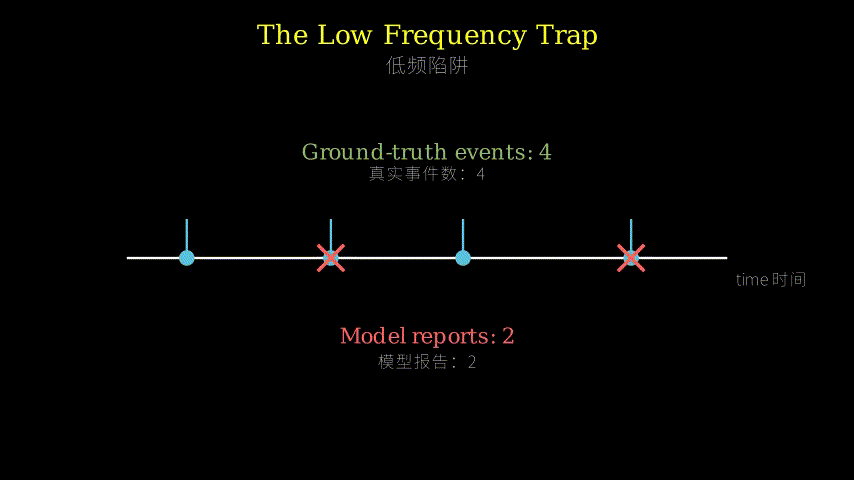
Programmatic and synthetic benchmarks (CLEVRER-style causal video QA, procedurally generated temporal tasks) fix the control problem — you can dial one knob at a time. But they inherit the grading convention of QA benchmarks: they check the final answer. If the model says “9 bounces” and the truth is 9, it scores 1.0, whether it saw the right nine bounces, hallucinated four while missing four, or guessed the modal answer. A count is a scalar, and scalars are the easiest thing in the world to get right for the wrong reasons. Compensating errors — one miss cancelling one double-count — are invisible to exact-match accuracy.
So the gap is specifically this: nobody was auditing the itemization. This paper’s move is to make the generator emit, alongside each video, an executable event trace with timestamps, so that the model’s reported events can be lined up against ground truth event by event.
   [PROBLEM]
   Video evals cannot localize temporal failure
      |
      +-- real clips: N, rate F, duration, clutter all entangled
      +-- synthetic clips: controlled, but graded on the final scalar only
      |
      v
   [ASSUMPTION]
   If you own the renderer, you own the ground-truth ledger.
   So: hold rendering fixed, sweep only (N, F), and keep the trace.
      |
      v
   [METHOD]
   Trace-grounded parametric profiling
      +-- 3 tasks: bounce contacts / blinks / state transitions
      +-- 2,190 videos on an (N x F) grid
      +-- 2 scores per video: final count  AND  timestamp-level recall
      |
      v
   [EVIDENCE]
   * capability surface: state transitions OK to N=12 at 0.5-1.0 Hz
   * transient blinks: no reliable region at all, anywhere
   * high N, high F: 0.2% counts correct, 18.1% events recovered
   * 2x frames: 19.6% -> 29.3% accuracy, but 3.7% sequence agreement
      |
      v
   [CONCLUSION]
   Failure is staged, not gradual. Event *representation* gates access;
   count and frequency then compound. And accuracy can rise while
   faithfulness does not -- so accuracy alone is a misleading metric.
The Increment
One sentence: Before, a video model that reported the right number of events was scored as having counted correctly; after, you can show it got the number right while recovering fewer than one in five of the actual events — and you can name the exact (count, frequency, event-type) region where it stops working.
Core Mechanism
The machinery is deliberately unglamorous. A parametric generator renders three families of videos. In bounce, a ball travels and makes wall contacts; the event is an impulse — an instant with no aftermath. In blink, an element turns on and off; the event is transient, present for a short window and then gone without trace. In state transition, an object changes category and stays changed; the event leaves a standing residue that any later frame still testifies to. Two knobs are swept: N, the number of events, and F, the frequency at which they occur. Everything else — resolution, palette, geometry, motion style — is pinned, so the only thing varying between two cells of the grid is event count and event rate. That yields 2,190 videos on an (N x F) lattice.
The second half is the actual contribution. Because the generator scripted the events, it can emit them as an executable trace: a list of (event, timestamp) pairs that is ground truth by construction rather than by annotation. The model is asked not just for a total but for the events it saw, and each report is scored twice. The scalar score is the old exact-count accuracy. The trace score aligns reported timestamps against the true trace within a tolerance and reports recall, precision, and whether the whole reported sequence agrees with the ledger. Sweeping this over the grid produces a capability surface: for each event type, the contour in (N, F) space inside which the model clears an 80% reliability bar.
What falls out is a staged picture rather than a smooth decay. Persistent state transitions are handled cleanly out to twelve events at 0.5 and 1.0 Hz. Transient blinks have no reliable positive-count region anywhere on the grid — the model never gets a foothold, regardless of how few events there are. In the high-N high-F corner, 0.2% of totals are correct and 18.1% of true events are recovered. Then the diagnostic pays off: doubling the frame budget lifts bounce accuracy from 19.6% to 29.3%, which looks like progress until you check the ledger and find that the reported sequence matches ground truth only 3.7% of the time. The extra frames bought better guesses, not better bookkeeping.
  PARAMETRIC GENERATOR (rendering held fixed)
  +--------------------------------------------------+
  |  sweep N = event count     sweep F = event rate  |
  |  task = bounce | blink | state-transition        |
  +--------------------------------------------------+
        |                                  |
        v                                  v
   [ VIDEO FRAMES ]                 [ EVENT TRACE ]
        |                            (e_1, t_1)
        |                            (e_2, t_2)  ... executable
        v                                  |
   [ VLM + prompt ]                        |
        |                                  |
        v                                  |
   report: total = k                       |
           events = (e', t'), ...          |
        |                                  |
        +---------------+------------------+
                        |
             +----------+-----------+
             |                      |
             v                      v
      [ SCALAR SCORE ]      [ TRACE ALIGNMENT ]
      exact count match     match t' to t within tol
      (the old metric)      -> recall / precision
             |              -> sequence agreement
             +----------+-----------+
                        v
              [ CAPABILITY SURFACE ]
        F ^  . . . x x x        F ^  x x x x x x
          |  . . . x x x          |  x x x x x x
          |  o o o o o o          |  x x x x x x
          |  o o o o o o          |  x x x x x x
          +--------------> N      +--------------> N
          state transitions        transient blinks
        o = >= 80% reliable   x = below   . = mixed
The metaphor: this is a forensic audit, and the auditors wrote the company’s books themselves.
Normally when you audit an accountant you compare their reported total against your own total. If both say 4,000 turns out to have missed three payments and invented three others — the bottom line reconciles, the ledger does not. That is exactly the 0.2%-correct-but-18.1%-recall situation, and exactly why 29.3% accuracy with 3.7% sequence agreement should worry you: a bookkeeper whose totals improved while their line items stayed wrong got luckier, not better.
The three event types are three kinds of transaction. A state transition is a permanent change to an account balance: even if you only glance at the books once a month, the new balance is sitting there, so you can reconstruct that something happened. A blink is a same-day deposit-and-withdrawal that nets to zero — unless you happen to open the ledger during those few hours, the event leaves no trace in any snapshot. A bounce is a single instantaneous transfer, somewhere in between. This is why the failure is staged rather than gradual: whether the auditor can see anything at all is decided by transaction type before volume even matters, and only then does volume (N) and velocity (F) grind down whatever accuracy remained.
The (N, F) sweep is auditing companies of increasing transaction volume and velocity to find the largest books this accountant can still be trusted with. The 80% contour is where you draw the line on the engagement letter. And raising the frame budget is sampling more days out of the month: it raises the odds your total comes out right, without making you any better at knowing which transactions actually happened.
Key Concepts
-
Trace-grounded evaluation: Most benchmarks grade a compressed answer — a number, a letter, a yes/no. Compression destroys evidence about *how the answer was produced. Suppose you ask someone to count the cars that pass a window in a minute and they say “seven.” Right or wrong, you learn almost nothing. Now ask them to write down the time of each car. If the truth was 7 cars at seconds 3, 11, 19, 28, 40, 47, 55 and they wrote 7 cars at seconds 5, 12, 20, 21, 22, 48, 56, you can see that they hallucinated a cluster around second 21 and missed the one at 40 — and that their “correct” total was two errors cancelling. Trace grounding is just: make the ground truth itemized and executable, and require the model’s answer to be itemized too, so cancellation cannot hide.
-
Capability surface and the reliability threshold: A single benchmark number says “this model is 62% good at video counting,” which is a statement about the benchmark’s difficulty mix, not about the model. Instead, put the two things that actually make the task hard on two axes — how many events (N) and how fast (F) — run the model at every cell, and shade the region where it clears some bar you’d actually accept in production, here 80%. What you get is shaped like a flight envelope: an operating region with a boundary. “Reliable up to 12 events at 1 Hz, unreliable above” is a usable engineering fact. “62%” is not.
-
Persistent vs transient events (and why representation gates access): A frame-sampled model does not watch video; it looks at a handful of stills. That makes some events structurally recoverable and others structurally invisible. If a traffic light changes from red to green and stays green, any later still tells you the change happened — the event is written into the state. If the light flickers green for 200 ms and returns to red, no still outside that 200 ms window contains any evidence at all; you would need to have sampled inside the flicker. This is the paper’s sharpest point: before you talk about temporal reasoning ability, ask whether the evidence is even in the frames the model received. Transient events at frequency F sampled at rate R are simply gone when R is too low, no matter how good the reasoning is — and the paper’s finding that blinks have *no reliable region anywhere is consistent with that being a hard access failure, not a reasoning failure.
Framework Shift
Before (mainstream approach):          After (this paper):

  fixed real clip                        parametric generator
  +-------------------+                  +-------------------+
  | N, F, duration,   |                  |  sweep N  x  F    |
  | clutter: entangled|                  |  render: FIXED    |
  +-------------------+                  +-------------------+
          |                                   |          |
          v                                v          v
      [ model ]                        [ frames ]  [ trace ]
          |                                   |          |
          v                                v          |
     answer = k                        report = k, (t'..)|
          |                                   |          |
          v                                +----+-----+
     k == truth ?                                  |
          |                                +-------+-------+
          v                                |               |
     ACCURACY: 62%                         v               v
     (one scalar,                    count match     line-item
      no localization)                                tie-out
                                           |               |
                                           +-------+-------+
                                                   v
                                       F ^ o o o x x x
                                         | o o x x x x
                                         +------------> N
                                       envelope + faithfulness
From one aggregate number to an operating envelope with an audit trail, the core shift is that evaluation stops asking how good is this model and starts asking where exactly does it break, and is it right for the right reasons.
Expert Assessment
Problem choice: Real gap, and a well-chosen one. The “correct answer, wrong reasoning” problem is widely acknowledged in text (chain-of-thought faithfulness, process reward models) but has barely been operationalized for video, where the compressed-answer convention is even more entrenched. Counting is the ideal wedge: it is the simplest possible temporal aggregation, so failure here is genuinely damning, and it happens to be the one task where the ground truth is naturally itemizable. The framing also lands on something the field keeps stumbling over — that frame sampling silently defines what is knowable — and gives it a measurement apparatus instead of a hand-wave. This sits squarely in the diagnostic-benchmark turn (BIG-Bench Hard to targeted probes, aggregate leaderboards to capability surfaces), which is where video eval was overdue to go.
Method maturity: Clever in framing, light in machinery. There is no new model, no new algorithm — it is a generator, a sweep, and an alignment scorer. That is fine; the insight is that owning the generator gets you a free ledger, and the value is in having actually built it and run the grid. But it *is thin, and the thinness shows in one place: the timestamp alignment tolerance is a hyperparameter that directly manufactures the headline numbers. If “3.7% sequence agreement” is sensitive to whether tolerance is 0.2 s or 1.0 s, that number is soft, and I would want the sensitivity curve, not a footnote. A simpler alternative the paper seems to skip: multiset agreement on event identities without timestamps, which is tolerance-free and would still expose compensating errors. Reporting both would make the claim much harder to argue with.
Experimental integrity: The internal comparisons are clean — rendering held fixed is the right control, and the accuracy-up-faithfulness-flat result is the kind of finding that only shows up if you were not fishing for it. Two red flags. First, the headline rests on a single model (Gemini 3.6 Flash, a cheap fast-tier model); the abstract mentions prompting variants and real-world checks but not a spread of models, and “fast-tier model is bad at dense temporal detail” is a much weaker claim than “video LMs fail.” Second, and more serious: there is no oracle or information-availability baseline. If the model receives K frames and the video contains N events at frequency F, there is a hard ceiling on what any system could recover, and for the high-N high-F corner that ceiling may be near the observed performance. Without computing it — or running a trivial frame-differencing CV pipeline on the same sampled frames — you cannot separate “did not reason” from “was never shown.” The paper gestures at this by raising the sampling rate, which is the right instinct, but a measured ceiling would convert a suggestive result into a proof. The 18.1% recall figure in particular is uninterpretable until I know the ceiling at that grid cell.
Writing quality: The abstract is doing heavy nominalization work — “trace-grounded parametric profiling for capability-surface estimation” is four abstractions stacked on an idea a smart reader gets in one sentence (“we ship the answer key with timestamps”). That kind of naming tends to signal padding out a light contribution. “Staged temporal failure” is the one coinage that earns its keep. The section I would rewrite is whatever handles sampling: it needs an explicit information-availability analysis with a Nyquist-style argument for the transient tasks and an oracle bound per grid cell. Done well, that single addition upgrades the paper from “models do badly on our probe” to “here is the boundary between what is unknowable given frame budget and what is a genuine reasoning failure” — which is a substantially more citable result and probably the real paper hiding inside this one.
Verdict: weak accept — the trace-grounded audit and the accuracy-rises-while-faithfulness-does-not result are genuinely useful and will change how people report counting evals, but the single-model evidence base and the missing information-theoretic ceiling leave the headline claims less pinned down than the framing implies.
Takeaways
Things you can lift directly:
Never report exact-match accuracy on an aggregation task alone. Any metric that grades a scalar derived from many sub-decisions can be satisfied by compensating errors. Add a set-level or sequence-level agreement metric next to it. This transfers immediately to counting, tallying, deduplication, log summarization, “how many times did X occur in this document,” financial extraction — anywhere the answer is a reduction over items. The specific diagnostic signature to watch for: accuracy improves, item-level agreement does not. That means you bought better guessing.
When you build a synthetic eval, make the generator emit the answer key in itemized, executable form. It costs nearly nothing at generation time and is impossible to retrofit later. The general pattern: build the eval so that ground truth is a *program trace, not a label. Then any intermediate claim the model makes is checkable.
Separate event representation from event count in your own task analysis. Before blaming a model’s reasoning, classify your events: does each one leave a persisting residue in state, or does it vanish? Persisting events are recoverable from sparse snapshots; transient events require sampling inside their window. If your production task involves transient events, the fix is not a better prompt or a bigger model — it is sampling policy, and you should compute the sampling rate your event frequency demands before anything else. The blink-versus-state-transition result says this distinction dominates everything downstream.
Replace single-number evals with a two-axis reliability envelope. Pick the two parameters that actually drive difficulty in your domain, sweep them, and shade where the system clears the bar you would actually ship at. “Reliable to 12 events at 1 Hz” is something you can design a system around; “62% on the benchmark” is not. This is cheap to do and disproportionately useful for capability-based routing and for deciding when to hand a subtask to code instead of a model.
Architectural implication: if your application needs event bookkeeping, do not ask a video LM for a total. Have it detect within short windows where evidence is dense, and aggregate in code. The paper is essentially a measurement of why the monolithic-count approach fails, and the failure is not the kind that scales away with prompting.
论文: 2608.06361 作者: Sarvesh Baskar, Zikui Cai, Shayan Shabihi, Anirudh Satheesh, Muhammad R. Islam, Udari Madhushani Sehwag, Tom Goldstein, Furong Huang 分类: cs.AI
缺口
视频评测目前分两派,两派漏的是同一个洞。
真实视频评测集(Video-MME、TempCompass、EgoSchema 这一类)片源真实、覆盖面广,但每段片子都是一个焊死的整体:事件有几个、来得多快、视频多长、画面多乱,全都绑在一起动。
模型答错了,你说不出它是被十四个事件卡住的、被 3 Hz 的节奏卡住的、被两分钟的时长卡住的,还是被杂乱背景卡住的。自变量互相纠缠,归因无从下手。
程序化生成的评测集(CLEVRER 那一类因果视频问答、按规则生成的时序任务)解决了控制变量的问题——你可以一次只拧一个旋钮。
但它们继承了问答评测的打分习惯:只看最终答案。模型说”9 次弹跳”、真值是 9,就得 1.0 分。不管它看见的是不是那 9 次,不管它有没有漏了四次同时又编了四次,也不管它是不是直接猜了个众数。
计数是个标量,而标量是这世上最容易”因为错误的理由而正确”的东西。一次漏检抵掉一次重复计数——这种相互抵消的错误,在精确匹配的准确率里完全隐形。
所以缺口很具体:没人在审”明细”。这篇论文的动作就是让生成器在输出视频的同时,输出一份带时间戳的可执行事件轨迹,于是模型报告的每一个事件都能和真值逐条对账。
   [问题]
   视频评测无法定位时序失败点
      |
      +-- 真实片源: N / 频率 F / 时长 / 杂乱度 全部纠缠
      +-- 合成片源: 变量可控, 但只给最终标量打分
      |
      v
   [假设]
   谁掌握渲染器, 谁就掌握真值总账。
   于是: 渲染固定, 只扫 (N, F), 并保留轨迹
      |
      v
   [方法]
   trace-grounded 参数化剖析
      +-- 3 类任务: 弹球触壁 / 闪烁 / 状态跃迁
      +-- (N x F) 网格上 2,190 段视频
      +-- 每段视频两个分数: 最终计数 + 时间戳级召回
      |
      v
   [证据]
   * 能力曲面: 状态跃迁在 0.5-1.0 Hz 下可到 N=12
   * 瞬态闪烁: 全网格找不到任何可靠区域
   * 高 N 高 F: 计数正确率 0.2%, 事件召回 18.1%
   * 加倍采样: 19.6% -> 29.3%, 但序列一致率仅 3.7%
      |
      v
   [结论]
   失败是分阶段的, 不是渐变的。事件的"表征形式"先决定
   证据能否被访问, 之后数量与频率才叠加恶化。
   而准确率能涨、忠实度不涨 -- 所以只看准确率会骗人。
增量
一句话: 以前,一个报出正确事件数的视频模型就算”数对了”;现在你能证明它数字报对、真实事件却只找回不到五分之一,并且能精确点出它在(数量、频率、事件类型)空间的哪一块彻底失灵。
核心机制
装置本身故意做得毫不华丽。一个参数化生成器渲染三类视频。
弹球里,球运动并撞墙,事件是一个脉冲——发生在一瞬,之后什么都不留。闪烁里,某个元素亮起再灭掉,事件是瞬态的,只在一小段窗口内存在,过后无迹可寻。状态跃迁里,物体改变类别并保持改变,事件留下了一个常驻残留——之后任何一帧都还在替它作证。
被扫的旋钮只有两个:N(事件数)和 F(事件频率)。其余一切——分辨率、配色、几何、运动风格——全部钉死,于是网格上任意两格之间唯一变化的就是事件数量和速率。这样得到 (N x F) 格点上的 2,190 段视频。
第二部分才是真正的贡献。因为事件是生成器编排的,它可以把事件导出成一份可执行轨迹:一串(事件,时间戳)二元组,其真值性来自构造本身,而不是来自人工标注。
模型被要求不只给出总数,还要给出它看见的每个事件;每份报告被打两次分。标量分就是旧的精确计数准确率。轨迹分把报告的时间戳在某个容差内和真值轨迹做对齐,报出召回、精确率,以及整条报告序列是否与总账一致。把这套东西在网格上扫一遍,得到一张能力曲面:对每种事件类型,画出在 (N, F) 空间中模型跨过 80% 可靠性门槛的等值线内区域。
跑出来的是分段图景,不是平滑衰减。持久性状态跃迁在 0.5 和 1.0 Hz 下干净地做到 12 个事件。瞬态闪烁在整张网格上没有任何可靠的正计数区域——不管事件有多少,模型从头到尾没能站住脚。在高 N 高 F 那个角上,0.2% 的总数正确,18.1% 的真实事件被找回。
然后诊断价值兑现了:把帧预算加倍,弹球准确率从 19.6% 升到 29.3%,看着像进步;可一查总账,报告序列与真值一致的比例只有 3.7%。多给的帧买来的是更好的猜,不是更好的记账。
  参数化生成器 (渲染固定)
  +--------------------------------------------------+
  |  扫 N = 事件数        扫 F = 事件频率            |
  |  任务 = 弹球 | 闪烁 | 状态跃迁                   |
  +--------------------------------------------------+
        |                                  |
        v                                  v
   [ 视频帧 ]                       [ 事件轨迹 ]
        |                            (e_1, t_1)
        |                            (e_2, t_2)  ... 可执行
        v                                  |
   [ 视频语言模型 + prompt ]               |
        |                                  |
        v                                  |
   报告: 总数 = k                          |
         事件 = (e', t'), ...              |
        |                                  |
        +---------------+------------------+
                        |
             +----------+-----------+
             |                      |
             v                      v
      [ 标量打分 ]           [ 轨迹对齐 ]
      总数精确匹配            t' 与 t 容差内匹配
      (旧指标)               -> 召回 / 精确率
             |               -> 序列一致性
             +----------+-----------+
                        v
                 [ 能力曲面 ]
        F ^  . . . x x x        F ^  x x x x x x
          |  . . . x x x          |  x x x x x x
          |  o o o o o o          |  x x x x x x
          |  o o o o o o          |  x x x x x x
          +--------------> N      +--------------> N
             状态跃迁                  瞬态闪烁
        o = 达到 80% 可靠   x = 未达   . = 混合
核喻:这是一次法务审计,而审计师自己就是那家公司的记账人。
平常你审一个会计,是拿他报的总数和你自己算的总数比。两边都是 4000 块,你就放过去了。这里的巧劲在于研究者就是那家公司:每一笔交易都是他们自己编排的,所以他们手里握着一本每行都带时间戳的总账。现在可以逐行对账了。
结果这个报出 4000 块的会计,其实漏记了三笔付款、又凭空编了三笔——底线对上了,明细没对上。这正是”0.2% 正确、18.1% 召回”那个局面,也正是”29.3% 准确率配 3.7% 序列一致率”应该让你警觉的原因:一个总数变准、分录照错的记账员,是运气变好了,不是本事变好了。
三类事件就是三种交易。状态跃迁是账户余额的永久变动:哪怕你一个月只翻一次账本,新余额就摆在那儿,你能反推出发生过什么。
闪烁是当天存进又当天取出、净额为零的一笔——除非你恰好在那几个小时里打开账本,这笔交易在任何一张快照里都不留痕迹。
弹球是一次瞬时划转,介于两者之间。
这就是为什么失败是分阶段的而非渐变的:审计师能不能看见任何东西,在交易量还没上场之前,就已经被交易类型判定了;之后才轮到交易量(N)和交易速度(F)来磨掉剩下那点准确率。
而 (N, F) 扫描,就是去审规模和流速递增的一系列公司,找出这个会计还能被信任的最大账本。80% 等值线就是你在业务委托书上该划的那条线。
至于提高帧预算,等于多抽查几天的账目:它提高了你总数碰对的概率,却完全没让你更清楚到底发生过哪几笔交易。
关键概念
-
轨迹接地的评测(trace-grounded evaluation): 大多数评测打分打的是一个被压缩过的答案——一个数、一个选项、一个是非。压缩会销毁”答案是怎么来的”这部分证据。
假设你让人数一分钟内窗外过了几辆车,他说”七辆”。对或错,你几乎学不到东西。
现在让他把每辆车经过的时刻也写下来。如果真值是 7 辆车分别在第 3、11、19、28、40、47、55 秒,而他写的是 7 辆车在第 5、12、20、21、22、48、56 秒,你就能看出他在第 21 秒附近幻觉出了一簇、漏掉了第 40 秒那一辆——他那个”正确”的总数是两个错误相互抵消的产物。
轨迹接地就是一句话:把真值做成明细化、可执行的,并要求模型的回答也明细化,让抵消无处藏身。
-
能力曲面与可靠性门槛: 单个评测数字说的是”这个模型在视频计数上有 62% 的水平”,那其实是关于评测集难度配比的陈述,不是关于模型的陈述。
换个做法:把真正让任务变难的两件事放到两根轴上——事件多少(N)和多快(F)——在每一格上跑模型,把它跨过你在生产里真能接受的那条线(这里是 80%)的区域涂上色。
你得到的东西形状像飞行包线:一个有明确边界的可用区。“1 Hz 下 12 个事件以内可靠,再往上不可靠”是一条能拿来做工程决策的事实。“62%“不是。
-
持久事件 vs 瞬态事件(以及表征为何决定”能否访问”): 一个按帧采样的模型并不在”看视频”,它在看少数几张静止图。这让某些事件在结构上可还原,另一些在结构上不可见。
如果红灯变绿并一直是绿的,之后任何一张静止图都告诉你这个变化发生了——事件被写进了状态里。
如果灯只闪了 200 毫秒绿又回到红,那 200 毫秒窗口之外的任何一张图都不含任何证据;你必须恰好采样在闪烁内部。
这是本文最锋利的一点:在谈时序推理能力之前,先问证据到底有没有进到模型收到的那些帧里。频率为 F 的瞬态事件在采样率 R 过低时就是没了,推理再强也无济于事——而”闪烁在任何地方都没有可靠区域”这个发现,与”这是一次硬性的访问失败、而非推理失败”是一致的。
框架转变
之前 (主流方法):                    之后 (本文方法):

  固定的真实片段                      参数化生成器
  +-------------------+               +-------------------+
  | N / F / 时长 /    |               |   扫 N  x  F      |
  | 杂乱度: 全部纠缠  |               |   渲染: 固定      |
  +-------------------+               +-------------------+
          |                                |          |
          v                             v          v
       [ 模型 ]                      [ 帧 ]     [ 轨迹 ]
          |                                |          |
          v                             v          |
      答案 = k                     报告 = k, (t'..) |
          |                                |          |
          v                             +----+-----+
      k == 真值 ?                               |
          |                             +-------+-------+
          v                             |               |
    准确率: 62%                          v               v
    (一个标量,                     总数匹配        逐条对账
     无法定位)                            |               |
                                          +-------+-------+
                                                  v
                                      F ^ o o o x x x
                                        | o o x x x x
                                        +------------> N
                                      可用包线 + 忠实度
一句话:从一个聚合数字到一张带审计轨迹的可用包线,核心转变是评测不再问”这模型有多好”,而开始问”它究竟在哪里崩、以及它是不是因为对的理由而对的”。
专家评审
选题眼光: 真缺口,而且选得好。“答案对、过程错”这个问题在文本领域已经被广泛承认(思维链忠实度、过程奖励模型),但在视频领域几乎没有被操作化过,而视频恰恰是”只看压缩答案”这一习惯扎得最深的地方。
计数是理想的切入楔子:它是最简单的时序聚合,所以在这里失败是真的难看;同时它又刚好是真值天然可明细化的那类任务。
论文的框架还落在了整个领域反复绊倒的一件事上——帧采样在悄悄定义”什么是可知的”——并且给它配了测量装置,而不是挥挥手带过。这稳稳处在”诊断型评测”这个转向上(从 BIG-Bench Hard 到定向探针、从聚合榜单到能力曲面),而视频评测本来早就该走这一步了。
方法成熟度: 框架上是巧劲,机械上很轻。没有新模型、没有新算法——就是一个生成器、一次扫描、一个对齐打分器。
这本身没问题:洞见在于”掌握生成器就等于白拿一本总账”,价值在于真把它建出来并把网格跑完了。
但它确实薄,而薄在一个地方暴露了:时间戳对齐的容差是个超参,而它直接制造了那几个头条数字。如果”3.7% 序列一致率”对容差取 0.2 秒还是 1.0 秒很敏感,那这个数字是软的,我想看的是敏感性曲线,不是一个脚注。
有个更简单的方案论文似乎跳过了:不带时间戳、只在事件身份上做多重集一致性比较——它无需容差,同样能暴露相互抵消的错误。两个都报,这个结论会难反驳得多。
实验诚意: 内部对照是干净的——固定渲染是对的控制手段;而”准确率涨、忠实度不涨”这种结果,只有在你没有为它钓鱼的时候才会冒出来。
两处需要警惕。
第一,头条结论压在单个模型上(Gemini 3.6 Flash,一个便宜的快速档模型);摘要提到了 prompt 变体和真实视频核验,但没提模型谱系,而”快速档模型不擅长密集时序细节”是个远比”视频语言模型不行”弱得多的主张。
第二,也更严重:没有 oracle 或”信息可得性”基线。如果模型收到 K 帧、视频里有 N 个频率为 F 的事件,那么任何系统能还原的上限都是硬的;在高 N 高 F 那个角上,这个上限可能就贴着观测性能。
不把它算出来——或者在同一批采样帧上跑一个朴素的帧间差分 CV 流水线——你就无法把”没推理”和”根本没给它看”分开。
论文通过提高采样率朝这个方向点了一下,直觉是对的,但一个测出来的天花板才能把”暗示性结果”变成”证明”。尤其 18.1% 召回这个数字,在我知道那一格的天花板之前是无法解释的。
写作功力: 摘要在大量堆名词化结构——“trace-grounded parametric profiling for capability-surface estimation”是把四层抽象摞在一个聪明读者一句话就懂的想法上(“我们把带时间戳的答案卷一起发出来”)。这种命名方式通常在给一个偏轻的贡献充气。
“staged temporal failure”(分阶段时序失败)是唯一一个真挣到了自己位置的新词。
我会重写的那一节,是处理采样的那部分:它需要一个明确的信息可得性分析,对瞬态任务给出奈奎斯特式的论证,并在每个网格格点给出 oracle 上界。
这一处加好了,论文就从”模型在我们的探针上表现很差”升级成”这里是’受帧预算限制而不可知’与’真正的推理失败’之间的分界线”——那是个可引用性高得多的结果,而且大概就是藏在这篇论文里的那篇真论文。
判决: 弱接收 —— 轨迹接地的对账方法、以及”准确率涨而忠实度不涨”这个结果确实有用,会改变人们汇报计数类评测的方式;但单模型的证据基础和缺失的信息论天花板,让头条主张没有被钉得像框架暗示的那么牢。
要点总结
可以直接拿走的东西:
永远不要在聚合类任务上只报精确匹配准确率。 任何”由许多子判断归约出一个标量”的指标,都能被相互抵消的错误满足。在它旁边加一个集合级或序列级的一致性指标。
这条立刻迁移到计数、盘点、去重、日志摘要、“X 在这份文档里出现了几次”、财务抽取——凡是答案是对条目做归约的地方都适用。要盯的具体诊断信号是:准确率提升了,条目级一致性没有提升。那意味着你买到的是更好的瞎猜。
自己造合成评测时,让生成器把答案卷以明细化、可执行的形式一起吐出来。 生成时几乎不花成本,事后想补是补不上的。
通用模式:把评测设计成真值是一段程序轨迹,而不是一个标签。这样模型给出的任何中间断言都可核查。
在自己的任务分析里,把”事件表征”和”事件数量”分开。 在怪模型推理不行之前,先给你的事件分类:每个事件是在状态里留下持久残留,还是转瞬即逝?
持久事件能从稀疏快照还原;瞬态事件必须采样到它的窗口内部。
如果你的生产任务涉及瞬态事件,解法不是更好的 prompt 或更大的模型,而是采样策略——你应该在做别的一切之前,先算出你的事件频率要求多高的采样率。闪烁 vs 状态跃迁那个结果说的就是:这个区分支配着下游的一切。
用两轴可靠性包线替代单数字评测。 挑出在你领域里真正驱动难度的两个参数,扫一遍,把系统跨过你真会上线的那条线的区域涂色。
“1 Hz 下 12 个事件以内可靠”是能拿来设计系统的;“评测集上 62%“不是。这件事做起来很便宜,而对基于能力的路由、以及决定何时把子任务交给代码而不是模型,收益不成比例地大。
架构层面的含义: 如果你的应用需要事件记账,不要向视频语言模型索取一个总数。让它在证据密集的短窗口内做检测,然后在代码里做聚合。
这篇论文本质上是一次测量,量的是”整体式计数”这条路为什么走不通;而且这种失败不是靠调 prompt 就能规模化消掉的那一类。