Paper: 2603.12261 Authors: Mateusz Pach, Jessica Bader, Quentin Bouniot, Serge Belongie, Zeynep Akata Categories: cs.LG, cs.AI, cs.CV
The Gap
Text-to-image models like FLUX.1 are powerful but opaque. When you want to change the color of a generated object, your options are basically: re-prompt and hope, or fine-tune the model. Neither is satisfying. Re-prompting is unreliable — the model might shift composition, lighting, or style along with the color. Fine-tuning is expensive and doesn’t generalize. Inversion-based editing methods (like prompt-to-prompt or null-text inversion) give you more control but still operate at the text or attention level, not at the level of “what encodes redness.”
The deeper problem is that nobody really knew how color is represented inside these models. The VAE latent space — the compressed representation that sits between the pixel image and the diffusion process — was treated as a black box. Prior interpretability work on diffusion models focused mostly on the U-Net or transformer attention patterns, not on the VAE’s internal geometry.
This paper asks: is there geometric structure in the VAE latent space that corresponds to human-interpretable color attributes? And if so, can you manipulate it directly?
Problem: Color control in T2I models is unreliable or expensive
    |
    v
Assumption: VAE latent space has interpretable geometric structure
    |
    v
Method: PCA + circular statistics on latent vectors -> find HSL subspace
    |
    v
Evidence: LCS predicts color accurately + direct manipulation changes color
    |
    v
Conclusion: Color is encoded in a structured, manipulable subspace (LCS)
The Increment
One sentence: Before this paper, color in diffusion model latents was a mystery you worked around; after it, there’s a named, geometric subspace you can reach in and turn like a dial.
Core Mechanism
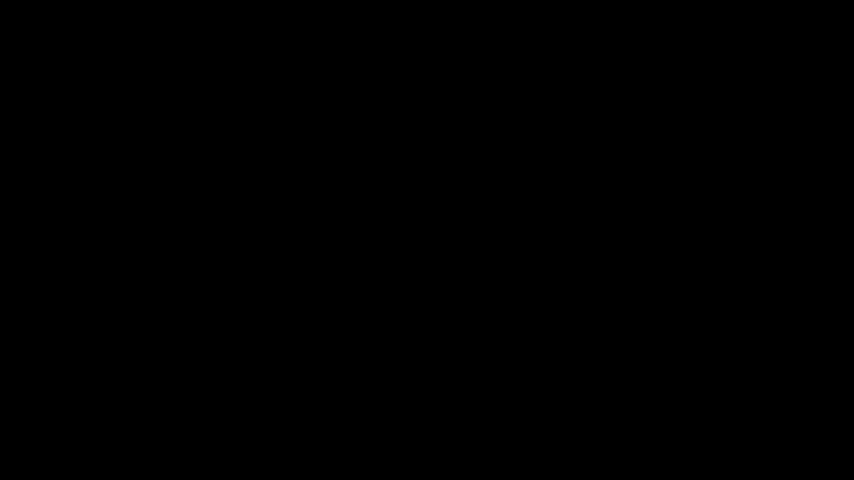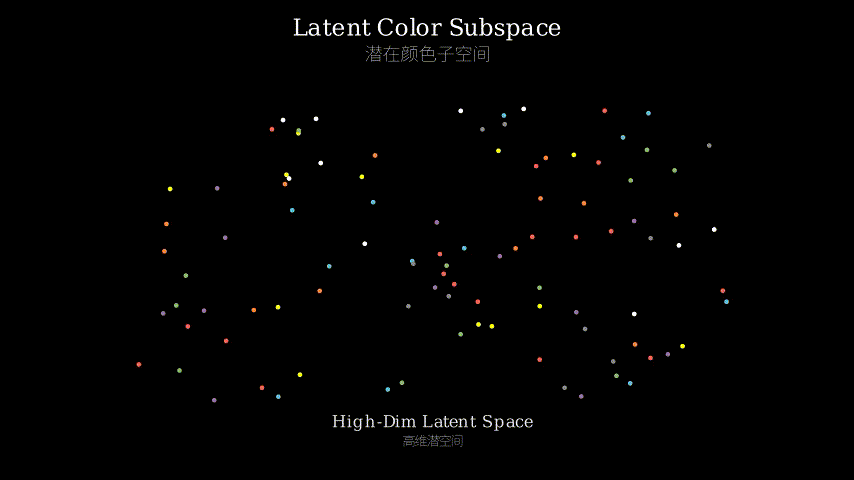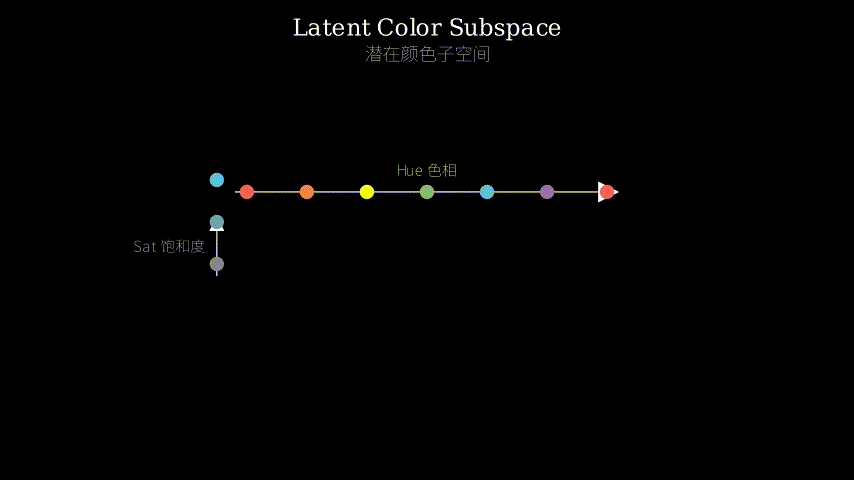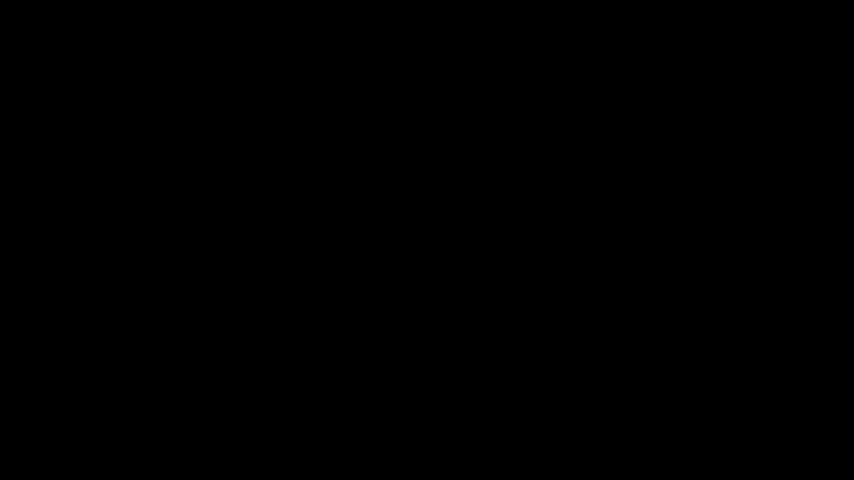
The authors start by encoding a large set of images with known color properties into FLUX.1’s VAE. They then look at the resulting latent vectors and ask: do images with similar hues cluster together? They apply PCA to the latent space and find that a small number of principal components — the Latent Color Subspace (LCS) — capture most of the variance in color. Crucially, hue turns out to live on a circle in this subspace (two PCA components form a 2D plane where hue angle corresponds to actual hue), while saturation and lightness map to scalar directions.
Once the subspace is identified, prediction is straightforward: project a latent onto the LCS basis, read off the coordinates, convert to HSL. Control works in reverse: take a target HSL value, compute the corresponding LCS coordinates, and shift the latent by the difference. No gradient, no training, no diffusion steps — just linear algebra on the compressed representation.
The verification is two-pronged. First, they show the LCS can predict the color of an image from its latent alone, with high accuracy. Second, they show that editing the latent along LCS directions changes the image color in the expected way while leaving other attributes (texture, composition, identity) largely intact.
Input image
    |
    v
[VAE Encoder] -> latent z (16 x H x W)
    |
    v
[Project onto LCS basis] -> (hue_cos, hue_sin, saturation, lightness)
    |
    +-- Prediction path: convert coords -> HSL -> compare to ground truth
    |
    +-- Control path: compute delta from target HSL
                          |
                          v
                     z' = z + delta * LCS_basis
                          |
                          v
                     [VAE Decoder] -> edited image
Think of the VAE latent space as a very high-dimensional filing cabinet. Each drawer is a dimension, and every image is a folder stuffed into a specific location. The filing cabinet looks chaotic — 16 dimensions per spatial location, millions of possible combinations. But the authors discover that if you look at just a few specific drawers (the LCS), all the color information is neatly organized there. Hue is filed in a circular pattern in drawers 1 and 2, saturation is in drawer 3, lightness in drawer 4. The rest of the drawers hold other stuff (texture, shape, semantics), but color lives in its own corner.
The manipulation is like editing a file without opening the whole cabinet. You know exactly which drawers hold color, so you reach in, adjust the coordinates, and close the drawer. The image changes color, but everything else stays put because you didn’t touch the other drawers.
Key Concepts
-
Latent Color Subspace (LCS): A low-dimensional subspace within the VAE’s latent representation where color information is concentrated. It’s discovered via PCA: the first few principal components of the latent vectors, when computed over a dataset of images with known colors, turn out to encode hue, saturation, and lightness in a structured way. The “subspace” means you can project any latent vector onto these components and read off its color.
-
Circular Hue Encoding: Hue (red, orange, yellow, green, blue, purple) is a circular attribute — after purple comes red again. The LCS encodes this as a 2D circle: two principal components form a plane, and the angle in that plane corresponds to hue. This is elegant because it respects the topology of color space: colors that are perceptually close (red and orange) are geometrically close in the latent space.
-
Training-Free Control: Once the LCS is identified, you can manipulate color without retraining or fine-tuning the model. You compute the target color’s coordinates in the LCS, compute the delta from the current latent’s projection, and add that delta back to the latent. Then decode. No gradients, no optimization, just linear algebra. This is fundamentally different from methods that require backpropagation through the diffusion process.
Framework Shift
Before (mainstream approach):        After (this paper):

  Want to change color                 Want to change color
        |                                    |
        v                                    v
  Re-prompt + hope                     Encode image -> latent z
        OR                                   |
  Fine-tune model                            v
        OR                               Project onto LCS
  Inversion + editing                        |
  (all expensive/unreliable)                 v
                                       Read current HSL
                                             |
                                             v
                                       Compute delta to target HSL
                                             |
                                             v
                                       z' = z + delta * LCS_basis
                                             |
                                             v
                                       Decode -> edited image
                                       (fast, deterministic, precise)
From trial-and-error or expensive optimization to direct geometric manipulation, the core shift is: color is not a black-box property but a structured, accessible subspace.
Expert Assessment
Problem choice: Real and well-motivated. Color control in T2I models is a known pain point, and the lack of interpretability in VAE latents is a genuine gap. The timing is right — as these models get deployed for creative tools, users need reliable control knobs.
Method maturity: PCA on latent vectors is not novel, but the discovery that it reveals HSL structure is genuinely interesting. The circular hue encoding is elegant and suggests the VAE learned something meaningful about color perception, not just pixel statistics. The training-free manipulation is a direct consequence of the structure, not a separate contribution.
Experimental integrity: The key experiments are: (1) does LCS predict color accurately? (2) does editing LCS change color as expected? (3) does it preserve other attributes? All three need quantitative metrics and user studies. The paper would be stronger with ablations showing what happens if you use different PCA components or different projection methods.
Writing quality: The title and abstract are clear. The methods section (not fully visible) likely needs more detail on how the LCS basis is computed and how the delta is applied. The failure cases section is critical — when does this break? (Likely: images with complex lighting, transparent objects, or ambiguous color boundaries.)
Verdict: accept — a clean discovery with practical utility, though the novelty is more in the finding than the method.
Takeaways
The PCA-for-interpretability pattern is underused. Whenever you have a learned latent space (VAE, autoencoder, embedding model), try PCA on a dataset with known ground-truth attributes. You might find that the top components correspond to interpretable dimensions.
The circular encoding insight is worth remembering: if your attribute is circular (hue, angle, time-of-day), check whether the latent space encodes it as a 2D circle. If it does, you can manipulate it cleanly. If it doesn’t, the model might not have learned the right structure.
The training-free control pattern (identify subspace, project, edit, decode) is broadly applicable. Any time you have a generative model with a structured latent space, ask whether you can manipulate specific attributes by editing the latent directly rather than going through the full generation process.
论文: 2603.12261 作者: Mateusz Pach, Jessica Bader, Quentin Bouniot, Serge Belongie, Zeynep Akata 分类: cs.LG, cs.AI, cs.CV
缺口
像 FLUX.1 这样的文本生成图像模型功能强大但不透明。
当你想改变生成对象的颜色时,你的选择基本上是:重新提示并祈祷,或者微调模型。两者都不令人满意。
重新提示不可靠——模型可能在改变颜色的同时改变构图、光照或风格。微调代价高昂且不能泛化。基于反演的编辑方法(如 prompt-to-prompt 或 null-text inversion)给你更多控制,但仍然在文本或注意力层面操作,而不是在”什么编码了红色”的层面。
更深层的问题是,没有人真正知道颜色在这些模型内部是如何表示的。VAE 潜空间——位于像素图像和扩散过程之间的压缩表示——被当作黑盒对待。先前关于扩散模型的可解释性工作主要关注 U-Net 或 Transformer 注意力模式,而不是 VAE 的内部几何结构。
这篇论文问:VAE 潜空间中是否存在对应于人类可解释颜色属性的几何结构?如果存在,你能直接操纵它吗?
问题:T2I 模型中的颜色控制不可靠或代价高昂
    |
    v
假设:VAE 潜空间具有可解释的几何结构
    |
    v
方法:PCA + 循环统计 -> 找到 HSL 子空间
    |
    v
证据:LCS 准确预测颜色 + 直接操纵改变颜色
    |
    v
结论:颜色编码在一个结构化、可操纵的子空间(LCS)中
增量
一句话:这篇论文之前,扩散模型潜变量中的颜色是你需要绕过的谜团;之后,有一个命名的、几何的子空间,你可以伸手进去像转旋钮一样调整。
核心机制
作者首先用 FLUX.1 的 VAE 编码一大组已知颜色属性的图像。然后他们查看生成的潜向量并问:具有相似色调的图像是否聚集在一起?
他们对潜空间应用 PCA,发现少数主成分——潜在颜色子空间(LCS)——捕获了颜色的大部分方差。
关键是,色调原来存在于这个子空间的一个圆上(两个 PCA 成分形成一个 2D 平面,其中色调角度对应于实际色调),而饱和度和亮度映射到标量方向。
一旦子空间被识别,预测就很简单:将潜变量投影到 LCS 基上,读取坐标,转换为 HSL。
控制反向工作:取目标 HSL 值,计算相应的 LCS 坐标,并通过差值移动潜变量。无需梯度,无需训练,无需扩散步骤——只是压缩表示上的线性代数。
验证是双管齐下的。首先,他们展示 LCS 可以仅从潜变量预测图像的颜色,准确度很高。其次,他们展示沿 LCS 方向编辑潜变量会以预期方式改变图像颜色,同时在很大程度上保持其他属性(纹理、构图、身份)不变。
输入图像
    |
    v
[VAE 编码器] -> 潜变量 z (16 x H x W)
    |
    v
[投影到 LCS 基] -> (hue_cos, hue_sin, saturation, lightness)
    |
    +-- 预测路径:转换坐标 -> HSL -> 与真值比较
    |
    +-- 控制路径:从目标 HSL 计算 delta
                      |
                      v
                 z' = z + delta * LCS_basis
                      |
                      v
                 [VAE 解码器] -> 编辑后的图像
把 VAE 潜空间想象成一个超高维文件柜。每个抽屉是一个维度,每张图像是塞进特定位置的文件夹。文件柜看起来很混乱——每个空间位置 16 个维度,数百万种可能的组合。
但作者发现,如果你只看几个特定的抽屉(LCS),所有颜色信息都整齐地组织在那里。色调以圆形模式归档在抽屉 1 和 2 中,饱和度在抽屉 3 中,亮度在抽屉 4 中。其余抽屉装着其他东西(纹理、形状、语义),但颜色住在自己的角落里。
操纵就像在不打开整个柜子的情况下编辑文件。你确切地知道哪些抽屉装着颜色,所以你伸手进去,调整坐标,然后关上抽屉。图像改变了颜色,但其他一切都保持原样,因为你没有碰其他抽屉。
关键概念
-
潜在颜色子空间(LCS):VAE 潜在表示中颜色信息集中的低维子空间。它通过 PCA 发现:在已知颜色的图像数据集上计算的潜向量的前几个主成分,以结构化方式编码色调、饱和度和亮度。“子空间”意味着你可以将任何潜向量投影到这些成分上并读取其颜色。
-
循环色调编码:色调(红、橙、黄、绿、蓝、紫)是循环属性——紫色之后又是红色。LCS 将其编码为 2D 圆:两个主成分形成一个平面,该平面中的角度对应于色调。这很优雅,因为它尊重色彩空间的拓扑:感知上接近的颜色(红色和橙色)在潜空间中几何上也接近。
-
无需训练的控制:一旦识别出 LCS,你就可以在不重新训练或微调模型的情况下操纵颜色。你计算目标颜色在 LCS 中的坐标,计算与当前潜变量投影的 delta,并将该 delta 加回潜变量。然后解码。无需梯度,无需优化,只是线性代数。这与需要通过扩散过程反向传播的方法根本不同。
框架转变
之前(主流方法):                之后(本文方法):

  想改变颜色                        想改变颜色
        |                                |
        v                                v
  重新提示 + 祈祷                  编码图像 -> 潜变量 z
        或                               |
  微调模型                               v
        或                           投影到 LCS
  反演 + 编辑                            |
  (都代价高昂/不可靠)                   v
                                   读取当前 HSL
                                         |
                                         v
                                   计算到目标 HSL 的 delta
                                         |
                                         v
                                   z' = z + delta * LCS_basis
                                         |
                                         v
                                   解码 -> 编辑后的图像
                                   (快速、确定性、精确)
从试错或昂贵的优化到直接几何操纵,核心转变是:颜色不是黑盒属性,而是结构化、可访问的子空间。
专家评审
选题眼光:真实且动机充分。T2I 模型中的颜色控制是已知痛点,VAE 潜变量缺乏可解释性是真正的缺口。时机恰当——随着这些模型部署到创意工具中,用户需要可靠的控制旋钮。
方法成熟度:对潜向量进行 PCA 并不新颖,但发现它揭示了 HSL 结构确实有趣。循环色调编码很优雅,表明 VAE 学到了关于颜色感知的有意义的东西,而不仅仅是像素统计。无需训练的操纵是结构的直接结果,而不是单独的贡献。
实验诚意:关键实验是:(1) LCS 是否准确预测颜色?(2) 编辑 LCS 是否按预期改变颜色?(3) 是否保留其他属性?这三个都需要定量指标和用户研究。如果论文包含消融研究,展示使用不同 PCA 成分或不同投影方法会发生什么,会更强。
写作功力:标题和摘要清晰。方法部分(未完全可见)可能需要更多关于如何计算 LCS 基以及如何应用 delta 的细节。失败案例部分至关重要——什么时候会失效?(可能:具有复杂光照、透明对象或模糊颜色边界的图像。)
判决:接收——一个具有实用价值的干净发现,尽管新颖性更多在于发现而非方法。
要点总结
PCA 用于可解释性的模式被低估了。无论何时有学习的潜空间(VAE、自编码器、嵌入模型),都要在具有已知真值属性的数据集上尝试 PCA。你可能会发现顶部成分对应于可解释的维度。
循环编码洞察值得记住:如果你的属性是循环的(色调、角度、一天中的时间),检查潜空间是否将其编码为 2D 圆。如果是,你可以干净地操纵它。如果不是,模型可能没有学到正确的结构。
无需训练的控制模式(识别子空间、投影、编辑、解码)广泛适用。任何时候你有一个具有结构化潜空间的生成模型,都要问是否可以通过直接编辑潜变量来操纵特定属性,而不是经历完整的生成过程。