Paper: 2608.11146 Authors: Abigail Oppong, P Sam Sahil, Tadesse Destaw Belay, Maryam Ibrahim Mukhtar, Esmael Ahmed Abdu, Tassallah Abdullahi, Jessica Oparebea, Saminu Mohammad Aliyu, Idris Abdulmumin, Abubakar Juma Chilala Categories: cs.CL
The Gap
The multilingual jailbreak literature already established the surface fact: translate a harmful prompt into Zulu or Scots Gaelic and safety-tuned models often comply. Yong et al.’s low-resource jailbreak work, MultiJail, XSafety and the various translated-AdvBench derivatives all documented this. But nearly all of that work is generation-based — you prompt, you read the output, you classify it as refusal or compliance. That measurement strategy has two structural weaknesses that this paper targets.
First, generation-based evaluation confounds safety failure with capability failure. When a model produces garbled Twi in response to a harmful Twi prompt, is that a refusal? A comply? An artifact of the model not really speaking Twi? Judge models — usually GPT-4-class, themselves weak in these languages — are asked to arbitrate, and their unreliability propagates silently into the headline numbers. Second, generation-only evidence cannot distinguish two very different internal stories: (a) the model doesn’t understand the harmful request in Hausa, versus (b) the model understands it perfectly well but the understanding never reaches whatever circuitry produces refusals. These have opposite engineering implications — (a) says fix the tokenizer and pretraining mix, (b) says fix the alignment routing — and the field has been treating them as one problem.
There’s a second gap on the data side. Existing multilingual safety benchmarks are overwhelmingly translations of English harm taxonomies. That bakes in an assumption that harm is culturally invariant, which is exactly what you should not assume when the whole paper is about whether safety generalizes. A literal translation of “how do I buy a gun without a background check” may be near-meaningless in a jurisdiction with different institutions, while genuinely dangerous local prompts — around traditional medicine, ethnic tension, local financial scams — simply do not exist in translated benchmarks.
LoDNA plus the latent geometric probe is the paper’s response to both: paired literal/localized prompts to separate translation artifacts from cultural specificity, and hidden-state geometry to separate comprehension from refusal routing.
  PROBLEM
  [safety alignment trained in English]
        |
        v
  IMPLICIT ASSUMPTION
  [there exists one language-agnostic
   "harm manifold"; refusal generalizes]
        |
        +---- prior tests: generate + judge ----> confounded
        |     (capability failure ~= safety failure?)
        |
        v
  METHOD (this paper)
  [LoDNA: literal || localized pairs]  x  [4 langs: tw ha am sw]
        |
        v
  [extract hidden states per layer]
        |
        v
  [refusal direction r = mean(harmful) - mean(benign), in English]
        |
        v
  [project non-English prompts onto r  ==>  retained refusal signal]
        |
        v
  EVIDENCE
  * < 10% of English refusal signal retained (most lang-model pairs)
  * literal vs localized: cos 0.95 - 0.996  (semantically same)
  * but layerwise drift between them grows with depth
        |
        v
  CONCLUSION
  [meaning IS encoded; it is NOT routed to safety.
   multilingual alignment is superficial, not universal]
The Increment
One sentence: Before, we knew low-resource-language prompts *elicit unsafe outputs; after, we have hidden-state evidence that the models actually encode the harmful meaning and simply fail to connect it to the refusal mechanism — which relocates the bug from comprehension to routing.
Core Mechanism
The pipeline has three stages. Stage one is dataset construction. For each harmful concept, LoDNA holds two versions in each of Twi, Hausa, Amharic and Swahili: a literal translation of an English seed prompt, and a culturally localized prompt expressing comparable harmful intent in terms that make sense in the local context — local institutions, local substances, local social fault lines. Both are authored or validated by native speakers (the author list is largely African NLP researchers, which is what makes this dataset credible rather than MT output). A benign control set mirrors the same languages and surface style, which matters because you need a contrast set to define what “refusal” even looks like geometrically.
Stage two extracts the refusal direction. Run the English harmful set and the English benign set through the model, capture the residual-stream hidden state at each layer (typically at the final prompt token), and take the difference of means: r_L = mean(h_L | harmful_en) - mean(h_L | benign_en). This is the well-known difference-in-means refusal direction from the mechanistic-interpretability literature — a single vector per layer that, when ablated, reliably breaks refusal behavior in English. It functions here as a ruler: it defines the axis along which “I should refuse this” is written inside the model.
Stage three is the measurement. Push the Twi/Hausa/Amharic/Swahili prompts through the same model, grab the same layers, and project onto r_L. The retained fraction — how much of the English harmful-prompt projection magnitude survives in the non-English case — is the headline metric, and it comes out under 10% for most language-model pairs. Separately, cosine similarity between the literal and localized versions of the same harmful concept is computed layerwise. Early layers: 0.95–0.996, essentially identical representations. Deeper layers: the two drift apart. That combination is the argument. High similarity says the model is not confused about semantics. Low projection says that semantic content never lands on the refusal axis. Growing drift says whatever downstream processing exists treats literal and localized harm as different objects, so patching one form won’t cover the other.
  [LoDNA]
    |
    +-- EN seed harmful ---+
    +-- EN benign ---------+
    |                      |
    |                  (calibration)
    |                      |
    |                      v
    |            +---------------------------+
    |            | model forward pass        |
    |            | capture h at layers 1..L  |
    |            +---------------------------+
    |                      |
    |                      v
    |        r_L = mean(h|harm_en) - mean(h|benign_en)
    |                      |
    |                      |   * the "refusal ruler" per layer
    |                      |
    +-- tw / ha / am / sw --+
        (literal, localized)|
                            v
                +-----------------------------+
                | project h_nonEN onto r_L    |
                +-----------------------------+
                    |                     |
                    v                     v
          retained signal < 10%     cos(literal, localized)
                                     0.95 .. 0.996 early
                                       \
                                        \  drift grows
                                         v  with depth
                                    layer 1 ...... layer L
                                    [ ==== ] ... [ =   = ]
                                     tight        split
Structural metaphor: an airport with one working X-ray lane.
Think of the model as an airport terminal. Passengers are prompts. Somewhere deep in the building there is a security checkpoint — the refusal mechanism — and it works well: put an English passenger carrying a weapon through it, and the alarm fires. The refusal direction r_L is literally the alarm wire: the paper measures voltage on that wire.
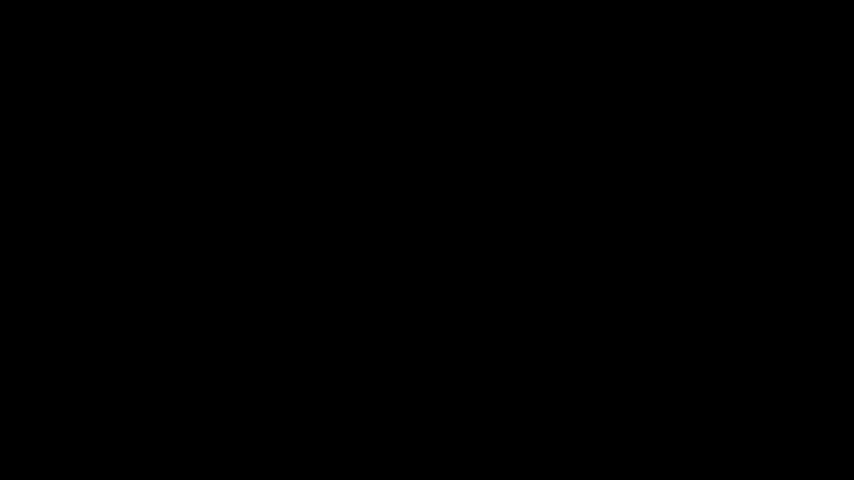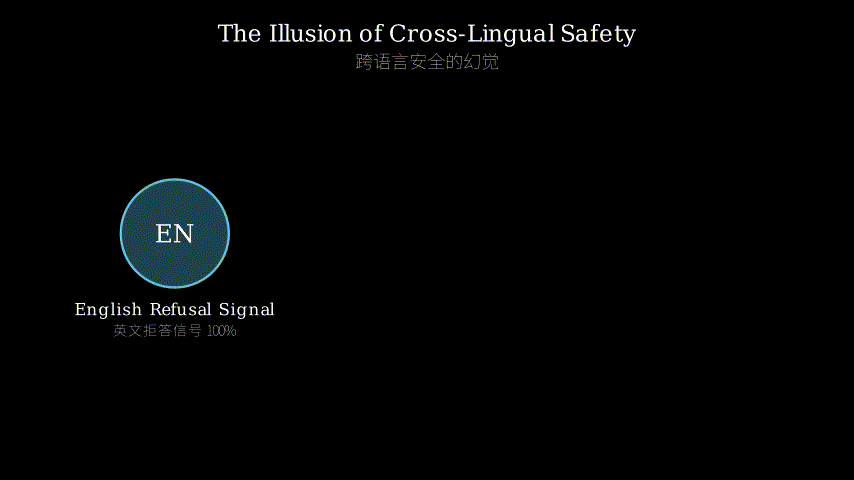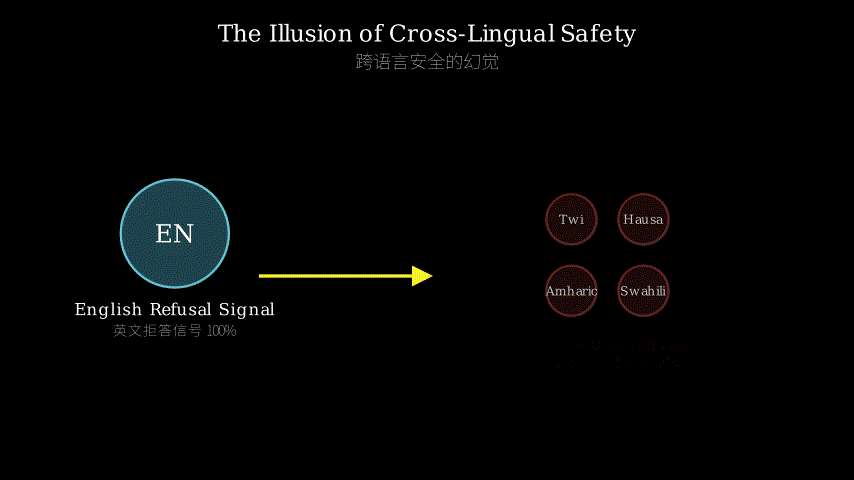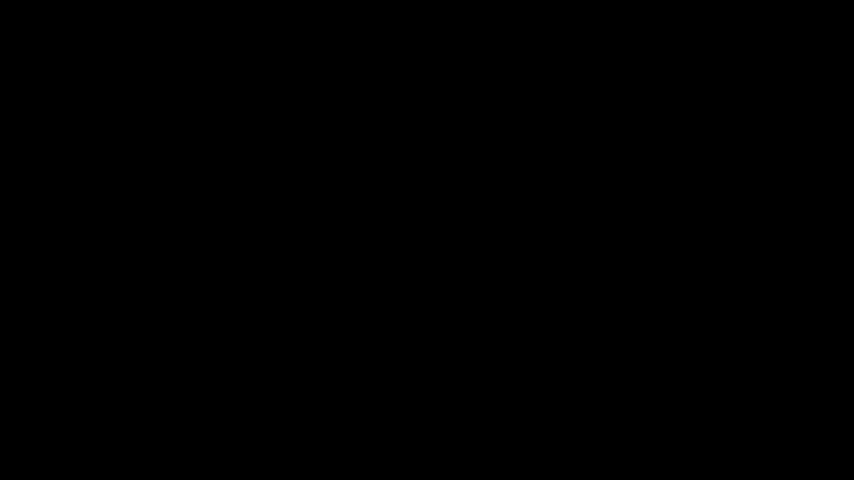
Now the finding. The Hausa passenger walks in carrying the same weapon. Check-in scans him and correctly records what he’s carrying — that’s the 0.95–0.996 cosine similarity, the terminal’s paperwork is accurate, the system knows what this bag contains. But the corridor from the Hausa check-in desk never connects to the X-ray lane. He walks to the gate through a side hallway. The alarm wire reads under 10% of the voltage it reads for the English passenger. Not because the scanner is broken, and not because nobody logged the weapon — because the routing between the desk and the checkpoint was only ever built for English traffic.
The literal-versus-localized drift is the second half of the metaphor. Two passengers carry functionally equivalent contraband: one has a translated English-style weapon, the other a locally-made one. At check-in they look nearly the same (high cosine). Deeper into the terminal, staff route them to different hallways (layerwise drift). So even if you built one new corridor to the checkpoint for translated prompts, the locally-authored ones would still walk past it. That’s the practical sting: patching translated benchmarks does not patch the culturally native attack surface.
Key Concepts
-
Refusal direction (difference-in-means probing): Inside a transformer, every prompt becomes a long list of numbers at each layer — call it a point in a high-dimensional space. If you take 200 harmful English prompts and 200 harmless ones and average each group’s point, the arrow from the harmless average to the harmful average is one particular direction in that space. Empirically, that single arrow is remarkably meaningful: push a prompt’s representation along it and the model becomes more likely to refuse; subtract it and refusals collapse, even for clearly harmful requests. It behaves like a scalar dial labeled “this is dangerous.” So the natural question becomes: when I feed the model a harmful Amharic prompt, how far does it move along that dial? Answer in this paper: barely. Under 10% of the English deflection.
-
Semantic encoding vs. safety routing: These are separable, and the paper’s whole contribution rests on the separation. Encoding means the information is physically present in the activations — you could train a probe to read it out. Routing means that information actually influences the downstream computation that produces behavior. Analogy: a smoke detector’s battery is charged and the sensor detects smoke, but the wire to the siren was never soldered. Diagnostics say “smoke present.” The house stays quiet. Prior generation-based work could only observe the silence; this paper checks the sensor and finds it working, which tells you where to solder.
-
Literal vs. localized harm: A literal prompt is the English harm question, translated. A localized prompt asks for something comparably dangerous but grounded in the actual context — say, a harmful traditional-remedy preparation, or a locally specific fraud script, or content targeting a locally salient ethnic fault line. The distinction matters for two reasons. Evaluation validity: a literal prompt can be so contextually alien that neither compliance nor refusal means much. And coverage: safety training built from translated data will have seen nothing resembling the localized attack surface. High cosine similarity between the two forms plus growing layerwise divergence is the paper’s evidence that they are semantically twinned but computationally handled apart.
Framework Shift
Before (mainstream approach):          After (this paper):

 harmful prompt (low-res lang)          harmful prompt (low-res lang)
        |                                       |
        v                                       v
   [   MODEL   ]  <-- black box            [ M O D E L ]
        |                                    |   |   |
        v                                    v   v   v
    generation                           h_1  h_k  h_L  (per layer)
        |                                    |   |   |
        v                                    +---+---+
   [ LLM judge ]                                 |
   refuse? comply?                               v
        |                              project onto r (EN refusal axis)
        v                                        |
   ASR = 71%                                     v
        |                            "meaning present (cos .99)
        v                              but < 10% on refusal axis"
  "it jailbreaks"                              |
  (why? unknown:                               v
   bad Twi? bad align?)              "encoded, not routed"
                                     (actionable diagnosis)
From attack-success rate to activation geometry, the core shift is that safety is measured as an internal signal path rather than an output label — which turns “it jailbreaks” into “the harm is understood but never reaches the refusal circuit.”
Expert Assessment
Problem choice: Real gap, well chosen. The low-resource jailbreak phenomenon has been known since 2023, and the field’s response has mostly been more benchmarks with more languages — a saturating direction. Asking *why it fails, with a mechanistic probe, is the right next move, and the literal/localized split is the kind of thing that only comes from a team with genuine native-language expertise rather than a translation API budget. It sits at the confluence of two live threads (multilingual safety, refusal-direction interpretability), and joining them is a natural but genuinely un-done step. The one thing I’d push back on: framing it as “strong evidence against a universal harm manifold” is a slightly grandiose reading of what is really a routing/coverage result — the abstract’s own hedge (“within the specific low-resource languages studied”) is doing a lot of work.
Method maturity: Clever reuse rather than new machinery. Difference-in-means refusal directions are off-the-shelf, and applying them cross-lingually is an obvious-in-hindsight move. That’s fine; the value is in the dataset and the framing. But the method is thinner than “latent geometric framework” implies. Two simpler controls I’d want and suspect are underweighted: (1) a high-resource non-English baseline — French, Chinese, Spanish. If French also retains only 40% of the English refusal signal, the story becomes “refusal directions are language-specific by construction,” which is a much weaker claim than “low-resource languages are unsafe.” Some deflation is expected purely because r was estimated on English activations, and the paper needs to show the low-resource numbers are anomalous, not just non-unity. (2) Perplexity or comprehension controls — the drift-with-depth result is exactly what you’d also expect if the model’s grasp of Twi degrades in deeper layers, so “encoding without routing” needs a positive comprehension check (e.g., a translation probe or topic probe that succeeds at the same layers where refusal projection fails). Without those, the headline conclusion is plausible but not nailed down.
Experimental integrity: The cosine numbers (0.95–0.996) are suspiciously high and deserve scrutiny. Hidden-state cosine similarity in transformer residual streams is notoriously inflated by a large shared component — the anisotropy problem. Two *unrelated prompts often sit at 0.9+ before centering. If those figures are raw cosines rather than mean-centered, they may show much less about semantic alignment than claimed, and “literal and localized are semantically aligned” would be partly an artifact. The <10% retention figure is more robust in direction, if not in exact magnitude, since it’s a relative comparison against the English condition. Four languages and (presumably) a handful of open-weight models is a modest footprint; the abstract’s careful scoping is appropriate but also limits how much the result generalizes. And a dataset of harmful localized prompts authored by native speakers is inherently hard to audit externally — I’d want inter-annotator agreement on harmfulness reported prominently, not in an appendix.
Writing quality: The dataset section is where the real contribution lives and, judging from the abstract’s proportions, where the least page space likely goes. LoDNA’s construction protocol — who authored the localized prompts, against what harm taxonomy, with what agreement, how the literal/localized pairing was validated as *matched in severity — is the load-bearing claim of the whole paper, and severity matching is essential: if localized prompts are simply milder, everything else follows trivially. Rewriting that section with full protocol detail and agreement statistics would elevate the paper more than any additional model. The “latent geometric framework” branding is oversold for what is a projection onto a difference-in-means vector; plainer language would build more trust.
Verdict: weak accept — the dataset and the encoded-but-not-routed framing are genuinely valuable contributions, but the causal claim needs a high-resource control language and a comprehension baseline before “encoded, not routed” is established rather than argued.
Takeaways
Things a practitioner can actually lift:
-
Use a known interpretability direction as a cross-domain ruler. The trick generalizes far past languages: estimate a behavioral direction (refusal, sycophancy, uncertainty, tool-use intent) on the distribution where you *know the behavior works, then measure retained projection on any distribution you’re worried about. This gives you a safety coverage metric that doesn’t need a judge model — valuable anywhere your judge is weaker than your model, which is most non-English and most specialized-domain settings.
-
Separate “does it know?” from “does it act?” in every eval you build. If a safeguard fails, run a probe to check whether the relevant information is present in activations. Present-but-unused points at alignment/routing fixes (targeted fine-tuning, activation steering on the deficient distribution). Absent points at pretraining data and tokenization. These consume very different budgets, and generation-only evals cannot tell you which you’re facing.
-
Pair literal with localized in every non-English eval set. This is a cheap, high-yield design pattern. If your translated set passes and your localized set fails, you’ve learned that your safety training memorized surface forms. If both fail equally, translation-based augmentation might actually help. Most teams only build the translated half and thereby cannot distinguish these.
-
Distrust raw cosine similarity in residual streams. Center your activations before comparing. If you’re reporting 0.99 similarities, first check what two random prompts score under the same measurement.
-
The negative-result-as-metric framing. “Retained fraction of the reference signal” is a nice reusable form for regression-testing alignment: pick a canonical direction once, then track retention as you ship new languages, domains, or fine-tunes.
论文: 2608.11146 作者: Abigail Oppong, P Sam Sahil, Tadesse Destaw Belay, Maryam Ibrahim Mukhtar, Esmael Ahmed Abdu, Tassallah Abdullahi, Jessica Oparebea, Saminu Mohammad Aliyu, Idris Abdulmumin, Abubakar Juma Chilala 分类: cs.CL
缺口
多语言越狱这条线上,表层事实早就清楚了:把一个有害提示翻译成祖鲁语或苏格兰盖尔语,对齐过的模型往往就照做了。 Yong 等人的低资源越狱工作、MultiJail、XSafety,以及各种 AdvBench 的翻译衍生集,都记录过这个现象。 但这些工作几乎全是基于生成的评测:给提示、读输出、判定是拒答还是顺从。 这种测量方式有两个结构性弱点,正是本文要打的地方。
第一,基于生成的评测把「安全失效」和「能力失效」混在了一起。 当模型面对一条有害的特威语提示,吐出一段语法混乱的特威语——这算拒答?算顺从?还是只是模型根本不会说特威语的副产品? 仲裁这件事通常交给 GPT-4 级别的裁判模型,而这些裁判在这些语言上本身就很弱,它们的不可靠会静悄悄地渗进最终数字里。
第二,只看生成,没法区分两个内部机制完全不同的故事:(a) 模型压根没听懂这条豪萨语的有害请求;(b) 模型听得明明白白,但这份理解从来没有抵达产生拒答的那套线路。 这两者的工程含义是相反的——(a) 说要修分词器和预训练配比,(b) 说要修对齐的路由——而领域里一直把它们当成同一个问题处理。
数据侧还有第二个缺口。 现有的多语言安全基准绝大多数是英语危害分类体系的译本。 这等于预设了「危害是跨文化不变的」,而当整篇论文要问的恰恰是安全能不能泛化时,这正是最不该预设的东西。 「怎样不做背景审查就买到枪」直译过去,在制度完全不同的地区可能近乎无意义;而真正危险的本地化提示——涉及传统医药、族群张力、本地金融诈骗的那些——在翻译基准里根本不存在。
LoDNA 加上潜空间几何探针,就是对这两个缺口的回应:用字面/本地化配对把翻译产物和文化特异性分开,用隐藏状态几何把「理解」和「拒答路由」分开。
  问题
  [安全对齐在英语上训练]
        |
        v
  隐含假设
  [存在一个与语言无关的
   "危害流形",拒答会泛化]
        |
        +---- 旧测法: 生成 + 裁判 ----> 混淆
        |     (能力失效 ~= 安全失效?)
        |
        v
  方法 (本文)
  [LoDNA: 字面 || 本地化 配对]  x  [4 语言: tw ha am sw]
        |
        v
  [逐层抽取隐藏状态]
        |
        v
  [拒答方向 r = mean(有害) - mean(无害), 英语上估计]
        |
        v
  [把非英语提示投影到 r  ==>  保留的拒答信号]
        |
        v
  证据
  * 多数语言-模型组合保留 < 10% 英语拒答信号
  * 字面 vs 本地化: cos 0.95 - 0.996  (语义几乎同一)
  * 但两者随层数加深而漂移分离
        |
        v
  结论
  [语义"编码"了,但没被"路由"到安全机制。
   多语言对齐是表层的,不是普适的]
增量
一句话: 之前我们知道低资源语言提示能「诱出」不安全输出;之后我们有了隐藏状态层面的证据,说明模型其实编码了那份有害语义,只是没有把它接到拒答机制上——这把 bug 的位置从「理解」搬到了「路由」。
核心机制
管线分三段。 第一段是数据集构造。 对每个有害概念,LoDNA 在特威语、豪萨语、阿姆哈拉语、斯瓦希里语各保留两个版本:一个是英语种子提示的字面翻译,一个是文化本地化提示——用在当地语境里真正说得通的方式(本地机构、本地物质、本地社会断层线)表达可比的有害意图。 两者都由母语者撰写或校验(作者名单基本是非洲 NLP 研究者,这才是这份数据集可信而非机翻产物的原因)。 还有一个与之语言、文体对应的无害对照集——这一点很关键,因为你需要对照组才能在几何上定义「拒答」长什么样。
第二段抽取拒答方向。
把英语有害集和英语无害集分别喂进模型,在每一层捕获残差流的隐藏状态(一般取提示的最后一个 token),然后做均值差:r_L = mean(h_L | 有害_en) - mean(h_L | 无害_en)。
这就是机制可解释性里那个成熟的 difference-in-means 拒答方向——每层一个向量,把它消融掉,英语上的拒答行为会可靠地崩掉。
在这里,它扮演的是一把尺子:它定义了「我应该拒绝这个」在模型内部被写在哪根轴上。
第三段是测量。
把四种语言的提示过同一个模型、取同样的层、投影到 r_L。
保留比例——非英语情况下投影幅度相对英语有害提示还剩多少——就是头条指标,多数语言-模型组合低于 10%。
另一条线是逐层计算同一有害概念的字面版与本地化版之间的余弦相似度:浅层 0.95–0.996,几乎是同一个表示;深层则彼此漂离。
这个组合才是论证本身。 高相似度说明模型在语义上并不糊涂;低投影说明这份语义内容从来没落到拒答轴上;漂移增长说明下游处理把「字面危害」和「本地化危害」当成两个不同的东西,所以补上一种形式并不能覆盖另一种。
  [LoDNA]
    |
    +-- 英语种子(有害) ---+
    +-- 英语(无害) -------+
    |                     |
    |                  (标定)
    |                     |
    |                     v
    |            +---------------------------+
    |            | 模型前向                  |
    |            | 捕获 1..L 层的 h          |
    |            +---------------------------+
    |                     |
    |                     v
    |        r_L = mean(h|有害_en) - mean(h|无害_en)
    |                     |
    |                     |   * 每层一把"拒答尺"
    |                     |
    +-- tw / ha / am / sw -+
        (字面, 本地化)     |
                           v
                +-----------------------------+
                | 把 h_非英语 投影到 r_L      |
                +-----------------------------+
                    |                     |
                    v                     v
             保留信号 < 10%        cos(字面, 本地化)
                                   浅层 0.95 .. 0.996
                                     \
                                      \  随深度漂移
                                       v
                                  第1层 ...... 第L层
                                  [ ==== ] ... [ =   = ]
                                    紧贴          分开
核喻:一座只有一条安检通道通电的机场。
把模型想成一个航站楼,提示是旅客。
楼里深处有一道安检口——就是拒答机制——而它运作良好:让一个携带武器的英语旅客过去,警报就响。
拒答方向 r_L 就是那根警报线,这篇论文测的正是这根线上的电压。
现在看结论。 豪萨语旅客带着同样的武器走进来。 值机台扫描了他,并且准确记录了他带的东西——这就是 0.95–0.996 的余弦相似度,航站楼的登记单是对的,系统知道这个包里是什么。 但从豪萨语值机台通往那条 X 光通道的走廊,压根没修。 他从侧边过道直接走到了登机口。 警报线上读到的电压,不到英语旅客那次的 10%。 不是因为扫描仪坏了,也不是因为没人登记这件武器——而是因为值机台到安检口之间的路由,当初只为英语客流铺过。
字面 vs 本地化的漂移是核喻的后半段。 两名旅客带的违禁品功能等价:一个是翻译过来的英式武器,一个是本地手工造的。 在值机台上它们看起来几乎一样(高余弦)。 往里走,工作人员把他们引进了不同的走廊(逐层漂移)。 所以哪怕你专门为翻译型提示补修了一条通往安检口的走廊,本地原创的那批人还是会从旁边绕过去。 这才是实际的痛点:修补翻译基准,补不上文化原生的攻击面。
关键概念
-
拒答方向(均值差探针): 在 transformer 内部,每个提示在每一层都变成一长串数字——就当它是高维空间里的一个点。 取 200 条有害英语提示和 200 条无害提示,各求平均,得到两个点;从「无害均值」指向「有害均值」的那支箭头,就是这个空间里的一个特定方向。 经验上,这支箭头意外地有意义:把一个提示的表示沿它推,模型更倾向拒答;把它减掉,即使面对明显有害的请求,拒答也会崩塌。 它像一个刻着「这东西危险」的旋钮。 于是自然的问题变成:喂一条有害的阿姆哈拉语提示,模型在这个旋钮上转了多少? 本文的答案:几乎没转,不到英语偏转量的 10%。
-
语义编码 vs 安全路由: 这两件事可以分开,而本文的全部贡献就压在这个区分上。 编码是指信息物理上确实存在于激活里——你能训一个探针把它读出来。 路由是指这份信息真的影响了产生行为的下游计算。 打个比方:烟雾报警器电池是满的,传感器也确实测到了烟,但通往蜂鸣器的那根线从来没焊上。 自检说「检测到烟雾」,房子里一片安静。 基于生成的旧工作只能观察到这份安静;这篇论文去查了传感器,发现它是好的——这就告诉你该往哪儿焊线。
-
字面危害 vs 本地化危害: 字面提示是英语危害问题的译文。 本地化提示问的是危险程度可比、但扎根于真实语境的东西——比如一种有害的传统药方配法、一套本地特有的诈骗话术、针对当地敏感族群断层的内容。 这个区分之所以重要,有两个理由。 评测有效性:字面提示可能在语境上过于异质,以至于顺从还是拒答都说明不了什么。 以及覆盖度:用翻译数据做出来的安全训练,压根没见过本地化的那片攻击面。 两种形式之间高余弦相似 + 随层加深而分离,正是本文用来说明「它们语义上是孪生的,计算上却被分开处理」的证据。
框架转变
之前(主流方法):                    之后(本文方法):

 有害提示(低资源语言)                  有害提示(低资源语言)
        |                                    |
        v                                    v
   [   模型   ]  <-- 黑盒              [  模  型  ]
        |                               |    |    |
        v                               v    v    v
      生成文本                        h_1  h_k  h_L (逐层)
        |                               |    |    |
        v                               +----+----+
   [ 裁判模型 ]                              |
   拒答? 顺从?                                v
        |                          投影到 r (英语拒答轴)
        v                                    |
    ASR = 71%                                 v
        |                        "语义在 (cos .99)
        v                          但拒答轴上 < 10%"
   "它被越狱了"                            |
   (为什么? 不知道:                        v
    特威语差? 对齐差?)              "编码了, 没路由"
                                     (可行动的诊断)
一句话:从攻击成功率到激活几何,核心转变是把安全当成一条内部信号通路来量、而不是当成输出标签来判——于是「它被越狱了」变成了「危害被理解了,但从没抵达拒答电路」。
专家评审
选题眼光: 真缺口,选得好。 低资源越狱现象从 2023 年就众所周知,而领域的回应主要是「更多基准、更多语言」——一条正在饱和的路。 用机制探针去问为什么失效,是正确的下一步;而字面/本地化的切分,只有真正具备母语专长的团队才做得出来,不是买翻译 API 额度能凑的。 它落在两条活跃线索(多语言安全、拒答方向可解释性)的交汇处,把它们接起来是自然但确实还没人做的一步。 我要顶一句的是:把结论包装成「强有力地反驳普适危害流形」略显宏大,这本质上是一个路由/覆盖度的结果;摘要自己那句限定(「在所研究的特定低资源语言范围内」)承担了相当多的重量。
方法成熟度: 是巧劲,但更多是聪明的复用,而非新机械。
均值差拒答方向是现成的,把它用到跨语言上属于「事后看很显然」的一步。
这没问题——价值在数据集和框架上。
但方法比「潜空间几何框架」这个名号要单薄。
两个更简单的对照我很想看到,且怀疑被低估了:
(1) 高资源非英语基线——法语、中文、西班牙语。
如果法语也只保留 40% 的英语拒答信号,故事就变成「拒答方向本身就是语言特异的」,这比「低资源语言不安全」弱得多。
由于 r 是在英语激活上估计的,出现一定衰减本来就在预期之内;论文需要证明低资源语言的数字是异常低,而不只是「不等于 1」。
(2) 困惑度或理解力对照——「随深度漂移」这个结果,恰好也是「模型对特威语的把握在深层退化」会给出的预测。
所以「编码但未路由」需要一个正向的理解力检验:比如在拒答投影失效的同一批层上,翻译探针或主题探针依然成功。
没有这些,头条结论可信但没钉死。
实验诚意: 0.95–0.996 这组余弦数字高得可疑,值得推敲。 transformer 残差流里的隐藏状态余弦相似度,出名地会被一个巨大的共享成分抬高——各向异性问题。 两条毫不相关的提示,在不做中心化时经常也在 0.9 以上。 如果论文报的是原始余弦而非去均值后的余弦,那这些数字能说明的东西就远少于宣称的,「字面与本地化语义对齐」有一部分会是测量产物。 <10% 的保留率在方向上更稳(虽然精确幅度未必),因为它是相对英语条件的比值。 四种语言、(大概)少数几个开源权重模型,覆盖面不大;摘要的谨慎限定是恰当的,但也框住了结论能外推多远。 另外,由母语者撰写的有害本地化提示集,天然难以被外部审计——我希望标注者间一致性(对「是否有害」的一致性)被放在正文显眼处,而不是附录里。
写作功力: 真正的贡献活在数据集那一节,而从摘要的篇幅配比看,那一节大概是页数最少的。 LoDNA 的构造流程——本地化提示由谁撰写、依据什么危害分类体系、一致性多少、字面/本地化配对是如何被验证为严重度匹配的——是全文承重的主张。 严重度匹配尤其关键:如果本地化提示本身就更温和,后面的一切都是同义反复。 把这一节重写成完整的流程细节加一致性统计,比再加一个模型更能把整篇论文抬一档。 「潜空间几何框架」这个包装,对一个「投影到均值差向量」的操作而言明显过度;说得朴素些反而更能建立信任。
判决: 弱接收 — 数据集与「编码了但没路由」这个框架确有价值,但因果主张需要一个高资源对照语言和一条理解力基线,才能把「编码而未路由」从论证变成结论。
要点总结
实践者能真正拿走的东西:
-
把一个已知的可解释性方向当作跨域的尺子。 这个套路远不止用于语言:在你确知行为有效的分布上估计一个行为方向(拒答、谄媚、不确定性、工具调用意图),然后在任何你担心的分布上测保留投影。 这给你一个不需要裁判模型的安全覆盖度指标——凡是裁判比被测模型更弱的场景都值钱,而这几乎覆盖了所有非英语和所有专业垂域。
-
在你构建的每个评测里,都把「它知道吗」和「它做了吗」分开。 安全机制失效时,先跑探针看相关信息在不在激活里。 在但没用上 → 指向对齐/路由类修法(在薄弱分布上做定向微调、激活引导)。 不在 → 指向预训练数据与分词。 这两条路的预算量级完全不同,而只看生成的评测无法告诉你自己面对的是哪一条。
-
在每个非英语评测集里,把字面版和本地化版成对做出来。 这是个便宜、高产出的设计模式。 翻译集过了、本地化集挂了,你就知道你的安全训练只是背下了表层形式。 两边挂得一样多,那基于翻译的数据增强也许真的有用。 多数团队只做了翻译那一半,于是永远分不清这两种情况。
-
不要轻信残差流里的原始余弦相似度。 比较前先做中心化。 要报 0.99 的相似度,先看看同样的测法下两条随机提示能打多少分。
-
「负结果即指标」的这种框法。 「相对参考信号的保留比例」是个好用的可复用形式,适合做对齐的回归测试:一次性选定一个基准方向,然后在你上新语言、新垂域、新微调时持续跟踪保留率。