Paper: <img alt=“2604.03191” src=“https://e1a4c9d0d2f9f737c5e1.ucr.io/-/preview/https://api.urlbox.io/v1/NTYqWgJv5s0qDIxN/jpeg?url=https%3A%2F%2Farxiv.org%2Fabs%2F2604.03191&full_page=true&width=1024&max_height=2048&quality=80” />
Authors: Takuya Shiba
Categories: cs.RO, cs.CV, cs.LG
The Gap
In the world of Vision-Language Models (VLMs), the recipe is simple: use a bigger, better vision encoder, and the whole model gets smarter. Naturally, researchers applied this to Vision-Language-Action (VLA) models for robotics. However, they hit a wall. Even when swapping a basic CLIP encoder for a massive DINOv2-Giant, the robot’s manipulation performance often remained flat.
Prior research assumed that the “bottleneck” was always data or the vision representation. This paper identifies a hidden structural limitation: Discrete Tokenization. When we turn continuous robot actions into a small set of “words” (tokens) to fit them into a Transformer, we create a fixed-capacity filter that throws away the very improvements the vision encoder provides.
[ Problem ] -> Upgrading Vision doesn't improve Robot Actions
      |
[Assumption] -> The Vision Encoder is the primary bottleneck
      |
[ Method  ] -> Factorial Analysis (Discrete vs. Continuous Actions)
      |
[ Evidence] -> Continuous (Diffusion) scales; Discrete (OAT) plateaus
      |
[Conclusion] -> Codebook capacity is the "Compression Gap"
The Increment
One sentence: This paper proves that scaling laws in robotics are dictated by the “tightest” part of the pipe, showing that better vision is useless if your action vocabulary is too small to express it.
Core Mechanism
The authors contrast two ways of handling robot actions. In Continuous Action pipelines (like Diffusion Policy), the vision features flow directly into a generator that can express infinite nuance. In Discrete Action pipelines (like OAT), vision features are squashed to match a “Codebook”—a dictionary of predefined movements.
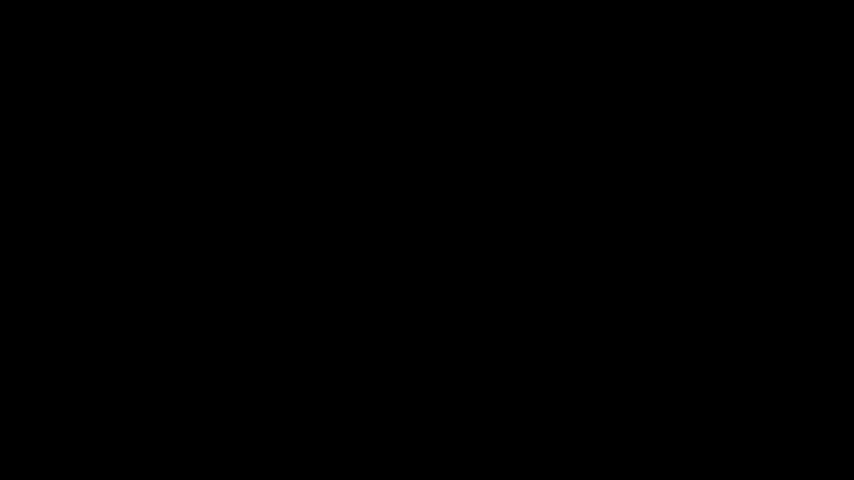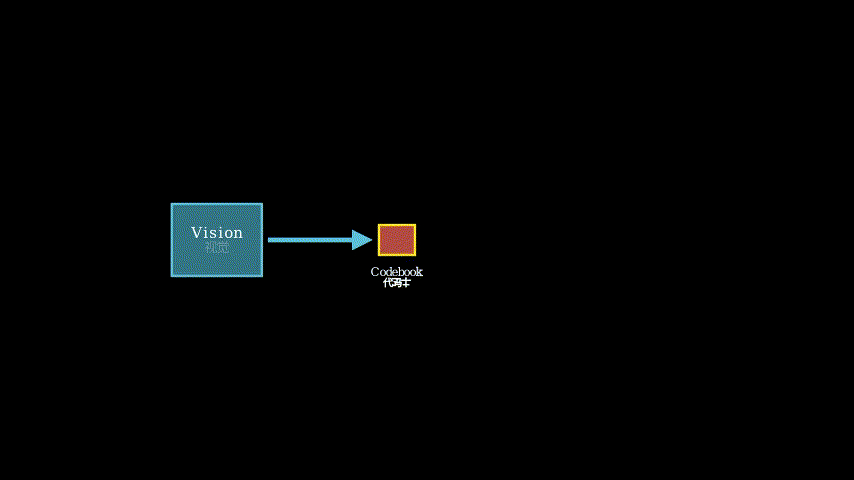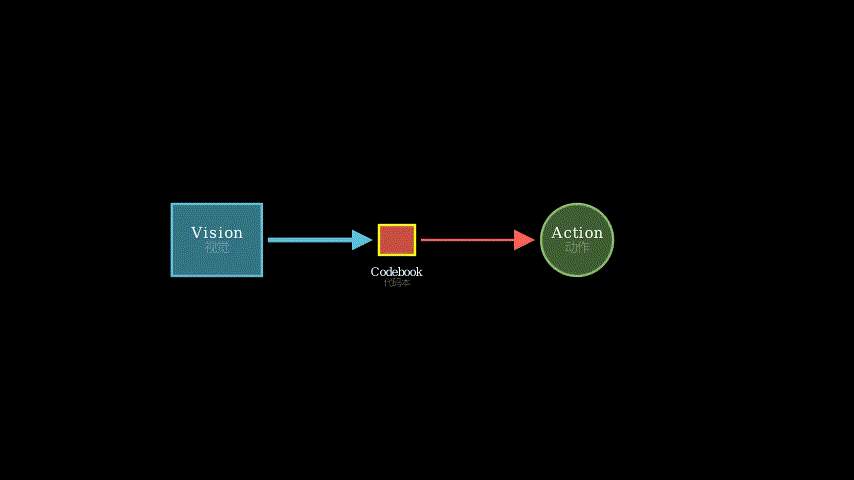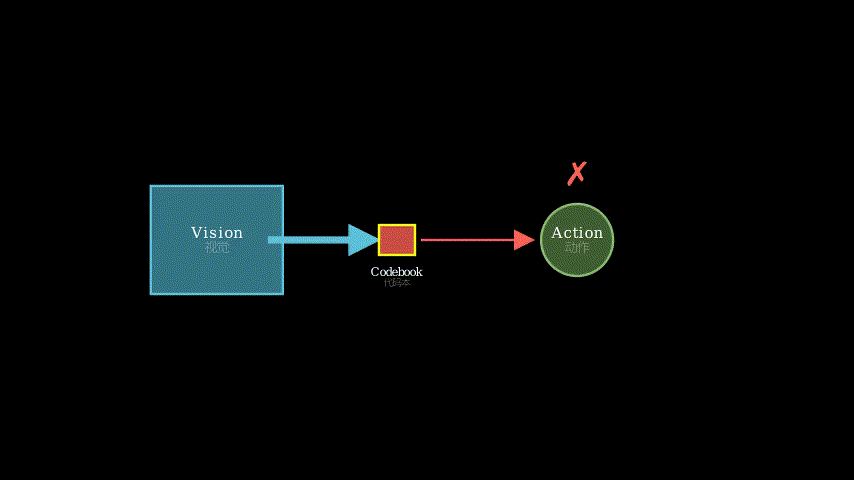
When the vision encoder is upgraded, it creates a “higher fidelity” map of the world. However, if the Codebook only has 1,000 entries, it cannot represent the subtle adjustments the better encoder enables. The information is simply discarded at the quantization step.
VISION ENCODER      ACTION TOKENIZER      ROBOT POLICY
(Information)        (Quantization)       (Execution)
      |                    |                   |
[   Rich    ]  --->  [   Fixed    ]  --->  [  Limited  ]
[   Input   ]        [ Capacity   ]        [  Output   ]
      |                    |                   |
      +----( Bottleneck occurs here )----------+
To explain this, imagine the “Garden Hose and the Fire Hydrant” metaphor:
- The Vision Encoder is a massive Fire Hydrant (input).
- The Action Codebook is a Garden Hose (the connector).
- The Robot’s Performance is the amount of water putting out a fire.
- If you upgrade the Hydrant to a high-pressure industrial system, but keep the same narrow Garden Hose, the amount of water coming out doesn’t change. The hose is the “Compression Gap.” To get more water, you don’t need a bigger hydrant; you need a wider hose (larger codebook) or a pipe that doesn’t restrict flow (continuous actions).
Key Concepts
- The Compression Gap: The difference between the rich information available in a vision representation and the limited information that can be squeezed through a discrete action vocabulary.
- Information Bottleneck: The concept that the total intelligence of a system is limited by its narrowest point. In VLAs, this shifts from “vision” to “tokens” as encoders get better.
- Diffusion Policy: An approach that predicts actions as a continuous distribution, effectively removing the “hose” bottleneck and allowing vision scaling to work.
Framework Shift
Before (Mainstream VLA):              After (This Paper):
[Vision] -> [Tokenizer] -> [LLM]     [Vision] -> [Bottleneck?] -> [Action]
      ^           |                        ^            |
      |           v                        |            v
    Scale       Scale                    Identify     Choose
    Vision      Data                     Bottleneck   Head Type
One sentence: From “blindly scaling vision,” the core shift is to “balancing vision quality with action capacity.”
Expert Assessment
Problem choice: Exceptional. We have been scratching our heads for two years wondering why RT-2 doesn’t just “get better” when we plug in better encoders. This addresses the most annoying friction point in Physical AI.
Method maturity: The factorial experiment is the gold standard for causal evidence. By isolating the encoder quality from the action representation, Shiba provides an undeniable proof that the bottleneck is structural, not just “not enough data.”
Experimental integrity: LIBERO is a rigorous benchmark for manipulation. The use of four different encoders (CLIP, DINOv2, etc.) across various scales provides a clear gradient that makes the “flat line” of OAT look even more damning.
Writing quality: The abstract is a masterclass in clarity. However, the information-theoretic proofs in the middle could be more accessible to practitioners who aren’t familiar with mutual information math.
Verdict: Strong Accept — It provides a clear “Stop” sign for researchers wasting compute on vision scaling without fixing their action heads.
Takeaways
- Abandon small codebooks: If you are using discrete tokens for actions, your codebook size must scale proportionally with your vision encoder size.
- Prioritize Diffusion: For high-fidelity tasks, continuous action heads are currently the only way to “unlock” the full power of SOTA vision models like DINOv2.
- Bottleneck Audit: Before starting a 10,000 GPU-hour run, check if your model’s “bottleneck” is where you think it is.
论文: The Compression Gap: Why Discrete Tokenization Limits Vision-Language-Action Model Scaling 作者: Takuya Shiba 分类: cs.RO, cs.CV, cs.LG
缺口
在视觉-语言模型(VLM)的世界里,逻辑很简单:视觉编码器(Encoder)越强,模型就越聪明。 自然而然,机器人领域的研究者也想把这一套搬到视觉-语言-动作(VLA)模型上。 然而,大家撞墙了:即便把基础的 CLIP 换成巨大的 DINOv2-Giant,机器人的操作表现往往毫无起色。 此前研究认为瓶颈在于数据量或视觉表征不够细。 本文精准指出了一处隐蔽的结构性限制:离散化 Token(Discrete Tokenization)。 当我们为了把动作塞进 Transformer 而将其转换成有限的“词汇”(代码本)时,我们实际上制造了一个固定容量的过滤器,把视觉编码器辛苦提升的信息量全给过滤掉了。
[ 问题 ] -> 升级视觉编码器无法提升机器人表现
      |
[ 假设 ] -> 视觉编码器是主要的性能瓶颈
      |
[ 方法 ] -> 析因实验(对比离散动作 vs 连续动作)
      |
[ 证据 ] -> 连续动作(扩散策略)随规模增长;离散(OAT)陷入停滞
      |
[ 结论 ] -> 代码本容量构成了“压缩缺口”
增量
一句话: 这篇论文证明了机器人大模型的扩展定律取决于管道中“最细”的那一段,证明了如果动作词汇量太小,再好的视觉也是白搭。
核心机制
作者对比了处理机器人动作的两种方式。 在连续动作管道中(如扩散策略),视觉特征直接流向一个能表达无限细微差别的生成器。 而在离散动作管道中(如 OAT),视觉特征必须被强行挤进一个“代码本”(Codebook)——即预定义的动作字典。 当视觉编码器升级时,它对世界的感知变得更清晰了。 但如果你的“动作字典”只有 1000 个词,它根本表达不出这种清晰度带来的细微调整,信息在量化阶段就被扔掉了。
视觉编码器           动作 Tokenizer          机器人策略
 (信息源)              (量化瓶颈)             (执行端)
     |                    |                    |
[ 高信息量 ]  --->  [ 固定容量 ]  --->  [ 有限表现 ]
[   输入   ]        [ 代码本   ]        [   输出   ]
     |                    |                    |
     +----( 这里产生了信息瓶颈 )---------------+
为了解释这一点,我们可以使用**“消火栓与花园水管”**的核喻:
- 视觉编码器是巨大的消火栓(输入)。
- 动作代码本是连接用的花园水管(连接件/瓶颈)。
- 机器人的表现是最后灭火的水量。
- 如果你把消火栓升级成工业级高压系统,但还是用那根细细的花园水管,出来的水量是不会变的。 这根水管就是“压缩缺口”。 想多出水,你不需要更大的消火栓,你需要一根更粗的水管(更大的代码本),或者干脆直接用大口径管道(连续动作)。
关键概念
- 压缩缺口 (The Compression Gap): 指视觉表征中蕴含的丰富信息与离散动作词汇能承载的有限信息之间的落差。
- 信息瓶颈 (Information Bottleneck): 系统总智能受限于其最窄的环节。 在 VLA 中,随着编码器变强,瓶颈从“看不明”变成了“说不出”。
- 扩散策略 (Diffusion Policy): 一种将动作预测为连续分布的方法,它实际上去掉了“水管”瓶颈,让视觉规模化的威力得以释放。
框架转变
之前(主流 VLA):                之后(本文方法):
[视觉] -> [Tokenizer] -> [LLM]     [视觉] -> [寻找瓶颈] -> [动作]
      ^           |                        ^            |
      |           v                        |            v
    扩展        扩展                     识别         选择
    视觉        数据                     瓶颈         输出头
一句话:从“盲目堆视觉参数”,转变为“平衡视觉质量与动作表达容量”。
专家评审
选题眼光: 极佳。 这两年大家一直在纳闷为什么 RT-2 换了更强的编码器还是那个样子。 这篇论文直接指出了物理 AI 领域最让人心烦的摩擦点。
方法成熟度: 析因实验是因果证据的金标准。 通过剥离编码器质量和动作表征方式,作者提供了不可辩驳的证明:瓶颈是结构性的。
实验诚意: LIBERO 是公认的机器人操作基准。 使用了 CLIP、DINOv2 等四种不同编码器在多尺度下的对比,清晰地展示了 OAT 那条纹丝不动的“性能平线”。
写作功力: 摘要写得非常有力量感,一针见血。 不过中间关于信息论的数学证明对不熟悉互信息计算的开发者来说稍微有点硬核。
判决: 强接收 —— 它给那些在没搞定动作输出头之前就疯狂烧钱堆视觉规模的研究者发了一张明确的“限行证”。
要点总结
- 抛弃小代码本: 如果你坚持在动作上使用离散 Token,代码本的大小必须随视觉编码器的规模同比例增长。
- 优先考虑扩散模型: 对于高精度任务,连续动作头目前是唯一能“解锁” DINOv2 等 SOTA 视觉模型全部威力的途径。
- 瓶颈审计: 在开始万小时级别的 GPU 训练前,先确认你模型的“瓶颈”是不是真的在你以为的地方。