Paper: 2606.19329 Authors: V. Samuel Pérez-Díaz, Vinay L. Kashyap, Joshua D. Ingram, David Fouhey, Juan Rafael Martínez-Galarza, Pavlos Protopapas, Jeremy J. Drake, Dong-Woo Kim, Cecilia Garraffo Categories: astro-ph.IM, cs.LG
The Gap
Existing cross-matching between X-ray (Chandra) and optical (Gaia) catalogs relies almost entirely on spatial proximity: nearest-neighbour, likelihood ratios, or Bayesian frameworks like NWAY that incorporate positional errors and source densities.
These methods work well when the fields are sparse, but in crowded regions (Galactic plane, clusters) they produce ambiguous matches (multiple plausible optical counterparts for one X-ray source) and false positives (chance alignments misidentified as counterparts).
The field lacked a systematic way to use the rich multi-band information (magnitudes, colors, parallaxes) that both catalogs provide to break these degeneracies.
This paper’s logical chain:
[Problem: ambiguous / false matches with spatial-only methods]
    |
    v
[Assumption: source properties (mag, color, distance) carry discriminant power]
    |
    v
[Method: use NWAY to build high-confidence training set, then train LightGBM classifier on ~20 features]
    |
    v
[Evidence: on COUP validation, classifier matches 95% of NWAY decisions *without any positional features*]
    |
    v
[Conclusion: ML-based cross-matching reliably resolves ambiguity and flags chance coincidences]
The Increment
One sentence: Before this paper, cross-matching Chandra and Gaia meant choosing the “closest” optical source and hoping it was right; after this paper, we have a probabilistic catalog that knows *why a match is likely, flags ambiguous cases instead of forcing one answer, and identifies ~20k spurious alignments that pure-spatial methods would have accepted.
Core Mechanism
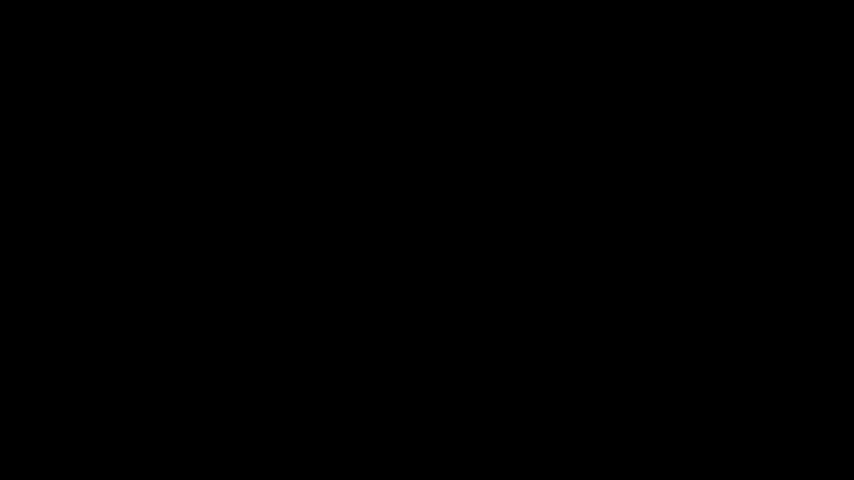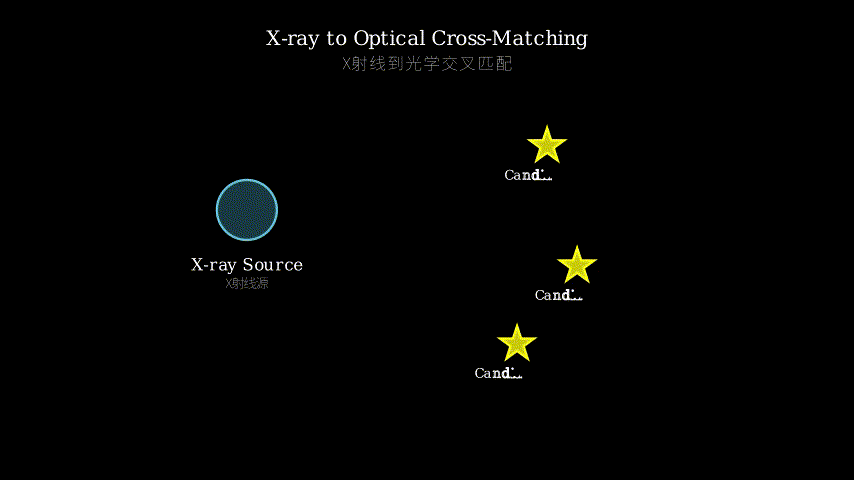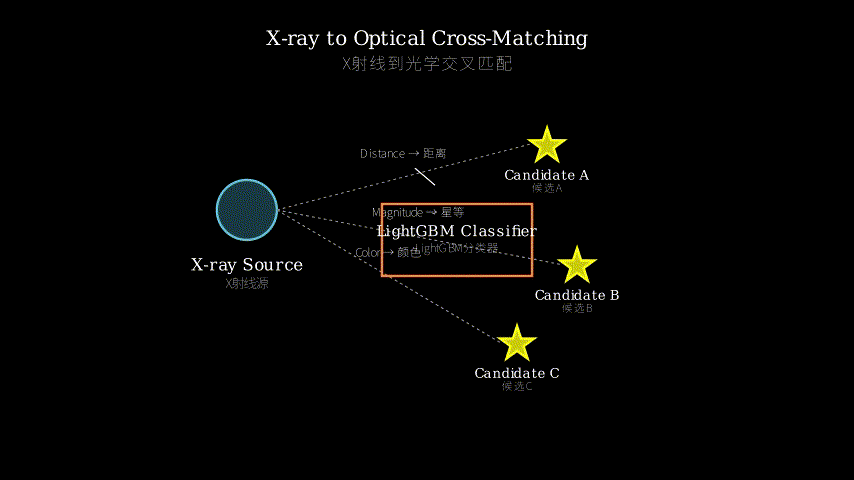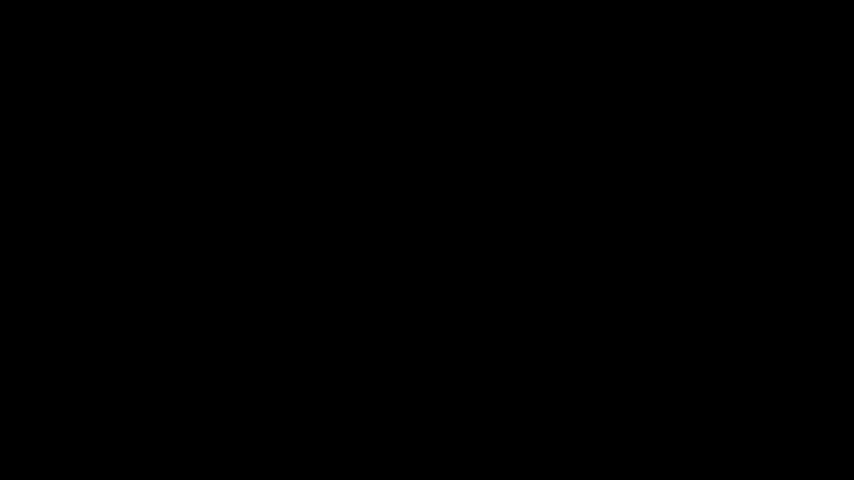
The pipeline starts by constructing candidate pairs: every Chandra X-ray source (254k) is paired with every Gaia optical source lying within a generous 5-arcsecond radius (covering typical positional uncertainties).
This creates millions of candidate pairs, most of which are not true counterparts.
To train a classifier, the authors first use NWAY, a Bayesian cross-matching tool that combines positions, magnitudes, and local densities to assign a probability of being a true counterpart.
They take only the highest-confidence NWAY matches (probability > 0.8) as positive labels, and randomly sample non-matches (pairs without a high-probability NWAY assignment) as negative labels.
This training set feeds a gradient-boosted decision tree (LightGBM), which learns from ~20 features:
Gaia magnitudes (G, BP, RP), colors (BP-RP, G-RP), parallax and its error, X-ray hardness ratios, and distance between the two sources (yes, distance is included, but the model is tested without it to prove astrophysical features work alone).
The trained classifier outputs a match probability for every candidate pair.
Then a decision logic per X-ray source:
- If the highest probability > 0.9 → single counterpart.
- If two or more candidates have probability > 0.5 → ambiguous multiple matches (flagged for user).
- If all probabilities
< 0.3→ no counterpart (likely chance coincidence).
[Data flow schematic]
CSC X-ray sources (254K)    Gaia DR3 (1.8B)
        |                        |
        +------ cross-match cutoff: 5 arcsec ------+
                         |
                   Candidate pairs (millions)
                         |
              +----------+----------+
              |                     |
         NWAY (Bayesian)      Feature vector: mag,
         => high-conf labels    color, parallax,
              |                 hardness ratios,
              |                 distance (optional)
              v                     |
         Training set: + labels     |
              |                     |
              +----------+----------+
                         |
                   LightGBM classifier
                         |
                   Match probability per pair
                         |
                   Decision rule (thresholds)
                         |
          +--------------+--------------+
          |              |              |
    counterpart   ambiguous(7k)   no counterpart(20k)
       (113k)                     (flagged by pure-spatial
                                   as matches, now rejected)
Structural metaphor: Think of this like a detective matching a blurry security camera photo (X-ray source) to a database of known faces (Gaia sources).
The old method only used “where the person was standing” (spatial position).
In a crowd, many people stand at similar positions, so the detective picks the nearest and often gets it wrong.
This paper gives the detective a complete profile: height (magnitude), skin tone (color), age (parallax -> distance), and gait (X-ray hardness).
NWAY is like an expert witness who already made a few perfect identifications; the ML model (LightGBM) learns from those to match all remaining faces.
When the profile matches two equally likely suspects, the detective marks the case as “ambiguous” instead of picking one at random.
When everyone in the crowd has a completely different profile, the detective correctly says “the person I saw is not in this database.”
Key Concepts
-
Cross-matching:
Different telescopes photograph the same patch of sky but see different “colors” of light.
Combining them requires linking the same physical star or galaxy across images.
The naive approach: if an X-ray dot and an optical dot are within a few arcseconds, they are probably the same object.
Problem: X-ray positions are fuzzy (arcsecond-level errors), and in dense clusters you can have 5 optical candidates inside that error circle.
Cross-matching is the art of deciding which one, if any, is the real counterpart. -
NWAY:
A Bayesian framework that computes the probability a given pair is a true match.
It considers:- Positional offset (with error bars)
- Local source density (how many other optical stars are nearby)
- Optional magnitude priors (e.g., X-ray sources tend to be bright at optical).
It is highly principled but computationally expensive for millions of pairs and does not natively handle multiple ambiguous solutions — it picks the most probable one.
This paper uses NWAY only to generate reliable training labels, not as the final classifier.
-
Gradient-boosted classifier (LightGBM):
An ensemble of many shallow decision trees, each trained to correct the mistakes of the previous ones.
It is fast, handles mixed data types (continuous numbers, categories), and automatically learns non-linear interactions between features.
In this problem, it learns that “blue optical colors + high X-ray hardness” might indicate an accreting binary, while “red colors + small parallax” points to a distant background galaxy.
Framework Shift
Before (mainstream approach):        After (this paper):

[Chandra source]                     [Chandra source]
      |                                     |
      | spatial cutoff (3" radius)          | spatial envelope (5")
      |                                     |
      v                                     v
[one nearest Gaia star]              [multiple Gaia candidates]
      |                                     |
      | accept if distance < 2"             | compute ~20 features
      | otherwise: no match                 | (mag, color, parallax, ...)
      |                                     |
      v                                     v
[single answer, no uncertainty]      [LightGBM probability for each
                                       candidate pair]
                                            |
                          +-----------------+-----------------+
                          |                                   |
                     prob > 0.9:                    all prob < 0.3:
                     counterpart                     no counterpart
                          |                                   |
                     prob 0.5-0.9 for             [spurious match
                     >1 candidate:                avoided]
                     flagged ambiguous
One sentence: From X to Y, the core shift is moving from a single spatial threshold to a probabilistic decision that leverages the full multi-wavelength information content of both catalogs.
Expert Assessment
Problem choice: Real gap.
Cross-matching Chandra and Gaia is a bottleneck for multi-wavelength science (e.g., identifying counterparts of X-ray binaries, active galaxies, young stellar objects).
The problem of ambiguous matches is known but typically handled ad-hoc per science case.
This paper provides a general, data-driven solution that fits squarely into the trajectory of “ML for astronomical source association.”
Method maturity: Clever insight rather than brute force.
The key idea is to use NWAY as a label generator instead of forcing it to be the final decision maker.
LightGBM is a standard tool, but the feature engineering (combining X-ray hardness with Gaia colors) and the probabilistic decision rule are well-tuned.
One could argue that a simple random forest would have worked similarly, but LightGBM’s speed scales to hundreds of millions of pairs — a practical necessity.
Experimental integrity: Solid, with one caution.
The COUP validation is elegant: training without positional features (distance removed) still yields 95% agreement with NWAY.
This directly proves that astrophysical features alone carry enough signal to recover the Bayesian baseline.
The caution: NWAY itself uses magnitudes in its priors, so the training labels are not entirely independent of the features.
However, the authors handle this by testing on a truly independent dataset (COUP) and by showing that results hold even when distance is withheld.
No red flags; the catalog release is a genuine contribution.
Writing quality: Competent but a bit dense in the methods section.
The description of NWAY vs LightGBM decision flow could be clarified with a single flowchart in the main text (the paper currently has one in the appendix).
The abstract oversells “no positional information” but later admits that distance is used in some models — minor inconsistency.
Rewriting the “Training data construction” paragraph (Sect 3) to explicitly state how ambiguous NWAY matches are treated would elevate the paper.
Verdict: Weak accept — the problem is important, the solution is robust and immediately useful, but the methodological novelty is incremental (applying off-the-shelf ML to a well-defined astronomical problem).
Takeaways
-
Use NWAY as a label source, not as a decision engine.
If you have a trusted but slow Bayesian method, generate a high-confidence subset, then train a fast classifier to generalize to the full dataset.
This pattern applies to any cross-matching task (radio-optical, UV-optical, etc.). -
Feature engineering from multi-wavelength data is the secret sauce.
Don’t just concatenate magnitudes; compute colors (BP-RP, G-RP) and hardness ratios.
These ratios are often more physically informative than absolute values because they cancel distance and extinction effects. -
A probabilistic decision rule with three regimes (confident, ambiguous, no-match) is more honest and useful than forcing a single match.
Practitioners can directly incorporate the “ambiguous” flag into their statistical analyses (e.g., only use single-counterpart objects for astrophysical inference, treat ambiguous ones as separate samples).
论文: 2606.19329 作者: V. Samuel Pérez-Díaz, Vinay L. Kashyap, Joshua D. Ingram, David Fouhey, Juan Rafael Martínez-Galarza, Pavlos Protopapas, Jeremy J. Drake, Dong-Woo Kim, Cecilia Garraffo 分类: astro-ph.IM, cs.LG
缺口
现有的X射线(钱德拉)与光学(盖亚)星表交叉匹配几乎完全依赖空间距离:最近邻、似然比、或像NWAY这样的贝叶斯框架(结合位置误差和源密度)。
这些方法在稀疏天区表现良好,但在拥挤区域(银道面、星团)会产生模糊匹配(一个X射线源对应多个光学候选)和假阳性(偶然靠近被误认为对应体)。
领域内缺乏系统性的方法利用两个星表共有的丰富多波段信息(星等、颜色、视差)来打破这些简并。
本文的逻辑链条:
[问题: 纯空间方法产生模糊/虚假匹配]
    |
    v
[假设: 源属性(星等、颜色、距离)具有判别能力]
    |
    v
[方法: 用NWAY构建高置信度训练集,然后用LightGBM在20个特征上训练分类器]
    |
    v
[证据: 在COUP验证集上,分类器在不使用任何位置特征时复现了95%的NWAY匹配结果]
    |
    v
[结论: 基于机器学习的交叉匹配能可靠解决模糊性并识别偶然重合]
增量
一句话: 这篇论文之前,钱德拉与盖亚的匹配意味着选最近的源并祈祷正确;之后,我们有了一个概率性星表,它知道**为什么*一个匹配是可信的,标记模糊情况而不是强行给出单一答案,并识别出约2万个纯空间方法会接受的虚假重合。
核心机制
管线首先构建候选对:每个钱德拉X射线源(25.4万)与它周围5角秒圆内的所有盖亚光学源配对(保守半径覆盖典型位置误差)。
这产生了数百万个候选对,其中绝大多数不是真实对应体。
为了训练分类器,作者先用NWAY(一种贝叶斯交叉匹配工具,结合位置、星等和局部密度)给每个候选对指派一个匹配概率。
他们只取概率>0.8的高置信度NWAY匹配作为正样本,并随机采样非匹配(没有高概率NWAY归属的对)作为负样本。
这个训练集送入梯度提升决策树(LightGBM),从约20个特征中学习:
盖亚星等(G, BP, RP)、颜色(BP-RP, G-RP)、视差及误差、X射线硬度比、以及两个源之间的距离(距离特征被包含,但模型在去除距离后仍能工作以证明天体物理特征独立有效)。
训练好的分类器为每个候选对输出一个匹配概率。
然后针对每个X射线源执行决策逻辑:
- 如果最高概率 > 0.9 → 单一对应体。
- 如果有两个或更多候选概率 > 0.5 → 模糊多重匹配(标记给用户)。
- 如果所有概率
< 0.3→ 无对应体(很可能是偶然重合)。
[数据流示意图]
钱德拉 X射线源 (25.4万)    盖亚 DR3 (1.8B)
        |                        |
        +--- 交叉匹配半径 5 角秒 ---+
                     |
               候选对 (数百万)
                     |
          +----------+----------+
          |                     |
     NWAY (贝叶斯)        特征向量: 星等,
     => 高置信标签          颜色, 视差,
          |                 硬度比,
          |                 距离(可选)
          v                     |
     训练集: 标签 + 特征         |
          |                     |
          +----------+----------+
                     |
               LightGBM 分类器
                     |
               每个候选对的匹配概率
                     |
               决策规则(阈值)
                     |
          +----------+----------+
          |          |          |
       对应体    模糊(7千)   无对应体(2万)
      (11.3万)              (纯空间方法
                             曾错误匹配)
核喻: 想象侦探对比一张模糊的监控摄像头照片(X射线源)与已知面孔数据库(盖亚源)。
老方法只看“这个人站在哪里”(空间位置)。
在人群中,很多人站的位置差不多,所以侦探选最近的,经常选错。
这篇论文给了侦探完整档案:身高(星等)、肤色(颜色)、年龄(视差→距离)、步态(X射线硬度)。
NWAY像是一个已经做了几次完美识别的专家证人;机器学习模型(LightGBM)从它学习,然后匹配剩下的所有面孔。
当档案匹配到两个同样可能的嫌疑人时,侦探标记案件为“模糊”而不是随机选一个。
当人群里所有人的档案都完全不同时,侦探正确地说“照片上的人不在这个数据库里”。
关键概念
-
交叉匹配:
不同望远镜拍摄同一片天空但看到不同“颜色”的光。
将两者结合起来需要将同一颗星或星系在不同图像中关联起来。
朴素方法:如果一个X射线点和光学点相距几角秒,它们很可能是同一个天体。
问题:X射线位置模糊(角秒级误差),在密集星团里一个误差圆内可能有5个光学候选。
交叉匹配的艺术就是决定哪一个(如果有的话)是真正的对应体。 -
NWAY:
一个贝叶斯框架,计算给定对是真实匹配的概率。
它考虑:- 位置偏移(带误差)
- 局部源密度(附近有多少其他光学星)
- 可选的星等先验(例如X射线源光学上通常较亮)。
它理论严谨,但处理数百万对计算量大,且不天然处理多个模糊解——它选最可能的一个。
这篇论文只将NWAY用于生成可靠训练标签,而不是作为最终分类器。
-
梯度提升分类器(LightGBM):
许多浅层决策树的集成,每棵树都在修正前一棵树的错误。
它速度快,能处理混合数据类型(连续值、类别),自动学习特征之间的非线性交互。
在这个问题中,它学会“蓝色光学+高X射线硬度”可能是一个吸积双星,而“红色+小视差”指向遥远的背景星系。
框架转变
之前(主流方法):              之后(本文方法):

[钱德拉源]                    [钱德拉源]
      |                              |
      | 空间半径裁切(3角秒)            | 空间包络(5角秒)
      |                              |
      v                              v
[最近的盖亚星]                 [多个盖亚候选]
      |                              |
      | 如果距离<2角秒则接受           | 计算约20个特征
      | 否则: 无匹配                   | (星等,颜色,视差...)
      |                              |
      v                              v
[单一答案, 无不确定性]         [LightGBM 为每个候选对
                                  输出概率]
                                       |
                     +------------------+------------------+
                     |                                     |
                概率>0.9:                         所有概率<0.3:
                对应体                                  无对应体
                     |                                     |
                概率0.5-0.9                    [避免了虚假匹配]
                且>1个候选:
                标记为模糊
一句话: 从依赖单一空间距离阈值到利用多维特征和机器学习概率决策,核心转变是引入了源属性信息作为判别依据。
专家评审
选题眼光: 真缺口。
钱德拉与盖亚的交叉匹配是多波段科学(例如识别X射线双星、活动星系、年轻恒星天体的对应体)的瓶颈。
模糊匹配问题众所周知,但通常针对具体科学案例临时处理。
本文提供了通用、数据驱动的解决方案,完全契合“机器学习用于天文学源关联”的发展轨迹。
方法成熟度: 巧劲而非蛮力。
核心思路是用NWAY作为标签生成器,而不是强迫它做最终决策。
LightGBM是标准工具,但特征工程(将X射线硬度与盖亚颜色结合)和概率决策规则调优得当。
可以争辩说简单的随机森林也会得到类似结果,但LightGBM的速度能扩展到数亿对——这是实际需求。
实验诚意: 扎实,有一点要注意。
COUP验证很优雅:在去除距离特征后训练仍达到95%的NWAY一致率。
直接证明了天体物理特征本身足以复现贝叶斯基准线。
需要注意:NWAY本身在其先验中使用了星等信息,所以训练标签并非完全独立于特征。
但作者通过在真正独立的COUP数据上测试,以及显示去除距离后结果仍然成立,化解了这个问题。
没有值得警惕之处;星表发布是真正的贡献。
写作功力: 合格,但方法部分略显密集。
NWAY与LightGBM决策流程的描述如果能在正文中放一张流程图会更好(论文当前在附录中)。
摘要里过分强调“无位置信息”,但后面又承认距离特征在某些模型中使用——有一处小不一致。
重写“训练数据构建”段落(第3节),明确指出NWAY模糊匹配是如何处理的,会让整篇论文提升一个档次。
判决: 弱接收 — 问题重要,解决方案稳健且立即可用,但方法论创新有限(将现成的机器学习应用到明确的天文学问题上)。
要点总结
-
用NWAY作为标签来源,而不是决策引擎。
如果你有一个可靠但缓慢的贝叶斯方法,先生成一个高置信度子集,然后用快速分类器推广到整个数据集。
这一模式可以用于任何交叉匹配任务(射电-光学、紫外-光学等)。 -
多波段数据的特征工程是秘密武器。
不要只拼接星等;计算颜色(BP-RP, G-RP)和硬度比。
这些比例通常比绝对值更具物理信息,因为它们抵消了距离和消光效应。 -
三种状态的概率决策规则(置信、模糊、无匹配)比强行单一匹配更诚实、更有用。
实践者可以直接将“模糊”标记纳入统计分析(例如只使用单一对应体目标进行天体物理推断,将模糊目标作为独立样本处理)。