Paper: 2608.06370 Authors: Ishan Patel, Sahil Sen, Elias Lumer, Vamse Kumar Subbiah Categories: cs.CL
The Gap
The “tools as code” idea has been floating around for a while. CodeAct (Wang et al.) argued that letting an LLM emit Python instead of structured actions gives it composition for free. Anthropic’s engineering posts on code execution with MCP made the same argument from a token-economics angle: if you have 50 tools, don’t paste 50 schemas into context, expose them as importable stubs and let the model write a script. Several agent frameworks shipped variants. The claim became folklore fast.
What was missing was boring but essential: a controlled comparison on an established function-calling benchmark, with the same tools, the same models, and the only difference being the invocation surface. Prior work either (a) introduced a new agent scaffold and a new benchmark together, so you cannot tell whether the scaffold or the benchmark did the work, (b) measured token savings rather than task accuracy, or (c) tested one model family, so you cannot tell whether the effect is a property of the paradigm or a property of that model’s post-training. And nobody had checked the two conditions that actually break production agents: wide parallel fan-out (call the same tool 20 times) and context rot (the tool call you need is buried under 100k tokens of prior junk).
This paper does the boring thing. 14 models, BFCL v4, two invocation surfaces, three conditions.
   [ PROBLEM ]
   "tools as code" is folklore, not measured
        |
        v
   [ ASSUMPTION ]
   code-capable models have stronger priors for
   writing Python than for emitting tool-call JSON
        |
        v
   [ METHOD ]
   hold tools + models + benchmark fixed;
   vary ONLY the invocation surface
   .------------------------.    .-----------------------.
   | native JSON tool call  | vs | typed Python stubs +  |
   | (one call per turn)    |    | sandbox exec, 1 turn  |
   '------------------------'    '-----------------------'
        |
        v
   [ EVIDENCE ]
   base:      PTC >= JSON in 11 / 14 models
   fan-out:   PTC >= JSON in 13 / 14 models
   ctx rot:   JSON -2.3% avg, PTC ~flat
   GPT-5.6 family: +10.6% over JSON
        |
        v
   [ CONCLUSION ]
   PTC is a viable default, not a niche trick;
   and the gain SCALES with model generation
   (weak models: no gain or worse)
That last clause is the paper’s actual title. The bitter lesson framing: don’t engineer a better JSON schema protocol, just let the model write code and wait for the next generation.
The Increment
One sentence: Before, “tools as code” was a plausible design pattern backed by anecdote and token-count arguments; after, it’s a measured claim with a known failure mode (weak models) and a known robustness advantage (long context), on a benchmark people already trust.
Core Mechanism
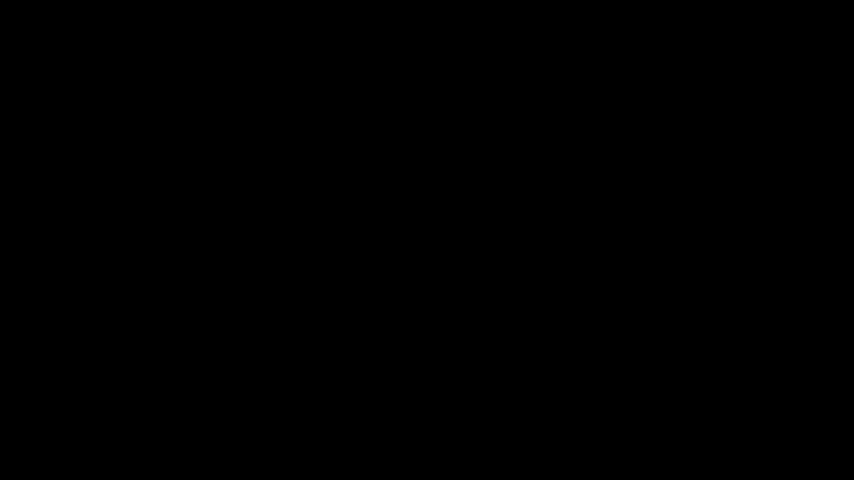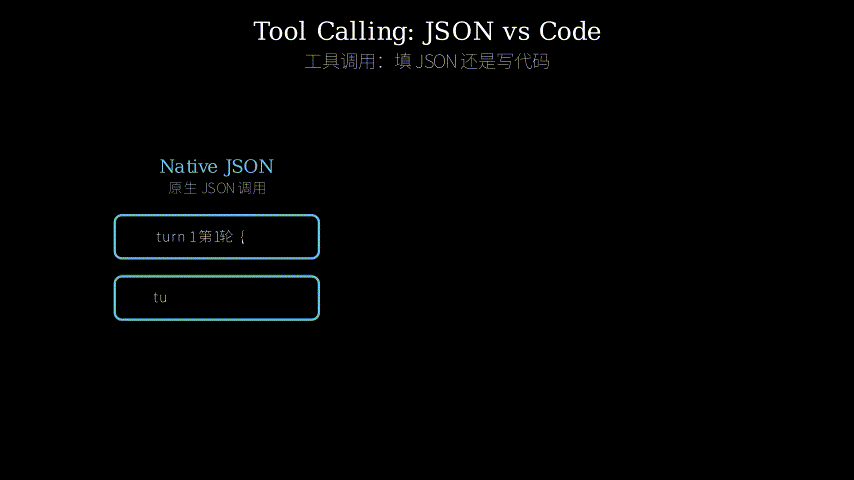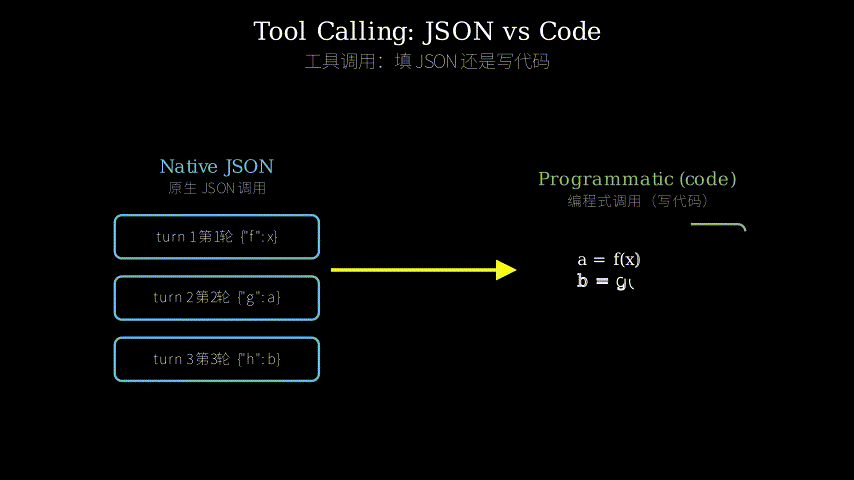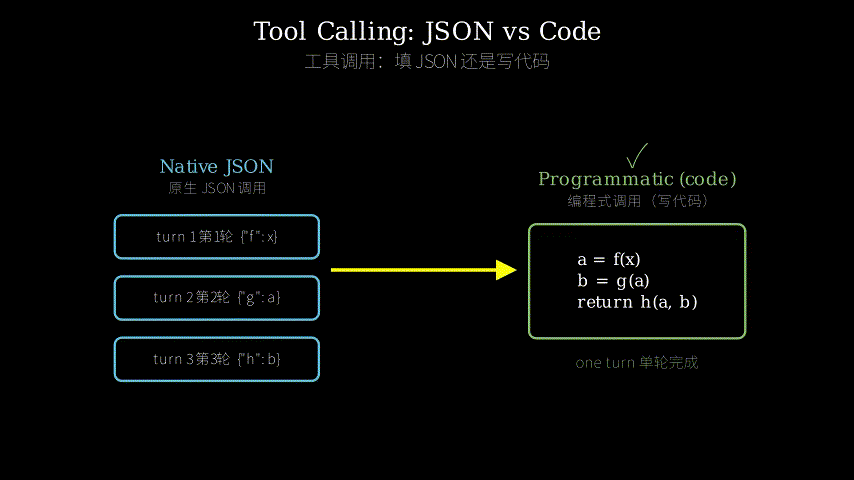
The setup is deliberately thin, which is the point. In the JSON condition, you do what every API does: dump tool schemas into the request, model emits a structured call object, harness executes it, result comes back as a tool message, next turn. Each call costs a full model round trip. Twenty parallel calls means twenty result messages threaded back through the conversation (or one batched turn, if the model supports parallel calls, which is uneven).
In the PTC condition, the harness takes the same BFCL tool definitions and compiles them into typed Python stubs — function signatures with type annotations and docstrings, in a module the model can import. The model receives these stubs as context and is asked to write a script. The script runs in a sandbox where the stub bodies are wired to the real tool implementations. Loops, conditionals, list comprehensions, intermediate variables — all of it is just Python, so chaining tool A’s output into tool B’s input never leaves the sandbox and never round-trips through the model. Crucially, execution and result handling collapse into a single agent turn: the model writes one script, the harness runs it, and only what the script prints or returns comes back.
That single-turn collapse is where the context-rot robustness comes from. In JSON mode, every intermediate result is a message in the transcript, so a 20-call task inflates context by 20 payloads, and the model has to re-read all of it on every subsequent turn. In PTC mode, the intermediate results live in Python variables inside the sandbox and never enter the model’s context at all. The model’s context stays roughly constant regardless of how many calls the script makes.
  JSON tool calling (baseline)
  ============================
   model                        harness
    |  emit {"name": f, ...}      |
    |---------------------------->| exec f
    |<----------------------------| tool_result_1  ..... enters context
    |  emit {"name": g, ...}      |
    |---------------------------->| exec g
    |<----------------------------| tool_result_2  ..... enters context
    |            ...              |
    |  N calls = N round trips = N payloads in context

  Programmatic tool calling (PTC)
  ===============================
   tool defs
      |
      v
   [ stub compiler ]  ->  tools.py :
                            def f(x: int) -> Doc: ...
                            def g(d: Doc) -> str: ...
      |
      v
   model writes ONE script
      |
      |   out = [g(f(i)) for i in ids]
      |   print(summarize(out))
      v
   [ sandbox ]  --binds stubs--> real tool impls
      |             (loops, branches, N calls
      |              all happen in here)
      v
   only stdout / return value  .....  enters context
      |
      v
   model, context still small
The metaphor: JSON tool calling is ordering at a drive-through window; PTC is handing over a shopping list.
At the drive-through, you say one item, they hand it to you, you say the next item, they hand it to you. Every item is a full exchange through the window, and everything you’ve received so far is piled on your passenger seat, in your way, for the rest of the transaction. If you want to decide item 3 based on what item 2 turned out to be, that decision has to happen at the window, out loud, with you holding up the queue.
With a shopping list, you write “get 20 apples, if the red ones are bruised get green, then weigh the total and tell me the number” and hand it to a shopper. The shopper walks the aisles, makes the conditional call about red versus green without asking you, and comes back with one number. Your car stays empty. The stub compiler is the store’s aisle directory — it tells you what’s available and in what units, so your list is writable without you having to see the shelves. The sandbox is the store. The single returned number is stdout.
Now the failure mode is obvious in the metaphor too: a shopping list only works if the shopper can read and follow conditionals. Hand a complex list to a shopper who can’t, and you get worse results than the drive-through, where you were supervising each step. That’s exactly the paper’s finding — weak/older models do worse with PTC, and the advantage tracks model generation.
Key Concepts
-
Programmatic tool calling (PTC): Instead of the model producing a data structure that names a function and its arguments, the model produces *code that calls the function. Concretely: rather than emitting
\{"name": "get_weather", "arguments": \{"city": "Tokyo"\}\}and waiting, the model writesw = get_weather("Tokyo")inside a larger script that might also loop over ten cities and compare them. The function is real — the harness has generated a Python stub whose body dispatches to the actual tool. The model never learns anything new; it just uses a skill (writing Python) that it has vastly more training data for than it does for any particular JSON tool-call format. -
Context rot: The observation that model accuracy on a task degrades as irrelevant material accumulates in context, even when the relevant material is still present and technically retrievable. It’s not a hard context-limit failure — the needle is in the window, the model just gets worse at finding and using it. This is why the paper’s single-turn collapse matters: it isn’t only cheaper, it keeps the model’s working context from filling with tool outputs that are no longer needed. The measured effect here is modest and asymmetric: JSON drops 2.3% on average, PTC stays roughly flat.
-
Parallel fan-out: A task that requires calling the same tool many times over different inputs — check inventory at 30 stores, look up 50 tickers. JSON APIs handle this with “parallel tool calls,” which is really just a batched array of call objects; support and reliability vary by model, and the results all come back as separate context payloads. In code, fan-out is a
forloop or a list comprehension, which is arguably the single most common pattern in all Python training data. This is where PTC’s win is widest (13 of 14 models), and that’s not surprising. -
BFCL v4: Berkeley Function-Calling Leaderboard, the standard benchmark for whether models call functions correctly — right function, right arguments, right handling of the multi-turn and no-call-needed cases. Using it matters because it’s a benchmark the community has already argued about and calibrated against, which removes the “new method, new benchmark” escape hatch.
Framework Shift
  Before (mainstream approach):          After (this paper):

   [ all tool schemas ]                  [ aisle directory ]
   inlined in context                    typed stubs, importable
          |                                     |
          v                                     v
   model picks ONE tool                  model writes ONE script
          |                                     |
      +---+---+                                 |
      |       |                            .----+----.
      v       v                            |  sandbox |
   turn 1  turn 2  turn 3 ...              |  loop    |
      |       |       |                    |  branch  |
      v       v       v                    |  chain   |
   result  result  result                  '----+----'
      \       |       /                         |
       \      |      /                          v
        v     v     v                     one printed answer
   [ context grows with              [ context flat regardless
     every intermediate ]              of call count ]

   control lives in the              control lives in the
   ORCHESTRATION LOOP                MODEL-WRITTEN PROGRAM
From protocol design to program synthesis: the core shift is that control flow over tools stops being something the harness orchestrates turn by turn and becomes something the model expresses once, in a language it already knows.
Expert Assessment
Problem choice: Real gap, and an unglamorous one, which is a point in its favor. The field had converged on “tools as code is better” through blog posts and framework releases without a clean controlled comparison on shared ground. Somebody had to run this. Where it sits in the trajectory: this is the consolidation paper that arrives after the idea paper, and those are undersupplied relative to their value. The bitter-lesson framing — that the right move is to let capability scaling absorb the problem rather than engineer better calling protocols — is the most interesting claim in the paper, and it’s an argument about *research direction, not just about a scaffold. It’s also the claim with the least direct evidence behind it (see below).
Method maturity: Honestly, there’s barely a method here, and I mean that neutrally. The contribution is an experimental design plus a stub compiler. That’s fine — evaluation papers are allowed to be thin on machinery — but it does mean the paper lives or dies on experimental care, and the reader should judge it as an eval paper, not a methods paper. The one genuinely non-obvious design choice is collapsing execution and result handling into a single turn, which is what produces the context-rot result. A simpler thing being underexplored: JSON tool calling with a *stateful result store (return handles, not payloads) would capture much of the context benefit without requiring code generation, and would work for non-code models. The paper doesn’t try it, and it’s the obvious middle baseline.
Experimental integrity: The baseline is fair in the important sense — same tools, same benchmark, same models. But I’d want to know how hard the JSON baseline was tuned. Native tool calling is very prompt- and schema-sensitive, and PTC gets a fresh, presumably well-iterated prompt. If the JSON condition is “whatever the provider’s default looks like,” the comparison quietly favors PTC. Second concern: 11-of-14 and 13-of-14 are vote counts, not effect sizes. “Matches or exceeds” bundles ties with wins, and on BFCL, differences of a point or two are within run-to-run noise unless you’re averaging multiple seeds. I’d want per-model deltas with variance before believing the headline framing. Third: the +10.6% on the GPT-5.6 family is doing a lot of rhetorical work for one family, and the “tracks model capability across generations” claim is drawn from a scatter of 14 heterogeneous models across different labs, training recipes, and code-capability levels — that’s suggestive, not a scaling law. Fourth: the context-rot number, 2.3% average degradation, is small. It’s directionally consistent with the mechanism, but it’s not a dramatic result and shouldn’t be sold as one. Finally, PTC requires a sandbox with real execution; any comparison that ignores sandbox failures, timeouts, and syntax errors as a cost category is understating the operational difference.
Writing quality: The abstract is doing the paper’s best work, which is usually a warning sign. The stub compiler deserves a full section — what happens with tools whose arguments are unserializable, with tools that need auth, with tools that return huge payloads the script must summarize? Those are exactly the details a practitioner needs, and they’re where PTC gets hard in production. The section I’d rewrite is the analysis of the three models where PTC *loses. That’s the most informative data in the paper and the place where the bitter-lesson thesis is either earned or not. If the losses are all on weaker or non-code-tuned models, say so with evidence and the thesis stands; if there’s a strong model in there that regresses, the story is more complicated and more interesting. Skipping that analysis is the paper’s biggest missed opportunity.
Verdict: weak accept — a needed, well-scoped controlled comparison whose headline claims are stated more strongly than vote-count metrics and small effect sizes support, but which nonetheless gives the community shared ground on a question everybody had already answered by assumption.
Takeaways
Things you can actually use:
Handles, not payloads. The transferable insight isn’t “write code” — it’s that intermediate results should live somewhere the model can *reference without reading. You can apply this without adopting PTC at all: have your tools return an ID plus a one-line summary, keep the full payload in a side store, and give the model a fetch(id) tool. Most of the context-rot benefit, none of the sandbox.
Fan-out is a loop, so make it one. If your agent’s workload is dominated by same-tool-many-inputs patterns, this is where code invocation wins widest and most reliably. It’s also the easiest thing to migrate — you don’t need to convert your whole tool surface, just the hot fan-out paths.
Gate PTC on model capability, and measure it. The paper’s real operational lesson is that this isn’t a strict upgrade. If you’re routing across a model tier (cheap model for easy turns, frontier model for hard ones), the invocation surface should probably be part of what you route on. Don’t assume the pattern that works on your best model transfers to your cheap one.
Typed stubs as the tool interface. Even if you keep JSON calling, generating typed Python stubs from your tool registry is a useful artifact: it forces you to have real types, it’s readable documentation, and it makes the migration cheap later. Cheap to build, useful regardless.
A framing worth stealing for your own eval work. Hold everything fixed and vary one surface, across a generation range of models, on a benchmark you didn’t create. Then report whether the effect grows with capability. That last step is what separates “this trick works” from “this trick is the future,” and most scaffold papers skip it.
What not to take: the +10.6% number. It’s one family, one benchmark, and the paper doesn’t give you the variance.
论文: 2608.06370 作者: Ishan Patel, Sahil Sen, Elias Lumer, Vamse Kumar Subbiah 分类: cs.CL
缺口
“把工具当代码用”这个想法已经流传一阵了。
CodeAct 论证过:让模型直接写 Python 而不是输出结构化动作,组合能力就是免费送的。
Anthropic 关于 MCP 代码执行的工程博客从 token 经济学角度讲了同一件事:有 50 个工具的时候,不要把 50 份 schema 全塞进上下文,把它们暴露成可 import 的桩函数,让模型写脚本。
好几个 agent 框架都出了自己的版本。这个说法很快变成了行业共识。
缺的东西很无聊但很要紧:一次在已有的函数调用基准上做的受控对比——同样的工具、同样的模型,唯一变的是调用界面。
此前的工作要么 (a) 同时引入新的 agent 脚手架和新的基准,于是你分不清是脚手架起作用还是基准的特性;要么 (b) 测的是省了多少 token 而不是任务准确率;要么 (c) 只测一个模型家族,于是你分不清这是范式的性质还是那个模型后训练的性质。
而且没人检查过真正让生产环境 agent 崩掉的两种条件:宽并行扇出(同一个工具调 20 次)和上下文腐化(你需要的那次调用被埋在 10 万 token 的垃圾底下)。
这篇论文就干了这件无聊的事。14 个模型,BFCL v4,两种调用界面,三种条件。
   [ 问题 ]
   "工具即代码" 是传说, 不是测量结果
        |
        v
   [ 假设 ]
   会写代码的模型, 写 Python 的先验
   远强于吐特定工具调用 JSON 的先验
        |
        v
   [ 方法 ]
   固定工具 + 模型 + 基准;
   只变调用界面
   .------------------------.    .-----------------------.
   | 原生 JSON 工具调用     | vs | 带类型的 Python 桩 +  |
   | (一轮一次调用)         |    | 沙箱执行, 单轮完成    |
   '------------------------'    '-----------------------'
        |
        v
   [ 证据 ]
   基础:     PTC >= JSON, 11 / 14 模型
   扇出:     PTC >= JSON, 13 / 14 模型
   上下文腐化: JSON 平均 -2.3%, PTC 基本不动
   GPT-5.6 家族: 相对 JSON +10.6%
        |
        v
   [ 结论 ]
   PTC 可以当默认选项, 不是小众技巧;
   而且收益随模型代际 放大
   (弱模型: 没收益, 甚至更差)
最后那句才是标题的真意。“苦涩教训”的框架是说:别去精心设计更好的 JSON schema 协议了,让模型写代码,然后等下一代模型。
增量
一句话: 之前,“工具即代码”是一个靠轶事和 token 计数支撑的合理设计模式;之后,它变成了一个在大家已经认可的基准上被测量过的论断,带着一个已知的失效模式(弱模型)和一个已知的鲁棒性优势(长上下文)。
核心机制
整个设置刻意做得很薄,这正是重点。
JSON 那一侧就是所有 API 在做的事:把工具 schema 塞进请求,模型吐出结构化调用对象,框架执行,结果作为 tool message 回来,进入下一轮。每次调用都是一个完整的模型往返。二十次并行调用意味着二十条结果消息穿回对话里(或者一轮批量搞定,前提是模型支持并行调用——而这件事各家支持程度参差不齐)。
PTC 那一侧,框架拿同样的 BFCL 工具定义,编译成带类型的 Python 桩:有类型标注和 docstring 的函数签名,放在一个模型可以 import 的模块里。模型看到这些桩,被要求写一个脚本。脚本在沙箱里跑,桩的函数体接到真正的工具实现上。循环、分支、列表推导、中间变量——全都只是 Python,所以把工具 A 的输出接到工具 B 的输入这件事,从头到尾没离开沙箱,也没往返过模型。
关键在于执行和结果处理塌缩成单轮:模型写一个脚本,框架跑一次,只有脚本 print 或返回的东西回到上下文。
这个单轮塌缩就是上下文腐化鲁棒性的来源。
JSON 模式下,每个中间结果都是对话记录里的一条消息,所以 20 次调用的任务会让上下文膨胀 20 份 payload,而模型在之后每一轮都得把这些全部重读一遍。
PTC 模式下,中间结果活在沙箱里的 Python 变量里,压根没进模型的上下文。不管脚本调了多少次工具,模型的上下文长度基本不变。
  JSON 工具调用 (基线)
  ====================
   模型                        框架
    |  吐出 {"name": f, ...}     |
    |--------------------------->| 执行 f
    |<---------------------------| tool_result_1  ..... 进入上下文
    |  吐出 {"name": g, ...}     |
    |--------------------------->| 执行 g
    |<---------------------------| tool_result_2  ..... 进入上下文
    |            ...             |
    |  N 次调用 = N 次往返 = N 份 payload 堆在上下文里

  程序化工具调用 (PTC)
  ====================
   工具定义
      |
      v
   [ 桩编译器 ]  ->  tools.py :
                       def f(x: int) -> Doc: ...
                       def g(d: Doc) -> str: ...
      |
      v
   模型写 一个 脚本
      |
      |   out = [g(f(i)) for i in ids]
      |   print(summarize(out))
      v
   [ 沙箱 ]  --桩绑定--> 真实工具实现
      |          (循环, 分支, N 次调用
      |           全都发生在这里面)
      v
   只有 stdout / 返回值  .....  进入上下文
      |
      v
   模型, 上下文依然很短
核喻:JSON 工具调用是在汽车餐厅窗口一件件点单;PTC 是把一张购物清单交给别人。
在餐厅窗口,你说一样,对方递给你一样,你再说下一样,再递一样。每件东西都是一次穿过窗口的完整交换,而且你已经拿到的所有东西都堆在副驾上,在接下来的整个交易过程中一直挡着你。
如果你想根据第 2 件东西的实际情况来决定第 3 件买什么,这个决定必须在窗口前当场大声做出来,后面的车排着队等你。
换成购物清单:你写”拿 20 个苹果,红的要是磕坏了就换青的,然后称总重量报个数给我”,交给采购员。采购员自己走遍货架,红的青的这个条件判断他自己就决定了,不用回头问你,最后带回来一个数字。你的车里始终是空的。
桩编译器是超市的货架索引——它告诉你有什么、按什么单位卖,所以你不用亲眼看见货架也能写出清单。
沙箱是超市。带回来的那个数字是 stdout。
现在失效模式在这个比喻里也一目了然:购物清单要成立,采购员得看得懂字、执行得了条件判断。把一张复杂清单交给做不到这些的采购员,结果会比在窗口一件件点更糟——因为在窗口你至少在盯着每一步。
这正是论文的发现:弱模型、老模型用 PTC 反而更差,优势随模型代际增长。
关键概念
-
程序化工具调用 (PTC): 模型不再产出一个”点名函数+参数”的数据结构,而是产出调用这个函数的代码。具体说:不是吐出
\{"name": "get_weather", "arguments": \{"city": "Tokyo"\}\}然后等着,而是在一个更大的脚本里写w = get_weather("Tokyo"),这个脚本可能还顺手循环了十个城市并做了比较。这个函数是真的——框架已经生成了一个 Python 桩,它的函数体会分派到真实工具上。模型没学任何新东西,它只是在用一项自己训练数据多得多的技能:写 Python。相比之下,任何一种特定的 JSON 工具调用格式,它见过的样本都少得可怜。 -
上下文腐化 (context rot): 指的是随着无关内容在上下文里堆积,模型在任务上的准确率会下降——即使相关内容还在里面、技术上完全取得到。这不是硬性的上下文长度溢出:针还在窗口里,只是模型找它、用它的能力变差了。这就是单轮塌缩为什么重要:它不只是更省钱,它让模型的工作上下文不被那些已经用不着的工具输出填满。不过这里测出来的效应不大也不对称:JSON 平均掉 2.3%,PTC 基本平。
-
并行扇出 (parallel fan-out): 一个任务需要用不同输入把同一个工具调很多次——查 30 家门店的库存、查 50 支股票代码。JSON API 用”并行工具调用”处理这个,本质上就是一个批量的调用对象数组;各家模型的支持程度和可靠性都不一样,而且结果全都作为独立的上下文 payload 回来。在代码里,扇出就是一个
for循环或者一句列表推导,这大概是所有 Python 训练数据里最常见的模式。所以 PTC 在这里赢得最宽(14 个模型里 13 个),一点也不意外。 -
BFCL v4: 伯克利函数调用榜,衡量模型是否正确调用函数的标准基准:函数选得对不对、参数对不对、多轮和”其实不需要调用”这些情况处理得对不对。用它很重要,因为这是社区已经吵过、已经校准过的基准,堵住了”新方法配新基准”这个逃生通道。
框架转变
  之前 (主流方法):                      之后 (本文方法):

   [ 全部工具 schema ]                   [ 货架索引 ]
   内联进上下文                          带类型的桩, 可 import
          |                                     |
          v                                     v
   模型挑 一个 工具                      模型写 一个 脚本
          |                                     |
      +---+---+                                 |
      |       |                            .----+----.
      v       v                            |   沙箱   |
    轮1     轮2    轮3 ...                 |  循环    |
      |       |      |                     |  分支    |
      v       v      v                     |  串联    |
    结果    结果    结果                    '----+----'
      \      |      /                           |
       \     |     /                            v
        v    v    v                        一个打印的答案
   [ 每个中间结果                    [ 上下文长度与调用次数
     都让上下文变长 ]                  无关, 基本恒定 ]

   控制流住在                        控制流住在
   编排循环 里                       模型写的程序 里
一句话:从协议设计到程序合成,核心转变是——工具之上的控制流不再由框架逐轮编排,而变成模型用它本来就会的语言一次性表达出来的东西。
专家评审
选题眼光: 真缺口,而且是个不体面的缺口,这反而是加分项。
整个领域靠博客和框架发布就收敛到了”工具即代码更好”,却没人在共同地基上做过干净的受控对比。这活总得有人干。
在发展轨迹上的位置:这是想法论文之后该来的那篇整理论文,而这类论文的供给相对于它们的价值一直不足。
“苦涩教训”这个框架——正确的动作是让能力增长把问题吸收掉,而不是去设计更好的调用协议——是全文最有意思的论断,而且它是关于研究方向的论证,不只是关于一个脚手架。它同时也是全文证据最薄的那个论断(见下)。
方法成熟度: 说实话这里几乎没有方法,我说这话不带贬义。
贡献是一套实验设计加一个桩编译器。这没问题——评测论文本来就允许机械部分很薄——但这意味着这篇论文的生死全押在实验的细致程度上,读者也该按评测论文而不是方法论文来判它。
唯一一个真正不显然的设计选择是把执行和结果处理塌缩成单轮,这正是产出上下文腐化结果的那一步。
有个更简单的东西没被探索:带状态结果存储的 JSON 工具调用——返回句柄而不是 payload。这能拿到上下文收益的大部分,却不需要模型会写代码,对非代码模型也适用。论文没试,而这是最该有的中间基线。
实验诚意: 基线在重要的意义上是公平的——同工具、同基准、同模型。
但我想知道 JSON 基线被调优到什么程度。原生工具调用对 prompt 和 schema 极其敏感,而 PTC 拿到的是一个全新的、大概反复迭代过的 prompt。如果 JSON 那一侧就是”厂商默认长什么样就什么样”,这个对比就在暗中偏向 PTC。
第二个顾虑:11/14 和 13/14 是票数,不是效应量。“匹配或超过”把平局和胜局打包在一起了,而在 BFCL 上,一两个点的差异如果不是多种子平均,基本在运行间噪声里。我想看每个模型的 delta 和方差,再决定信不信这个标题式说法。
第三:GPT-5.6 家族那个 +10.6% 承担了太多修辞任务,而它只是一个家族。“性能随模型代际提升”这个论断,是从 14 个来自不同实验室、不同训练配方、不同代码能力水平的异质模型散点里读出来的——这是提示性的,不是 scaling law。
第四:上下文腐化那个 2.3% 平均降幅很小。它方向上和机制一致,但不是一个戏剧性的结果,不该被卖成戏剧性的。
最后,PTC 需要一个真能执行的沙箱;任何忽略沙箱失败、超时、语法错误这些成本项的对比,都在低估两者的运维差距。
写作功力: 摘要写得比正文好,这通常是个警报。
桩编译器该有一整节:参数不可序列化的工具怎么办?需要鉴权的工具怎么办?返回巨大 payload、必须让脚本先做摘要的工具怎么办?这些恰恰是实践者需要的细节,也是 PTC 在生产里变难的地方。
我最想重写的一节是对 PTC 输掉的那 3 个模型的分析。那是全文信息量最大的数据,也是”苦涩教训”这个主论点站得住或站不住的地方。
如果这些败例全落在弱模型或没做代码调优的模型上,就用证据把它说清楚,主论点成立;如果里面混着一个强模型出现了退化,那故事就更复杂、也更有意思。跳过这段分析是全文最大的机会损失。
判决: 弱接收 —— 一次必要且边界清楚的受控对比,标题式论断的强度超过了票数指标和小效应量所能支撑的程度,但它确实给一个大家早已凭假设回答完的问题提供了共同地基。
要点总结
真能拿去用的东西:
要句柄,不要 payload。 可迁移的洞见不是”写代码”,而是:中间结果应该存在一个模型能引用但不必读取的地方。这一条你完全可以不采用 PTC 也用上——让工具返回一个 ID 加一行摘要,完整 payload 放在旁路存储里,再给模型一个 fetch(id) 工具。上下文腐化的收益你拿到大半,沙箱一个都不用。
扇出就是循环,那就让它是循环。 如果你 agent 的负载以”同一工具多输入”为主,这就是代码调用赢得最宽、最稳的地方。它也是最好迁移的:不用把整个工具面转过去,只转热的扇出路径。
按模型能力给 PTC 开关,并且去测。 这篇论文真正的运维教训是:这不是无条件升级。如果你在做模型分层路由(简单轮次用便宜模型,难的用前沿模型),调用界面大概也该成为路由维度之一。不要假设在你最好的模型上成立的模式能迁移到便宜的那个。
把带类型的桩当工具接口。 就算你继续用 JSON 调用,从工具注册表生成带类型的 Python 桩也是个有用的产物:它逼你真的把类型写清楚,它本身就是可读文档,而且以后迁移会很便宜。造起来便宜,怎么都有用。
一个值得偷走的评测框架。 固定一切,只变一个界面,跨一整个代际范围的模型,在一个不是你自己造的基准上做。然后报告效应是否随能力增长。最后那步才是”这招有用”和”这招是未来”的分界,而大多数脚手架论文都跳过了它。
不该拿走的:那个 +10.6%。一个家族、一个基准,而且论文没给你方差。