Paper: 2608.11191 Authors: Shiyu Xuan, Zechao Li Categories: cs.AI, cs.CL, cs.CV
The Gap
GUI visual grounding is the unglamorous bottleneck of every GUI agent: given a screenshot and an instruction like “open the export options,” produce the pixel coordinates to click. Everything downstream (planning, memory, tool use) fails silently if this fails.
The field’s answer so far has been more training data before deployment. SeeClick, OS-Atlas, UGround, Aria-UI, UI-TARS all scale grounding corpora — synthetic web renders, accessibility trees, mobile UI dumps — then ship frozen weights. This works remarkably well on interfaces resembling the training distribution and degrades badly on the ones that don’t: CAD tools, industrial control panels, obscure enterprise software, anything at 4K with 12-pixel icons (the ScreenSpot-Pro problem).
The obvious fix is test-time adaptation, and a recent line of work does exactly that with test-time RL: sample multiple predictions on an unlabeled test screen, use self-consistency or majority vote as a pseudo-reward, and run a policy gradient step. The limitation the authors target is precise. A scalar reward tells the model that it was wrong, not why. When all K rollouts cluster on the wrong icon — which is the common failure mode, since grounding errors are systematic rather than random — voting confidently rewards the wrong answer. And when the reward is zero, the gradient carries almost no information about which direction to move. There is no mechanism for reflection: no way for the model to represent “I clicked the search bar, but the instruction was about the filter control, which sits to its right.”
This paper’s bet: an MLLM can look at a screenshot plus a predicted click point and articulate the miss in words, and the same policy model, when handed those words in its context, will produce a better coordinate distribution — which can then be distilled back into weights.
[Problem] weights freeze at deploy time
          unseen UI (dense, high-res, domain-specific) => grounding misses
              |
              v
[Prior art]
   +-- train-time scaling: bigger grounding SFT corpora .... still frozen
   +-- test-time RL: self-consistency / vote as reward .... scalar only
            |
            +-- failure yields one bit: "wrong"
            +-- no direction, no cause
            +-- correlated errors => vote confidently endorses the miss
              |
              v
[Assumption] (a) a critic MLLM can name the cause of a miss in text
             (b) the policy can *use* that text if it is in context
             (c) => context-conditioned policy is a free teacher
              |
              v
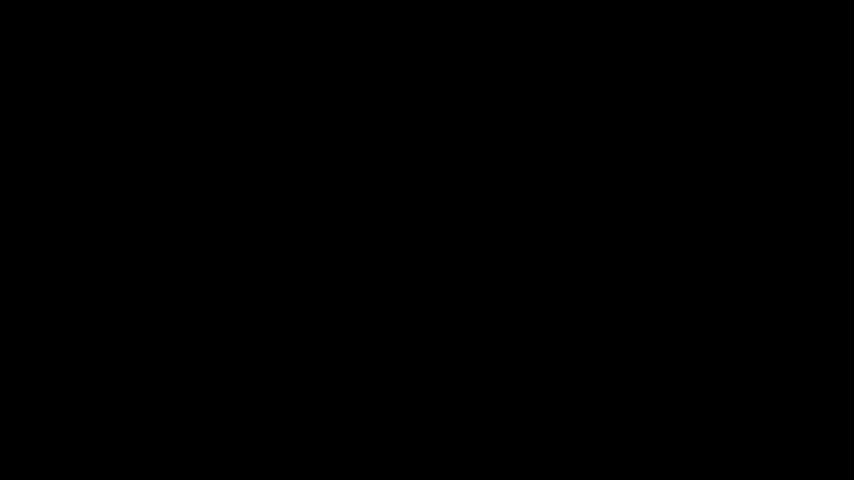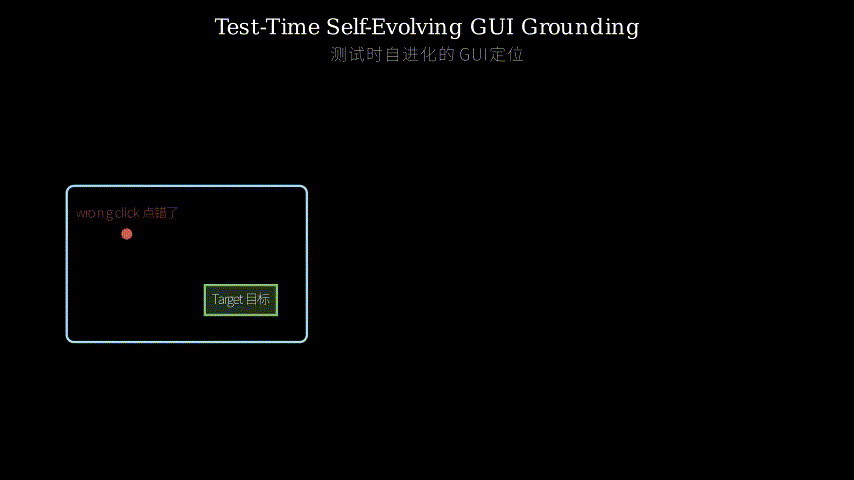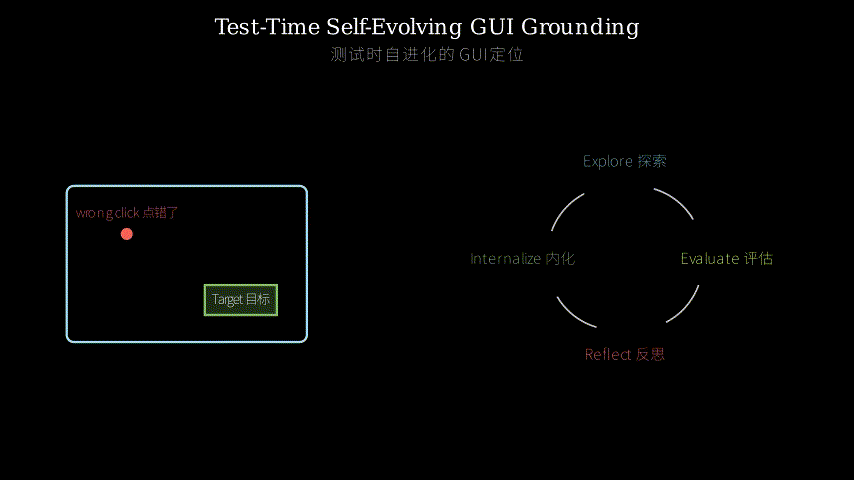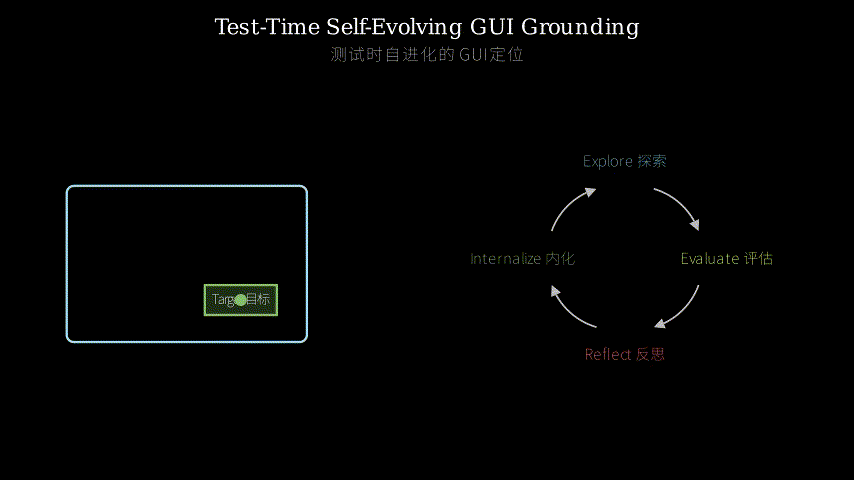
[Method] closed loop: Explore > Evaluate > Reflect > Internalize
         reflection-conditioned self-teacher => token-level KL
         + contrastive calibration to de-noise failed prefixes
              |
              v
[Evidence] 6 grounding benchmarks, +7.4% average over base model
              |
              v
[Conclusion] label-free post-deployment self-improvement is feasible;
             the "self-evolving agent" loop gains its missing leg
The Increment
One sentence: Before, a grounding model’s only test-time learning signal was a scalar “right/wrong”; after, it is a sentence explaining the miss, mechanically converted into a per-token target distribution the model can actually descend on.
Core Mechanism
The loop has four stations. Exploration: the policy samples K coordinate predictions for an instruction on an unlabeled screen — on-policy, meaning the training data is the model’s own current behavior, not a fixed corpus. Evaluation and Reflection: a Reflector MLLM receives the instruction, the screenshot (in practice, almost certainly a crop around the predicted point plus global context), and the prediction, then emits a verdict and a natural-language reflection describing what the region actually contains versus what was asked for.
Internalization is where the real engineering lives, because you cannot backpropagate a sentence into a coordinate head. The trick is a *conditioned self-teacher: take the same policy weights, prepend the reflection text to the context, and re-run the forward pass. That gives a distribution over coordinate tokens that is strictly better informed than the student’s — not because the teacher is a bigger model, but because it has been handed privileged information the student lacks at deployment. Minimizing token-level KL from this teacher to the unconditioned student compresses “knowing the reflection” into the weights. This is context distillation, applied on-policy, at test time.
Contrastive Calibration patches the failure case. Coordinate generation is autoregressive, so on a failed rollout the prefix is already corrupted — if the first digits of *x are wrong, every subsequent teacher distribution is conditioned on a bad history and its “corrected” targets are partly just the original mistake wearing a new hat. The calibration contrasts the reflection-conditioned logits against an unconditioned (or negatively conditioned) pass and keeps the difference, so the supervisory signal isolates what the reflection added rather than what the broken prefix implied. It is contrastive decoding repurposed as a target-denoising operator.
                    unlabeled test stream
                              |
                              v
      +--------------------------------------------------+
      |  1. EXPLORE   policy pi_theta                    |
      |  (screenshot, instruction) -> (x, y)             |
      |  sample K rollouts   == on-policy data           |
      +--------------------------------------------------+
                              |
                       rollouts r_1 .. r_K
                              v
      +--------------------------------------------------+
      |  2. EVALUATE  +  3. REFLECT     Reflector MLLM   |
      |  crop around (x,y) + instruction + global view   |
      |  -> verdict  : hit / miss                        |
      |  -> reflection z : what is there vs what was     |
      |                    asked, where the target lies  |
      +--------------------------------------------------+
                              |
              +---------------+----------------+
              |                                |
        successful rollout               failed rollout
              |                                |
              v                                v
   teacher pi( . | s, z )          teacher pi( . | s, z ) but the
   targets are trustworthy         prefix is already wrong
              |                                |
              |                                v
              |                CONTRASTIVE CALIBRATION
              |                q ~ softmax( logits( . | s, z )
              |                     - a * logits( . | s, z_neg ) )
              |                keep only what z contributed
              |                                |
              +---------------+----------------+
                              v
      +--------------------------------------------------+
      |  4. INTERNALIZE   on-policy self-distillation    |
      |  min_theta  sum_t KL( q_t || pi_theta( . | h_t ) )|
      |  teacher and student share weights;              |
      |  only the context differs                        |
      +--------------------------------------------------+
                              |
                              v
                  updated theta > next screen
The metaphor: a golf coach standing behind a player on a practice range.
The player takes a swing — that is exploration, and it must be the player’s own swing, not a textbook one, because the flaw only shows up in their actual motion (on-policy). The coach watches the ball slice right and says “your shoulders opened before your hips” — that is the Reflector: a verdict plus a cause, in words.
Here is the problem every coach faces: words do not become muscle memory. Telling someone about shoulder rotation does not change their swing. So the coach does the thing that actually works — puts a hand on the player’s shoulder and lets them swing with the hand there. The swing is now correct, and crucially it is still the player’s own body producing it. That guided swing is the conditioned self-teacher: same athlete, same muscles, one extra piece of external information present during execution. The player then practices reproducing that exact feel with the hand removed — that is the KL distillation step, transferring the guided motion into unguided weights.
Contrastive calibration is the coach’s discernment about which parts of the guided swing to keep. If the player’s grip was already wrong before the hand went on their shoulder, the guided swing still contains that bad grip; naively imitating the whole guided motion would ingrain the flaw along with the fix. So the coach mentally subtracts the unguided swing from the guided one and drills only the difference — the shoulder timing, not the grip. Same logic: subtract the unconditioned logits, keep what the reflection contributed.
And because there is no scorecard on the practice range — no ground truth labels at test time — the whole loop runs on the coach’s eye alone. Which, as we will get to, is exactly where the load-bearing risk sits.
Key Concepts
-
GUI visual grounding: The model’s job is regression disguised as text generation. Input: a screenshot and a phrase. Output: a coordinate, usually emitted as literal digit tokens like
(0.42, 0.81)or(806, 314). This has an odd consequence — the “answer” is a handful of tokens where the *first ones matter most. Getting0.4vs0.7for x is the whole ballgame; the trailing digits are refinement. That asymmetry is why prefix corruption is such a serious problem here and why the paper needs a fix for it. In a normal text task, a wrong early token drifts you into a different but coherent sentence. Here, a wrong early token means you have already clicked in the wrong half of the screen and everything downstream is decoration. -
On-policy self-distillation: “Distillation” normally means a big teacher and a small student. Here teacher and student are byte-identical weights — the only difference is what sits in the context window. The teacher sees the reflection; the student does not. So you are not transferring knowledge between models, you are transferring knowledge from *a prompt into parameters. Why bother, instead of just always putting the hint in the prompt? Because at deployment there is no hint — nobody will be there to tell the agent it clicked the wrong icon. The hint exists only during the adaptation loop, so it has to be baked into weights to be useful later. “On-policy” means the sequences being scored are the model’s own fresh samples, so the supervision lands exactly where the model’s current probability mass actually is, rather than on hypothetical trajectories it would never produce.
-
Contrastive calibration as denoising: Take two forward passes over the same corrupted prefix — one with the reflection in context, one without — and subtract the logits. Whatever both passes agree on is the model’s prior, including its confident mistake; whatever *differs is attributable to the reflection. Concrete version: the model has committed to
(0.7for x when the true target is at 0.35. Both passes will keep pushing plausible continuations of 0.7 because that is what the prefix demands. The reflection-conditioned pass, however, tilts slightly toward “further left.” Subtracting isolates that tilt and amplifies it into the training target, instead of letting the shared 0.7-consistent mass drown it out. This is the same operator as contrastive decoding or classifier-free guidance, just aimed at constructing a distillation target rather than sampling text.
Framework Shift
Before (test-time RL):              After (this paper):

  screenshot + instruction            screenshot + instruction
          |                                    |
          v                                    v
     sample K rollouts                    sample K rollouts
          |                                    |
          v                                    v
   vote / self-consistency            Reflector: text z = the cause
          |                                    |
          v                                    v
   reward r in \{0,1\}                  same weights + z in context
   one scalar per sequence             = better token distribution
          |                                    |
          v                                    v
   policy gradient nudges              per-token KL target
   the whole sequence                  (calibrated on failures)
          |                                    |
          v                                    v
   failure teaches: "no"               failure teaches:
   correlated errors =>                "no, and the target is left
   vote endorses the miss               of where you clicked"
From scalar reward to token-level target, the core shift is that failure stops being a single bit of bad news and becomes a described cause, and the model itself — merely by being told that cause — manufactures the supervision it needs.
Expert Assessment
Problem choice: A real gap, and well-located. The self-evolving-agent literature has memory, planning, and tool-use adaptation reasonably covered while perception stays frozen, which is a genuine asymmetry. Grounding is also the *right place to attempt test-time adaptation: the output space is tiny and low-dimensional, verification is cheap (crop a region, ask what is in it), and distribution shift between interfaces is severe and obvious. Nothing manufactured here. The narrower claim — “first to exploit on-policy self-distillation for test-time adaptation in GUI grounding” — is the usual triple-qualified first, but the underlying problem does not need that framing to be worth doing.
Method maturity: The conditioned self-teacher is the good idea, and it is clean: it solves a real type mismatch (text feedback, coordinate output) without introducing a reward model or a critic head. Contrastive calibration is the sharper insight — noticing that autoregressive prefix corruption poisons distillation targets on exactly the samples you most want to learn from, and reaching for a contrastive-decoding operator to fix it. That is the part I would expect to outlive the paper.
The obvious simpler baseline is looming, though, and how the paper handles it determines its worth: if you have a Reflector good enough to diagnose misses, why not just run verify-and-retry at inference — reject-sample until the critic approves, with zero weight updates? That is training-free, has no drift risk, and plausibly captures a large share of the reported gain. The paper’s value depends entirely on showing that the internalized version beats it at matched test-time compute, and that the improvement transfers to screens where the Reflector is no longer in the loop. Also worth interrogating: how much of the gain is any form of self-distillation versus the specific reflection mechanism. An ablation with the verdict only (hit/miss, no explanation) fed to the conditioned teacher is the load-bearing experiment.
Experimental integrity: +7.4% average over six benchmarks is a plausible, non-suspicious number for this kind of adaptation. The things I would check before believing it:
Whose knowledge is being distilled? If the Reflector is a substantially stronger model (GPT-4o class, or a larger open MLLM), then “self-evolving” is doing rhetorical work that “test-time distillation from a stronger critic” would do more honestly. That is still a useful result — but it is a different result, and the compute accounting changes completely.
Transductive leakage. Adapting on the test set, even without labels, is not comparable to frozen-model evaluation. Whether weights reset per sample, per benchmark, or accumulate across the whole test stream matters enormously, and results should be shown to be robust to sample ordering. Accumulating updates driven by an imperfect critic is a drift generator; I would want to see what happens after several thousand adaptation steps, not just the aggregate delta.
Where the gain lands. Average deltas over six benchmarks can hide a lot. If ScreenSpot-Pro (high-res, professional software, small targets — the actual motivating failure case) barely moves while easier benchmarks carry the average, the story weakens considerably. Conversely, gains concentrated on the hard benchmarks would be the strongest possible evidence.
Reflector reliability. The entire loop’s ceiling is the critic’s precision and recall on verdicts. There is no ground truth anywhere, so a critic that says “hit” on near-misses will actively teach the model to be sloppy. This deserves a measured table, not a sentence.
Cost. K rollouts, plus a Reflector call, plus two extra forward passes for calibration, plus a gradient step — per screen. For a system whose entire purpose is real-time interaction, latency and memory are not a footnote.
Writing quality: From the abstract’s structure, the four-station loop and the distillation math will be well-served, and I would bet the corner-cutting is in two places. First, the Reflector is treated as an oracle: prompt design, verdict accuracy, and behavior under confidently-wrong critiques are the kind of thing that gets one paragraph and deserves a full analysis section. Second, the cost accounting. The section that would elevate the whole paper is an honest, quantified head-to-head against training-free verify-and-retry at matched compute, plus reflector-accuracy numbers — because that section is the difference between “interesting mechanism” and “you should actually deploy this.” As written, the abstract’s closing flourish (“completes the self-evolving capability of GUI agents”) overreaches for what is a well-executed component contribution.
Verdict: weak accept — the conditioned-self-teacher plus contrastive-calibration pairing is a genuinely clean solution to the text-feedback-into-coordinate-supervision mismatch, but the headline gain rests on an unexamined external critic and an unstated compute budget, and the paper lives or dies on ablations the abstract does not promise.
Takeaways
The hint-distillation pattern is the transferable asset. Whenever you have information available during a training or adaptation loop that will be absent at inference — a reference answer, a critic’s diagnosis, a future observation, a privileged sensor — you do not need a separate teacher model. Put the information in the context, run a forward pass, and distill that distribution into the no-context version of the same weights. This generalizes far past GUIs: code repair with test failure logs available at adaptation time but not at generation time, SQL with schema hints, robot policies with post-hoc trajectory annotations.
Contrastive subtraction turns a noisy teacher into a usable one. If your teacher shares the student’s biases (which is guaranteed when they share weights), the raw teacher distribution is mostly redundant with the student and the useful signal is small. Subtracting an unconditioned pass isolates the delta attributable to the hint. Cheap, general, and applicable anywhere you build targets from a conditioned model — reward modeling, preference data synthesis, self-critique pipelines.
Prefix corruption is a specific, nameable failure of self-distillation on failed rollouts. This is worth internalizing beyond this paper. If you are distilling onto your own sampled sequences, the samples you most need to learn from are precisely the ones whose histories are already wrong, and the teacher’s targets on those histories are contaminated by the error. Most self-improvement pipelines just filter failures out and throw away the signal; this paper repairs them instead. If you have been discarding negative rollouts, that is a design decision you should revisit.
Pick tasks where verification is cheaper than generation. The reason this framework is tractable for grounding and would be miserable for, say, long-horizon planning is that checking a click means cropping a 100x100 region and asking “what is this?” — far easier than producing the coordinate from a full screenshot. When you are looking for a place to attempt label-free self-improvement, that asymmetry is the thing to search for first.
What not to take: the “self-evolving” framing. If a stronger external model supplies every learning signal, the honest description is test-time distillation with a critic in the loop, and describing it accurately makes it easier to reason about where the ceiling is.
论文: 2608.11191 作者: Shiyu Xuan, Zechao Li 分类: cs.AI, cs.CL, cs.CV
缺口
GUI 视觉定位是所有 GUI Agent 最不起眼但最要命的一环:给一张截图和一句”打开导出选项”,输出该点击的像素坐标。
这一步错了,后面的规划、记忆、工具调用全部静默失效——Agent 不会报错,它只是点了个奇怪的地方然后继续自信地往下走。
这个领域此前的答案是”部署前灌更多数据”。
SeeClick、OS-Atlas、UGround、Aria-UI、UI-TARS 都在扩大定位语料——合成网页渲染、可访问性树、移动端 UI dump——然后冻结权重发布。
在与训练分布相似的界面上效果确实很好,遇到不相似的就迅速崩塌:CAD 工具、工业控制面板、冷门企业软件、4K 分辨率下 12 像素的图标(也就是 ScreenSpot-Pro 揭示的那类问题)。
顺理成章的补丁是测试时适应,最近确实有一批工作在做测试时 RL:在无标注的测试截图上采样多个预测,用自一致性或多数投票当伪奖励,跑一步策略梯度。
本文瞄准的局限说得很准:标量奖励只告诉模型”错了”,不告诉它”错在哪”。
更糟的是,定位错误往往是系统性的而非随机的——K 次采样经常齐刷刷地落在同一个错误图标上,此时投票会自信地奖励错误答案。
而当奖励为零时,梯度里几乎不含”该往哪个方向挪”的信息。
整个流程缺少”反思”这个环节:模型没有任何机制表达”我点在了搜索框上,但指令说的是它右边那个筛选控件”。
本文的赌注是:一个 MLLM 能看着截图和预测点,用自然语言说出错在哪;而同一个策略模型,一旦把这句话放进它的上下文,就会输出更好的坐标分布——这个更好的分布可以被蒸馏回权重里。
[问题] 部署即冻结权重
       陌生界面(高密度、高分辨率、垂直领域)=> 定位失手
            |
            v
[已有做法]
   +-- 训练时扩展:更大的定位 SFT 语料 ...... 仍然是冻结的
   +-- 测试时 RL:自一致性 / 投票当奖励 ...... 只有标量
          |
          +-- 失败只给出 1 bit:"错了"
          +-- 没有方向,没有原因
          +-- 错误相关 => 投票反而给错误答案盖章
            |
            v
[假设] (a) 批评型 MLLM 能用文字说出失手的原因
       (b) 策略模型只要看到这段文字就能用上它
       (c) => 条件化后的策略本身就是一个免费教师
            |
            v
[方法] 闭环:探索 > 评估 > 反思 > 内化
       反思条件化的自教师 => token 级 KL
       + 对比校准,给失败前缀去噪
            |
            v
[证据] 6 个定位基准,相对基座模型平均 +7.4%
            |
            v
[结论] 无标注的部署后自我改进是可行的;
       "自进化 Agent"补上了缺的那条腿
增量
一句话:以前定位模型在测试时能拿到的学习信号只有一个”对/错”的标量,现在是一句解释失手原因的话,并且被机械地转换成模型真正能沿着下降的逐 token 目标分布。
核心机制
闭环有四站。
探索:策略在无标注截图上对一条指令采样 K 个坐标预测——这是 on-policy 的,训练数据就是模型当下的真实行为,不是固定语料。
评估与反思:Reflector MLLM 接收指令、截图(实际实现里几乎肯定是预测点周围的裁剪块加上全局视图)和预测结果,输出一个判定,以及一段自然语言反思,说明那个区域实际上是什么、指令要的是什么、目标大概在哪个方向。
内化是真正的工程所在,因为你没法把一句话反向传播进坐标输出。
关键手法是条件化自教师:拿同一份策略权重,把反思文本塞进上下文,重新跑一次前向。
得到的坐标 token 分布严格优于学生的分布——不是因为教师更大,而是因为它握有学生在部署时拿不到的特权信息。
最小化从这个教师到无条件学生的 token 级 KL,就是把”知道这段反思”压进权重。
本质上是 context distillation,被搬到了 on-policy、测试时的场景里。
对比校准补的是失败情形的漏洞。
坐标是自回归生成的,所以失败样本的前缀本身就已经坏了——如果 x 的头几位数字就错了,后续每一步教师分布都建立在错误历史上,它给出的”修正”目标里有相当一部分只是原来那个错误换了层皮。
校准的做法是把”有反思条件”的 logits 和”无反思(或负向反思)条件”的 logits 相减,只保留差值,于是监督信号里剩下的是反思带来的增量,而不是坏前缀本身的惯性。
这是把对比解码改造成了一个目标去噪算子。
                      无标注测试流
                              |
                              v
      +--------------------------------------------------+
      |  1. 探索   策略 pi_theta                          |
      |  (截图, 指令) -> (x, y)                           |
      |  采样 K 条 rollout   == on-policy 数据            |
      +--------------------------------------------------+
                              |
                       rollout r_1 .. r_K
                              v
      +--------------------------------------------------+
      |  2. 评估  +  3. 反思     Reflector MLLM           |
      |  (x,y) 周围裁剪 + 指令 + 全局视图                  |
      |  -> 判定   : 命中 / 失手                          |
      |  -> 反思 z : 那里是什么 vs 要的是什么,            |
      |              目标在哪个方向                        |
      +--------------------------------------------------+
                              |
              +---------------+----------------+
              |                                |
        成功的 rollout                   失败的 rollout
              |                                |
              v                                v
   教师 pi( . | s, z )              教师 pi( . | s, z ),但
   目标可信                          前缀本身已经是错的
              |                                |
              |                                v
              |                       对比校准
              |                q ~ softmax( logits( . | s, z )
              |                     - a * logits( . | s, z_neg ) )
              |                只留下 z 贡献的那部分
              |                                |
              +---------------+----------------+
                              v
      +--------------------------------------------------+
      |  4. 内化   on-policy 自蒸馏                       |
      |  min_theta  sum_t KL( q_t || pi_theta( . | h_t ) )|
      |  教师与学生共享同一份权重;                        |
      |  唯一的差别是上下文                                |
      +--------------------------------------------------+
                              |
                              v
                   更新后的 theta > 下一屏
核喻:练习场上站在学员身后的高尔夫教练。
学员挥一杆——这是探索,而且必须是他自己的挥杆,不是教科书动作,因为毛病只在他真实的动作里显形(这就是 on-policy)。
教练看着球右曲,说”你的肩膀比髋部先打开”——这是 Reflector:一个判定加一个原因,用语言表达。
接下来是每个教练都要面对的难题:语言不会变成肌肉记忆。
跟人讲肩部转动的道理,改不了他的挥杆。
于是教练做那件真正有效的事——把手搭在学员肩上,让他带着这只手再挥一次。
这一杆动作对了,而且关键在于,产生这个动作的仍然是学员自己的身体。
这一杆就是条件化自教师:同一个运动员、同一组肌肉,只是执行过程中多了一份外部信息在场。
然后学员反复练习,在手撤走的情况下复现那个手感——这就是 KL 蒸馏那一步,把”被辅助的动作”迁移进”无辅助的权重”。
对比校准则是教练的分辨力:被辅助的那一杆里,哪些部分值得练。
如果学员在手搭上肩之前握杆就是错的,那被辅助的挥杆里仍然带着这个错误握法;不加区分地整体模仿,就会把毛病和修正一起刻进去。
所以教练在心里把”无辅助那一杆”从”被辅助那一杆”里减掉,只练差值——练肩部时序,不练握法。
同一个逻辑:减掉无条件 logits,只留反思贡献的部分。
还有一点必须说清:练习场上没有记分卡——测试时没有任何 ground truth——整个闭环完全跑在教练那双眼睛上。
而这,正如后面会讲到的,恰恰是全部风险的承重点。
关键概念
-
GUI 视觉定位:这个任务本质是回归,只是伪装成文本生成。输入截图加一句话,输出坐标,通常以字面数字 token 的形式吐出来,比如
(0.42, 0.81)。这带来一个奇特后果:答案只有几个 token,而最前面的那几个决定一切。x 是 0.4 还是 0.7 就是全部胜负,后面的位数只是精修。这种不对称正是”前缀污染”在这里格外致命的原因,也是本文必须专门处理它的原因。普通文本任务里早期 token 错了,你只是漂进了另一句同样通顺的话;这里早期 token 错了,意味着你已经点在了屏幕的另一半,后面全是装饰。 -
On-policy 自蒸馏:通常说蒸馏是大教师带小学生。这里教师和学生是逐字节相同的权重,唯一差别是上下文窗口里装了什么:教师看得到反思,学生看不到。所以你不是在模型之间搬知识,你是在把知识从一段 prompt 搬进参数。那为什么不干脆一直把提示放在 prompt 里?因为部署时没有提示——不会有人在旁边告诉 Agent 它点错了图标。提示只存在于适应闭环期间,所以必须烧进权重才能在之后派上用场。而”on-policy”意味着被打分的序列是模型刚刚采出来的,监督信号正好落在模型当前概率质量真实所在的位置,而不是落在它根本不会产生的假想轨迹上。
-
对比校准即去噪:在同一个(已被污染的)前缀上跑两次前向,一次带反思、一次不带,然后把 logits 相减。两次都同意的部分是模型的先验,其中包含它那个自信的错误;有差异的部分才归因于反思。具体点:真实目标在 x=0.35,模型已经写出了
(0.7。两次前向都会继续推 0.7 的合理续写,因为前缀就要求这样。但带反思那一次会稍微向”再往左”倾斜。相减把这个倾斜分离出来并放大成训练目标,而不是让共有的、与 0.7 一致的概率质量把它淹掉。这个算子和对比解码、无分类器引导是同一个东西,只是用来构造蒸馏目标而不是采样文本。
框架转变
之前(测试时 RL):                  之后(本文方法):

    截图 + 指令                          截图 + 指令
        |                                    |
        v                                    v
    采样 K 条 rollout                    采样 K 条 rollout
        |                                    |
        v                                    v
   投票 / 自一致性                  Reflector:文字 z = 原因
        |                                    |
        v                                    v
   奖励 r in \{0,1\}                  同一份权重 + z 进上下文
   每条序列一个标量                    = 更好的 token 分布
        |                                    |
        v                                    v
   策略梯度整条序列                   逐 token 的 KL 目标
   一起被推一把                       (失败样本经过校准)
        |                                    |
        v                                    v
   失败教给你:"不对"                 失败教给你:
   错误相关 =>                        "不对,而且目标在
   投票给失手盖章                      你点的位置左边"
一句话:从标量奖励到 token 级目标,核心转变是失败不再是一个比特的坏消息,而是一条被描述出来的原因;而模型仅凭”被告知这条原因”,就自己造出了所需的监督信号。
专家评审
选题眼光:真缺口,而且位置选得好。
自进化 Agent 这条线里,记忆、规划、工具使用的适应都有人做,唯独感知一直冻着,这是个实实在在的不对称。
定位也确实是尝试测试时适应的正确落点:输出空间极小且低维,验证便宜(裁一块图问问里面是什么),界面之间的分布漂移又剧烈又直观。
没有人造痕迹。
至于”首个把 on-policy 自蒸馏用于 GUI 定位测试时适应”这种三重限定的 first,是行业惯例,但底层问题不靠这个说法也站得住。
方法成熟度:条件化自教师是好想法,而且干净——它解决了一个真实的类型不匹配(反馈是文本,输出是坐标),且没引入奖励模型或 critic head。
对比校准是更锋利的洞察:注意到自回归前缀污染恰好毒害的是你最想学的那批样本的蒸馏目标,然后伸手去拿对比解码这个工具来修。
我认为这部分的寿命会超过整篇论文。
但有个显而易见的简单基线在门口等着,论文怎么处理它决定了它的分量:既然你有一个足够好的 Reflector 能诊断失手,为什么不直接在推理时做”验证-重试”——拒绝采样直到 critic 通过,完全不更新权重?
那样是 training-free 的、没有漂移风险,而且很可能吃掉所报收益的一大块。
本文的价值完全取决于能否证明:内化版本在匹配测试时算力的条件下打赢它,并且提升能迁移到 Reflector 已经不在场的截图上。
另一个值得追问的是:收益里有多少来自”任何形式的自蒸馏”,多少来自”反思”这个具体机制。
只喂判定(命中/失手,不给解释)给条件化教师的 ablation,是那个承重实验。
实验诚意:六个基准平均 +7.4%,对这类适应方法来说是个可信、不可疑的数字。
我在相信它之前会查这几件事:
到底是谁的知识在被蒸馏。 如果 Reflector 明显更强(GPT-4o 级别,或更大的开源 MLLM),那”自进化”这个词就在做修辞工作,而”测试时从更强 critic 蒸馏”才是更诚实的描述。
后者依然是有用的结果——但是不同的结果,而且算力账目会完全变样。
转导式泄漏。 在测试集上做适应,哪怕没有标签,也不能和冻结模型的评测直接对比。
权重是每个样本重置、每个基准重置、还是跨整条测试流累积,差别巨大;并且结果应当被证明对样本顺序稳健。
在一个不完美 critic 驱动下持续累积更新,本身就是个漂移生成器;我想看的是几千步适应之后的曲线,而不只是一个汇总的 delta。
收益落在哪里。 六个基准的平均值能藏住很多东西。
如果 ScreenSpot-Pro(高分辨率、专业软件、小目标——也就是真正的动机场景)几乎没动,而简单基准撑起了平均,故事就弱不少。
反过来,如果收益集中在难基准上,那是最强的证据。
Reflector 的可靠性。 整个闭环的天花板就是这个 critic 判定的精确率和召回率。
全流程没有任何 ground truth,一个把”差一点”判成”命中”的 critic,会主动教模型变糙。
这值得一张量化的表,而不是一句话。
成本。 每一屏要付:K 条 rollout + 一次 Reflector 调用 + 两次额外前向(校准)+ 一步梯度。
对于一个存在意义就是实时交互的系统,延迟和显存不是脚注。
写作功力:从摘要的组织看,四站闭环和蒸馏公式应该写得不错,我打赌偷懒在两个地方。
第一,Reflector 被当成 oracle 对待:prompt 设计、判定准确率、以及”critic 自信地给出错误批评”时的行为,这类东西通常只得到一段,而它值得一整个分析章节。
第二,成本账目。
真正能让整篇论文升一档的,是一段诚实、量化的”与 training-free 验证-重试在匹配算力下的正面对比”,加上 Reflector 准确率的数字——因为这一段是”有趣机制”和”你真的该部署它”之间的分界线。
就目前而言,摘要结尾那句”补全了 GUI Agent 的自进化能力”,对一个执行良好的组件级贡献来说说得太满了。
判决:弱接收 —— 条件化自教师加对比校准这对组合,干净地解决了”文本反馈 vs 坐标监督”的类型不匹配,但头条数字建立在一个未被检验的外部 critic 和一份未公布的算力预算之上,而论文的生死取决于摘要里没有承诺的那几个 ablation。
要点总结
“提示蒸馏”这个模式才是可迁移的资产。 只要你有某种信息在训练/适应阶段可得、在推理阶段不可得——参考答案、critic 的诊断、未来的观测、特权传感器——你就不需要另一个教师模型。
把信息放进上下文,跑一次前向,再把那个分布蒸馏进同一份权重的无上下文版本。
这远远超出 GUI 的范围:用测试失败日志修代码、用 schema 提示写 SQL、用事后轨迹标注训机器人策略,都是同一个套路。
对比相减能把一个含噪教师变成可用教师。 如果教师和学生共享偏见(权重相同时这是必然的),原始教师分布大部分与学生冗余,有用信号很小。
减掉一次无条件前向,就把归因于提示的增量分离出来。
便宜、通用,适用于任何”用条件化模型构造目标”的场合——奖励建模、偏好数据合成、自我批评流水线。
“前缀污染”是自蒸馏在失败 rollout 上的一个具体、可命名的失效模式。 这一点值得超越本文记住:如果你在自己采样的序列上做蒸馏,那么你最需要学习的样本,恰恰是历史已经错了的那些,而教师在这些历史上给出的目标被错误污染了。
多数自我改进流水线的做法是直接把失败样本过滤掉,连信号一起丢;本文选择修复它们。
如果你一直在丢弃负向 rollout,这是个该重新审视的设计决定。
挑那些”验证比生成便宜”的任务。 这个框架在定位上可行、而放到长时程规划上会很惨,原因就在于:检查一次点击只需裁一块 100x100 的图问”这是什么”,比从整张截图产生坐标容易太多。
当你在寻找可以尝试无标注自我改进的落点时,先找这种不对称。
不要拿走的东西:那个”自进化”的框架叙事。
如果所有学习信号都由一个更强的外部模型供给,诚实的描述是”带 critic 在环的测试时蒸馏”;描述准确了,才更容易推断天花板在哪。