Paper: 2608.07429 Authors: Yan Zhou, Yue Ouyang, Kaiyang Zheng, Suncheng Xiang Categories: cs.AI
The Gap
Everyone building long-term memory for agents has converged on roughly two designs. The first is append-only: every observation, reflection, or summary gets embedded and dumped into a vector store, and retrieval is top-k similarity. This is the Generative Agents / MemoryBank / most-RAG-over-chat-logs lineage. The second is last-write-wins (LWW): maintain a key-value cache of “current facts,” and when a new fact arrives for an existing key, overwrite it. This is what most production assistant memories actually do with user preferences.
Both make the same silent assumption: that a stored memory is true until something more relevant comes along. Append-only makes staleness a ranking problem — the obsolete fact is still in the index, still semantically close to the query, and often still wins top-k because it was stated more explicitly than its replacement. LWW makes staleness a destruction problem — it fixes the retrieval set but throws away the history, so the agent can never explain why it believes what it believes, and can never re-adopt an old value if the world flips back.
The paper’s framing is the sharp part: memory persistence creates a falsifiability problem. An agent that cannot mark a memory as false is an agent whose beliefs cannot be corrected, only outvoted. And the headline evidence is the kind of result that makes you sit up: under full reversal of the environment, both memory systems scored *worse than having no memory at all (0.210 for both, versus 0.309 for a memory-free agent). Memory became a liability.
  [ agent stores fact F under world state W0 ]
                     |
                     v
       [ world moves to W1, F is now false ]
                     |
                     v
   [ F is still active + still retrievable + still fluent ]
                     |
                     v
      *problem*: "memory pollution" -- worse than no memory
                     |
    assumption: validity is a STATE of a memory record,
                not a side effect of recency or rank
                     |
                     v
     method: keyed precedents + explicit revocation
             read path sees active only
             audit path sees everything
                     |
        +------------+-------------+---------------+
        |            |             |               |
        v            v             v               v
  hidden-regime  real file    MemAgentBench   multi-hop /
  drift, 50 seed  exec drift     SH-6k         long ctx
   .950 vs .210  .950 vs .203  ties with LWW   both fail
        |            |             |               |
        +------------+-------------+---------------+
                     |
                     v
   conclusion: revocation is a first-class memory op,
   alongside write() and read() -- but it only fixes
   fact-level validity, not retrieval chains
The Increment
One sentence: Before, agent memory had write and read and hoped conflicts would sort themselves out at ranking time; after, memory has a revoke operation and a validity flag, so conflicts are resolved at write time and the stale record survives for audit instead of being either retrieved or destroyed.
Core Mechanism
TEPA stores observations as keyed precedents. A precedent is not just an embedded string; it is a record with a key (the slot the claim is about), a value (the claim), the evidence that produced it (a tool call, a file read, a user utterance), a timestamp, and — the load-bearing addition — a status in {active, revoked}. The key is what makes conflict detectable: two claims collide not because they are semantically similar, but because they are answers to the same question.
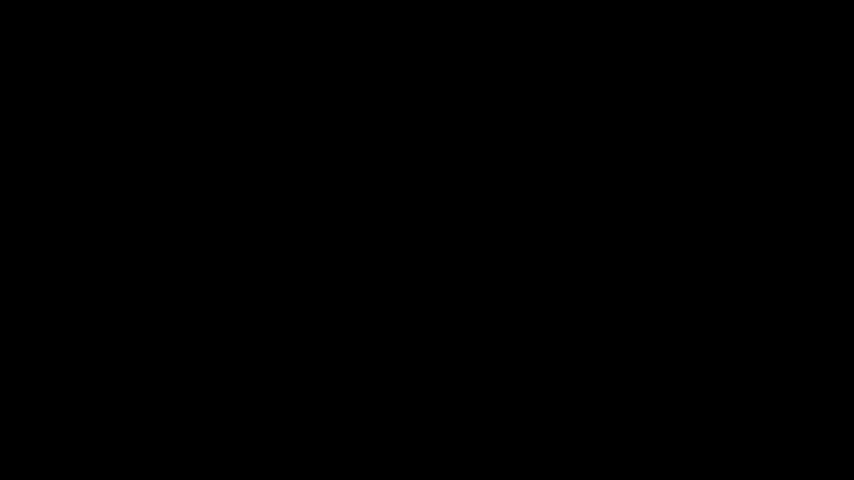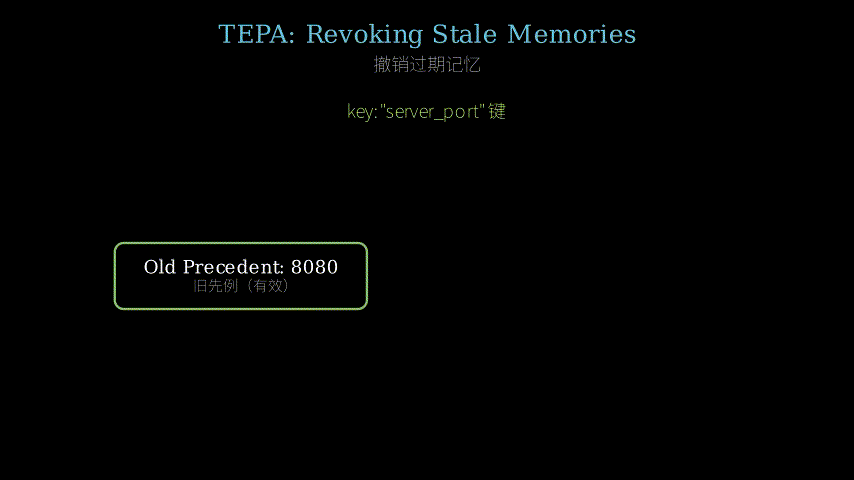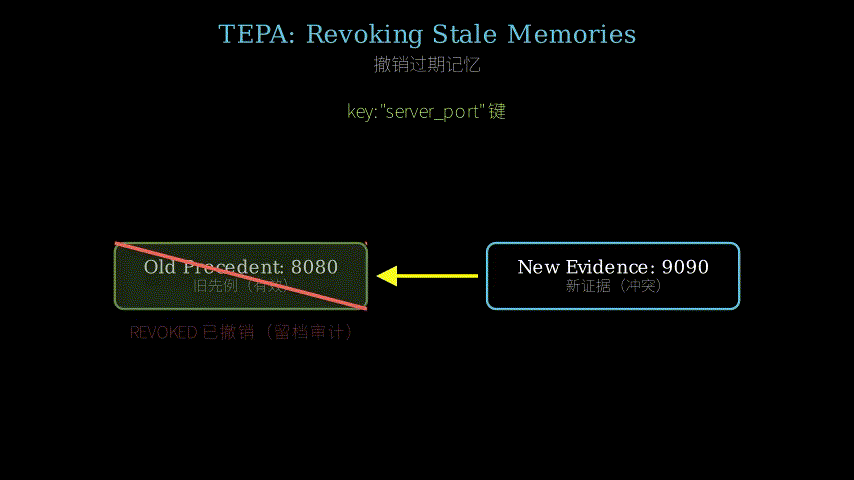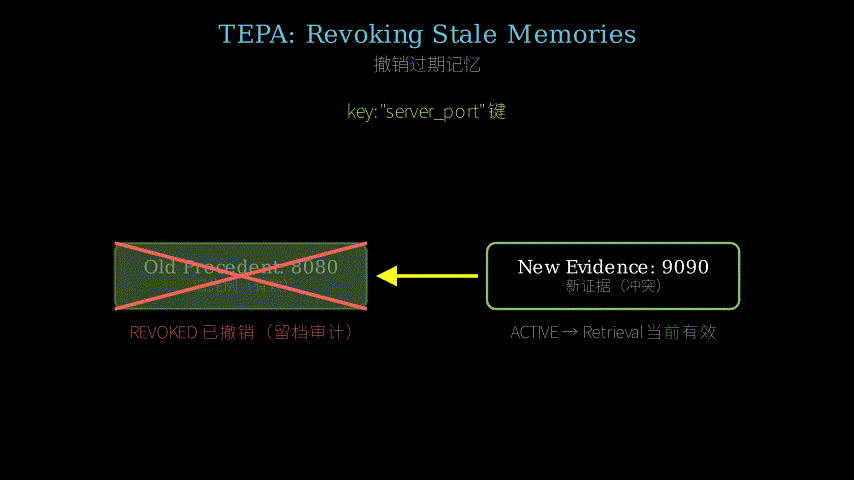
The write path does the work. A new observation gets a key extracted, then the store is checked for an active precedent under that same key. If none exists, insert as active. If one exists and the new evidence contradicts it, the old precedent’s status flips from active to revoked — it is not deleted, its evidence and the reason for revocation stay attached — and the new precedent is inserted as active. The read path is then almost trivially simple: retrieval filters on status == active, so a superseded fact is structurally incapable of entering the prompt. Two other paths fall out for free: an audit path that reads the full table including revoked rows, and re-promotion, where a revoked precedent can be flipped back to active if the evidence supporting it returns.
That last piece is what distinguishes this from soft deletion as a convenience. The claim is that in drifting environments, knowledge does not just decay — it oscillates. A deployment reverts, a config rolls back, a user changes their mind and then changes it back. If your only tools are append (keeps both, confuses retrieval) and overwrite (keeps one, forgets the other existed), you handle oscillation badly in both directions.
              new observation + evidence
                          |
                          v
                 [ key extraction ]
              key = (entity, attribute, scope)
                          |
                          v
            [ conflict check under SAME key ]
                    |            |
              no active       active + contradicts
              precedent            |
                    |              v
                    |     [ revoke old precedent ]
                    |      status: active -> revoked
                    |      keep: evidence, time, reason
                    |              |
                    +------+-------+
                           |
                           v
                 [ insert new as active ]
                           |
                           v
      +-------------------------------------------------+
      |              precedent store                    |
      | key   value   status    t    evidence           |
      | k1    v_new   active    t3   file:cfg.yaml      |
      | k1    v_old   REVOKED   t1   chat turn 4        |
      | k2    v_a     active    t2   tool:search        |
      +-------------------------------------------------+
           |                              |
           | read path                    | audit path
           v                              v
   filter status == active         read ALL rows,
           |                       replay belief history
           v                              |
     prompt context                       v
   (stale row cannot                 re-promote:
    appear here)                REVOKED -> active if
                                 evidence returns
Think of it as common law, which is clearly where the authors got their vocabulary. Each stored observation is a decided case. The key is the legal question the case answers — “what is the deploy target for service X?” — and the value is the holding. When a new case comes before the court on the *same question with contradicting evidence, the court does not shred the old ruling; it overrules it. The old case stays in the reporter, fully readable, with a note explaining what overruled it and when. But it is no longer *citable — a lawyer writing a brief today (the retrieval step assembling a prompt) may only cite good law.
The metaphor pays for itself on the two features that would otherwise seem arbitrary. Why keep revoked records instead of deleting them? Because a legal system whose overruled cases vanished could not explain its own reasoning, and neither can an agent that has to justify a decision after the fact. Why allow re-promotion? Because courts do revive overruled doctrines when circumstances return, and that is exactly the “regime flips back” case that breaks both baselines. And it clarifies the failure modes too: append-only memory is a law library where every ruling ever made is equally citable, so the brief is incoherent. LWW is a library that physically destroys overruled cases, so there is no appellate record at all.
Key Concepts
-
Memory pollution: The counterintuitive fact that memory can make an agent *worse than amnesia. Imagine you ask a colleague where the standup meeting is. Someone who has never been told anything says “I don’t know, check the calendar” — mildly useless, but harmless. Someone who was told six months ago “Room 4B” and never updated says “Room 4B” with total confidence, and you walk to an empty room. The no-memory agent falls back to reasoning or fresh lookup; the polluted agent short-circuits that with a fluent wrong answer. That is exactly the 0.210-below-0.309 result: the stale memory doesn’t just fail to help, it actively suppresses the recovery behavior the agent would otherwise have used.
-
Keying (and why it’s the real work): A “key” is a canonical name for the question a memory answers. The hard part is not storing the flag, it is deciding that “we deploy to us-east-1” and “the production region is Virginia” are answers to the same question, while “the staging region is Virginia” is not. Get keying too coarse and you revoke facts that were both true; too fine and conflicts go undetected and you’re back to append-only. Everything in this paper’s write path routes through key extraction, which is why I’d want to see it stress-tested more than the abstract suggests it was.
-
Validity as state vs. recency as proxy: Most systems approximate validity with a timestamp — newer is truer. That breaks in ordinary cases. A high-confidence measurement from Tuesday should not be overturned by a user’s offhand guess on Wednesday; a tool result that just returned “file not found” because of a transient permission error should not revoke a verified fact. Making validity an explicit, writable state means the *decision to invalidate becomes a place you can put policy, logging, and later, confidence thresholds. Recency gives you no such seam.
Framework Shift
Before (mainstream approach):          After (this paper):

  observation stream                    observation stream
        |                                     |
        v                                     v
  [ embed + append ]                   [ extract key ]
        |                                     |
        v                                     v
  +-----------------+                  [ conflict? revoke ]
  | m1  m2  m3  m4  |  all equal             |
  | m5  m6  m7 ...  |  citizens              v
  +-----------------+                 +------------------------+
        |                             | k1 v1 ACTIVE           |
        v                             | k1 v0 revoked <-+      |
  top-k similarity                    | k2 v2 ACTIVE    |      |
        |                             +-----------------|------+
        v                                   |           |
  prompt holds BOTH                    read filter      |
  old and new claims                   (active only)    |
        |                                   |        audit /
        v                                   v        re-promote
  LLM must referee                    prompt holds
  the contradiction                   ONE current claim
  at inference time
                                      conflict was settled
  (or LWW: overwrite m_old,           at WRITE time, and
   history gone, no audit,            history survives
   no way back)                       read-only
From ranking to lifecycle: the core shift is moving conflict resolution out of the retriever’s scoring function and into the memory record’s state machine, so “is this still true?” stops being something the LLM has to infer from a polluted context window.
Expert Assessment
Problem choice: Real gap, and well-named. Anyone who has run a memory-enabled assistant for more than a few weeks has watched it confidently repeat a preference the user revised, or a project detail that changed. The field has spent its energy on *what to store (summarization, reflection, hierarchy) and how to find it (embeddings, graphs, hybrid search), and comparatively little on when to stop believing it. The “worse than no memory” measurement is the paper’s best contribution as a framing device — it converts a vague annoyance into a falsifiable regression. It sits naturally in the trajectory from RAG-as-lookup toward memory-as-database, and it borrows the right prior art conceptually even if it doesn’t seem to name it: this is essentially MVCC plus tombstones plus time-travel queries, applied to agent memory.
Method maturity: Honestly, thin. Soft-delete with a validity flag and a keyed upsert is a design pattern, not a discovery — any engineer who has built an audit-logged CRUD system has shipped this. The paper’s own strongest counter-evidence is in its own abstract: on clean MemoryAgentBench SH-6k, TEPA *ties last-write-wins, and the authors concede “current-key replacement is the decisive operation.” So the novel component — keeping revoked rows and allowing re-promotion — buys auditability and reversal handling, not accuracy on standard benchmarks. That’s a legitimate contribution, but it’s a systems/observability contribution wearing a mechanism paper’s clothes. What’s genuinely underexplored: the conflict-detection policy. When does new evidence contradict rather than merely differ? Confidence-weighted revocation, evidence-source priority, revocation that requires corroboration — those are the interesting open problems, and the abstract suggests the paper treats detection as given.
Experimental integrity: The numbers are where I’d push hardest. Append-only and LWW scoring *identically (0.210) under full reversal is suspicious, because those systems have different retrieval sets by construction — identical scores usually mean the metric has saturated at a floor, i.e. both fail every reversed item and the task is effectively binary. Symmetrically, TEPA hitting exactly 0.950 in two structurally different experiments (synthetic drift and real file-backed execution) smells like a ceiling determined by the task generator rather than a measured capability. That doesn’t make the direction wrong, but it means the effect size (0.21 to 0.95) is a property of the benchmark design, not a transferable improvement estimate. The deeper question the abstract doesn’t answer: why does LWW fail at 0.210 during reversal if it also does current-key replacement? The only consistent explanation is that the drift benchmark presents conflicting facts under keys LWW does not recognize as identical, in which case the headline gap is measuring the key-extraction module, not revocation. If so, the paper’s title is pointing at the wrong component. Credit where due: reporting failures on multi-hop and long-context settings, and reporting that the ablation-like SH-6k comparison is a tie, is more honesty than most papers in this area offer.
Writing quality: The abstract never expands the acronym, which is a small tell about polish. The bigger gap is that the mechanism is described in outcome language (“revokes active precedents when fresh evidence contradicts them”) rather than operational language — what counts as contradiction, how keys are derived, who decides, what happens on ambiguous or low-confidence evidence. Rewriting the method section to specify the conflict-detection predicate and the key function, with failure cases and an honest cost accounting (extra LLM calls per write? latency? storage growth?), would elevate the whole paper, because that section is currently doing the least work relative to its importance. A close second: a paragraph reconciling the 0.210 baselines with the SH-6k tie would preempt the exact objection every reviewer will raise.
Verdict: borderline — the problem framing and the “memory worse than no memory” result deserve to be in the literature, but the mechanism is standard database hygiene and the headline gap appears to be attributable to a component the paper doesn’t foreground.
Takeaways
Things worth stealing regardless of what you think of the paper:
- Ship a
revokeoperation in your memory API, not justwriteandread. Even if your conflict detection is dumb, having validity be an explicit column gives you a place to hang policy, logging, and debugging later. Retrofitting this into an append-only vector store is painful; adding the column on day one is nearly free. - Separate the read path from the audit path. Retrieval filters to active records; incident review reads everything. This one split gives you “why did the agent say that?” for free, which is the question you will actually be asked in production.
- Benchmark against no-memory as a baseline. This is the paper’s most transferable methodological move. If your memory system can’t beat amnesia on a drifting task, you have a regression, and you would never see it comparing memory variants to each other. Add a reversal phase to your eval set: state a fact, use it, contradict it, then ask again.
- Test the flip-back case. Preferences and configs oscillate. Systems that only handle monotone updates silently fail here, and it’s cheap to test.
- The corollary the paper implies but doesn’t say loudly: if your fix for stale memory is “the LLM will notice the contradiction in context,” you have outsourced a database problem to a probabilistic reasoner. Settle conflicts at write time where the decision is auditable and cheap.
What not to take: the specific numbers. Treat 0.950 as “the mechanism works on a task designed to require it,” not as an expected improvement in your system.
论文: 2608.07429 作者: Yan Zhou, Yue Ouyang, Kaiyang Zheng, Suncheng Xiang 分类: cs.AI
缺口
做智能体长期记忆的人,最后基本收敛到两种设计。
一种是 append-only(只追加):每条观察、反思、摘要都做 embedding 扔进向量库,检索靠 top-k 相似度。 Generative Agents、MemoryBank,以及绝大多数「对聊天记录做 RAG」的方案都是这一脉。
另一种是 last-write-wins(后写覆盖,LWW):维护一份「当前事实」的键值缓存,同一个 key 来了新事实就覆盖旧的。 线上助手处理用户偏好,实际用的多半是这个。
两者共享同一个没人说出口的假设:存进去的记忆是真的,直到有更相关的东西出现。 append-only 把过期变成了排序问题——过时的事实还在索引里,还跟查询语义接近,而且往往因为当初表述得更明确而在 top-k 里赢过它的替代者。 LWW 把过期变成了销毁问题——检索集干净了,但历史丢了,智能体永远解释不清自己为什么这么认为,世界翻回去时也没法把旧值捡回来。
这篇论文的框架是最锋利的部分:记忆的持久化制造了一个可证伪性问题。 一个无法把某条记忆标记为「假」的智能体,它的信念不可被纠正,只能被投票压过去。
而最抓人的证据是这个:在环境完全反转的条件下,两种记忆系统的得分都低于完全没有记忆(两者都是 0.210,无记忆是 0.309)。 记忆从资产变成了负债。
  [ 世界处于 W0,智能体记下事实 F ]
                     |
                     v
       [ 世界变成 W1,F 已经是假的 ]
                     |
                     v
   [ F 仍是 active + 仍可检索 + 仍很流畅 ]
                     |
                     v
      *问题*: "记忆污染" -- 比没有记忆更差
                     |
    假设: 有效性是记忆记录的一个「状态」,
          而不是新鲜度或排序的副产品
                     |
                     v
     方法: 带 key 的先例 + 显式撤销
           读路径只看 active
           审计路径看全部
                     |
        +------------+-------------+---------------+
        |            |             |               |
        v            v             v               v
   隐藏 regime    真实文件      MemAgentBench    多跳 /
   漂移 50 seed   执行漂移        SH-6k         超长上下文
   .950 vs .210  .950 vs .203   与 LWW 打平     两项都挂
        |            |             |               |
        +------------+-------------+---------------+
                     |
                     v
   结论: 撤销应当是一等记忆操作,
   与 write() / read() 并列 -- 但它只修
   事实级有效性, 修不了检索链
增量
一句话:以前记忆只有「写」和「读」,指望冲突在排序阶段自己摆平;现在多了一个「撤销」操作和一个有效性标记,冲突在写入时就被裁决,过期记录既不会被检索到、也不会被销毁,而是留在原地供审计。
核心机制
TEPA 把观察存成带 key 的先例(keyed precedent)。 一条先例不只是一段做过 embedding 的文本,而是一条记录:key(这条断言在回答哪个槽位)、value(断言本身)、产生它的证据(一次工具调用、一次文件读取、一句用户话)、时间戳,以及承重的那一项——状态,取值 {active, revoked}。
key 是让冲突可被发现的关键:两条断言之所以冲突,不是因为它们语义相似,而是因为它们在回答同一个问题。
真正干活的是写路径。 新观察进来先抽取 key,然后在库里查同一 key 下有没有 active 的先例。 没有就直接插入为 active。 有、且新证据与之矛盾,那么旧先例的状态从 active 翻为 revoked——注意不是删除,它的证据和被撤销的原因都留着——然后新先例插入为 active。
于是读路径简单到近乎平庸:检索时按 status == active 过滤,被取代的事实在结构上就不可能进入 prompt。
另外两条路径顺带白拿:审计路径读全表(含 revoked 行),以及重新提升(re-promotion)——如果支持某条已撤销先例的证据回来了,它可以被翻回 active。
最后这一点,是它区别于「随手做个软删除图方便」的地方。 论文的主张是:在漂移环境里,知识不只是衰减,它会来回振荡。 部署回滚、配置还原、用户改了主意又改回来。 如果你手上只有 append(两条都留,检索被搞乱)和 overwrite(只留一条,连它存在过都忘了),那你在振荡的两个方向上都会处理得很糟。
                新观察 + 证据
                          |
                          v
                  [ key 抽取 ]
             key = (实体, 属性, 作用域)
                          |
                          v
             [ 在同一 key 下做冲突检查 ]
                    |            |
              无 active       有 active 且矛盾
               先例                 |
                    |              v
                    |     [ 撤销旧先例 ]
                    |      status: active -> revoked
                    |      保留: 证据, 时间, 原因
                    |              |
                    +------+-------+
                           |
                           v
                  [ 新先例插入为 active ]
                           |
                           v
      +-------------------------------------------------+
      |                  先例库                          |
      | key   value   status    t    evidence           |
      | k1    v_new   active    t3   file:cfg.yaml      |
      | k1    v_old   REVOKED   t1   对话第 4 轮         |
      | k2    v_a     active    t2   tool:search        |
      +-------------------------------------------------+
           |                              |
           | 读路径                        | 审计路径
           v                              v
    过滤 status == active           读全部行,
           |                        回放信念演化史
           v                              |
      prompt 上下文                        v
   (过期行进不来)                    重新提升:
                                REVOKED -> active
                                 若证据回归
用**判例法(common law)**来理解它,作者的词汇显然也是从这儿借的。
每条存下的观察是一个已决案件。 key 是这个案件所回答的法律问题——「服务 X 的部署目标是什么?」——value 是判决要旨。 当同一个问题带着矛盾证据再次上庭,法院不会把旧判决撕掉,而是推翻(overrule)它。 旧案件仍留在判例汇编里、原文可读,并附上一条说明:何时被什么推翻。 但它不再可被引用——今天写辩护意见书的律师(也就是组装 prompt 的检索步骤)只能引用「有效的法(good law)」。
这个核喻在两个否则看起来很随意的设计上立刻回本。 为什么保留被撤销的记录而不是删掉? 因为一个让被推翻判例凭空消失的法律体系,无法解释自己的推理过程;一个事后要为决策做辩护的智能体也一样。 为什么允许重新提升? 因为法院确实会在情势回归时复活被推翻的学说,而这正是「regime 翻回去」那个把两个基线都打穿的情形。
失败模式也随之清晰:append-only 是一座所有判决都同等可引用的法律图书馆,所以辩护意见书自相矛盾。 LWW 是一座把被推翻的案件物理销毁的图书馆,于是根本不存在上诉记录。
关键概念
-
记忆污染(memory pollution):一个反直觉的事实——记忆可能让智能体比失忆更差。 设想你问同事站会在哪个房间。 从没被告知的人说「不知道,你查下日历」——没什么用,但无害。 半年前被告知「4B 会议室」且从未更新的人,会非常自信地说「4B」,于是你走进一间空屋。 无记忆的智能体会退回到推理或现场查询;被污染的智能体用一个流畅的错误答案把这条恢复路径短路了。 这就是 0.210 低于 0.309 的含义:过期记忆不只是没帮上忙,它主动压制了智能体本来会采取的补救行为。
-
Keying(以及为什么它才是真正的工作量):key 是「这条记忆在回答什么问题」的规范化名字。 难的不是存那个状态标记,而是判定「我们部署到 us-east-1」和「生产区域是弗吉尼亚」在回答同一个问题,而「预发区域是弗吉尼亚」不是。 key 划得太粗,你会撤销掉两条都为真的事实;划得太细,冲突检测不到,你就退回了 append-only。 这篇论文写路径上的一切都要过 key 抽取这道关,所以我很想看到比摘要暗示的力度更狠的压力测试。
-
有效性作为状态,而非用新鲜度做代理:多数系统用时间戳近似有效性——越新越真。 这在很普通的情形下就会崩。 周二一次高置信度的测量,不该被周三用户随口一猜推翻;一次因权限抖动而返回「文件不存在」的工具结果,不该撤销一条已验证的事实。 把有效性做成显式、可写的状态,意味着「决定作废」这件事本身变成了一个可以挂策略、挂日志、之后挂置信度阈值的接口点。 新鲜度不给你这样一条缝。
框架转变
之前(主流方法):                    之后(本文方法):

    观察流                              观察流
      |                                   |
      v                                   v
 [ embed + append ]                  [ 抽取 key ]
      |                                   |
      v                                   v
+-----------------+                 [ 冲突? 撤销 ]
| m1  m2  m3  m4  | 全体记忆              |
| m5  m6  m7 ...  | 地位平等               v
+-----------------+                +------------------------+
      |                            | k1 v1 ACTIVE           |
      v                            | k1 v0 revoked <-+      |
  top-k 相似度                      | k2 v2 ACTIVE    |      |
      |                            +-----------------|------+
      v                                  |           |
 prompt 里同时装着                    读过滤          |
 旧断言和新断言                    (仅 active)    审计 /
      |                                  |       重新提升
      v                                  v
 让 LLM 在推理时                   prompt 里只有
 现场当裁判                        一条当前断言

 (或 LWW: 覆盖掉 m_old,            冲突在「写入时」
  历史没了, 无审计,                 就已裁决, 历史
  也回不去)                        以只读形式存续
一句话:从排序到生命周期,核心转变是把冲突裁决从检索器的打分函数里搬到记忆记录的状态机里,让「这条还成立吗」不再需要 LLM 从被污染的上下文里自己推断。
专家评审
选题眼光:真缺口,而且命名准确。 任何把带记忆的助手跑过几周的人,都见过它自信地重复一条用户已经改掉的偏好,或者一个早已变更的项目细节。 这个领域的精力大量花在存什么(摘要、反思、层级结构)和怎么找(embedding、图、混合检索)上,花在什么时候该停止相信上的极少。 「比没有记忆更差」这个测量是本文作为框架的最大贡献——它把一个模糊的恼人体验变成了一个可证伪的回归指标。 它在「RAG 即查表」走向「记忆即数据库」的轨迹上位置很自然。 不过它借的先验其实没点名:这基本上就是 MVCC + tombstone + time-travel query,搬到智能体记忆上。
方法成熟度:说实话,薄。 带有效性标记的软删除加上按 key 的 upsert,是一个设计模式,不是一项发现——任何做过带审计日志的 CRUD 系统的工程师都上线过它。 最有力的反证就写在论文自己的摘要里:在干净的 MemoryAgentBench SH-6k 上,TEPA 与 last-write-wins 打平,而作者自己承认「current-key replacement 才是决定性操作」。 也就是说,真正新增的部分——保留 revoked 行、允许重新提升——买到的是可审计性和反转处理能力,不是标准 benchmark 上的准确率。 这是正当的贡献,但它是一份系统/可观测性的贡献,穿着机制论文的外套。
真正没被展开的是冲突检测策略。 新证据在什么条件下算「矛盾」而不只是「不同」? 按置信度加权的撤销、按证据来源定优先级、需要交叉印证才允许撤销——这些才是有意思的开放问题,而摘要暗示论文把检测当成给定条件了。
实验诚意:数字是我最想追问的地方。 完全反转条件下 append-only 和 LWW 得分完全相同(都是 0.210)很可疑,因为这两个系统的检索集在构造上就不一样——分数完全相同通常意味着指标已经触到地板,即两者在所有反转项上全错,任务实际上是二值的。 对称地,TEPA 在两个结构上很不一样的实验里(合成漂移与真实文件执行)都恰好是 0.950,闻起来像是任务生成器设定的天花板,而非测出来的能力。 这不代表方向错,但意味着 0.21 到 0.95 这个效应量是 benchmark 设计的性质,不是一个可迁移的改进幅度估计。
摘要没回答的更深问题是:如果 LWW 也做同 key 替换,为什么它在反转期只有 0.210? 唯一自洽的解释是,漂移 benchmark 把冲突事实放在了 LWW 认不出是同一个 key 的键上——那么头条差距衡量的其实是 key 抽取模块,不是撤销机制。 若真如此,论文的标题指错了组件。
该给的分要给:主动报告多跳和长上下文设置上的失败,并且承认 SH-6k 那组近似消融的比较是平手,这份坦率超过这个方向上的多数论文。
写作功力:摘要里从头到尾没展开这个缩写,是个关于打磨程度的小信号。 更大的问题是机制被用结果语言描述(「当新证据与之矛盾时撤销 active 先例」),而不是操作语言:什么算矛盾、key 怎么导出、谁来裁决、证据模糊或低置信时怎么办。 把方法一节重写成给出冲突检测谓词和 key 函数的定义,配上失败案例和一份诚实的成本核算(每次写入多几次 LLM 调用?延迟?存储增长?),能把整篇论文拉高一档——因为这一节目前的产出与它的重要性最不匹配。 第二优先:加一段把 0.210 的基线与 SH-6k 的平手对账,这能提前挡掉每个审稿人都会提的那个反驳。
判决:临界 —— 问题框架和「记忆比没记忆更差」这个结果值得进文献,但机制本身是标准的数据库卫生学,而头条差距看起来要归因于论文没有摆到前台的那个组件。
要点总结
不管你怎么评价这篇论文,下面这些值得偷:
-
在你的记忆 API 里放一个
revoke,而不只是write和read。 哪怕你的冲突检测很笨,把有效性做成一个显式字段,就给你留下了之后挂策略、挂日志、做调试的位置。 把这件事回填进一个已经 append-only 的向量库很痛苦;第一天就加上这个字段几乎免费。 -
把读路径和审计路径分开。 检索只过 active 记录;事故复盘读全部。 就这一个切分,白送你「智能体当时为什么这么说」的追溯能力——而这恰恰是你在生产环境真正会被问到的问题。
-
把「无记忆」作为基线。 这是本文方法论上最可迁移的一招。 如果你的记忆系统在漂移任务上打不过失忆,那你有一个回归;而只在各记忆变体之间互相比较,你永远看不到它。 给评测集加一个反转阶段:陈述一个事实,用它,推翻它,再问一次。
-
测「翻回去」的情形。 偏好和配置是会振荡的。 只处理单调更新的系统在这里会静默失败,而测试成本很低。
-
论文暗示但没有大声说的推论:如果你对付过期记忆的方案是「LLM 会注意到上下文里的矛盾」,那你是把一个数据库问题外包给了一个概率推理器。 在写入时把冲突结掉——那里的决策可审计,而且便宜。
不要偷的:具体数字。 把 0.950 理解成「机制在一个专为需要它而设计的任务上有效」,而不是你系统里能预期的改进幅度。