Paper: 2603.28750 Authors: Aur Shalev Merin Categories: cs.LG
The Gap
Training recurrent networks online has been stuck in a memory trap. Real-Time Recurrent Learning (RTRL) computes exact gradients but requires O(n⁴) memory for n hidden units—impractical beyond tiny networks. Truncated Backpropagation Through Time (TBPTT) is cheaper but introduces bias by cutting temporal dependencies. Eligibility traces try to bridge this gap but corrupt gradients by mixing stale information with fresh signals.
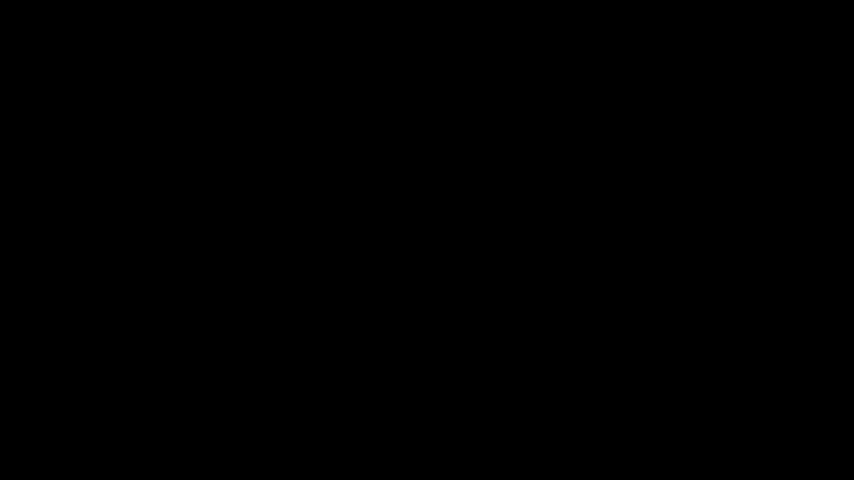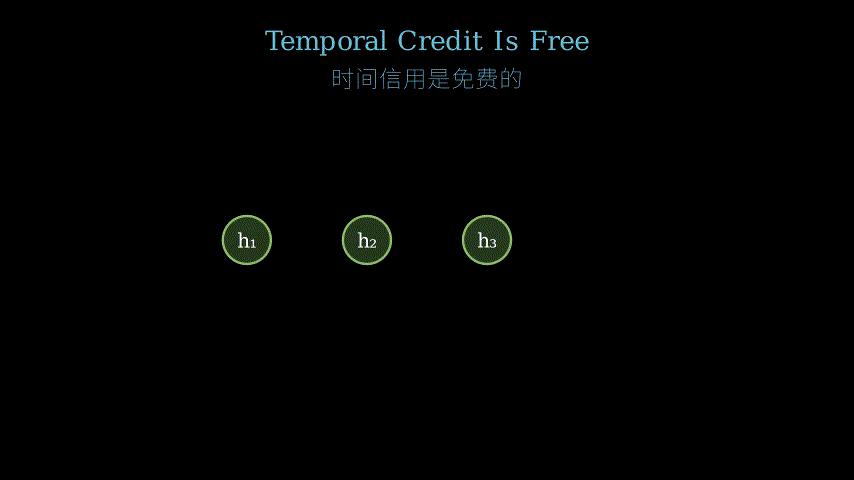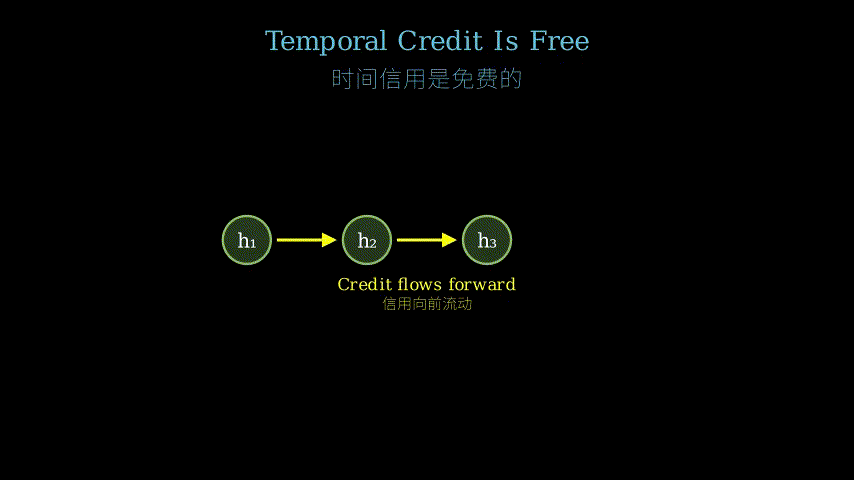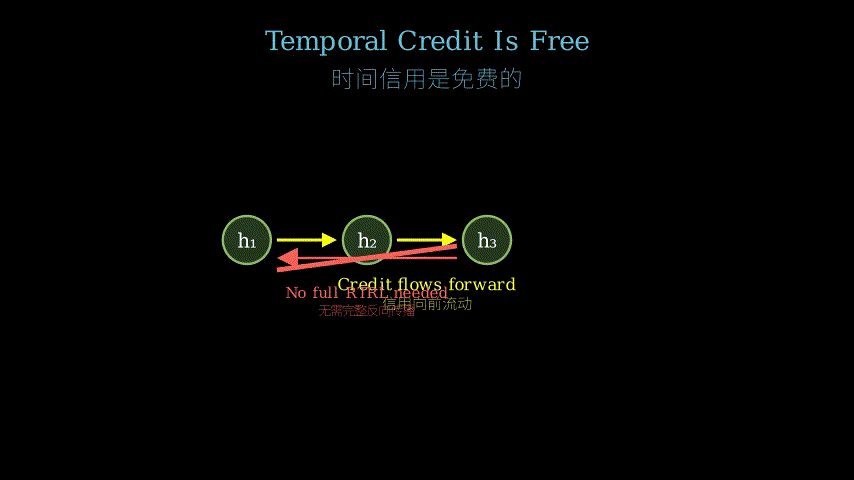
The field assumed you need full Jacobian propagation through time to assign credit correctly. This paper challenges that assumption: what if temporal credit already flows forward through the hidden state itself?
Problem: Online RNN learning
   |
   v
Assumption: Need Jacobian chains for temporal credit
   |
   +---> RTRL: O(n^4) memory ---> impractical
   |
   +---> TBPTT: truncate ---> biased gradients
   |
   +---> Eligibility traces ---> stale corruption
   |
   v
This paper's insight: Hidden state carries credit forward
   |
   v
Method: Immediate derivatives + selective normalization
   |
   v
Evidence: Match RTRL at 1000x less memory (n=1024)
   |
   v
Conclusion: Temporal credit is free in the forward pass
The Increment
One sentence: Before this paper, online RNN learning required either prohibitive memory (RTRL) or biased gradients (TBPTT/traces); after, immediate derivatives with architectural normalization rules match full temporal credit at 1000x memory savings.
Core Mechanism
The method has three components working in concert. First, immediate derivatives: compute gradients using only the current timestep’s Jacobian, ignoring all historical chain rule terms. This drops memory from O(n⁴) to O(n²). Second, forward credit flow: the recurrent hidden state h_t already encodes temporal dependencies from all previous steps—it’s a compressed summary of history. When you update parameters based on h_t’s gradient, you’re implicitly crediting past decisions that shaped h_t. Third, selective normalization: apply β₂ momentum (RMSprop’s second moment) only when gradients must pass through a nonlinear state update with no output bypass—a structural property you can identify from architecture alone.
Input x_t ---> [RNN Cell] ---> Output y_t
                  |  ^
                  |  |
                  v  |
              Hidden h_t (carries temporal credit)
                  |
                  v
         Immediate gradient: dL/dθ = dL/dh_t * dh_t/dθ
                  |
                  v
         Normalization check:
         Nonlinear update + no bypass? ---> Apply β₂
         Otherwise? ---> Skip normalization
                  |
                  v
         Parameter update: θ -= α * normalized_gradient
Think of the hidden state as a river carrying sediment. Each timestep, new sediment (information) enters the river. The river’s current composition reflects all upstream deposits—you don’t need to trace back to each individual source to know what’s in the water now. When you sample the river (compute gradients from h_t), you’re sampling the accumulated history. The immediate derivative is like testing the water at your current location: it tells you about everything upstream without needing a map of every tributary. Normalization is the filter you apply when the river passes through turbulent rapids (nonlinear bottlenecks)—without it, the sediment concentration becomes unstable. But in calm stretches (linear paths or bypasses), the filter just adds unnecessary resistance.
Key Concepts
-
Temporal credit assignment: In sequential learning, when a reward or error signal arrives at time T, which earlier decisions (at times 1, 2, …, T-1) deserve credit or blame? Traditional methods propagate gradients backward through time, computing how each past parameter setting influenced the final outcome. This requires storing or recomputing intermediate states—the memory bottleneck. The key insight here: if your hidden state h_t is a sufficient statistic of history, then ∂L/∂h_t already contains all the temporal credit information. You don’t need to unroll the computation graph backward; the forward pass already did the credit accounting by compressing history into h_t.
-
Jacobian propagation vs immediate derivatives: The Jacobian ∂h_t/∂h
_{t-1}describes how a small change in yesterday’s hidden state affects today’s. Full RTRL multiplies these Jacobians across all timesteps: ∂h_t/∂θ = ∂h_t/∂h_{t-1}· ∂h_{t-1}/∂h_{t-2}· … · ∂h_1/∂θ. This chain grows with sequence length. Immediate derivatives ignore the chain: ∂h_t/∂θ ≈ (∂h_t/∂θ)|_{direct}, treating h_{t-1}as constant. Sounds wrong—you’re throwing away temporal dependencies! But if h_{t-1}already encodes those dependencies, and you’re updating based on h_t which was built from h_{t-1}, the credit still flows. It’s like updating a recursive function: you don’t need to trace every recursive call if the return value already aggregates them. -
The β₂ normalization rule: RMSprop’s β₂ parameter controls second-moment momentum—it normalizes gradient scale by dividing by the root-mean-square of recent gradients. Why does this matter architecturally? When gradients pass through a nonlinear state update (like tanh or sigmoid) with no bypass path, small parameter changes can cause exponentially growing or shrinking gradients across layers. The nonlinearity acts as a gain modulator. β₂ stabilizes this by adapting the learning rate per parameter based on gradient history. But if there’s a bypass (like a residual connection), gradients have a linear path around the nonlinearity—no gain modulation, no instability, no need for normalization. The paper provides a decision rule: inspect the architecture, find bottlenecks, apply β₂ only there.
Framework Shift
Before (RTRL/TBPTT):                After (this paper):

Time:  t-2    t-1    t              Time:  t-2    t-1    t
       |      |      |                     |      |      |
       v      v      v                     v      v      v
      [h] -> [h] -> [h]                   [h] -> [h] -> [h]
       |      |      |                            |      |
       +------+------+                            |      |
       |      |      |                            v      v
       v      v      v                           [∇]    [∇]
      [∇] <- [∇] <- [∇]                           |      |
       ^      ^      ^                            v      v
       |      |      |                           [θ]    [θ]
  Backprop through time                    Immediate only
  (store all h_t or recompute)             (h_t carries credit)

  Memory: O(T * n^4)                       Memory: O(n^2)
One sentence: From explicitly backpropagating credit through time to letting the recurrent state implicitly carry it forward, the core shift is trusting the hidden state as a sufficient statistic.
Expert Assessment
Problem choice: This is a real gap with practical stakes. Online learning in recurrent networks matters for robotics, streaming data, and biological plausibility. The memory wall of RTRL has been known since the 1980s; eligibility traces were a workaround, not a solution. The problem sits at the intersection of theory (credit assignment) and engineering (memory constraints)—fertile ground.
Method maturity: The insight is elegant but not entirely novel—forward-mode differentiation and the idea that hidden states carry information are old. What’s new is the architectural normalization rule and the empirical demonstration that it works across diverse architectures. The β₂ rule feels slightly ad-hoc (why this specific condition?), but it’s testable and falsifiable. The paper doesn’t explore failure modes deeply—when does immediate credit fail? What about long-term dependencies that require explicit backprop?
Experimental integrity: Ten architectures, primate neural data, and ML benchmarks—solid breadth. The 1000x memory claim is fair (O(n⁴) vs O(n²)). However, the baselines are mostly RTRL and truncated BPTT; missing comparisons to recent sparse or low-rank RTRL approximations. The primate data experiment is intriguing but underexplained—how was ground truth established? The paper would benefit from ablations isolating the normalization rule’s contribution vs just using immediate derivatives.
Writing quality: The abstract oversells (“temporal credit is free” is catchy but imprecise—it’s not free, it’s already paid for in the forward pass). The architectural rule is buried in the middle; it should be front and center with a clear decision tree. The related work section conflates several distinct approaches without clearly positioning this work. Rewriting Section 3 to lead with the normalization rule, then justify it theoretically, would clarify the contribution.
Verdict: weak accept — Solid empirical work with a useful architectural heuristic, but the theoretical justification needs tightening and the experimental scope could be broader.
Takeaways
Steal the normalization rule: Before adding β₂ momentum to every parameter group, audit your architecture. If gradients have a linear bypass around nonlinear state updates, skip the normalization—you’ll train faster and avoid over-smoothing. This applies beyond RNNs: any architecture with optional residual paths.
Rethink what “temporal credit” means: If your state representation is rich enough, you don’t need to explicitly backpropagate through time. This suggests a design principle: invest in expressive state representations (larger hidden dimensions, better initialization) rather than complex credit assignment mechanisms. The forward pass can do more work than we give it credit for.
Memory-compute tradeoffs are architectural: The paper shows that O(n⁴) isn’t inevitable for online RNN learning—it’s a consequence of architectural choices. When designing new sequence models, ask: does this architecture force Jacobian chains, or can immediate derivatives suffice? The answer depends on information flow, not just mathematical convenience.
论文: 2603.28750 作者: Aur Shalev Merin 分类: cs.LG
缺口
在线训练循环网络一直困在内存陷阱里。
实时循环学习(RTRL)能算出精确梯度,但需要 O(n⁴) 内存(n 是隐藏单元数)——超过小网络就不现实了。
截断时间反向传播(TBPTT)便宜些,但切断时间依赖会引入偏差。
资格迹试图弥合这个鸿沟,但把陈旧信息和新鲜信号混在一起,污染了梯度。
该领域一直假设:要正确分配信用,必须通过时间做完整的雅可比传播。
这篇论文挑战这个假设:如果时间信用已经通过隐藏状态本身向前流动了呢?
问题:在线 RNN 学习
   |
   v
假设:需要雅可比链来传递时间信用
   |
   +---> RTRL: O(n^4) 内存 ---> 不现实
   |
   +---> TBPTT: 截断 ---> 梯度有偏
   |
   +---> 资格迹 ---> 陈旧污染
   |
   v
本文洞察:隐藏状态向前携带信用
   |
   v
方法:即时导数 + 选择性归一化
   |
   v
证据:在 n=1024 时以 1000 倍更少内存匹配 RTRL
   |
   v
结论:时间信用在前向传播中是免费的
增量
一句话: 这篇论文之前,在线 RNN 学习要么需要高昂内存(RTRL),要么梯度有偏(TBPTT/资格迹);
之后,带架构归一化规则的即时导数以 1000 倍内存节省匹配完整时间信用。
核心机制
方法有三个协同工作的组件。
第一,即时导数:只用当前时间步的雅可比计算梯度,忽略所有历史链式法则项。
这把内存从 O(n⁴) 降到 O(n²)。
第二,前向信用流:循环隐藏状态 h_t 已经编码了之前所有步骤的时间依赖——它是历史的压缩摘要。
当你基于 h_t 的梯度更新参数时,你在隐式地给塑造 h_t 的过去决策分配信用。
第三,选择性归一化:只在梯度必须通过无输出旁路的非线性状态更新时应用 β₂ 动量(RMSprop 的二阶矩)——这是你能从架构本身识别出的结构性质。
输入 x_t ---> [RNN 单元] ---> 输出 y_t
                  |  ^
                  |  |
                  v  |
              隐藏 h_t(携带时间信用)
                  |
                  v
         即时梯度: dL/dθ = dL/dh_t * dh_t/dθ
                  |
                  v
         归一化检查:
         非线性更新 + 无旁路? ---> 应用 β₂
         否则? ---> 跳过归一化
                  |
                  v
         参数更新: θ -= α * 归一化梯度
把隐藏状态想象成携带泥沙的河流。
每个时间步,新泥沙(信息)进入河流。
河流当前的成分反映了所有上游沉积——你不需要追溯到每个单独的源头就能知道现在水里有什么。
当你采样河流(从 h_t 计算梯度)时,你在采样累积的历史。
即时导数就像在当前位置测试水质:它告诉你上游的一切,而不需要每条支流的地图。
归一化是河流通过湍急急流(非线性瓶颈)时你应用的过滤器——没有它,泥沙浓度会变得不稳定。
但在平静河段(线性路径或旁路),过滤器只是增加不必要的阻力。
关键概念
- 时间信用分配:在序列学习中,当奖励或误差信号在时间 T 到达时,哪些早期决策(在时间 1, 2, …, T-1)应该得到信用或责备?
传统方法通过时间反向传播梯度,计算每个过去的参数设置如何影响最终结果。
这需要存储或重新计算中间状态——内存瓶颈。
这里的关键洞察:如果你的隐藏状态 h_t 是历史的充分统计量,那么 ∂L/∂h_t 已经包含了所有时间信用信息。
你不需要向后展开计算图;
前向传播已经通过把历史压缩进 h_t 完成了信用记账。
- 雅可比传播 vs 即时导数:雅可比 ∂h_t/∂h
_{t-1}描述昨天隐藏状态的微小变化如何影响今天的。
完整 RTRL 跨所有时间步乘这些雅可比:∂h_t/∂θ = ∂h_t/∂h_{t-1} · ∂h_{t-1}/∂h_{t-2} · … · ∂h_1/∂θ。
这条链随序列长度增长。
即时导数忽略链:∂h_t/∂θ ≈ (∂h_t/∂θ)|_{直接},把 h_{t-1} 当常量。
听起来不对——你在扔掉时间依赖!
但如果 h_{t-1} 已经编码了那些依赖,而你基于从 h_{t-1} 构建的 h_t 更新,信用仍然流动。
这就像更新递归函数:如果返回值已经聚合了它们,你不需要追踪每次递归调用。
- β₂ 归一化规则:RMSprop 的 β₂ 参数控制二阶矩动量——它通过除以近期梯度的均方根来归一化梯度尺度。
为什么这在架构上重要?
当梯度通过无旁路路径的非线性状态更新(如 tanh 或 sigmoid)时,小的参数变化会导致跨层指数增长或缩小的梯度。
非线性充当增益调制器。
β₂ 通过基于梯度历史调整每个参数的学习率来稳定这一点。
但如果有旁路(如残差连接),梯度有绕过非线性的线性路径——没有增益调制,没有不稳定,不需要归一化。
论文提供了决策规则:检查架构,找到瓶颈,只在那里应用 β₂。
框架转变
之前(RTRL/TBPTT):                之后(本文):

时间:  t-2    t-1    t              时间:  t-2    t-1    t
       |      |      |                     |      |      |
       v      v      v                     v      v      v
      [h] -> [h] -> [h]                   [h] -> [h] -> [h]
       |      |      |                            |      |
       +------+------+                            |      |
       |      |      |                            v      v
       v      v      v                           [∇]    [∇]
      [∇] <- [∇] <- [∇]                           |      |
       ^      ^      ^                            v      v
       |      |      |                           [θ]    [θ]
  通过时间反向传播                          仅即时
  (存储所有 h_t 或重算)                  (h_t 携带信用)

  内存: O(T * n^4)                         内存: O(n^2)
一句话:从显式地通过时间反向传播信用到让循环状态隐式地向前携带它,核心转变是信任隐藏状态作为充分统计量。
专家评审
选题眼光:这是个有实际意义的真缺口。
循环网络的在线学习对机器人、流数据和生物合理性都重要。
RTRL 的内存墙从 1980 年代就知道了;
资格迹是权宜之计,不是解决方案。
问题位于理论(信用分配)和工程(内存约束)的交叉点——肥沃的土壤。
方法成熟度:洞察优雅但不完全新颖——前向模式微分和隐藏状态携带信息的想法是旧的。
新的是架构归一化规则和跨多样架构有效的经验证明。
β₂ 规则感觉略显临时(为什么是这个特定条件?
),但它可测试和可证伪。
论文没有深入探索失败模式——即时信用何时失败?
需要显式反向传播的长期依赖怎么办?
实验诚意:十个架构、灵长类神经数据和 ML 基准——广度扎实。
1000 倍内存声明是公平的(O(n⁴) vs O(n²))。
然而,基线主要是 RTRL 和截断 BPTT;
缺少与最近稀疏或低秩 RTRL 近似的比较。
灵长类数据实验有趣但解释不足——真值如何建立?
论文会受益于隔离归一化规则贡献 vs 仅使用即时导数的消融实验。
写作功力:摘要过度推销(“时间信用是免费的”朗朗上口但不精确——它不是免费的,是在前向传播中已经支付了)。
架构规则埋在中间;
它应该在最前面,配清晰的决策树。
相关工作部分混淆了几种不同方法,没有清楚定位这项工作。
重写第 3 节以归一化规则开头,然后理论证明,会澄清贡献。
判决:弱接收 — 扎实的经验工作,带有有用的架构启发式,但理论证明需要收紧,实验范围可以更广。
要点总结
偷走归一化规则:在给每个参数组添加 β₂ 动量之前,审计你的架构。
如果梯度在非线性状态更新周围有线性旁路,跳过归一化——你会训练更快,避免过度平滑。
这超越 RNN 适用:任何有可选残差路径的架构。
重新思考”时间信用”的含义:如果你的状态表示足够丰富,你不需要显式地通过时间反向传播。
这提示一个设计原则:投资于表达性状态表示(更大的隐藏维度、更好的初始化),而不是复杂的信用分配机制。
前向传播能做的工作比我们给它的信用多。
内存-计算权衡是架构性的:论文表明 O(n⁴) 对在线 RNN 学习不是不可避免的——它是架构选择的后果。
设计新序列模型时,问:这个架构强制雅可比链,还是即时导数就够了?
答案取决于信息流,不只是数学便利性。