Paper: 2603.09974 Authors: Aleksei Rozanov, Arvind Renganathan, Vipin Kumar Categories: cs.LG, physics.ao-ph
The Gap
Existing carbon flux upscaling methods hit a wall: they’re trained on sparse flux tower measurements (think ~200 sites scattered across the globe), then asked to estimate fluxes everywhere. Pure data-driven approaches like FluxCom and FLUXNET learn patterns from observed sites but collapse when extrapolating to unobserved regions with different climate regimes or vegetation types. The core issue is distribution shift—models memorize local patterns rather than learning transferable physical relationships. This leads to systematic regional biases and R² values stuck around 20%, meaning 80% of variance remains unexplained.
Sparse flux towers    Data-driven model    Global estimates
(biased distribution) (overfits to sites) (poor generalization)
        |                     |                    |
        v                     v                    v
    [150 sites]  ------>  [learns local]  ---->  [fails on]
    [clustered]           [patterns only]        [new regions]
        |                                            |
        +--------------------------------------------+
                    Regional bias + high uncertainty
The Increment
One sentence: Before this paper, carbon flux upscaling was pattern matching on sparse data; after, it’s representation learning constrained by carbon balance physics.
Core Mechanism
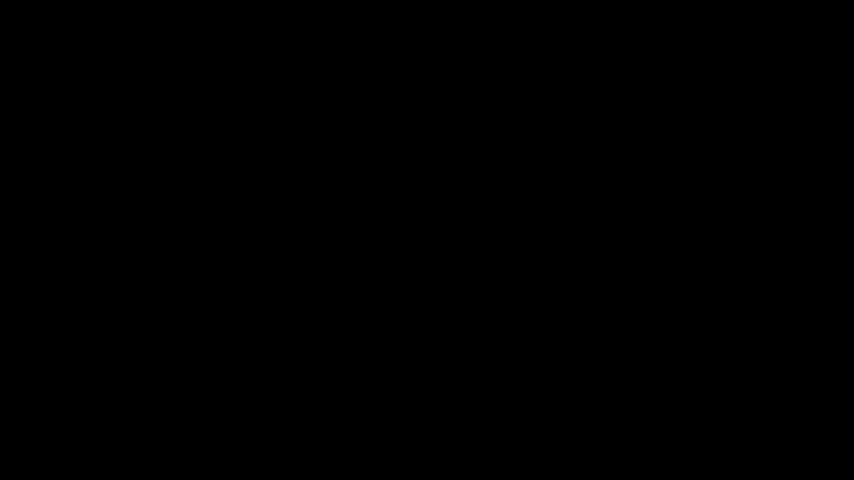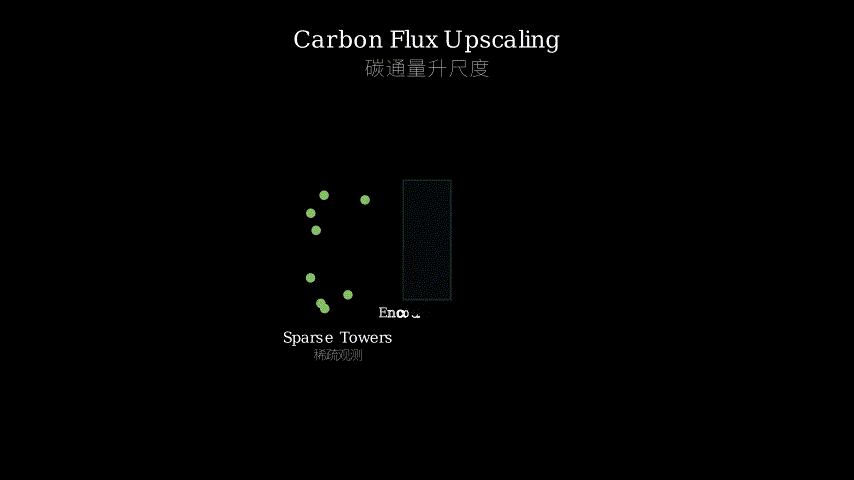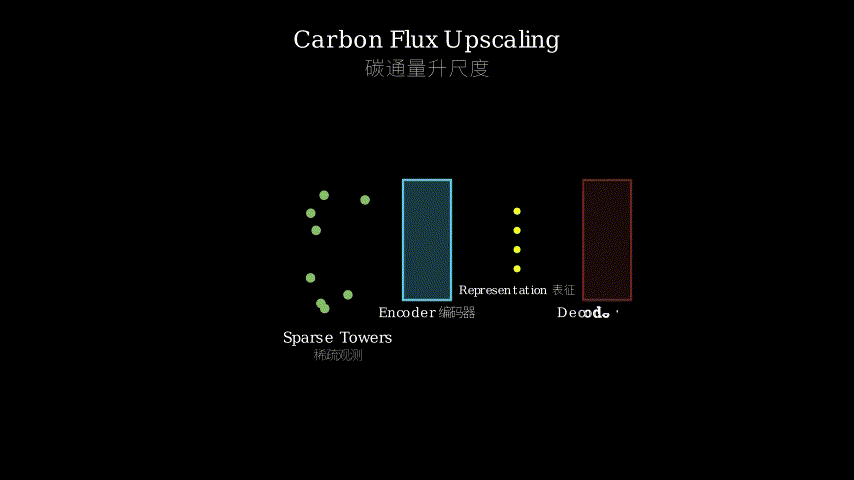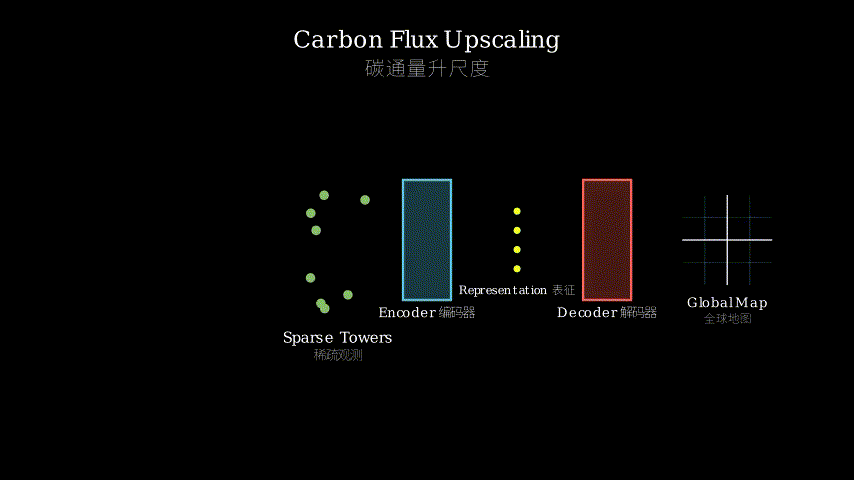
TAM-RL has three interlocking components. First, a spatio-temporal encoder learns representations from satellite imagery, climate data, and other environmental variables—think of it as compressing high-dimensional Earth observations into a latent space that captures relevant patterns. Second, task-aware modulation adapts these representations based on which flux you’re predicting (GPP, NEE, or respiration)—the same environmental conditions mean different things for different carbon processes. Third, the decoder reconstructs flux estimates while being supervised by a loss function derived from the carbon balance equation (GPP - respiration = NEE), ensuring predictions respect physical constraints.
Environmental data (satellite, climate, soil)
        |
        v
   [Encoder] -----> Learned representations
        |                    |
        |                    v
        |            [Task modulation]
        |            (adapt for GPP/NEE/Reco)
        |                    |
        +--------------------+
                 |
                 v
            [Decoder] -----> Flux predictions
                 |
                 v
        [Physics-guided loss]
        (GPP - Reco = NEE constraint)
Think of TAM-RL as a translation system for Earth’s carbon language. The encoder learns a universal vocabulary from environmental observations—temperature patterns, vegetation indices, soil moisture. But just as “bank” means different things in finance versus rivers, the same environmental state means different things for photosynthesis versus respiration. Task-aware modulation is like dialect adaptation: it takes the universal representation and inflects it for the specific carbon process you’re asking about. The physics constraint acts as grammar rules—you can’t violate carbon balance any more than you can violate subject-verb agreement. The decoder then “speaks” this adapted representation back into flux estimates, with the grammar checker (carbon balance loss) ensuring the output makes physical sense.
Key Concepts
-
Upscaling: Imagine you have thermometers in 150 cities worldwide, but you need to estimate temperature everywhere on Earth. That’s upscaling—going from sparse point measurements to continuous global fields. The challenge isn’t just interpolation (filling gaps between nearby points), but extrapolation (predicting in regions unlike anywhere you’ve measured). For carbon fluxes, this means taking CO₂ exchange measurements from flux towers in, say, temperate forests and estimating fluxes in tropical rainforests where you have no towers.
-
Task-aware modulation: Standard neural networks learn one set of features for all tasks. Task-aware modulation says: the same input should be processed differently depending on what you’re predicting. Concretely, it’s a learned transformation that scales and shifts the representation based on a task embedding. If you’re predicting photosynthesis (GPP), it might amplify features related to sunlight and chlorophyll; for respiration, it emphasizes temperature and soil moisture. It’s like adjusting equalizer settings based on whether you’re listening to speech or music.
-
Knowledge-guided loss: Most ML losses just measure prediction error. A knowledge-guided loss adds terms that penalize violations of domain knowledge. Here, the carbon balance equation (GPP - respiration = NEE) becomes a soft constraint in the loss function. If your model predicts GPP=10 and respiration=3, it better predict NEE≈7, or the loss increases. This prevents the model from learning physically impossible combinations, even if they fit the training data well.
Framework Shift
Before (mainstream approach):        After (this paper):

Environmental data                   Environmental data
        |                                    |
        v                                    v
  [Neural network]                    [Representation]
   (black box)                         [encoder]
        |                                    |
        v                                    v
  Flux predictions                    [Task modulation]
  (site-specific)                      (adapt by flux type)
                                             |
                                             v
                                        [Decoder with]
                                        [physics loss]
                                             |
                                             v
                                       Flux predictions
                                       (physically consistent)

Pattern matching                     Constrained learning
on local data                        with physical structure
From black-box pattern matching to structured representation learning, the core shift is embedding physical constraints directly into the learning objective rather than treating them as post-hoc validation checks.
Expert Assessment
Problem choice: This is a genuine bottleneck in climate science. The carbon budget has massive uncertainty, and flux tower networks are expensive to expand. Improving upscaling methods has real scientific value. The problem sits at a sweet spot where ML can help but domain knowledge is essential—pure data-driven approaches have plateaued.
Method maturity: The combination of representation learning + task modulation + physics constraints is thoughtful, not just throwing transformers at the problem. However, I’m curious whether simpler physics-informed baselines (like process-based models with learned parameters) were tested. The paper claims novelty in “task-aware modulation,” but this is essentially conditional computation, which has been explored in multi-task learning for years. The real contribution is the specific application to carbon fluxes with carbon balance constraints.
Experimental integrity: 150+ sites across diverse biomes is solid. The 8-9.6% RMSE reduction and R² jump from 19.4% to 43.8% are substantial. But I’d want to see: (1) performance breakdown by biome—does it actually generalize to underrepresented regions, or just improve where data is dense? (2) Ablation studies showing which component (representation learning, task modulation, or physics loss) contributes most. (3) Comparison to process-based models, not just other data-driven methods.
Writing quality: The abstract is crisp, but I suspect the method section glosses over implementation details. How exactly is the carbon balance constraint incorporated—hard constraint or weighted loss term? What’s the architecture of the encoder/decoder? These details matter for reproducibility. The paper would benefit from a clear diagram showing the full pipeline and a table of architectural choices.
Verdict: Weak accept—solid incremental improvement with good experimental validation, but the novelty is more in application than methodology, and key ablations/comparisons may be missing.
Takeaways
For ML practitioners: The task-aware modulation pattern is portable. If you’re building models that predict multiple related quantities from the same input (e.g., predicting different medical outcomes from patient data), consider learning a shared representation then modulating it per task rather than training separate models. The key is identifying which features should be task-specific versus shared.
For scientific ML: The carbon balance constraint shows how to embed domain equations into loss functions. If you have conservation laws, mass balance, or other physical relationships between predicted quantities, encode them as soft constraints rather than hoping the model learns them from data. This is especially powerful when data is sparse but physics is well-understood.
For climate/Earth science: The representation learning approach suggests a path forward for other upscaling problems (soil moisture, vegetation indices, etc.). The pattern is: learn rich representations from abundant remote sensing data, then adapt them for sparse ground truth using physics constraints. This could work wherever you have high-resolution satellite observations but sparse validation data.
论文: 2603.09974 作者: Aleksei Rozanov, Arvind Renganathan, Vipin Kumar 分类: cs.LG, physics.ao-ph
缺口
现有的碳通量尺度提升方法遇到了瓶颈:它们在稀疏的通量塔测量数据上训练(想象一下全球只有约200个站点),然后被要求估算所有地方的通量。
像FluxCom和FLUXNET这样的纯数据驱动方法能从观测站点学到模式,但在外推到具有不同气候条件或植被类型的未观测区域时就崩溃了。
核心问题是分布偏移——模型记住了局部模式,而不是学习可迁移的物理关系。
这导致系统性的区域偏差,R²值停留在20%左右,意味着80%的方差仍无法解释。
稀疏通量塔        数据驱动模型      全球估算
(分布有偏)        (过拟合站点)      (泛化差)
    |                 |               |
    v                 v               v
[150个站点]  ---> [只学局部]  ---> [新区域]
[聚集分布]        [模式]           [失效]
    |                                 |
    +---------------------------------+
          区域偏差 + 高不确定性
增量
一句话: 这篇论文之前,碳通量尺度提升是在稀疏数据上做模式匹配;之后,它变成了受碳平衡物理约束的表征学习。
核心机制
TAM-RL有三个相互咬合的组件。
首先,时空编码器从卫星图像、气候数据和其他环境变量中学习表征——可以理解为将高维地球观测数据压缩到一个捕获相关模式的潜在空间。
其次,任务感知调制根据你要预测的通量类型(GPP、NEE或呼吸作用)来调整这些表征——相同的环境条件对不同的碳过程意味着不同的事情。
第三,解码器重建通量估算,同时受到从碳平衡方程(GPP - 呼吸 = NEE)导出的损失函数监督,确保预测遵守物理约束。
环境数据(卫星、气候、土壤)
        |
        v
   [编码器] -----> 学习到的表征
        |                |
        |                v
        |        [任务调制]
        |        (针对GPP/NEE/Reco调整)
        |                |
        +----------------+
             |
             v
        [解码器] -----> 通量预测
             |
             v
    [物理引导损失]
    (GPP - Reco = NEE 约束)
把TAM-RL想象成地球碳语言的翻译系统。
编码器从环境观测中学习通用词汇——温度模式、植被指数、土壤湿度。
但就像”bank”在金融和河流中意思不同,相同的环境状态对光合作用和呼吸作用意味着不同的事情。
任务感知调制就像方言适配:它接收通用表征,然后根据你询问的具体碳过程对其进行变形。
物理约束充当语法规则——你不能违反碳平衡,就像你不能违反主谓一致。
解码器然后将这个调整后的表征”说”回通量估算,语法检查器(碳平衡损失)确保输出在物理上说得通。
关键概念
- 尺度提升: 想象你在全球150个城市有温度计,但你需要估算地球上所有地方的温度。
这就是尺度提升——从稀疏的点测量到连续的全球场。
挑战不仅是插值(填补邻近点之间的空白),还有外推(在与你测量过的任何地方都不同的区域进行预测)。
对于碳通量,这意味着从温带森林的通量塔获取CO₂交换测量,然后估算没有通量塔的热带雨林中的通量。
- 任务感知调制: 标准神经网络为所有任务学习一组特征。
任务感知调制说:相同的输入应该根据你要预测的内容进行不同处理。
具体来说,它是一个基于任务嵌入来缩放和平移表征的学习变换。
如果你在预测光合作用(GPP),它可能会放大与阳光和叶绿素相关的特征;对于呼吸作用,它强调温度和土壤湿度。
这就像根据你是在听语音还是音乐来调整均衡器设置。
- 知识引导损失: 大多数机器学习损失只测量预测误差。
知识引导损失添加了惩罚违反领域知识的项。
这里,碳平衡方程(GPP - 呼吸 = NEE)成为损失函数中的软约束。
如果你的模型预测GPP=10和呼吸=3,它最好预测NEE≈7,否则损失会增加。
这防止模型学习物理上不可能的组合,即使它们很好地拟合训练数据。
框架转变
之前(主流方法):              之后(本文方法):

环境数据                        环境数据
    |                               |
    v                               v
[神经网络]                      [表征编码器]
 (黑盒)                             |
    |                               v
    v                          [任务调制]
通量预测                        (按通量类型调整)
(站点特定)                          |
                                    v
                               [带物理损失]
                               [的解码器]
                                    |
                                    v
                               通量预测
                               (物理一致)

局部数据上的                    带物理结构的
模式匹配                        约束学习
从黑盒模式匹配到结构化表征学习,核心转变是将物理约束直接嵌入学习目标,而不是将其视为事后验证检查。
专家评审
选题眼光: 这是气候科学中的真实瓶颈。
碳预算有巨大的不确定性,而通量塔网络扩展成本高昂。
改进尺度提升方法具有真正的科学价值。
这个问题处于一个甜蜜点,机器学习可以提供帮助,但领域知识是必不可少的——纯数据驱动方法已经停滞不前。
方法成熟度: 表征学习+任务调制+物理约束的组合是经过深思熟虑的,不只是把transformer扔到问题上。
但我好奇是否测试了更简单的物理信息基线(如带学习参数的基于过程的模型)。
论文声称”任务感知调制”的新颖性,但这本质上是条件计算,在多任务学习中已经探索多年。
真正的贡献是将其具体应用于带碳平衡约束的碳通量。
实验诚意: 跨越不同生物群落的150多个站点是扎实的。
8-9.6%的RMSE降低和R²从19.4%跃升到43.8%是实质性的。
但我想看到:(1)按生物群落的性能分解——它真的泛化到代表性不足的区域,还是只在数据密集的地方改进?(2)消融研究显示哪个组件(表征学习、任务调制或物理损失)贡献最大。
(3)与基于过程的模型的比较,而不仅仅是其他数据驱动方法。
写作功力: 摘要简洁,但我怀疑方法部分掩盖了实现细节。
碳平衡约束究竟如何纳入——硬约束还是加权损失项?编码器/解码器的架构是什么?这些细节对可重复性很重要。
论文将受益于显示完整流程的清晰图表和架构选择表。
判决: 弱接收——具有良好实验验证的扎实增量改进,但新颖性更多在于应用而非方法论,关键的消融/比较可能缺失。
要点总结
对于机器学习从业者: 任务感知调制模式是可移植的。
如果你正在构建从相同输入预测多个相关量的模型(例如,从患者数据预测不同的医疗结果),考虑学习共享表征然后按任务调制它,而不是训练单独的模型。
关键是识别哪些特征应该是任务特定的,哪些是共享的。
对于科学机器学习: 碳平衡约束展示了如何将领域方程嵌入损失函数。
如果你有守恒定律、质量平衡或预测量之间的其他物理关系,将它们编码为软约束,而不是希望模型从数据中学习它们。
当数据稀疏但物理理解充分时,这尤其强大。
对于气候/地球科学: 表征学习方法为其他尺度提升问题(土壤湿度、植被指数等)指明了前进道路。
模式是:从丰富的遥感数据中学习丰富的表征,然后使用物理约束将它们适配到稀疏的地面真值。
这可以在任何你有高分辨率卫星观测但验证数据稀疏的地方工作。