Paper: 2605.12487 Authors: Ariel Gera, Shir Ashury-Tahan, Gal Bloch, Ohad Eytan, Assaf Toledo Categories: cs.CL, cs.IR, cs.LG
The Gap
Embedding models are fast and cheap to run at scale, but they struggle with zero-shot tasks where the query doesn’t match the training distribution. LLMs understand nuanced instructions better but are too expensive to run on every document in a large corpus. Prior work either fine-tunes embeddings (requires labeled data) or uses LLMs for reranking (still processes the whole corpus with embeddings first, missing documents that embeddings ranked poorly).
This paper asks: can we use an LLM to improve the embedding model’s understanding of a specific query, without running the LLM on the entire corpus?
Problem: Embedding models fail on nuanced zero-shot queries
         |
         v
Assumption: LLM can identify what makes a document relevant
            for a specific query by looking at examples
         |
         v
Method: Sample documents -> LLM analyzes -> Refine query embedding
        |
        v
Evidence: +25% on literature search, intent detection, key-point matching
          |
          v
Conclusion: Test-time adaptation bridges embedding/LLM tradeoff
The Increment
One sentence: Before this paper, you chose between cheap-but-rigid embeddings or expensive-but-smart LLMs; after, you can make embeddings task-aware at test time using LLM feedback on a tiny sample.
Core Mechanism
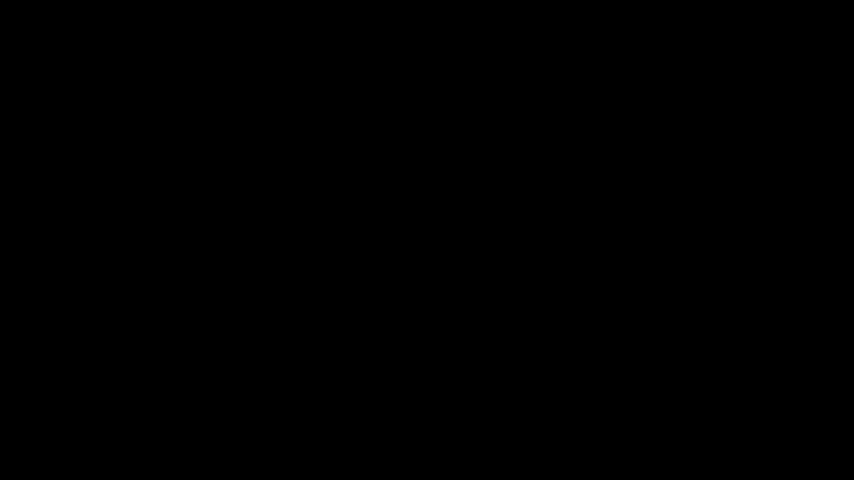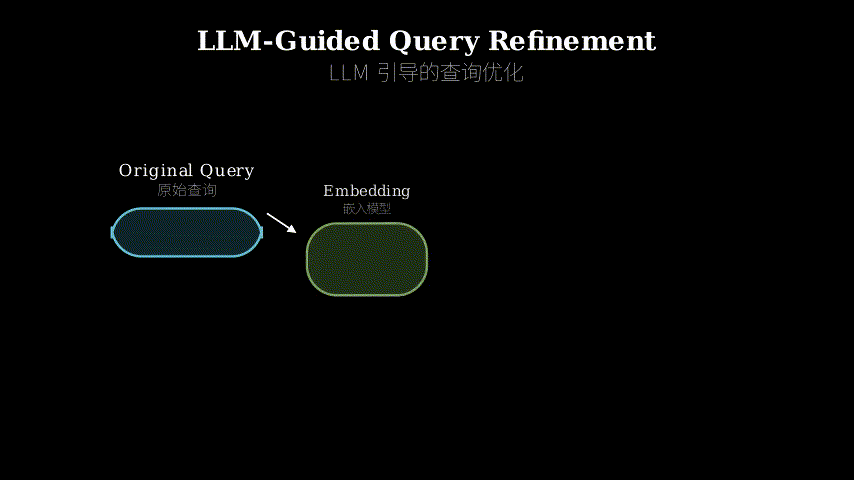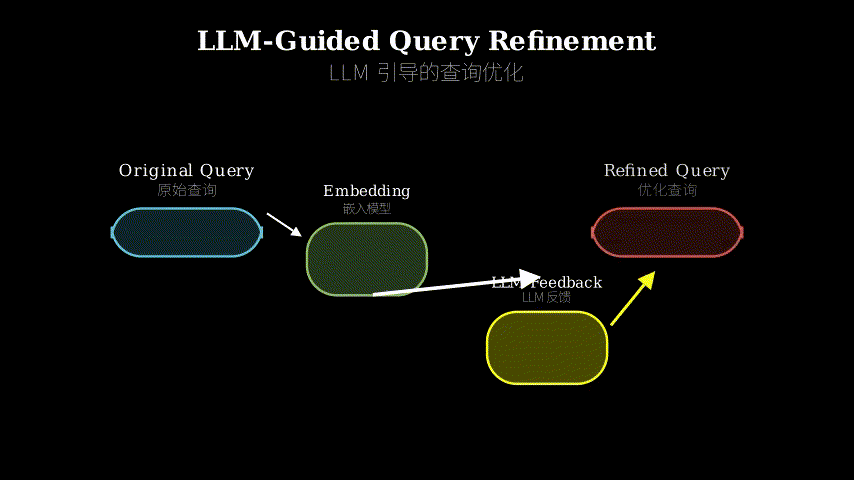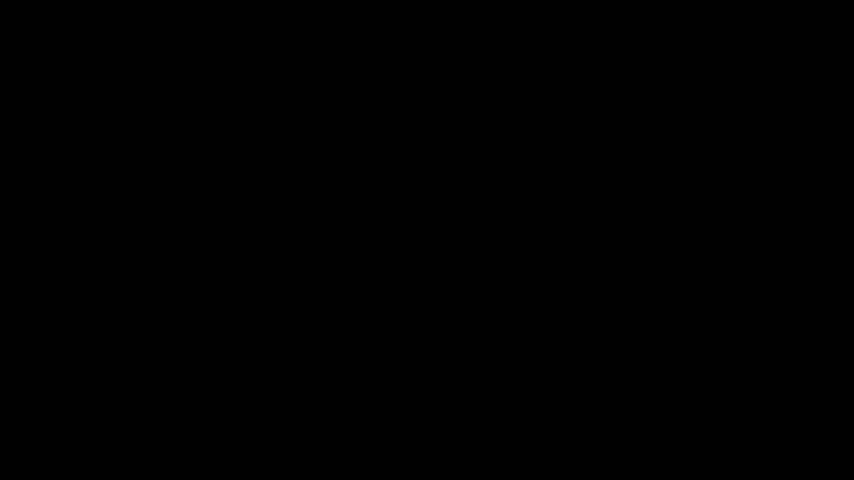
The method has three stages. First, use the original query embedding to retrieve a small sample of documents (say, 10-20). Second, feed these documents plus the query to an LLM and ask it to explain what makes a document relevant or irrelevant for this specific task. Third, use the LLM’s explanation to generate a refined query that better captures the task’s nuances, then re-embed this refined query and use it for the final corpus-wide search.
Original Query
      |
      v
[Embedding Model] --> Initial embedding
      |
      v
Sample top-k docs from corpus
      |
      v
[LLM Analysis]
  Input: Query + Sample docs
  Output: "Relevant docs discuss X, irrelevant ones focus on Y"
      |
      v
Generate refined query incorporating LLM insights
      |
      v
[Embedding Model] --> Refined embedding
      |
      v
Final corpus-wide search with refined embedding
Think of it like hiring a consultant for a job search. You (the embedding model) have a resume and a vague job description. You apply to a few companies and get mixed results. You hire a career coach (the LLM) who reviews those applications and says, “You’re emphasizing the wrong skills—this role cares about X, not Y.” You rewrite your resume (refined query) based on that feedback, then send the new version to all remaining companies. The coach only looked at a handful of applications, but their insight improves your entire job search.
The key insight: the LLM doesn’t need to see the whole corpus. By analyzing a small, diverse sample (retrieved by the initial embedding), it can identify the task-specific patterns that the embedding model missed. The refined query then propagates this understanding across the entire corpus through the embedding space.
Key Concepts
-
Test-time adaptation: Most embedding models are frozen after training—they produce the same representation for a query regardless of context. Test-time adaptation means adjusting the model’s behavior for a specific query at inference time, without retraining. Here, the adjustment happens by refining the query text itself based on LLM feedback, which changes what the embedding model encodes. It’s like adjusting your telescope’s focus for each star you observe, rather than using one fixed setting for the whole sky.
-
Query refinement vs reranking: Reranking takes an initial ranking and reorders it using a more powerful model (like an LLM). Query refinement changes the query itself to produce a better initial ranking. The difference matters for scale: reranking requires running the expensive model on every candidate document, while query refinement runs it once on a small sample, then uses the cheap embedding model for the full corpus. If you have a million documents, reranking means a million LLM calls; query refinement means 10-20 LLM calls plus a million embedding calls.
Framework Shift
Before (mainstream approach):        After (this paper):

Query --> [Embedding] --> Search     Query --> [Embedding] --> Sample
              |                                                    |
              v                                                    v
         All docs ranked                              [LLM analyzes sample]
                                                                   |
                                                                   v
                                                      Refined query --> [Embedding]
                                                                   |
                                                                   v
                                                              All docs ranked

Cost: O(corpus_size * embed_cost)    Cost: O(sample_size * LLM_cost)
                                            + O(corpus_size * embed_cost)
From static query representation to dynamic task-aware representation, the core shift is using LLM intelligence to guide embedding behavior without paying LLM costs at corpus scale.
Expert Assessment
Problem choice: Real gap. The embedding/LLM tradeoff is a genuine pain point in production systems. Zero-shot performance matters because most real-world queries don’t match training distributions. The problem sits at the intersection of efficiency and capability—a sweet spot for practical impact.
Method maturity: Clever insight, not brute force. The idea of using LLM feedback on a sample to refine the query is elegant. However, the paper doesn’t deeply explore failure modes—what happens when the initial sample is unrepresentative? How sensitive is performance to sample size and diversity? The method assumes the initial embedding is good enough to retrieve a useful sample, which may not hold for very hard zero-shot tasks.
Experimental integrity: Baselines are fair—they compare against both vanilla embeddings and LLM reranking. The benchmarks span diverse tasks (literature search, intent detection, key-point matching), which strengthens the claims. The +25% improvement is impressive but comes with caveats: gains vary widely across tasks (some show minimal improvement), and the paper doesn’t report variance across runs or analyze when the method fails. The cost analysis is honest—they acknowledge the LLM overhead—but doesn’t include latency numbers, which matter for real-time systems.
Writing quality: The abstract and introduction are clear, but the method section buries important details (like how they prompt the LLM and generate refined queries) in dense paragraphs. The paper would benefit from a dedicated “Prompting Strategy” subsection with concrete examples. The related work section is thorough but reads like a literature review rather than positioning the contribution. Rewriting Section 3 to lead with intuition before diving into implementation would elevate the whole paper.
Verdict: weak accept — Solid practical contribution with clear gains, but lacks depth on failure analysis and design choices. The idea is sound and the experiments are convincing enough for publication, but this feels like the first paper in a research thread rather than a definitive treatment.
Takeaways
Steal the two-stage retrieval pattern: Initial cheap pass to get candidates, expensive model analyzes sample to refine strategy, second cheap pass with refined strategy. This applies beyond embeddings—think database query optimization, hyperparameter tuning, or A/B test design.
Sample diversity matters more than sample size: The paper shows that 10-20 well-chosen documents give most of the benefit. When using LLMs for feedback, focus on getting a representative sample (top-ranked, bottom-ranked, and middle-ranked documents) rather than a large sample.
Query refinement is underexplored: Most work focuses on reranking or retrieval augmentation. Refining the query itself—whether through LLM feedback, user interaction, or learned transformations—is a cheaper way to improve retrieval quality. This framing transfers to any two-stage system where the first stage is fast but imperfect.
论文: 2605.12487 作者: Ariel Gera, Shir Ashury-Tahan, Gal Bloch, Ohad Eytan, Assaf Toledo 分类: cs.CL, cs.IR, cs.LG
缺口
嵌入模型运行快、成本低,适合大规模部署,但在零样本任务上表现不佳,尤其是当查询不符合训练分布时。
大语言模型(LLM)能理解细微的指令,但在大规模语料库上运行每个文档的成本太高。
此前的工作要么微调嵌入模型(需要标注数据),要么用 LLM 重排序(仍需先用嵌入模型处理整个语料库,会遗漏嵌入模型排名靠后的相关文档)。
本文提出的问题是:能否利用 LLM 改进嵌入模型对特定查询的理解,而不需要在整个语料库上运行 LLM?
问题:嵌入模型在细微的零样本查询上失效
      |
      v
假设:LLM 通过查看样本能识别文档与特定查询的相关性特征
      |
      v
方法:采样文档 -> LLM 分析 -> 优化查询嵌入
      |
      v
证据:文献搜索、意图检测、关键点匹配任务上提升 +25%
      |
      v
结论:测试时自适应弥合了嵌入模型与 LLM 之间的权衡
增量
一句话:本文之前,你只能在便宜但僵化的嵌入模型和昂贵但智能的 LLM 之间二选一;本文之后,你可以用 LLM 对少量样本的反馈让嵌入模型在测试时具备任务感知能力。
核心机制
方法分三个阶段。
首先,用原始查询的嵌入表示检索少量文档(比如 10-20 个)。
其次,将这些文档和查询一起输入 LLM,让它解释什么使文档与这个特定任务相关或不相关。
第三,利用 LLM 的解释生成一个优化后的查询,更好地捕捉任务的细微差别,然后重新嵌入这个优化查询,用于最终的全语料库搜索。
原始查询
   |
   v
[嵌入模型] --> 初始嵌入
   |
   v
从语料库采样 top-k 文档
   |
   v
[LLM 分析]
  输入:查询 + 样本文档
  输出:"相关文档讨论 X,不相关的关注 Y"
   |
   v
生成融合 LLM 洞察的优化查询
   |
   v
[嵌入模型] --> 优化后的嵌入
   |
   v
用优化嵌入进行最终的全语料库搜索
把它想象成为求职聘请顾问。
你(嵌入模型)有一份简历和一个模糊的职位描述。
你向几家公司投递简历,结果参差不齐。
你请了一位职业教练(LLM),他审查这些申请后说:“你强调了错误的技能——这个职位看重 X,而不是 Y。
“你根据反馈重写简历(优化查询),然后把新版本发给所有剩余的公司。
教练只看了少数几份申请,但他的洞察改进了你整个求职过程。
关键洞察:LLM 不需要看整个语料库。
通过分析一个小而多样的样本(由初始嵌入检索得到),它能识别嵌入模型遗漏的任务特定模式。
优化后的查询通过嵌入空间将这种理解传播到整个语料库。
关键概念
- 测试时自适应:大多数嵌入模型在训练后就冻结了——无论上下文如何,它们对查询产生相同的表示。
测试时自适应意味着在推理时针对特定查询调整模型行为,而不需要重新训练。
这里的调整通过基于 LLM 反馈优化查询文本本身来实现,从而改变嵌入模型编码的内容。
就像观察每颗星星时调整望远镜的焦距,而不是对整个天空使用一个固定设置。
- 查询优化 vs 重排序:重排序是用更强大的模型(如 LLM)对初始排名重新排序。
查询优化是改变查询本身以产生更好的初始排名。
这个区别对规模很重要:重排序需要在每个候选文档上运行昂贵的模型,而查询优化只在小样本上运行一次,然后用便宜的嵌入模型处理全语料库。
如果你有一百万个文档,重排序意味着一百万次 LLM 调用;查询优化意味着 10-20 次 LLM 调用加上一百万次嵌入调用。
框架转变
之前(主流方法):                之后(本文方法):

查询 --> [嵌入] --> 搜索          查询 --> [嵌入] --> 采样
            |                                         |
            v                                         v
       所有文档排序                         [LLM 分析样本]
                                                      |
                                                      v
                                         优化查询 --> [嵌入]
                                                      |
                                                      v
                                                 所有文档排序

成本:O(语料库大小 * 嵌入成本)    成本:O(样本大小 * LLM成本)
                                      + O(语料库大小 * 嵌入成本)
从静态查询表示到动态任务感知表示,核心转变是利用 LLM 智能引导嵌入行为,而不需要在语料库规模上支付 LLM 成本。
专家评审
选题眼光:真实缺口。
嵌入模型与 LLM 之间的权衡是生产系统中的真实痛点。
零样本性能很重要,因为大多数真实世界的查询不符合训练分布。
问题位于效率与能力的交叉点——这是实用影响的最佳位置。
方法成熟度:巧劲,非蛮力。
利用 LLM 对样本的反馈来优化查询的想法很优雅。
但论文没有深入探讨失败模式——当初始样本不具代表性时会发生什么?性能对样本大小和多样性有多敏感?方法假设初始嵌入足够好,能检索到有用的样本,这在非常困难的零样本任务上可能不成立。
实验诚意:基线公平——他们与原始嵌入和 LLM 重排序都进行了比较。
基准测试涵盖多样化任务(文献搜索、意图检测、关键点匹配),增强了论证。
+25% 的提升令人印象深刻,但有注意事项:不同任务的收益差异很大(有些改进微乎其微),论文没有报告多次运行的方差或分析方法何时失效。
成本分析是诚实的——他们承认 LLM 开销——但没有包括延迟数字,这对实时系统很重要。
写作功力:摘要和引言清晰,但方法部分将重要细节(如如何提示 LLM 和生成优化查询)埋在密集的段落中。
论文需要一个专门的”提示策略”小节,配有具体示例。
相关工作部分很全面,但读起来像文献综述,而不是定位贡献。
重写第 3 节,先讲直觉再深入实现,能提升整篇论文。
判决:弱接收 — 扎实的实用贡献,有明确收益,但缺乏对失败分析和设计选择的深度。
想法可靠,实验足够有说服力可以发表,但这感觉像研究线索的第一篇论文,而不是决定性的处理。
要点总结
偷走两阶段检索模式:初始便宜的遍历获取候选,昂贵模型分析样本以优化策略,第二次便宜遍历使用优化策略。
这适用于嵌入之外——想想数据库查询优化、超参数调优或 A/B 测试设计。
样本多样性比样本大小更重要:论文显示 10-20 个精心选择的文档就能获得大部分收益。
使用 LLM 获取反馈时,专注于获得代表性样本(排名靠前、靠后和中间的文档),而不是大样本。
查询优化未被充分探索:大多数工作关注重排序或检索增强。
优化查询本身——无论是通过 LLM 反馈、用户交互还是学习的转换——是改进检索质量的更便宜方式。
这个框架可以迁移到任何第一阶段快速但不完美的两阶段系统。