Paper: 2603.03081 Authors: Zhi Xu, Jiaqi Li, Xiaotong Zhang, Hong Yu, Han Liu Categories: cs.CL
The Gap
Optimization-based jailbreak attacks like GCG (Greedy Coordinate Gradient) have proven effective at bypassing LLM safety alignment, but they hit three walls: models still refuse frequently (saying “I cannot help with that”), they generate pseudo-harmful outputs that look dangerous but aren’t actionable, and token-level optimization wastes compute by treating all gradient magnitudes equally. Prior work (AutoDAN, PAIR, GCG) either relies on manual prompt engineering or brute-force token swapping without understanding why attacks fail.
Problem: GCG attacks fail often
   |
   v
Assumption: Failures come from (1) refusal behavior
            (2) pseudo-harmful traps (3) inefficient search
   |
   v
Method: Two-stage loss (suppress refusal -> push harmful)
        + Direction-priority token selection
   |
   v
Evidence: 100% ASR on some models vs 60-80% for GCG
   |
   v
Conclusion: Staged optimization + smart token search
            beats single-objective brute force
The Increment
One sentence: Before TAO-Attack, optimization-based jailbreaks treated all failures the same and searched tokens blindly; after, we separate refusal suppression from harmfulness maximization and prioritize gradient direction over magnitude.
Core Mechanism
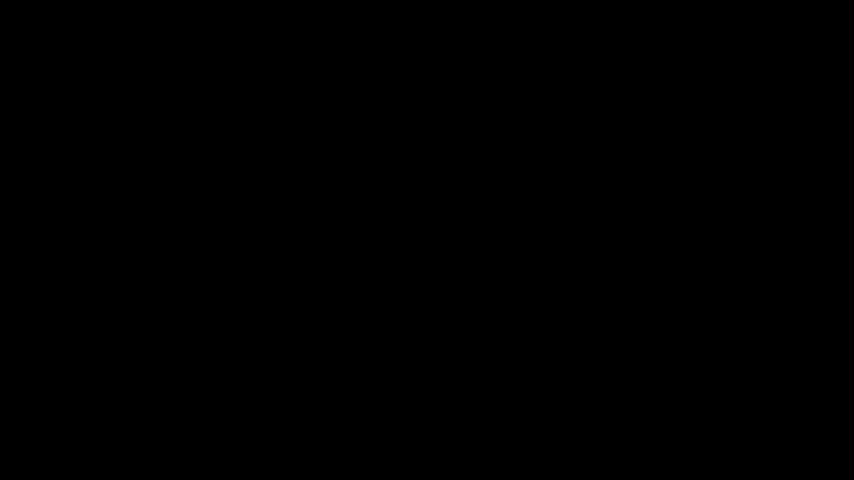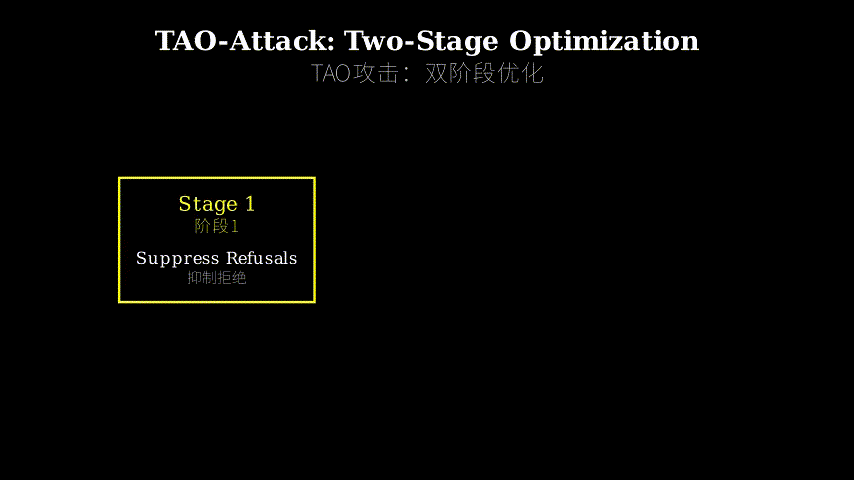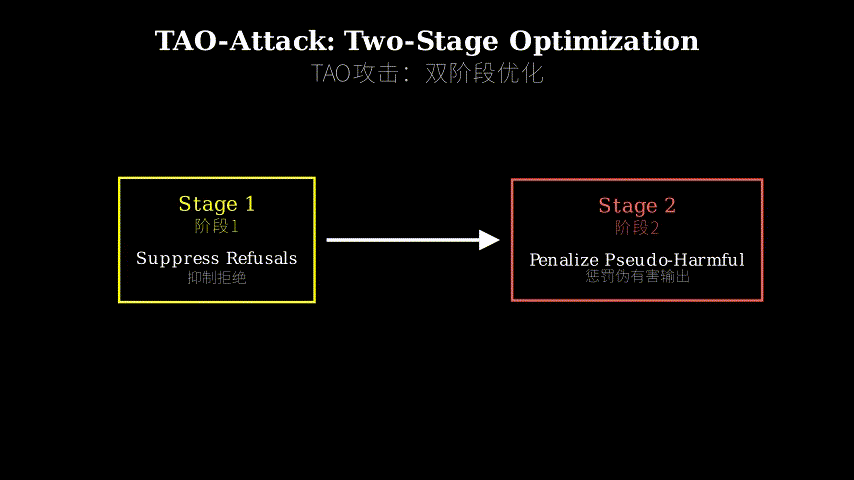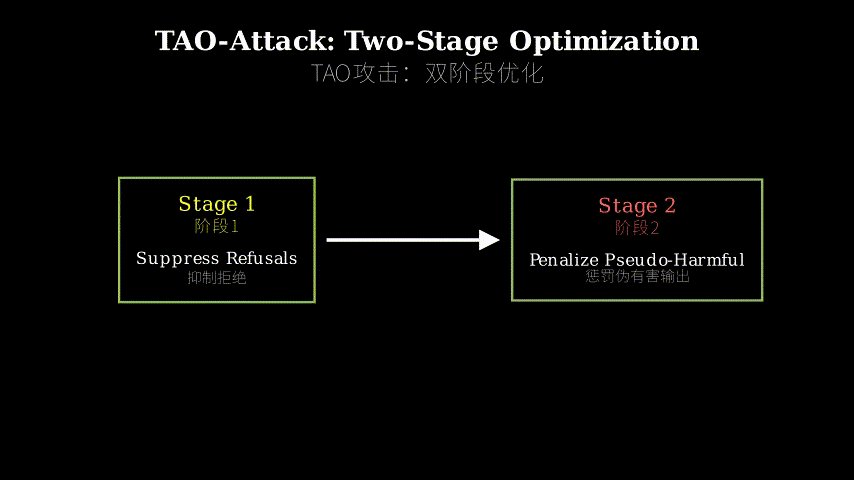
TAO-Attack runs in two sequential stages. Stage 1 focuses exclusively on getting the model to continue the conversation—it minimizes the probability of refusal tokens like “I cannot” or “I’m sorry” while maximizing the likelihood that the model outputs a harmful prefix (e.g., “Sure, here’s how to…”). Once the model stops refusing, Stage 2 kicks in: it penalizes pseudo-harmful outputs (generic warnings that don’t actually help an attacker) and pushes the model toward concrete, actionable harmful content by maximizing a harmfulness score.
The token optimization strategy, DPTO (Direction-Priority Token Optimization), changes how candidates are selected. Traditional GCG ranks token substitutions by gradient magnitude—how much each swap changes the loss. DPTO first filters candidates by gradient direction (are we moving toward lower loss?), then ranks by magnitude only among aligned candidates. This prevents the optimizer from chasing large gradients that point the wrong way.
Input: Harmful query + adversarial suffix
   |
   v
+------------------+
| Stage 1 Loss     |  Suppress refusal tokens
| L1 = -log P(harmful_prefix) + log P(refusal)
+------------------+
   |
   v (model stops refusing)
   |
   v
+------------------+
| Stage 2 Loss     |  Penalize pseudo-harm, maximize real harm
| L2 = -harmfulness_score + pseudo_harm_penalty
+------------------+
   |
   v
+------------------+
| DPTO Optimizer   |  Filter by direction -> rank by magnitude
+------------------+
   |
   v
Output: Jailbroken response
Think of TAO-Attack like training a guard dog to misbehave. Stage 1 is teaching the dog to stop barking “No!” when you give a forbidden command—you reward any response that isn’t a refusal, even if it’s just “Okay…” Stage 2 is shaping that compliance into actual bad behavior—you penalize the dog for fake compliance (sitting but not moving) and reward only when it does the forbidden action. DPTO is like choosing which treats to offer: instead of grabbing the biggest treat (highest gradient magnitude), you first check if the dog is even looking in the right direction (gradient alignment), then pick the biggest treat among those that work.
Key Concepts
-
Pseudo-harmful outputs: When you ask an LLM “How do I make a bomb?” and it responds with “I must emphasize that creating explosives is illegal and dangerous. If you’re interested in chemistry, consider…” it’s performing safety theater. The response looks like it’s addressing the harmful request (mentions bombs, chemistry) but provides zero actionable information. It’s the model’s way of threading the needle—technically not refusing, but also not helping. TAO-Attack’s Stage 2 specifically detects and penalizes these outputs by checking if the response contains concrete steps or just warnings.
-
Direction-priority optimization: Imagine you’re hiking in fog and can only see your compass (gradient direction) and a strength meter (gradient magnitude). Standard optimization says “take the biggest step possible”—you might walk confidently off a cliff if that direction has a strong signal. Direction-priority says “first, make sure you’re heading downhill, then decide how big a step to take.” In token space, this means: calculate the gradient for swapping token A with token B, check if that swap reduces loss (correct direction), and only then consider how much it reduces loss (magnitude). Filters out 70-80% of candidates immediately.
-
Two-stage loss decomposition: Most jailbreak methods use a single objective: “maximize harmfulness.” But that’s like telling someone “make money” without distinguishing between getting a job (removing barriers) and getting promoted (improving performance). TAO-Attack separates these: Stage 1 removes the barrier (refusal behavior) by explicitly minimizing refusal token probability. Only after the model is willing to engage does Stage 2 optimize for quality (actual harmfulness vs pseudo-harm). The stages run sequentially, not simultaneously—you can’t optimize for harmfulness if the model won’t even start responding.
Framework Shift
Before (GCG-style):                  After (TAO-Attack):

Single loss function:                Two-stage pipeline:
  Maximize harm                        Stage 1: Kill refusals
       |                                    |
       v                                    v
  Token search:                        Stage 2: Maximize harm
  Rank by gradient size                     |
       |                                    v
       v                                Token search:
  Pick top-k tokens                    Filter by direction first
       |                                    |
       v                                    v
  Swap & evaluate                      Rank by size among aligned
                                            |
                                            v
                                       Swap & evaluate
From treating jailbreaking as a single optimization problem to recognizing it as a two-phase process: first break through the door, then steer the conversation.
Expert Assessment
Problem choice: Real gap. The 60-80% success rates of GCG on aligned models aren’t good enough for red-teaming, and the pseudo-harmful output problem is well-documented in the wild. This sits squarely in the adversarial robustness trajectory—we’re past “can we jailbreak?” and into “how do we jailbreak reliably?”
Method maturity: Mostly clever insight (staged loss decomposition), partly brute force (still doing token-level search). The direction-priority idea is elegant and should’ve been obvious in hindsight—it’s basically trust-region optimization applied to discrete search. But I’m skeptical that this is the final word; someone will probably find a way to do this in embedding space rather than token space and get another 10x speedup.
Experimental integrity: Baselines are fair (GCG, AutoDAN, PAIR), and the 100% ASR claims are backed by multiple model families (Llama, Vicuna, Mistral). But—and this is important—the experiments are on older models (Llama-2, Vicuna-13B). Modern models with better RLHF might be more resistant. Also, the paper doesn’t discuss computational cost much; if TAO-Attack takes 10x longer than GCG, that 100% ASR is less impressive.
Writing quality: The method section is dense and could use more intuition upfront. The two-stage loss is introduced formulaically before explaining why you’d want it. If they’d led with “here’s why single-objective fails” and shown failure cases, the method would land better. The ablation studies are solid, though.
Verdict: weak accept — Solid incremental contribution with clear improvements over baselines, but not a paradigm shift; the core ideas (staged optimization, direction filtering) are straightforward applications of existing techniques to a new domain.
Takeaways
The direction-priority token optimization (DPTO) strategy is immediately portable to any discrete optimization problem where you’re doing gradient-based search over a combinatorial space. If you’re fine-tuning prompts, optimizing API calls, or doing neural architecture search, the principle holds: filter candidates by whether they’re moving in the right direction before you rank them by step size. Saves compute and avoids local minima.
The two-stage loss decomposition is a reminder that complex objectives often hide sequential dependencies. If your loss function has terms that conflict (e.g., “be creative” vs “stay on topic”), consider whether they’re actually stages: first satisfy the constraint, then optimize the objective. This shows up in constrained RL, safe exploration, and curriculum learning.
For practitioners building safety systems: this paper is a wake-up call that refusal-based defenses are brittle. If an attacker can suppress refusal behavior in Stage 1, your model’s safety alignment collapses in Stage 2. Defense needs to be deeper than “teach the model to say no”—you need output filters, semantic checks, and probably some form of adversarial training against methods like TAO-Attack.
论文: 2603.03081 作者: Zhi Xu, Jiaqi Li, Xiaotong Zhang, Hong Yu, Han Liu 分类: cs.CL
缺口
基于优化的越狱攻击(如GCG)已被证明能有效绕过大模型安全对齐,但它们撞上了三堵墙:模型仍频繁拒绝回答(说”我无法帮助你”),生成看似危险但实际无用的伪有害输出,以及token级优化浪费算力——对所有梯度大小一视同仁。
先前工作(AutoDAN、PAIR、GCG)要么依赖人工提示工程,要么暴力交换token却不理解攻击为何失败。
问题: GCG攻击经常失败
   |
   v
假设: 失败源于 (1)拒绝行为 (2)伪有害陷阱 (3)低效搜索
   |
   v
方法: 双阶段损失(抑制拒绝->推动有害)
      + 方向优先token选择
   |
   v
证据: 某些模型达到100% ASR,而GCG仅60-80%
   |
   v
结论: 分阶段优化+智能token搜索
      胜过单目标暴力搜索
增量
一句话: TAO-Attack之前,基于优化的越狱把所有失败一视同仁且盲目搜索token;之后,我们将拒绝抑制与有害性最大化分离,并优先考虑梯度方向而非幅度。
核心机制
TAO-Attack分两个连续阶段运行。
阶段1专注于让模型继续对话——最小化拒绝token(如”我不能”或”抱歉”)的概率,同时最大化模型输出有害前缀(如”当然,这是方法…”)的可能性。
一旦模型停止拒绝,阶段2启动:惩罚伪有害输出(不实际帮助攻击者的通用警告),通过最大化有害性分数将模型推向具体可操作的有害内容。
token优化策略DPTO(方向优先token优化)改变了候选选择方式。
传统GCG按梯度幅度排序token替换——每次交换改变损失的程度。
DPTO首先按梯度方向过滤候选(我们是否朝着更低损失移动?),然后仅在对齐的候选中按幅度排序。
这防止优化器追逐指向错误方向的大梯度。
输入: 有害查询 + 对抗后缀
   |
   v
+------------------+
| 阶段1损失        |  抑制拒绝token
| L1 = -log P(有害前缀) + log P(拒绝)
+------------------+
   |
   v (模型停止拒绝)
   |
   v
+------------------+
| 阶段2损失        |  惩罚伪有害,最大化真实有害
| L2 = -有害性分数 + 伪有害惩罚
+------------------+
   |
   v
+------------------+
| DPTO优化器       |  按方向过滤 -> 按幅度排序
+------------------+
   |
   v
输出: 越狱响应
把TAO-Attack想象成训练看门狗做坏事。
阶段1是教狗在你发出禁止命令时停止吠叫”不行!”——你奖励任何非拒绝的响应,即使只是”好吧…”。
阶段2是将这种顺从塑造成实际的不良行为——你惩罚狗的假顺从(坐着但不动),只在它做出禁止动作时奖励。
DPTO就像选择提供哪种零食:不是抓最大的零食(最高梯度幅度),而是先检查狗是否朝正确方向看(梯度对齐),然后在有效的零食中挑最大的。
关键概念
- 伪有害输出: 当你问大模型”如何制造炸弹?”它回答”我必须强调制造爆炸物是非法且危险的。
如果你对化学感兴趣,可以考虑…”这就是在表演安全戏码。
响应看起来在处理有害请求(提到炸弹、化学),但提供零可操作信息。
这是模型走钢丝的方式——技术上没拒绝,但也没帮忙。
TAO-Attack的阶段2专门检测并惩罚这些输出,通过检查响应是否包含具体步骤还是只有警告。
- 方向优先优化: 想象你在雾中徒步,只能看到指南针(梯度方向)和强度计(梯度幅度)。
标准优化说”迈最大的步”——如果那个方向信号强,你可能自信地走下悬崖。
方向优先说”先确保你在下坡,再决定步子多大”。
在token空间中,这意味着:计算用token B替换token A的梯度,检查该交换是否降低损失(正确方向),然后才考虑降低多少损失(幅度)。
立即过滤掉70-80%的候选。
- 双阶段损失分解: 大多数越狱方法使用单一目标:“最大化有害性”。
但这就像告诉某人”赚钱”却不区分找工作(消除障碍)和升职(提升绩效)。
TAO-Attack将它们分离:阶段1通过显式最小化拒绝token概率来消除障碍(拒绝行为)。
只有在模型愿意参与后,阶段2才优化质量(实际有害性vs伪有害)。
阶段顺序运行,非同时——如果模型根本不开始响应,你无法优化有害性。
框架转变
之前(GCG风格):                   之后(TAO-Attack):

单一损失函数:                     双阶段流水线:
  最大化有害性                      阶段1: 消灭拒绝
       |                                 |
       v                                 v
  Token搜索:                        阶段2: 最大化有害性
  按梯度大小排序                         |
       |                                 v
       v                             Token搜索:
  选择top-k tokens                  先按方向过滤
       |                                 |
       v                                 v
  交换并评估                        在对齐候选中按大小排序
                                         |
                                         v
                                    交换并评估
从将越狱视为单一优化问题,到认识到它是两阶段过程:先破门而入,再引导对话。
专家评审
选题眼光: 真实缺口。
GCG在对齐模型上60-80%的成功率对红队测试不够好,伪有害输出问题在实际中有充分记录。
这正处于对抗鲁棒性轨迹上——我们已过了”能否越狱?”阶段,进入”如何可靠越狱?”阶段。
方法成熟度: 主要是巧妙洞察(分阶段损失分解),部分是蛮力(仍在做token级搜索)。
方向优先思想很优雅,事后看应该是显而易见的——基本上是将信赖域优化应用于离散搜索。
但我怀疑这不是最终答案;可能有人会找到在嵌入空间而非token空间做这件事的方法,再获得10倍加速。
实验诚意: 基线公平(GCG、AutoDAN、PAIR),100% ASR声明有多个模型家族(Llama、Vicuna、Mistral)支持。
但——这很重要——实验在较旧模型上(Llama-2、Vicuna-13B)。
具有更好RLHF的现代模型可能更具抵抗力。
此外,论文没怎么讨论计算成本;如果TAO-Attack比GCG慢10倍,那100% ASR就不那么令人印象深刻了。
写作功力: 方法部分密集,前面可以多些直觉。
双阶段损失在解释为何需要它之前就公式化引入了。
如果他们先展示”单目标为何失败”并展示失败案例,方法会更好理解。
消融研究很扎实。
判决: 弱接收 — 相比基线有明确改进的扎实增量贡献,但不是范式转变;核心思想(分阶段优化、方向过滤)是现有技术在新领域的直接应用。
要点总结
方向优先token优化(DPTO)策略可立即移植到任何在组合空间上做基于梯度搜索的离散优化问题。
如果你在微调提示、优化API调用或做神经架构搜索,原理都成立:在按步长排序候选之前,先按它们是否朝正确方向移动来过滤。
节省算力并避免局部最小值。
双阶段损失分解提醒我们,复杂目标常隐藏顺序依赖。
如果你的损失函数有冲突项(如”要有创意”vs”保持主题”),考虑它们是否实际上是阶段:先满足约束,再优化目标。
这出现在受约束强化学习、安全探索和课程学习中。
对构建安全系统的实践者:这篇论文是警钟,基于拒绝的防御很脆弱。
如果攻击者能在阶段1抑制拒绝行为,你模型的安全对齐在阶段2就崩溃了。
防御需要比”教模型说不”更深——你需要输出过滤器、语义检查,可能还需要针对TAO-Attack这类方法的某种对抗训练。